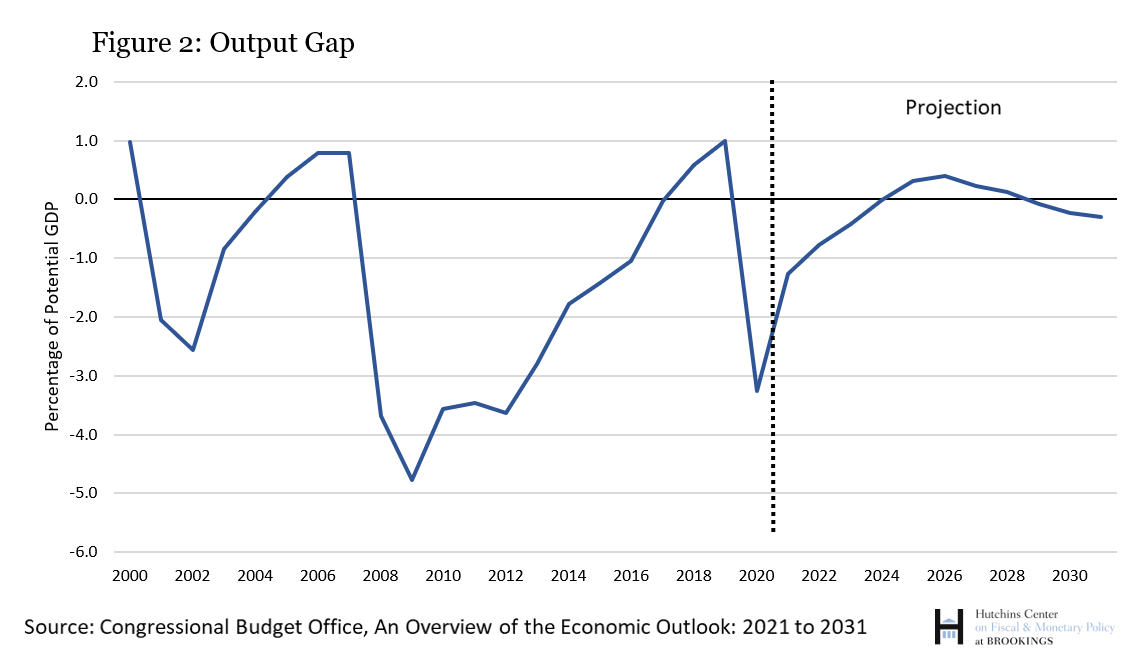
In a recent post, I pointed out that US corporate profit margins (that’s profits as a share of national income) had reached record levels, 19.4%—the highest recorded in the US since the 1940s! The converse was the case for labour’s share which had fallen to a new low. If we measure the ratio of profits
Labour’s share
Sample Surveys · Economics · Generalized Linear Models · Statistical Learning
National Survey on Aspects of Virtuality Linked to the COVID-19 Pandemic (ENAVIRPA 2021)
Economic Impact Module, descriptive results, inferential design, and reproducible evaluation
PROLOGUE
The National Survey on Aspects of Virtuality Linked to the COVID-19 Pandemic (ENAVIRPA 2021) was a collective effort carried out by the students enrolled in Introduction to Sample Surveys at the University of Costa Rica. Fieldwork, questionnaire integration, and the different thematic modules belong to that collective project. This document focuses primarily on the Economic Impact (AE) module, whose design and analysis correspond to José Mauricio Gómez Julián, and makes complementary use of questions from other modules developed by other members of the course. The presence of those items in the analysis does not imply that their construction is attributed to the author of the economic module.
The exercise had a twofold purpose. First, to carry out a real telephone survey during the health crisis and describe material aspects associated with the pandemic. Second, to use the data as a pedagogical setting for studying what can —and cannot— be done with a sample survey when moving from description to inference, generalized linear models, and predictive evaluation.
The scope must be established from the outset. The 235 interviews constitute a real data set, but the number of observations alone is not enough to turn every sample statistic into an unbiased national estimate. Representativeness also depends on the selection mechanism, frame coverage, inclusion probabilities, nonresponse, weighting, measurement error, and questionnaire constraints. The design was carried out under the time and coordination limitations inherent in an academic exercise; moreover, the modules did not originate from a single common theoretical framework. The results are therefore interpreted primarily as results from this sample and as methodological evidence concerning the procedures employed.
It is also useful to distinguish a survey from a psychometric instrument. A survey is a procedure for collecting information and may contain demographic, labor, economic, attitudinal, or psychometric-scale variables. Not every questionnaire is, merely by virtue of being a questionnaire, a psychometric instrument. When a module seeks to measure a latent construct, additional problems of reliability, validity, and measurement error arise and require specific procedures. ENAVIRPA did not undertake a global psychometric validation of the questionnaire; this constitutes a limitation only for interpretations that seek to attribute the measurement of latent constructs to sets of items.
The criterion for incorporating complementary modules was to study the multidimensional distribution of social losses associated with the pandemic: work, income, access to virtual environments, food, hydration, physical activity, and other living conditions. The economy does not exist separately from these concrete determinations, and for that reason the AE module is also analyzed in relation to sociodemographic information and variables from other modules.
One final methodological clarification applies throughout the
document: whenever the questionnaire, analytical database, and a
published table appear to suggest different numerical codings,
the unit of interpretation will always be the substantive
category, not the number arbitrarily assigned to it. The
ENAVIRPA2021csv.csv database stores AE3-AE9 as textual
labels —“Aumentó”, “Disminuyó”, “Sin cambios”, “No es una fuente de
ingresos/apoyo”, and “No responde”—. The reproducible analysis in this
report uses those labels directly and does not depend on an undocumented
numerical recoding.
I. OBJECTIVES
I.1. General objective
To plan, conduct, and analyze a sample survey associated with the health crisis caused by COVID-19, with particular emphasis on its economic impact.
I.2. Specific objectives
- To describe the main results of the Economic Impact module.
- To integrate, when conceptually appropriate, information from the sociodemographic, virtual education, technology, telework, and health-habits modules.
- To examine what types of inference can be formulated from the collected data and under which restrictions.
- To study generalized linear models, particularly probit and logit, as tools for analyzing binary variables.
- To show the complementarity between statistical inference and supervised learning, distinguishing fitting, inference, and out-of-sample generalization.
- To make explicit the restrictions imposed by the sampling design, nonresponse, absence of weighting, coding, skip patterns, and sample size.
II. DESCRIPTIVE METHODOLOGY
II.1. General summary
| Element | Description |
|---|---|
| Study population | Persons aged 18 or older, cell-phone users, and residents of Costa Rica. |
| Operational frame | Active cellular-number banks constructed from operator prefixes, according to the information used by the course. |
| Data-collection mode | Computer-assisted telephone interviewing (CATI), using CSPro 7.4. |
| Selection procedure | Sampling from active cellular-number banks using the Waksberg procedure as a reference. |
| Originally planned sample size | 300 interviews, 30 for each of the ten participating students. |
| Final sample size | 235 completed interviews. |
| Fieldwork | June–July 2021, according to the course chronology. |
| Reference sampling error | ±6.39 percentage points for a proportion under the idealized SRS
calculation with p=0.5; this is not a measure of total
survey error. |
| Weighting | A complete system of design weights, nonresponse adjustments, and calibration was not available. |
| Scope | Academic exercise with real data; descriptive results are presented primarily as sample results. |
II.2. General description of the research process
Fieldwork was carried out by ten students from a graduate program at the University of Costa Rica. The group received training in CSPro 7.4; the modules prepared by the different participants were subsequently assembled, a pilot test of approximately three interviews per student was conducted, and fieldwork then proceeded. The collective target was 300 interviews. A total of 235 were completed.
For the fieldwork carried out by José Mauricio Gómez Julián, 332
calls and approximately 18 hours of telephone contact were recorded. The
summary log reports 34 busy numbers, 94 unanswered calls, and 183 calls
after inactive numbers were excluded. From those three figures one can
compute 1-(128/183)=0.300546; however, that
quantity should not automatically be called a “response rate.”
The 55 residual cases are not necessarily completed interviews, and the
denominator does not fully classify eligibility, refusal, contact, and
unknown eligibility. A standardized response rate would require final
dispositions for all cases under an explicit definition, such as those
used by AAPOR.
Accordingly, this report retains the raw call counts but does not assign the 30.0546% figure the meaning of a standardized response rate. The verifiable fact for the author of the economic module is that the 30 interviews assigned to him were completed; the verifiable collective fact is that 235 of the 300 planned interviews were completed, or 78.3% of the production target. Neither ratio is, by itself, a probabilistic response rate.
II.2.1. Activity schedule

II.2.2. Telephone-number banks

II.2.3. General chronology of fieldwork

II.2.4. Call log

II.3. Presentation of the Economic Impact (AE) module
| ECONOMIC IMPACT |
|---|
| AE1 |
Have you received, or did you receive, any financial benefit or support from the national or local government since the health emergency/quarantine caused by COVID-19 began?
|
|---|---|
| AE2 |
Please indicate which of the following benefits/support you receive or received (Multiple response)
|
| As a result of the health emergency/quarantine caused by COVID, please indicate how your personal resources have been affected: have they increased, decreased, or remained unchanged? | Increased | No change | Decreased | Not a source of income/support | |
|---|---|---|---|---|---|
| AE3 | Income or earnings from paid work | 4 | 3 | 2 | 1 |
| AE4 | Money or goods received from family/friends living elsewhere in the country | 4 | 3 | 2 | 1 |
| AE5 | Money or goods received from family/friends living in another country | 4 | 3 | 2 | 1 |
| AE6 | Income from rental property, investments, or savings | 4 | 3 | 2 | 1 |
| AE7 | Pensions and/or retirement benefits or other social payments | 4 | 3 | 2 | 1 |
| AE8 | Government support | 4 | 3 | 2 | 1 |
| AE9 | Support/donation from NGOs, civil-society organizations, foundations, or other nonprofit organizations | 4 | 3 | 2 | 1 |
| AE10 |
Besides you, has any other member of your household experienced a change in economic income since the health emergency/quarantine caused by COVID-19 began?
|
|---|---|
| AE11 |
Since the health emergency/quarantine caused by COVID-19 began, would you say that the total salary or income your family receives each month is enough or not enough to live on? (PROBE FOR THE BEST ANSWER)
|
II.3.1. Note on the coding of AE3-AE9
In the data-collection instrument, AE3-AE9 appear with the codes
4 = Increased, 3 = No change,
2 = Decreased, and
1 = Not a source of income/support. A later table may order
the same categories using a different numbering solely for presentation.
A reader could quite reasonably believe, when comparing the two places,
that the data were interpreted using incompatible codes. That
need not be the case, because the number is only a label and
can be recoded; what would be problematic is being unable to determine
which substantive category each value represents during analysis.
The available analytical database removes that ambiguity because AE3-AE9 are stored directly as text. Consequently, every table and constructed variable here uses the semantic categories rather than a numerical sequence. Reproducibility therefore does not depend on reconstructing an intermediate recoding that was not documented.
II.4. Items used from other modules
II.4.1. SOCIODEMOGRAPHIC MODULE (SD)
| SOCIODEMOGRAPHIC | ||||||
|---|---|---|---|---|---|---|
| SD1 |
INTERVIEWER: RECORD RESPONDENT’S SEX |
|
||||
| SD2 | Please tell me, how old are you? | YEARS /____/____/ | ||||
| SD3 | Are you Costa Rican? 1. YES 2. NO | |||||
| SD5 |
What is this household’s total monthly income? (PROBE) |
|
|
|||
II.4.2. VIRTUAL EDUCATION MODULE (E)
| CHALLENGES OF VIRTUAL EDUCATION |
|---|
| E6 | What is the reason you have not participated in or enrolled in any virtual/online education or training program? |
|---|---|
|
|
II.4.3. TECHNOLOGY MODULE (TC)
| TECHNOLOGY – EVERYONE |
|---|
| TC1 |
Do you have fixed internet/modem service in your home?
|
|---|
II.4.4. TELEWORK MODULE (TE)
| TELEWORK – JORDAN/CARLOS | |
|---|---|
|
At present, during a typical week, what is your main work activity? SELECT THE OPTION THAT BEST APPLIES
IF RESPONSE IS 5 TO 99, GO TO V1
|
|
II.4.5. PHYSICAL AND MENTAL HEALTH MODULE (FN)
| PHYSICAL-HEALTH AND NUTRITION HABITS – LUIS |
|---|
| FN2 |
Regarding your water consumption, during the pandemic have you increased the amount of water you drink?
|
|---|
| Regarding mealtime habits, comparing current frequency with the year before the pandemic, would you say they increased, decreased, or remained the same? | Remained the same | Increased | Decreased | DK/NA | |
|---|---|---|---|---|---|
| FN6 | Breakfast | 1 | 2 | 3 | 9 |
| FN7 | Lunch | 1 | 2 | 3 | 9 |
| FN8 | Dinner | 1 | 2 | 3 | 9 |
| Regarding the foods I am going to mention, comparing current frequency with your habits in the year before the pandemic, would you say your consumption of … (READ FOOD) increased, decreased, or remained the same? | HAS NOT EATEN IT | YES | DK/NA | |||
|---|---|---|---|---|---|---|
| Remained the same | Increased | Decreased | ||||
| FN9 | Fruits and vegetables | 0 | 1 | 2 | 3 | 9 |
| FN10 | Legumes (beans, chickpeas, lentils) | 0 | 1 | 2 | 3 | 9 |
| FN11 | Dairy products (milk, yogurt, cheese) | 0 | 1 | 2 | 3 | 9 |
| FN12 | Starches (rice, pasta) | 0 | 1 | 2 | 3 | 9 |
| FN13 | Meat or eggs (beef, pork, chicken, fish, processed meats) | 0 | 1 | 2 | 3 | 9 |
| FN14 | Foods/sweets/beverages that are sources of sugar (cookies, sodas, Hi-C, Powerade, etc.; sweets, chocolates, candy, ice cream) | 0 | 1 | 2 | 3 | 9 |
| FN15 | Fats and fast foods (butter, sour cream, dressings, mayonnaise; fried chicken, French fries, pizza, hamburgers, tacos, pastries, packaged snacks, etc.) | 0 | 1 | 2 | 3 | 9 |
III. PRESENTATION OF DESCRIPTIVE RESULTS
III.1. AE module: economic impact
III.1.1. AE1. Government financial support
| Response | n | % |
|---|---|---|
| Yes | 56 | 23.8 |
| No | 179 | 76.2 |
| Total | 235 | 100.0 |
Fifty-six people, 23.8% of the sample, reported having received some benefit or financial support from the national or local government since the beginning of the emergency; 179, or 76.2%, answered that they had not.
III.1.2. AE2. Type of support received
AE2 was conditional on AE1: only the 56 people who answered “yes” to AE1 were supposed to answer it. In the database, the other 179 records correctly appear as missing values generated by the questionnaire skip. They are not “does not know/no answer”; they are not applicable. Since AE2 allowed multiple responses, each percentage must be calculated over the 56 eligible people, and the percentages need not add to 100%.
| Type of support | Yes (n) | % of the 56 | No (n) | % of the 56 |
|---|---|---|---|---|
| Food/groceries | 23 | 41.1 | 33 | 58.9 |
| Financial resources | 48 | 85.7 | 8 | 14.3 |
| Medical prevention supplies | 4 | 7.1 | 52 | 92.9 |
| Personal-hygiene supplies | 2 | 3.6 | 54 | 96.4 |
Thus, among those who received some form of support, 41.1% reported food and 85.7% financial resources. It is not correct to divide each selection by the total number of selections made and describe the resulting figure as a percentage of people.
III.1.3. AE3-AE9. Changes in sources of income and support
| Item/source | Decreased | Increased | No change | Not a source | NR |
|---|---|---|---|---|---|
| AE3 — Income or earnings from paid work | 87 (37.0%) | 9 (3.8%) | 90 (38.3%) | 43 (18.3%) | 6 (2.6%) |
| AE4 — Money/goods from family or friends within the country | 26 (11.1%) | 3 (1.3%) | 33 (14.0%) | 168 (71.5%) | 5 (2.1%) |
| AE5 — Money/goods from family or friends in another country | 11 (4.7%) | 0 (0.0%) | 17 (7.2%) | 202 (86.0%) | 5 (2.1%) |
| AE6 — Income from rental property, investments, or savings | 13 (5.5%) | 5 (2.1%) | 21 (8.9%) | 192 (81.7%) | 4 (1.7%) |
| AE7 — Pensions, retirement benefits, or other social payments | 7 (3.0%) | 0 (0.0%) | 39 (16.6%) | 185 (78.7%) | 4 (1.7%) |
| AE8 — Government support | 8 (3.4%) | 18 (7.7%) | 22 (9.4%) | 185 (78.7%) | 2 (0.9%) |
| AE9 — Support from NGOs, civil society, foundations, or other nonprofit organizations | 4 (1.7%) | 2 (0.9%) | 13 (5.5%) | 214 (91.1%) | 2 (0.9%) |
Paid work was the source with the greatest presence and also the largest number of contractions: 87 people, 37.0% of the entire sample, reported a decrease; nine, 3.8%, an increase; and 90, 38.3%, no change. In AE6, 192 people, 81.7%, indicated that income from rental property, investments, or savings was not a source of income/support during the observed period.
Means of production as capital: scope of AE6
In the specific sense used in this analysis, the possession of means of production does not refer merely to ownership of instruments personally used by an independent producer, but to their possession as capital, that is, as property generating income separable from the owner’s direct labor.
The distinction is substantive. A self-employed worker may own tools, a vehicle, or a machine and reproduce materially through his or her own labor without the observed income thereby arising from capital in the sense defined here. AE6, by contrast, asks about income from rental property, investments, or savings and therefore serves as an empirical indicator of the presence of property or patrimonial income. Under this operationalization, the 192 cases stating that AE6 is not a source are classified as an observed absence of income associated with property-capital; the 39 cases reporting increase, decrease, or stability are classified as presence of that source; four cases remain indeterminate because of nonresponse.
This is not equivalent to a legal inspection of assets. A person may own an asset that temporarily produces no rent or whose profits are reinvested. That is an observational limitation, not an objection to the concept. The inference should therefore be formulated as the observed absence or presence of income indicative of property-capital within the categories captured by AE6.
TE1 separately retains information on labor status and business ownership. It is useful for distinguishing wage workers, employers, and independent producers, but it should not be mechanically confused with AE6: “own business without employees” and “receives income from property-capital” are related but nonidentical variables.
III.1.4. AE10. Income change among other household members
| Response | n | % |
|---|---|---|
| No change in income | 112 | 47.7 |
| Income increased | 8 | 3.4 |
| Income decreased | 104 | 44.3 |
| No response | 11 | 4.7 |
A total of 44.3% indicated that another member of the household had experienced a decrease in income; 47.7% reported no change and 3.4% reported an increase.
III.1.5. AE11. Sufficiency of family income
| Response | n | % |
|---|---|---|
| Not enough; great difficulties | 24 | 10.2 |
| Not enough; difficulties | 57 | 24.3 |
| Just enough, without great difficulties | 111 | 47.2 |
| Enough; can save | 40 | 17.0 |
| DK/NA | 3 | 1.3 |
A total of 34.5% reported that income was not enough to live on —10.2% with great difficulties and 24.3% with difficulties—; 47.2% said it was just enough, and 17.0% said it was enough and allowed them to save. AE11 directly measures subjective income sufficiency and is kept separate from a formal poverty line.
III.2. TE module: work and telework
III.2.1. TE1. Main activity
| Activity | n | % |
|---|---|---|
| Works for an employer | 105 | 44.7 |
| Helps in an unpaid family business | 5 | 2.1 |
| Own business with employees | 11 | 4.7 |
| Own business without employees | 33 | 14.0 |
| Pensioner/retiree | 12 | 5.1 |
| Homemaker | 40 | 17.0 |
| Full-time student | 17 | 7.2 |
| Does not work because of a physical/mental limitation | 1 | 0.4 |
| Does not work, is not seeking work, and is unavailable | 2 | 0.9 |
| Does not work, is seeking work | 8 | 3.4 |
| Other | 1 | 0.4 |
The sample contains 105 wage workers, 33 producers with their own business and no employees, and 11 business owners who employ other people. Only the last category directly identifies an employer relation involving the labor of others; the own-business-without-employees category describes independent production. This distinction prevents every ownership of instruments or of a small business from being transformed into capitalist ownership in the substantive sense used for AE6.
III.2.2. TE6. Change in working hours or remuneration
| Response | n | % among 38 applicable cases |
|---|---|---|
| Fewer hours | 2 | 5.3 |
| More hours | 16 | 42.1 |
| Lower pay for the same amount of work | 6 | 15.8 |
| Lower pay for more work | 7 | 18.4 |
| Higher pay for more work | 1 | 2.6 |
| Higher pay for less work | 1 | 2.6 |
| Other | 5 | 13.2 |
| Not applicable because of questionnaire flow | 197 | — |
TE6 produced 38 substantive responses and 197 cases that were not applicable because of the module flow. Among the 38 people exposed to the question, 16 —42.1%— reported working more hours. This percentage should not be projected onto all 235 interviews because the question was not asked of every participant.
III.3. FN module: physical-health and nutrition habits
III.3.1. FN2. Hydration
| Response | n | % |
|---|---|---|
| Increased | 87 | 37.0 |
| Remained the same | 133 | 56.6 |
| Decreased | 14 | 6.0 |
| DK/NA | 1 | 0.4 |
III.3.2. FN6-FN8. Frequency of meals
| Meal | Same | Increased | Decreased |
|---|---|---|---|
| Breakfast | 183 (77.9%) | 24 (10.2%) | 28 (11.9%) |
| Lunch | 193 (82.1%) | 19 (8.1%) | 23 (9.8%) |
| Dinner | 185 (78.7%) | 18 (7.7%) | 32 (13.6%) |
III.3.3. FN9-FN15. Changes in food groups
| Group | Does not consume | Same | Increased | Decreased | DK/NA |
|---|---|---|---|---|---|
| Fruits and vegetables | 7 | 158 | 49 | 19 | 2 |
| Legumes | 10 | 179 | 31 | 14 | 1 |
| Dairy products | 12 | 166 | 26 | 30 | 1 |
| Starches | 2 | 176 | 28 | 28 | 1 |
| Meat or eggs | 1 | 170 | 38 | 25 | 1 |
| Foods/beverages that are sources of sugar | 42 | 109 | 27 | 56 | 1 |
| Fats and fast foods | 33 | 115 | 23 | 63 | 1 |
A change in frequency does not by itself have a nutritional sign. Reducing sugary drinks or fast food does not have the same meaning as reducing fruits, vegetables, or protein sources. Any index of “diet deterioration” must therefore rest on an explicit nutritional rule rather than on the simple operation “decreased = worsened.”
III.3.4. FN17. Hours of sleep during the pandemic
| Change | n | % |
|---|---|---|
| Increased | 35 | 14.9 |
| Remained the same | 134 | 57.0 |
| Decreased | 63 | 26.8 |
| DK/NA | 3 | 1.3 |
The data do not show that 57% slept more: 35 people —14.9%— reported an increase in hours of sleep, while 63 —26.8%— reported a decrease and 134 —57.0%— stability. The 57% figure corresponds to “remained the same.”
III.3.5. FN18. Physical activity
| Change | n | % |
|---|---|---|
| Increased | 61 | 26.0 |
| Remained the same | 110 | 46.8 |
| Decreased | 57 | 24.3 |
| DK/NA | 7 | 3.0 |
Physical activity increased for 61 people —26.0%— and decreased for 57 —24.3%—.
III.4. E module: virtual education
E6 has 161 applicable responses and 74 nonapplicable cases.
| Reason | n | % of 161 applicable cases |
|---|---|---|
| Insufficient time | 27 | 16.8 |
| Insufficient money | 11 | 6.8 |
| Not interested in training | 59 | 36.6 |
| Lacks computer skills | 8 | 5.0 |
| Low motivation | 6 | 3.7 |
| Virtual environment is boring | 1 | 0.6 |
| Poor time organization | 5 | 3.1 |
| Repeatedly postpones starting | 1 | 0.6 |
| Virtual environment is uncomfortable | 4 | 2.5 |
| Does not want to start alone | 1 | 0.6 |
| Online education is too expensive | 1 | 0.6 |
| Other | 22 | 13.7 |
| DK/NA | 15 | 9.3 |
Lack of money was reported by 11 people, 6.8% of applicable cases and 4.7% of the entire sample. Lack of time was reported by 27, 16.8% of applicable cases and 11.5% of the total. The denominator must be stated: using 235 describes prevalence in the full sample; using 161 describes the composition of those who actually received E6.
IV. GENERAL DESIGN OF THE INFERENTIAL METHODOLOGY
IV.1. Information of interest
The analytical design sought to extract or construct information on age; internet access; geographic location; nationality; barriers to virtual education; relation to social wealth; changes in diet, hydration, sleep, and physical activity; variation in income; sex; and household economic sufficiency. The intention was to study jointly dimensions that, although separated in the questionnaire for operational reasons, are materially related.
Transforming some responses into dichotomous variables is useful for binary models, but every dichotomization sacrifices information. Binary variables are therefore treated as analytical constructions rather than ontological substitutes for the continuous or multinomial phenomena from which they arise.
IV.2. Measurement mechanism and operationalization
- Age: SD2, retained quantitatively whenever
possible; for some models
adult25 = 1is also constructed if the person is 25 years of age or older. - Nationality: SD3; Costa Rican/non-Costa Rican is distinguished and DK/NA is treated as missing.
- Sex: SD1.
- Fixed internet: TC1.
- Rural/urban location: the design intended to construct it from SD13 and INEC’s geographic classification. That classification was not completed during the exercise and therefore does not enter the models actually estimated.
- Observed property-capital: AE6, according to the
substantive definition given above.
1if the source exists —increased, decreased, or remained unchanged—;0if the person states that it is not a source;NAif there is no response. - Occupational position/business ownership: TE1 is retained as a separate variable. Employer, independent producer, and wage worker are not collapsed into a single indicator of “capital.”
- Income contraction: may be defined as the existence of at least one decrease in AE3-AE9 or a decrease in the income of another household member in AE10. AE11 should not be mechanically included in this indicator because it measures current sufficiency, not temporal change.
- Monthly economic stress: AE11, retained ordinally or dichotomized only when the objective requires it.
- Barriers to virtual education: E6 is analyzed among applicable cases. It cannot simply be converted into “access/no access” for all 235 people, because absence generated by a skip has a different meaning from a negative response.
- Diet: FN6-FN15 require differentiated substantive rules by food type. A decrease is not necessarily negative, and an increase is not necessarily positive.
- Hydration: FN2.
- Sleep: FN17 and the level of hours in FN16, where relevant.
- Physical activity: FN18.
IV.3. Dichotomous working variables
To reproduce the core models, the following variables are defined:
VD1: nationality, 1 = non-Costa Rican, 0 = Costa Rican.VD2: observed presence of property-capital income according to AE6.VD4: sex, 1 = woman, 0 = man.VD7: 1 = age 25 or older, 0 = younger than 25.VD8: income contraction under the explicit rule defined in IV.2.
The rurality variable remains a design proposal rather than an estimated variable. The barrier to virtual education is used descriptively unless the analytical universe is restricted to cases for which E6 applies.
IV.4. Proposed combined analyses
The first model studies the observed presence of property-capital income as a function of sex, age, and nationality:
\[ VD2_i = f(VD4_i,VD7_i,VD1_i). \]
Rurality is not included because it was not constructed reproducibly.
A second analysis could study income contraction in relation to sex, age, nationality, and barriers to virtuality, but only after precisely defining the E6 universe and the contraction variable. It is therefore retained as an analytical extension rather than being confused with the model actually estimated in Section IX.
IV.5. Correlation and causality
Correlation can describe covariation; it does not by itself transform an association into a causal mechanism. In social research, causal interpretation requires substantive theory, temporality, design, and identification assumptions that are not automatically contained in a coefficient.
Ritchey uses examples involving poverty, racial composition, and crime to show how an aggregate association may reflect institutional history, segregation, economic exclusion, and omitted variables. The methodological argument is not to replace one correlation with another monocausal explanation, but to remember that the coefficient does not contain the entire causal structure of the phenomenon.
The same caution applies to contemporary racial categories. Findings on the African origin of modern human lineages and later evidence of admixture with archaic populations do not turn social categories of race into discrete biological units capable of replacing historical and causal analysis. Regression quantifies relations under a model; causality requires an additional theory of how the phenomenon is produced.
V. FOUNDATIONS OF SAMPLE SURVEYS
V.1. Mathematical statistics, estimation, and surveys
Cochran emphasizes that survey theory historically adopted simple and robust procedures because a single survey may contain many attributes with different distributions. This does not imply a separation between sampling theory and regression: ratio and regression estimators use auxiliary information to improve precision.
It is useful, however, to distinguish two objects:
\[ \text{regression estimator in sampling} \neq \text{regression model fitted to survey variables}. \]
The former uses known auxiliary information to improve estimation of a population mean or total; the latter represents a conditional relationship among variables and may serve inferential or predictive purposes. The fact that both use the word “regression” does not make their objectives identical.
V.2. Sample size and the actual role of the Central Limit Theorem
A reader could quite reasonably believe that using p=0.5
in a sample-size formula is justified because, as n
increases, the original responses “become normal,” eventually distribute
themselves symmetrically, and therefore half must fall in each category.
That is not the case.
For a Bernoulli variable X_i taking values 0 and 1, the
sample proportion is:
\[ \hat p=\frac1n\sum_{i=1}^nX_i, \]
with:
\[ E(\hat p)=p, \qquad \operatorname{Var}(\hat p)=\frac{p(1-p)}n \]
under the ideal independent scheme. In sampling without replacement from a finite population there is also a finite-population correction:
\[ \operatorname{Var}(\hat p) =\frac{p(1-p)}n\frac{N-n}{N-1}. \]
The Central Limit Theorem enters elsewhere. Under appropriate conditions, it allows the sampling distribution of the standardized proportion to be approximated by a normal distribution:
\[ \frac{\hat p-p}{\sqrt{p(1-p)/n}} \approx N(0,1). \]
This is a statement about the distribution of a statistic
across repeated samples, not a claim that the original
distribution of responses itself becomes normal. Nor does it imply that
p tends to 0.5.
The reason for using p=0.5 when the population
proportion is unknown is algebraic. Bernoulli variance depends on:
\[ f(p)=p(1-p)=p-p^2. \]
Its derivative is:
\[ f'(p)=1-2p, \]
and the maximum occurs at:
\[ p=\frac12, \qquad p(1-p)=\frac14. \]
Therefore:
\[ p(1-p)\le 0.25. \]
Choosing p=0.5 maximizes the variance and yields the
most conservative sample size for a prespecified margin of error. For a
large population, or one of unknown size:
\[ n_0=\frac{z_{\alpha/2}^2p(1-p)}{d^2}. \]
With z=1.96, p=0.5, and
d=0.0639:
\[ n_0\approx235.2. \]
This gives the scale of the 235 interviews. The result makes sense as an idealized calculation of sampling precision for a proportion under SRS. By itself, it does not demonstrate that the actual design has total error of ±6.39%.
If sample size approached the size of a finite population, the factor
(N-n)/(N-1) would tend to zero. The reason is elementary:
when nearly the entire population is observed, progressively less
uncertainty remains because of sampling. The original responses do not
undergo a “normalization.”
V.3. Nonresponse and the Birnbaum-Sirken formula
Birnbaum and Sirken, as discussed by Cochran, studied bias due to nonavailability. The expression discussed in the original paper can be written, using the notation employed there, as:
\[ n=\frac{t_\alpha^2}{4d(d-W_2)W_1}-1. \]
The condition built into the formula itself shows that there is no
admissible n when W_2>d. If substitution of
a nonresponse rate larger than the tolerated error changes the sign of
the denominator and produces n<0, the result is
not a physically negative magnitude that should be repaired by taking
its absolute value. It indicates that the calculation has left
the domain in which the formula can satisfy the stated guarantee.
An analogy with the absolute value of an economic elasticity does not repair this violation of conditions. The correct conclusion is simply: the formula does not provide an admissible solution for that combination of nonresponse and tolerated error.
This point is also consistent with Cochran’s warning: substantial
amounts of nonresponse are not mechanically neutralized by increasing
sample size. If nonrespondents systematically differ from respondents,
bias may persist even with a large n.
V.4. Types of nonresponse and call dispositions
Cochran distinguishes problems such as noncoverage, temporary absence, inability to respond, and persistent refusal. In a modern telephone survey it is also useful to distinguish completed interview, partial interview, refusal, noncontact, nonresidential number, ineligible case, and unknown eligibility. Only with such final dispositions can a standardized response rate be constructed.
The ENAVIRPA fieldwork manual distinguished busy number, no answer, inactive, completed, pending, not completed, incomplete, refusal, business, and duplicate. The raw log is useful for documenting the process, but a standard rate requires the final disposition of each unit and explicit denominator rules.
V.5. Margin of error and total survey error
Under an ideal SRS, n=235, p=0.5, and 95%
confidence give:
\[ 1.96\sqrt{\frac{0.25}{235}}\approx0.0639. \]
That is, ±6.39 percentage points. This number refers to idealized sampling error. It does not automatically incorporate coverage, differential nonresponse, measurement, processing, telephone selection, weighting, or the additional uncertainty of subsequent models.
V.6. Expansion factor and weighting
The base weight of a probabilistically selected unit is the inverse of its inclusion probability:
\[ w_i=\frac1{\pi_i}. \]
In a multistage design, if a geographic unit h, a
household j within h, and a person
i within the household have conditional probabilities
f_h, f_(j|h), and f_(i|jh), the
joint probability is:
\[ f_{ijh}=f_hf_{(j|h)}f_{(i|jh)}, \]
and the basic weight is:
\[ W_{ijh}=\frac1{f_{ijh}} =\frac1{f_h}\frac1{f_{(j|h)}}\frac1{f_{(i|jh)}}. \]
Similarity between some sample and population proportions does not prove that weighting is unnecessary. The decision depends on inclusion probabilities and subsequent adjustments for nonresponse and calibration. ENAVIRPA did not reconstruct a complete weighting system; therefore its estimates are not presented as though every observation had been demonstrated to carry the same population weight.
VI. GENERALIZED LINEAR MODELS
The generalized linear model is one of the clearest examples of how a statistical theory can develop by preserving an earlier structure while simultaneously extending its domain of application. The classical linear model does not disappear: it remains contained as a special case within a more general construction. The essential idea is to preserve a linear systematic component,
\[ \eta_i=x_i^T\beta, \]
while abandoning the requirement that every response variable be Gaussian and that its mean coincide directly with the linear predictor. The conditional mean,
\[ \mu_i=E(Y_i\mid x_i), \]
is connected to the predictor through a link function:
\[ g(\mu_i)=\eta_i. \]
In this way, Gaussian linear regression, logistic regression, Poisson count models, and certain gamma specifications can be studied within a common framework.
VI.1. Preliminary concepts: variables, scales, and predictors
A traditional classification of measurement scales distinguishes nominal, ordinal, interval, and ratio variables. The distinction between discrete and continuous, however, belongs to a different axis. Number of children, for example, is discrete but has a meaningful zero and interpretable ratios; it can therefore be regarded as a discrete variable on a ratio scale. It is not appropriate to turn “discrete/continuous” into additional levels of the nominal-ordinal-interval-ratio hierarchy.
The word covariate also deserves clarification. Some applied traditions used it in a restricted sense for continuous predictors. In modern regression theory it is clearer to use it broadly: a covariate or predictor may be continuous, discrete, binary, or categorical through appropriate coding. This is different from covariance, which denotes a measure of association between variables.
The word factor likewise depends on context. In experimental design it may denote a controlled or explanatory categorical variable; in factor analysis it denotes a latent construct. Neither meaning should be inferred solely from the name assigned to a column by a software package.
These clarifications matter because the model is not determined by the computer format of a variable, but by the mathematical and probabilistic structure of the phenomenon one wishes to represent.
VI.2. Genetic connection with linear regression
Gujarati and Porter recall that the term regression originated in Galton’s work on the heights of parents and children. Its contemporary meaning is much broader: the aim is to represent how the distribution of a response —and very often its conditional mean— changes when one or more predictors change.
In the simple linear model:
\[ E(Y_i\mid x_i)=\alpha+\beta x_i. \]
In matrix form:
\[ \mu=X\beta. \]
The fitted line is not merely a geometric object superimposed on points. Its coordinates represent observed magnitudes, and its parameters acquire statistical meaning from a probabilistic specification. This distinction allows us to separate geometric fitting from a statistical model, even when both share mathematical tools.
VI.2.1. Regression and causality
Regression does not automatically transform an association into causality. A coefficient can quantify a conditional relationship under a set of assumptions without identifying, by itself, the mechanism that produces it. Causal interpretation requires substantive theory, temporal structure, design, interventions, or additional identification assumptions.
Ritchey uses examples involving poverty, racial composition, and crime to show that an aggregate correlation may condense institutional history, segregation, economic exclusion, selection, and omitted variables. The methodological point is not to replace a bivariate association with another monocausal explanation; it is to deny that the coefficient contains, by itself, the totality of the causal process.
The same caution applies to contemporary racial categories. Genetic evidence concerning a recent African origin of modern human lineages and later admixture with archaic populations does not transform social racial categories into discrete biological units that can replace historical analysis. Regression measures relations under a representation; causal explanation requires reconstructing how those relations are produced.
VI.3. Regression and least squares are not synonyms
Three objects should be distinguished: model, estimation criterion, and numerical algorithm. In the classical Gaussian model:
\[ Y=X\beta+\varepsilon, \qquad \varepsilon\sim N(0,\sigma^2I), \]
maximum-likelihood estimation of \(\beta\) coincides with minimizing:
\[ S_2(\beta)=\sum_{i=1}^n(y_i-x_i^T\beta)^2 =\|y-X\beta\|_2^2. \]
This is the source of the close historical relation between linear regression and least squares. But regression can use other criteria —absolute deviations, robust losses, penalization— and least squares can also be used in problems that do not seek to construct a complete probabilistic model. The coincidence in the Gaussian case does not justify identifying the two concepts.
VI.4. Geometric digression: norms, metrics, convexity, and discrepancy
Geometry helps explain why least squares has such a natural form. If
\[ e=y-X\beta, \]
OLS minimizes \(\|e\|_2^2\). In a finite-dimensional vector space, for \(p\ge1\),
\[ \|x\|_p=\left(\sum_i|x_i|^p\right)^{1/p} \]
is a norm and induces the metric
\[ d(x,y)=\|x-y\|_p. \]
The logical relation should not, however, be reversed: not every metric is induced by a norm, and a topology does not by itself determine a unique distance. Topological structure determines which sets are open and which notions of continuity are preserved; metric structure adds further information about distance.
Convexity should likewise not be confused with subadditivity and positive homogeneity. A function \(F\) is convex when
\[ F(\lambda x+(1-\lambda)y) \le \lambda F(x)+(1-\lambda)F(y), \qquad 0\le\lambda\le1. \]
Norms are convex and satisfy additional properties, but those properties are not the general definition of convexity.
McCullagh and Nelder use discrepancy in a broader sense than metric distance. In least squares, discrepancy has an immediate Euclidean interpretation. In a GLM, by contrast, a central measure is the deviance:
\[ D=2\{\ell(\text{saturated model})-\ell(\text{fitted model})\}. \]
Deviance arises from log-likelihoods and need not satisfy the axioms of a metric. The geometric intuition can be preserved —searching within a class for a representation that disagrees as little as possible with the data under a criterion— but the criterion need not be an \(L_p\) norm.
VI.5. Exponential families
Nelder and Wedderburn identified a class of distributions broad enough to contain several models of interest and structured enough to support a common theory. A standard form of an exponential dispersion family is:
\[ f(y_i;\theta_i,\phi) = \exp\left\{ \frac{y_i\theta_i-b(\theta_i)}{a(\phi)} +c(y_i,\phi) \right\}. \]
Here \(\theta_i\) is the natural or canonical parameter and \(\phi\) the dispersion parameter. Under the usual regularity conditions:
\[ E(Y_i\mid x_i)=b'(\theta_i)=\mu_i, \]
\[ \operatorname{Var}(Y_i\mid x_i)=a(\phi)b''(\theta_i). \]
In standard GLM notation this is summarized as:
\[ \operatorname{Var}(Y_i\mid x_i)=\phi V(\mu_i), \]
apart from known weight factors introduced by particular parameterizations. The function \(V(\mu)\) is the variance function. This expression displays an essential generalization: in the homoskedastic Gaussian model variance may be constant, whereas in Bernoulli and Poisson models it depends systematically on the mean.
For example:
| Family | Mean | Variance function \(V(\mu)\) |
|---|---|---|
| Gaussian | \(\mu\in\mathbb R\) | \(1\) |
| Bernoulli | \(0<\mu<1\) | \(\mu(1-\mu)\) |
| Poisson | \(\mu>0\) | \(\mu\) |
| Gamma | \(\mu>0\) | \(\mu^2\) |
VI.6. The three components of a GLM
VI.6.1. Stochastic component
The response belongs to an exponential family. A standard GLM generally works with conditionally independent responses:
\[ Y_i\mid x_i\sim\mathcal F(\mu_i,\phi). \]
This does not require identical distributions in the sense of sharing the same mean, because
\[ \mu_i=g^{-1}(x_i^T\beta) \]
may vary from one observation to another.
That statement should be distinguished from a different historical observation by McCullagh and Nelder. In discussing general principles of discrepancy, the authors state that observations should be independent or at least interchangeable in some sense that permits impartial treatment. That formulation belongs to their conceptual framework and is not equivalent to requiring equality of all conditional means in a regression.
VI.6.2. Systematic component
The predictors generate:
\[ \eta_i = \beta_0+\beta_1x_{i1}+\cdots+\beta_px_{ip} = x_i^T\beta. \]
The relevant linearity is linearity in the parameters. Thus,
\[ \eta=\beta_0+\beta_1x+\beta_2x^2 \]
is nonlinear in \(x\) but remains linear in \(\beta_0,\beta_1,\beta_2\).
VI.6.3. Link function
The mean and the predictor are connected through:
\[ g(\mu_i)=\eta_i, \qquad \mu_i=g^{-1}(\eta_i). \]
The link makes it possible to model the mean on a scale appropriate to its domain. A probability must remain between 0 and 1; a Poisson mean must be positive. The transformation allows the linear predictor to operate on a more convenient scale without violating these restrictions.
VI.7. Identity link and canonical link
The identity link is:
\[ g(\mu)=\mu, \]
and only in that case:
\[ \mu=\eta. \]
A canonical link means something different: \(g\) is chosen so that the linear predictor coincides with the natural parameter of the family:
\[ \boxed{\eta_i=\theta_i}. \]
Thus identity is the canonical link for the Gaussian, logit for the binomial, and log for the Poisson. For Gamma, the canonical link is inverse, with the sign convention depending on the parameterization.
| Distribution | Canonical link |
|---|---|
| Gaussian | \(g(\mu)=\mu\) |
| Bernoulli/Binomial | \(g(\mu)=\log[\mu/(1-\mu)]\) |
| Poisson | \(g(\mu)=\log\mu\) |
| Gamma | \(g(\mu)\propto1/\mu\) |
The canonical link has algebraic advantages, but it is not compulsory. A binomial response may use probit instead of logit if the theoretical or empirical construction justifies it.
VI.8. Maximum likelihood
Parameters are normally estimated by maximizing:
\[ \ell(\beta)=\sum_{i=1}^n\ell_i(\beta). \]
In general the score equations,
\[ U(\beta)=\frac{\partial\ell}{\partial\beta}=0, \]
do not admit a closed-form algebraic solution. This leads to iterative procedures.
VI.9. IRLS: distinguishing two algorithms that share a name
There is a family of algorithms called iteratively reweighted least squares used for \(L_p\) losses, approximations to least absolute deviations, and robust regression. In that setting weights such as
\[ w_i\propto|e_i|^{p-2} \]
may appear. The formulation discussed by Burrus belongs to this context. It is a legitimate IRLS algorithm, but it does not explain the IRLS ordinarily used to fit GLMs.
In GLMs, IRLS arises from applying Fisher scoring to the log-likelihood; with canonical links there is an especially close relationship with Newton-Raphson. The conceptual sequence is:
\[ \text{exponential family} \rightarrow \text{log-likelihood} \rightarrow \text{score} \rightarrow \text{Fisher information} \rightarrow \text{Fisher scoring} \rightarrow \text{IRLS}. \]
VI.9.1. Score and Fisher information
Let
\[ \eta_i=x_i^T\beta, \qquad \mu_i=g^{-1}(\eta_i). \]
The score can be written, omitting parameterization details that do not alter the central idea, as:
\[ U(\beta) = X^T \operatorname{diag}\left( \frac{d\mu_i/d\eta_i}{\phi V(\mu_i)} \right) (y-\mu). \]
The expected information takes the form:
\[ \mathcal I(\beta)=X^TWX, \]
with working weights:
\[ \boxed{ w_i = \frac1\phi \frac{(d\mu_i/d\eta_i)^2}{V(\mu_i)} }. \]
When \(1/\phi\) is a common factor it can be omitted when updating \(\beta\).
VI.9.2. Working response
At iteration \(t\):
\[ \eta_i^{(t)}=x_i^T\beta^{(t)}, \qquad \mu_i^{(t)}=g^{-1}(\eta_i^{(t)}). \]
The first-order linear approximation leads to the working response:
\[ \boxed{ z_i^{(t)} = \eta_i^{(t)} + g'(\mu_i^{(t)})(y_i-\mu_i^{(t)}) }. \]
Since \(g'(\mu)=d\eta/d\mu\), it may also be written:
\[ z_i^{(t)} = \eta_i^{(t)} + \frac{y_i-\mu_i^{(t)}}{d\mu_i/d\eta_i}. \]
VI.9.3. Weighted step
The update is obtained by solving:
\[ \boxed{ \beta^{(t+1)} = (X^TW^{(t)}X)^{-1}X^TW^{(t)}z^{(t)} }. \]
Hence the name of the algorithm: at each iteration a weighted least-squares problem is solved, but the weights and the working variable change because they depend on the estimated mean at the current iteration.
The procedure can be summarized as follows:
- choose admissible initial values;
- compute \(\eta^{(t)}\);
- obtain \(\mu^{(t)}=g^{-1}(\eta^{(t)})\);
- construct \(W^{(t)}\);
- construct \(z^{(t)}\);
- solve the weighted problem;
- repeat until a convergence criterion is satisfied.
Three cases show the unity of the method:
| Model | \(d\mu/d\eta\) | \(V(\mu)\) | Weight apart from scale |
|---|---|---|---|
| Gaussian + identity | \(1\) | \(1\) | constant |
| Poisson + log | \(\mu\) | \(\mu\) | \(\mu\) |
| Binomial + logit | \(\mu(1-\mu)\) | \(\mu(1-\mu)\) | \(\mu(1-\mu)\) |
The Gaussian case reveals the connection with OLS: because the weights are constant, the iteration reduces to the ordinary linear problem.
VI.10. What does not explain IRLS convergence
It may be tempting to think that reweighting “brings” observations closer together, reduces predictor variance, and that the Central Limit Theorem makes the algorithm converge toward a normal distribution. That does not happen. The weights depend on conditional variance and the derivative of the link; they do not physically move the values of \(X\) or force \(\operatorname{Var}(X)\to0\).
The CLT appears elsewhere in the theory: under regularity conditions it contributes to the asymptotic normal approximation of maximum-likelihood estimators. That is an inferential property of sequences of estimators, not the numerical mechanism of IRLS.
Nor is it sufficient to write
\[ \beta^{(t+1)}=F(\beta^{(t)}) \]
to invoke Banach’s fixed-point theorem. That theorem requires proving that \(F\) is a contraction on an appropriate complete space. The mere existence of an iteration does not prove contractivity. In practice, GLMs may exhibit convergence problems due to poor numerical conditioning, collinearity, separation, boundary solutions, or problematic specifications.
VI.11. Sufficient statistics under a canonical link
When
\[ \theta_i=\eta_i=x_i^T\beta, \]
the part of the log-likelihood jointly linking \(y\) and \(\beta\) contains:
\[ \frac1{a(\phi)}\beta^TX^Ty. \]
For fixed dispersion and under the usual conditions of an exponential family, the relevant dependence of the sample on \(\beta\) appears through \(X^Ty\). This explains the sufficient-statistic structure emphasized in classical GLM theory. In canonical log-linear models with factors, the score equations may additionally imply equality between certain observed and fitted margins; this is a property of those specifications, not a universal rule for every link.
The conceptual unity can finally be summarized as:
\[ \boxed{ \text{probability family} + \text{linear predictor} + \text{link function} }. \]
The generalization does not consist in erasing differences among distributions, but in identifying which structure can remain while their particular determinations change systematically.
VII. PROBIT AND LOGIT MODELS
Probit and logit models arise when the response is binary and the immediate object is to model a conditional probability:
\[ p_i=P(Y_i=1\mid x_i). \]
The problem with the linear probability model is that \(x_i^T\beta\) can take any real value, whereas a probability must remain in \([0,1]\). Probit and logit links solve this incompatibility by transforming the probability onto an unrestricted scale.
VII.1. Probit model
The probit uses the standard normal distribution function:
\[ \Phi^{-1}(p_i)=x_i^T\beta, \]
so that:
\[ p_i=\Phi(x_i^T\beta). \]
The observed response remains Bernoulli; the normal distribution appears in the link function or, equivalently, in a latent-variable interpretation in which an unobserved normal variable crosses a threshold and generates the 0/1 response. It should therefore not be claimed that the observed binary variable is normal.
One may imagine:
\[ Y_i^*=x_i^T\beta+u_i, \qquad u_i\sim N(0,1), \]
\[ Y_i=1\quad\text{if}\quad Y_i^*>0, \]
which yields precisely \(P(Y_i=1\mid x_i)=\Phi(x_i^T\beta)\).
VII.2. Logit model
The logit uses:
\[ \operatorname{logit}(p_i) = \log\left(\frac{p_i}{1-p_i}\right) = x_i^T\beta. \]
The odds satisfy:
\[ \frac{p}{1-p}\in(0,\infty), \]
whereas their logarithm ranges over the entire real line. Inverting the link:
\[ p_i = \frac{1}{1+\exp(-x_i^T\beta)}. \]
The general logistic function can be written:
\[ f(x)=\frac{L}{1+e^{-k(x-x_0)}}, \]
with asymptotes 0 and \(L\) and central symmetry around \((x_0,L/2)\). In ordinary binary regression one takes \(L=1\).
VII.2.1. Interpretation of coefficients
In logit, a coefficient \(\beta_j\) represents the change in log-odds associated with a one-unit increase in \(x_j\), holding the other covariates constant. Therefore:
\[ e^{\beta_j} \]
is the multiplicative odds ratio associated with that change. An odds ratio greater than 1 implies increased odds; less than 1, reduced odds; equal to 1, no multiplicative change.
This should not be confused with a constant marginal effect on probability. Since
\[ p(x)=\Lambda(x^T\beta), \]
the marginal effect of a continuous covariate is:
\[ \frac{\partial p}{\partial x_j} = \beta_jp(1-p), \]
so it depends on the individual’s position on the logistic curve.
VII.3. Probit and logit: similarities and differences
Both links are sigmoidal, monotonic, and yield admissible probabilities. Their results are often qualitatively similar in many applications; their coefficients, however, are not on the same scale. Logit has a particularly convenient interpretation through odds ratios; probit is naturally connected to a normal latent-variable formulation.
The choice should not be reduced to habit. It may depend on disciplinary tradition, interpretability, substantive assumptions, fit comparison, or computational convenience.
VII.4. Inference
Maximum likelihood yields \(\hat\beta\). Under regularity conditions, the inverse information matrix approximates the covariance matrix of the estimators. An individual Wald test uses:
\[ z_j=\frac{\hat\beta_j}{SE(\hat\beta_j)}. \]
Likelihood-ratio tests compare nested models through:
\[ LR=2\{\ell(\hat\beta_1)-\ell(\hat\beta_0)\}. \]
The AIC criterion is:
\[ AIC=-2\ell(\hat\beta)+2k. \]
These quantities answer different questions. An individual p-value does not summarize predictive ability; an AIC does not prove causality; and a model that classifies reasonably well does not automatically make all of its coefficients well-identified parameters.
VII.5. Separation and unstable estimates
In binary regression, complete separation may occur when a combination of predictors perfectly classifies the cases, or quasi-complete separation when separation occurs except for some overlaps. Under those conditions, ordinary maximum likelihood may drive some coefficients toward very large magnitudes; Wald standard errors grow and conventional inference ceases to be reliable.
Thus enormous coefficients accompanied by enormous standard errors should not simply be interpreted as “very large but nonsignificant effects”: they may be a geometric symptom of separation or extremely sparse cells. Possible responses include reviewing coding, simplifying categories when substantively defensible, obtaining more observations, penalization, or bias-reduction methods such as Firth’s correction.
VIII. STATISTICAL LEARNING THEORY
VIII.1. General definition
Following James, Witten, Hastie, and Tibshirani, an elementary representation of supervised learning is:
\[ Y=f(X)+\varepsilon. \]
The problem is to estimate the unknown function \(f\) from the data. In some problems the main interest is predicting new observations; in others, understanding which variables are associated with the response and how; in many cases both goals coexist.
The expression learning from data does not mean dispensing with theory. Every choice of variables, representation, functional class, loss, and validation procedure contains decisions about which regularities are regarded as possible and relevant.
Historically, statistics developed a tradition particularly concerned with probability models, estimation, uncertainty, and inference, whereas machine learning emerged under a strong influence from computer science, algorithms, and predictive performance. This difference helps explain cultural emphases, but it does not establish an essential boundary. Statistics predicts, and machine learning uses probability and inference.
Nor is it correct to say that machine-learning methods “make few assumptions” in an absolute sense. Many shift assumptions from an explicit parametric form toward an inductive bias: hypothesis class, architecture, loss function, regularization, invariances, and training rules.
A hypothesis space or class can be written:
\[ \mathcal H=\{h:X\rightarrow Y\}. \]
It is not the same object as the \(H_0\) and \(H_1\) hypotheses of Neyman-Pearson. There is a very broad logical kinship —delimiting possibilities— but the mathematical objects and inferential problems are different.
VIII.2. Learning paradigms
In an elementary classification:
- supervised learning: pairs \((x_i,y_i)\) are observed and the aim is to learn a relation that predicts \(y\) from \(x\);
- unsupervised learning: \(x_i\) are observed without an explicit supervising response, and patterns or representations are sought;
- reinforcement learning: an agent interacts with an environment through states, actions, and rewards.
Online learning belongs to another axis. It describes a procedure that updates the model as observations arrive. There can be supervised online learning, unsupervised online learning, and so forth.
In unsupervised learning, clustering is only one possibility. Others include dimensionality reduction, density estimation, anomaly detection, association rules, and representation learning.
VIII.3. Binary classification
If the positive class is the event of interest, there are four possibilities:
- true positive (TP): actual positive, predicted positive;
- false positive (FP): actual negative, predicted positive;
- true negative (TN): actual negative, predicted negative;
- false negative (FN): actual positive, predicted negative.
The confusion matrix organizes these cases:
| Predicted negative | Predicted positive | |
|---|---|---|
| Actual negative | TN | FP |
| Actual positive | FN | TP |
The matrix may be computed on training, validation, test, or external data. When it is computed on the same cases used to estimate the model, it describes in-sample performance.
VIII.4. Classification metrics
Accuracy is:
\[ Accuracy=\frac{TP+TN}{TP+TN+FP+FN}. \]
The error rate is its complement:
\[ Error=\frac{FP+FN}{N}=1-Accuracy. \]
Sensitivity or recall is:
\[ Sensitivity=\frac{TP}{TP+FN}, \]
and measures the proportion of actual positives detected.
Specificity is:
\[ Specificity=\frac{TN}{TN+FP}. \]
Classification precision, also called positive predictive value, is:
\[ Precision=\frac{TP}{TP+FP}. \]
Negative predictive value is:
\[ NPV=\frac{TN}{TN+FN}. \]
A terminological ambiguity should be avoided: classification precision is not metrological precision understood as low dispersion among repeated measurements. They are different concepts that share a word.
Accuracy can be misleading with imbalanced classes. If 90% of cases belong to the negative class, a classifier that always answers “negative” obtains 90% accuracy and yet has zero sensitivity. Every evaluation should therefore be compared with a baseline and with metrics consistent with the scientific cost of errors.
VIII.5. Training error and generalization error
For a classifier \(\hat f\), the observed error on the training data is:
\[ \widehat{Err}_{train} = \frac1n\sum_{i=1}^nI(y_i\ne\hat y_i). \]
But the predictive objective is not to memorize already observed data. What matters is performance on a new observation \((X_0,Y_0)\):
\[ Err_{test} = E\left[I\{Y_0\ne\hat f(X_0)\}\right]. \]
The difference is fundamental. A highly flexible model may fit the training data extraordinarily well and fail on new observations. This is overfitting. Test sets, cross-validation, or other procedures are used to estimate generalization while preventing the algorithm from being evaluated only on cases it already used to learn.
VIII.6. Probabilities, thresholds, and classification
A probabilistic model such as logit produces \(\hat p_i\), not logically necessary classes. To classify, a threshold \(c\) must be chosen:
\[ \hat Y_i=I\{\hat p_i>c\}. \]
Changing \(c\) changes the confusion
matrix. Lowering the threshold usually detects more positives and raises
sensitivity, but it may also produce more false positives and reduce
specificity. Thus 0.5 is not a sacred value, and
0.25 cannot be adopted without explanation either. The
choice should follow costs, prevalence, the study objective, or a rule
defined on validation data, not the value that produces the most
favorable appearance on the training sample.
ROC curves examine sensitivity against the false-positive rate across all thresholds. In problems with a rare positive class, precision-recall curves may be especially informative because they display directly the tradeoff between positive detection and the purity of positive predictions.
VIII.7. GLMs and supervised learning
GLMs are historically statistical models. Nevertheless, when fitted to \((X,Y)\) pairs to predict new responses they also function as supervised-learning procedures. Bayesian treatment is not what creates this status: a frequentist, Bayesian, or penalized GLM may be used predictively.
Logistic regression is the clearest example. It models:
\[ \log\left( \frac{P(Y=1\mid X)}{1-P(Y=1\mid X)} \right) =X\beta. \]
By its structure, it is a probabilistic regression model. But its probabilities can legitimately be converted into classes through a threshold. There is no contradiction:
\[ \boxed{ \text{logistic regression = probabilistic regression model} } \]
and simultaneously:
\[ \boxed{ \text{it can be used as a supervised classifier} }. \]
The historical origin of the method explains its construction, but does not exhaust all of its later scientific uses.
VIII.8. Inference and prediction are not two different models
Different questions can be asked of the same logit. From an inferential perspective: how much does the conditional association change with each covariate? How uncertain is the coefficient? Which model is compatible with the data? From a predictive perspective: what probability does it assign to an unseen case? Does it discriminate better than a baseline? What errors does it make out of sample?
These questions require different diagnostics, but they do not automatically turn logit into two algorithms. The same fit can be studied for both inferential and predictive properties. This is precisely why an individual coefficient may be imprecise while a combination of predictors still has some predictive utility; or, conversely, a model may contain statistically detectable associations yet discriminate new cases poorly.
The ENAVIRPA evaluation that follows deliberately keeps the two questions separate.
IX. REPRODUCIBLE INFERENTIAL RESULTS
IX.1. Analytical database and coding audit
The ENAVIRPA2021csv.csv database contains 235 rows and
161 variables. AE1 contains 56 “SÍ” and 179 “NO”. In AE2A-AE2D, the 179
cases excluded by the AE1 skip appear as NA, confirming
that they must be classified as not applicable rather
than DK/NA.
AE3-AE9 already appear in the database as textual labels. The visible
discrepancy between the questionnaire codes 4-3-2-1 and the
1-2-3-4 order used in some presentation tables therefore
ceases to affect reproducibility: categories are processed by name.
IX.2. Main variable: property-capital income
AE6 contains:
- 192 cases “No es una fuente de ingresos/apoyo”;
- 21 “Sin cambios”;
- 13 “Disminuyó”;
- 5 “Aumentó”;
- 4 “No responde”.
The main binary variable is therefore defined with 39 positive cases, 192 negative cases, and four missing cases. After also removing four missing ages and one DK/NA nationality, the complete model sample consists of 227 observations: 39 positive and 188 negative.
IX.3. Correlations among the model’s binary variables
With capital=1 for presence of the AE6 source,
mujer=1, adulto25=1, and
extranjero=1, the Pearson correlation matrix —equivalent to
the phi coefficient when both variables are binary— is:
| Variable | capital | adult25 | female | foreign |
|---|---|---|---|---|
| capital | 1.000 | 0.011 | -0.070 | -0.011 |
| adult25 | 0.011 | 1.000 | 0.145 | 0.056 |
| female | -0.070 | 0.145 | 1.000 | 0.009 |
| foreign | -0.011 | 0.056 | 0.009 | 1.000 |
The associations are small in magnitude. This anticipates that a model using these three predictors will have little ability to explain variation in the AE6 indicator within this sample.
IX.4. Logit model
The estimated model is:
\[ \operatorname{logit}[P(VD2_i=1)] =\beta_0+\beta_1Woman_i+\beta_2Adult25_i+\beta_3Foreign_i. \]
| Term | Coef. | SE | z | p | OR | 95% CI for OR |
|---|---|---|---|---|---|---|
| Intercept | -1.5250 | 0.5578 | -2.734 | 0.006 | 0.218 | [0.073, 0.649] |
| Woman (1 = woman) | -0.3893 | 0.3563 | -1.093 | 0.275 | 0.678 | [0.337, 1.362] |
| Age ≥ 25 | 0.1895 | 0.5838 | 0.324 | 0.746 | 1.209 | [0.385, 3.795] |
| Foreign (1 = non-Costa Rican) | -0.1149 | 0.6576 | -0.175 | 0.861 | 0.891 | [0.246, 3.235] |
The model contains 227 observations, a log-likelihood of
-103.51, a null log-likelihood of
-104.13, McFadden’s pseudo-R² of
0.0060, and a joint likelihood-ratio test with
p=0.740. None of the three predictors provides individual
statistical evidence of an association different from zero at
conventional levels in this specification.
Unlike the operationalization based on TE1 business ownership, the AE6 indicator does not produce explosive coefficients or standard errors measured in thousands of units. This difference confirms that construct specification and cell distribution can radically alter the numerical behavior of a model.
IX.5. Probit model
| Term | Coef. | SE | z | p | 95% CI for coef. |
|---|---|---|---|---|---|
| Intercept | -0.9099 | 0.3095 | -2.940 | 0.003 | [-1.517, -0.303] |
| Woman (1 = woman) | -0.2161 | 0.1988 | -1.087 | 0.277 | [-0.606, 0.174] |
| Age ≥ 25 | 0.0952 | 0.3200 | 0.297 | 0.766 | [-0.532, 0.722] |
| Foreign (1 = non-Costa Rican) | -0.0653 | 0.3631 | -0.180 | 0.857 | [-0.777, 0.646] |
The probit leads to the same substantive conclusion: sex, dichotomized age, and nationality together have very little explanatory ability for the observed property-capital income indicator in AE6. Logit and probit use different link scales, so their coefficients should not be compared one by one in magnitude.
IX.6. Rurality and other planned predictors
Rurality appeared in the conceptual design but was not constructed during the available period. It would not be methodologically correct to include it by pretending that a textual locality is already a rural/urban classification. INEC classifies geographic units using specific criteria; until that classification is applied reproducibly to SD13, the variable must remain outside the model.
Similarly, E6 does not provide a universal variable of “access to virtual education”: it was asked only of 161 cases according to questionnaire flow. It can be analyzed as a barrier among applicable cases or incorporated into a model restricted to that universe, but it cannot be imputed as “yes” or “no” to the 74 cases omitted by the skip.
X. PREDICTIVE EVALUATION: WHAT IT SHOWS AND WHAT IT DOES NOT SHOW
The same logistic regression can be studied from two perspectives. In inference, we ask what the coefficients and their uncertainty indicate about a modeled relationship. In prediction, we ask how well the estimated probabilities generalize to observations the algorithm did not see during fitting. These are not necessarily two different models: they can be two evaluations of the same model.
A reader might believe that it is enough to fit the logit to the 235 observations and then compute a confusion matrix on those same observations. That answers only: “how well does the model reproduce the data on which it was estimated?” It does not answer: “how well will it predict new cases?” This is the difference between in-sample performance and generalization.
Under the AE6 operationalization used here, the fitted logit
probabilities range approximately from 0.129 to 0.208.
With the threshold c=0.25, no observation exceeds the
cutoff. The resulting classifier predicts “no property-capital income”
for all 227 people:
| Metric at threshold 0.25 | Result |
|---|---|
| True positives | 0 |
| True negatives | 188 |
| False positives | 0 |
| False negatives | 39 |
| Accuracy | 82.8% |
| Sensitivity | 0.0% |
| Specificity | 100.0% |
The 82.8% accuracy is not a predictive victory: it coincides with the proportion of the majority class —82.8%— and is obtained at the cost of zero sensitivity. The model identifies no positive cases at this threshold.
This illustrates why accuracy should not be evaluated in isolation with imbalanced classes. An algorithm that always predicts the majority class can achieve high accuracy and nevertheless be useless for detecting the minority class.
The threshold is not a universal mathematical constant either. Choosing 0.25, 0.5, or another value changes the tradeoff between sensitivity and specificity. It should be defined by a cost function, a substantive need, or a validation procedure, not by post-hoc inspection of the same sample.
Finally, five-fold stratified cross-validation on these three predictors yields, as a reference, an approximate ROC AUC of 0.485 and an average precision close to 0.167. These results are compatible with virtually no discriminative ability in this specification. The pedagogical objective is not to make “classical statistics” or “machine learning” win, but to show that a predictive claim requires out-of-sample evaluation.
XI. LIMITATIONS
XI.1. Collective character of the design
The modules were designed by different members of the course and assembled for a common survey. There was no single theoretical framework determining every question from the outset. This limits later constructions that require combining items originally written for different objectives.
XI.2. Number of interviews
Three hundred interviews were planned and 235 were completed. The difference reduces precision and, above all, limits subgroup analyses and models with many categories. The issue is not that 235 is intrinsically “small”; adequacy depends on prevalence, the number of parameters, and cell structure.
XI.3. Design, coverage, and weighting
The telephone frame excludes persons outside operational coverage and may produce unequal inclusion. Complete design weights and nonresponse/calibration adjustments were not reconstructed. Results are therefore not presented as fully weighted national estimates.
XI.4. Nonresponse
The aggregate call-log data do not permit calculation of a complete
AAPOR response rate. In addition, nonresponse and noncontact may be
associated with socioeconomic conditions, so merely increasing
n does not guarantee absence of bias.
XI.5. Rurality
The rural/urban variable was conceived but not constructed. INEC assigns degrees of urbanization to specific geographic units; the work needed to link SD13 to that classification was not completed.

XI.6. Skip patterns and analysis universes
AE2, TE6, and E6 show why NA does not have a single
meaning. It may mean not applicable because of a skip, nonresponse, or
missing data. The correct denominator depends on the universe of each
question. Treating every missing value as DK/NA changes percentages and
may bias derived variables.
XI.7. Dichotomous variables
Dichotomizing age, diet, income, or economic stress simplifies modeling but sacrifices gradients. Whenever possible, original variables should be retained and dichotomies used only when justified by the model or substantive question.
XI.8. Capital as an observed variable
AE6 is an indicator of property-capital income, not an asset census. It can distinguish observed presence/absence of that source during the period, but it cannot legally verify every asset owned by a person or detect capital with no observed flow. This is an observational limitation.
XI.9. Income and poverty
SD5 records bands of gross monthly household income, not continuous equivalized disposable income. It therefore cannot directly implement the 60%-of-median-equivalized-disposable-income methodology used by the European/UNECE at-risk-of-poverty indicator.
XI.10. Causality
The study is observational and cross-sectional. Regression associations do not, by themselves, identify causal effects of sex, age, nationality, or other variables.
XI.11. Predictive evaluation
Training performance is not a measure of generalization. Any predictive claim should rely on independent test data or appropriate cross-validation and should consider class imbalance and threshold selection.
XII. CONCLUSIONS
Government support. Fifty-six people, 23.8% of the sample, reported having received support. Among them, 85.7% reported financial resources and 41.1% food. Because AE2 allows multiple responses, those percentages are calculated over eligible people and may sum to more than 100%.
Labor income. Income or earnings from paid work decreased for 37.0% of the full sample, increased for 3.8%, and remained unchanged for 38.3%.
Household income. In AE10, 44.3% reported a decrease in the income of another household member. In AE11, 34.5% indicated that family income was insufficient to live on and 47.2% that it was just enough; 17.0% stated that it was enough and allowed them to save.
Observed property-capital. For 81.7% of respondents, AE6 was not a source of income/support. In the specific sense used in this analysis, this indicates an observed absence of income derived from property-capital within the categories asked. It does not mean that an exhaustive legal inspection of assets was carried out.
Own business and independent producer. TE1 shows 33 people with an own business and no employees and 11 with an own business employing other people. Those positions should not be collapsed into one another or automatically confused with AE6.
Civil organizations. For 91.1% of the sample, support from NGOs, foundations, or nonprofit organizations was not a source of support in AE9.
International remittances. AE5 was an effective source for 28 people —17 with no change and 11 with a decrease— plus five nonresponses; 202 reported that it was not a source. Among the 28 people with a substantive response confirming the source, 39.3% reported a decrease.
Work. A total of 44.7% worked for an employer. TE6 was applicable to only 38 people; within that universe, 42.1% reported more working hours.
Health and habits. Hydration increased for 37.0%. Hours of sleep remained the same for 57.0%, decreased for 26.8%, and increased for 14.9%. Physical activity increased for 26.0% and decreased for 24.3%.
Virtual education. Among the 161 applicable E6 cases, 6.8% reported lack of money and 16.8% lack of time. Relative to all 235 interviews, these correspond to 4.7% and 11.5%, respectively.
Sample size. The value
p=0.5is used because it maximizesp(1-p)and yields a conservative calculation, not because the CLT forces responses to split 50/50. The ±6.39% is a reference sampling error under ideal SRS, not a guarantee of ENAVIRPA’s total error.Nonresponse. The 30.0546% figure computed from busy and unanswered calls does not by itself constitute a standardized response rate. The Birnbaum-Sirken formula cannot be repaired by taking an absolute value when its conditions produce an inadmissible
n.Inference on capital. Under the AE6 operationalization, logit and probit provide no evidence of a substantive association between observed property-capital income and sex, age ≥25, or nationality in the analytical sample of 227 cases.
Prediction. With the same predictors, the model has little discriminative ability. A 0.25 threshold classifies every case as negative and obtains 82.8% accuracy only because that is the majority class. Out-of-sample evaluation is indispensable.
Poverty. No “UNECE poverty rate” is presented by taking 60% of mean gross household income. The relative standard requires the median of equivalized disposable income; SD5 does not contain that variable in the required form.
Scope. ENAVIRPA 2021 is especially valuable as an exercise in applied methodology: it shows that design, skips, coding, nonresponse, operationalization, and evaluation criteria determine what can be claimed from data. Technical correction does not diminish the empirical value of the survey; it more precisely delimits its informational content.
XIII. APPENDIX A. TOPOLOGICAL DISTANCES, METRIC DISTANCES, AND COLLECTIVE BEHAVIOR
In graph theory, a graph is a pair G=(V,E). An
isomorphism between G_1 and G_2 is a bijection
f:V(G_1)→V(G_2) preserving adjacency:
\[ \{u,v\}\in E(G_1) \Longleftrightarrow \{f(u),f(v)\}\in E(G_2). \]

Preservation of adjacency implies preservation of graph distance, defined as the minimum number of edges in a path between two vertices. It does not imply preservation of Euclidean distances in a particular drawing of the graph.


Three ideas must be kept separate: graph isomorphism; topological invariance under homeomorphisms in general topology; and “topological distance” in studies of collective behavior. A homeomorphism does not in general preserve metric distances —that is the role of an isometry—. It is therefore incorrect to define a topological distance simply as a distance that remains invariant under perturbations.
In Ballerini and colleagues’ work on starling flocks, “topological distance” means neighbor rank: first neighbor, second, third, and so on. The empirical evidence indicated interaction with approximately six or seven neighbors, relatively independently of metric density. The conceptual distinction is:
- metric rule: a physical radius is kept fixed and the number of neighbors inside it changes;
- topological rule: approximately the number/rank of neighbors is kept fixed and the physical radius containing them changes.
The anisotropy of the angular distribution of neighbors made it
possible to estimate up to what rank interaction persisted; for an
isotropic distribution, the expected value of the relevant factor is
1/3. Later studies of jackdaws also showed that the regime
can change with context, with topological interactions appearing during
transit and metric interactions in other situations. The methodological
lesson is material: the relevant structure must be determined
empirically and may change with the concrete conditions of the
system.
XIV. APPENDIX B. INCOME DISTRIBUTION AND THE POVERTY CRITERION
SD5 recorded bands of total monthly household income. The database contains:
| Reported band | n | % of total |
|---|---|---|
| DK/NA | 55 | 23.4 |
| 200 thousand to less than 400 thousand | 53 | 22.6 |
| Less than 200 thousand colones | 42 | 17.9 |
| 400 thousand to less than 600 thousand | 24 | 10.2 |
| 1 million to less than 1.5 million | 18 | 7.7 |
| 600 thousand to less than 800 thousand | 17 | 7.2 |
| 1.5 million or more | 14 | 6.0 |
| 800 thousand to less than 1 million | 12 | 5.1 |
The problem is not that poverty cannot be studied with a survey, but that the available variable must be matched with a definition corresponding to what it actually measures. A reader might believe that it is enough to take 60% of national mean income and compare that amount with gross monthly household income. That is not the relative criterion used by Eurostat/UNECE.
The usual at-risk-of-poverty measure uses 60% of the median equivalized disposable income. There are three important differences:
- median, not mean;
- disposable income, not unadjusted gross income;
- equivalized, that is, adjusted for household size and composition.
SD5 records intervals of total household income and a nonresponse category. Without sufficient information to reconstruct individual equivalized disposable income and its population median, it is not methodologically legitimate to call a percentage obtained by applying 60% of mean gross income a “UNECE poverty rate.”
It is possible to describe how many households in the sample fall within each band, and AE11 may be used as an indicator of subjective income sufficiency. A future measurement compatible with the relative standard could also be designed by collecting disposable income, household composition, and the elements required for equivalization.
XV. R CODE FOR REPRODUCTION
The following code is designed to run with
ENAVIRPA2021csv.csv in the same directory as the analysis
file. The database is encoded in Windows-1252. Variable names and
categorical values remain in Spanish because they are the literal values
stored in the original database.
datos <- read.csv(
  "ENAVIRPA2021csv.csv",
  fileEncoding = "Windows-1252",
  stringsAsFactors = FALSE,
  check.names = FALSE
)

stopifnot(nrow(datos) == 235)
stopifnot(all(c("AE1","AE2A","AE2B","AE2C","AE2D",
                "AE3","AE4","AE5","AE6","AE7","AE8","AE9",
                "AE10","AE11") %in% names(datos)))
XV.1. Verification of AE1-AE2 and skip patterns
table(datos$AE1, useNA = "ifany")
table(datos$AE2A, useNA = "ifany")
table(datos$AE2B, useNA = "ifany")
table(datos$AE2C, useNA = "ifany")
table(datos$AE2D, useNA = "ifany")

# There must be 179 NAs in AE2A-AE2D because AE1=NO skips to AE3.
stopifnot(sum(is.na(datos$AE2A)) == 179)
stopifnot(sum(is.na(datos$AE2B)) == 179)
stopifnot(sum(is.na(datos$AE2C)) == 179)
stopifnot(sum(is.na(datos$AE2D)) == 179)
XV.2. AE3-AE9 tables using labels rather than numerical codes
vars_ae <- paste0("AE", 3:9)
lapply(datos[vars_ae], table, useNA = "ifany")
XV.3. Construction of the observed property-capital indicator
datos$capital <- ifelse(
  datos$AE6 == "No es una fuente de ingresos/apoyo", 0,
  ifelse(
    datos$AE6 %in% c("Disminuyó", "Aumentó", "Sin cambios"), 1, NA
  )
)

table(datos$capital, useNA = "ifany")
XV.4. Covariates and model sample
datos$edad <- suppressWarnings(as.numeric(datos$SD2))
datos$adulto25 <- ifelse(is.na(datos$edad), NA, as.integer(datos$edad >= 25))
datos$mujer <- ifelse(datos$SD1 == "Mujer", 1,
                      ifelse(datos$SD1 == "Hombre", 0, NA))
datos$extranjero <- ifelse(datos$SD3 == "No", 1,
                           ifelse(datos$SD3 == "Sí", 0, NA))

modelo <- na.omit(datos[c("capital","mujer","adulto25","extranjero")])
stopifnot(nrow(modelo) == 227)
table(modelo$capital)
cor(modelo)
XV.5. Logit and probit
fit_logit <- glm(
  capital ~ mujer + adulto25 + extranjero,
  family = binomial(link = "logit"),
  data = modelo
)

fit_probit <- glm(
  capital ~ mujer + adulto25 + extranjero,
  family = binomial(link = "probit"),
  data = modelo
)

summary(fit_logit)
summary(fit_probit)

# Odds ratios and approximate Wald confidence intervals for the logit
b <- coef(fit_logit)
se <- sqrt(diag(vcov(fit_logit)))
OR <- exp(b)
IC_OR <- cbind(exp(b - 1.96 * se), exp(b + 1.96 * se))
cbind(Coeficiente = b, EE = se, OR = OR, IC_OR)
XV.6. In-sample evaluation at threshold 0.25
p_hat <- predict(fit_logit, type = "response")
y_hat <- ifelse(p_hat > 0.25, 1, 0)
y <- modelo$capital

TP <- sum(y == 1 & y_hat == 1)
TN <- sum(y == 0 & y_hat == 0)
FP <- sum(y == 0 & y_hat == 1)
FN <- sum(y == 1 & y_hat == 0)

accuracy <- (TP + TN) / length(y)
sensitivity <- TP / (TP + FN)
specificity <- TN / (TN + FP)
precision <- if ((TP + FP) == 0) NA else TP / (TP + FP)
npv <- TN / (TN + FN)

c(TP=TP,TN=TN,FP=FP,FN=FN,
  accuracy=accuracy,sensitivity=sensitivity,
  specificity=specificity,precision=precision,npv=npv)

# Majority-class baseline
mean(y == 0)
range(p_hat)
XV.7. Five-fold stratified cross-validation
set.seed(2021)
K <- 5
fold <- rep(NA_integer_, nrow(modelo))

# Simple stratified assignment by class
for (cl in sort(unique(modelo$capital))) {
  idx <- which(modelo$capital == cl)
  fold[idx] <- sample(rep(1:K, length.out = length(idx)))
}

p_cv <- rep(NA_real_, nrow(modelo))
for (k in 1:K) {
  train <- modelo[fold != k, ]
  test  <- modelo[fold == k, ]
  fit_k <- glm(capital ~ mujer + adulto25 + extranjero,
               family = binomial(link="logit"), data=train)
  p_cv[fold == k] <- predict(fit_k, newdata=test, type="response")
}

# AUC function without additional packages (Mann-Whitney / ranks)
auc_rank <- function(y, p) {
  pos <- y == 1; neg <- y == 0
  r <- rank(p, ties.method="average")
  (sum(r[pos]) - sum(seq_len(sum(pos)))) / (sum(pos) * sum(neg))
}

auc_cv <- auc_rank(modelo$capital, p_cv)
auc_cv

# Confusion matrix at the same threshold, only as an example.
y_cv <- ifelse(p_cv > 0.25, 1, 0)
table(Real=modelo$capital, Predicho=y_cv)
XV.8. Income contraction without mixing it with AE11 sufficiency
vars_ingreso <- paste0("AE", 3:9)
disminucion_fuente <- apply(
  datos[vars_ingreso], 1,
  function(x) any(x == "Disminuyó", na.rm = TRUE)
)

datos$contraccion_ingreso <- as.integer(
  disminucion_fuente | datos$AE10 == "Ingreso disminuido"
)

# AE11 is kept separate as an indicator of sufficiency/economic stress.
table(datos$contraccion_ingreso, useNA="ifany")
table(datos$AE11, useNA="ifany")
XVI. REFERENCES
Aldrich, J. H., & Nelson, F. D. (1984). Linear Probability, Logit, and Probit Models. Sage.
American Association for Public Opinion Research. (2016). Standard Definitions: Final Dispositions of Case Codes and Outcome Rates for Surveys (9th ed.). AAPOR.
Ballerini, M., Cabibbo, N., Candelier, R., Cavagna, A., Cisbani, E., Giardina, I., et al. (2008). Interaction ruling animal collective behavior depends on topological rather than metric distance: Evidence from a field study. Proceedings of the National Academy of Sciences, 105(4), 1232-1237.
Birnbaum, Z. W., & Sirken, M. G. (1950). Bias due to non-availability in sampling surveys. Journal of the American Statistical Association, 45(249), 98-111.
Bishop, C. M. (2006). Pattern Recognition and Machine Learning. Springer.
Cann, R. L., Stoneking, M., & Wilson, A. C. (1987). Mitochondrial DNA and human evolution. Nature, 325, 31-36.
Cochran, W. G. (1977). Sampling Techniques (3rd ed.). Wiley.
Departamento Administrativo Nacional de Estadística. (2003). Methodological documentation on expansion factors and sampling design. DANE.
Greene, W. H. (2012). Econometric Analysis (7th ed.). Pearson.
Gujarati, D. N., & Porter, D. C. (2009). Basic Econometrics (5th ed.). McGraw-Hill.
Hastie, T., Tibshirani, R., & Friedman, J. (2009). The Elements of Statistical Learning: Data Mining, Inference, and Prediction (2nd ed.). Springer.
Instituto Nacional de Estadística y Censos de Costa Rica. (2016). Manual de Clasificación Geográfica con Fines Estadísticos de Costa Rica. INEC.
Instituto Nacional de Estadística y Censos de Costa Rica. (2019). ENIGH 2018: Cuadros sobre ingresos de los hogares. INEC.
James, G., Witten, D., Hastie, T., & Tibshirani, R. (2013). An Introduction to Statistical Learning with Applications in R. Springer.
Kolmogorov, A. N., & Fomin, S. V. (1975). Introductory Real Analysis. Dover.
Ling, H., Mclvor, G. E., van der Vaart, K., Vaughan, R. T., Thornton, A., & Ouellette, N. T. (2019). Local interactions and their group-level consequences in flocking jackdaws. Nature Communications, 10, 5174.
Lohr, S. L. (2019). Sampling: Design and Analysis (2nd ed.). CRC Press.
McCullagh, P., & Nelder, J. A. (1989). Generalized Linear Models (2nd ed.). Chapman & Hall.
Nelder, J. A., & Wedderburn, R. W. M. (1972). Generalized Linear Models. Journal of the Royal Statistical Society, Series A, 135(3), 370-384.
Reich, D., Green, R. E., Kircher, M., Krause, J., Patterson, N., Durand, E. Y., et al. (2010). Genetic history of an archaic hominin group from Denisova Cave in Siberia. Nature, 468, 1053-1060.
Ritchey, F. J. (2008). The Statistical Imagination: Elementary Statistics for the Social Sciences (2nd ed.). McGraw-Hill.
United Nations Economic Commission for Europe. (2017). Guide on Poverty Measurement. United Nations.
Vapnik, V. N. (1998). Statistical Learning Theory. Wiley.
Waksberg, J. (1978). Sampling methods for random digit dialing. Journal of the American Statistical Association, 73(361), 40-46.
Wooldridge, J. M. (2010). Econometric Analysis of Cross Section and Panel Data (2nd ed.). MIT Press.