Espartaco

“Is that to say we are against Free Trade? No, we are for Free Trade, because by Free Trade all economical laws, with their most astounding contradictions, will act upon a larger scale, upon the territory of the whole earth; and because from the uniting of all these contradictions in a single group, where they will stand face to face, will result the struggle which will itself eventuate in the emancipation of the proletariat.”

Karl Heinrich Marx · Marx-Engels Collected Works, Vol. VI, p. 290

28,589 views since December 2020

28,589 visitas desde diciembre de 2020

EnglishEspañol

Category: Mathematics

  • METRIC EMBEDDINGS, PART I: PRINCIPAL COMPONENT ANALYSIS AND CLUSTER ANALYSIS. THEIR CONCEPTUAL INTERPRETATION, GEOMETRIC LOGIC-INTUITION, MATHEMATICAL FORMALISM, AND COMPUTATIONAL APPLICATIONS

    METRIC EMBEDDINGS, PART I: PRINCIPAL COMPONENT ANALYSIS AND CLUSTER ANALYSIS. THEIR CONCEPTUAL INTERPRETATION, GEOMETRIC LOGIC-INTUITION, MATHEMATICAL FORMALISM, AND COMPUTATIONAL APPLICATIONS

    Data geometry · Methodological studies · Part I

    Metric Embeddings, PCA, and Cluster Analysis

    Geometric intuition, mathematical foundations, and interpretation of results in R and Minitab

    Originally published:
    Revised:

    Abstract

    Representing data in a few dimensions requires deciding which relationships to preserve. This article develops principal component analysis through its geometry and algebraic structure, explains how it supports a mediated assessment of the relevance of the original variables, and connects dimensionality reduction with cluster analysis. It includes a worked example, verified applications using decathlon2 and USArrests, comparisons of metrics and validation criteria, and an extension on random projections and the Johnson–Lindenstrauss lemma.

    On small screens, tables, equations, and code that exceed the available width can be scrolled horizontally.

    1. Dimensionality, variables, and relationships

    A table with many columns provides numerous descriptions of its observations, but this does not guarantee that every column contributes a distinct relationship. Several measurements may vary together; others may introduce specific information or mainly reflect noise. Dimensionality reduction constructs a representation with fewer coordinates while seeking to preserve properties relevant to a specified question.

    A data matrix X∈ℝn×p contains n observations in its rows and p quantitative variables in its columns. The original representation space has dimension p; the rank of the centered data cannot exceed min(n−1, p). Intrinsic dimension expresses, more broadly, how many degrees of freedom are needed to describe the structure of the data at the required level of precision.

    Two related operations are involved: selecting original variables and extracting combinations of them. PCA directly performs the second and provides a mediated route to assessing the relevance of the first. This operational distinction does not remove their conceptual connection: the derived coordinates are constituted by the original variables and their relationships of covariation.

    The curse of dimensionality encompasses difficulties that arise under certain conditions as the number of dimensions increases: greater data requirements, concentration of distances, or instability of estimates. It is not a law rendering every wide table useless. Sample size, effective structure, distribution, metric, and task all matter.

    The problem of fitting lines and planes to systems of points appears in Pearson (1901). Contemporary machine learning motivations extend its applications, but should be distinguished from the history of the procedure. PCA and the later theory of random projections address related problems through different guarantees.

    2. What a transformation preserves

    Centering subtracts the mean of each variable. Translation changes the origin and preserves distances between observations. Standardization additionally divides each column by its standard deviation, changing the weight of its differences. This second operation generally changes the geometry expressed in the original units.

    zia=xia−x¯asa
    (1) Columnwise standardization requires a positive standard deviation.

    Neither centering nor standardization, by itself, transforms an arbitrary distribution into a Gaussian distribution. Standardizing a column is also different from dividing a direction vector by its length: the latter produces a unit vector.

    Different transformations provide different guarantees.
    OperationEffect on Euclidean distancesRole in the analysis
    CenteringPreserved.Place the point cloud around its mean.
    Full orthogonal change of coordinatesPreserved.Express the point cloud in a new orthonormal basis.
    Truncation to k componentsMay decrease; equality holds if the difference has no discarded component.Reduce dimension with loss controlled through reconstruction.
    StandardizationChange relative to the original units.Prevent a numerical scale from dominating automatically.
    Normalized random projectionApproximately preserved under probabilistic conditions.Control distance distortion for a finite set.

    Let V be a full orthogonal matrix. For any difference d between two observations, ‖dV‖2=‖d‖2 holds. Splitting the basis into retained and discarded directions, the Pythagorean identity gives:

    ‖d‖22=‖dVk‖22+‖dV⟂‖22
    (2) The loss of squared distance under truncation is exactly the squared component of the difference in the discarded subspace.

    A reduced PCA representation is therefore not necessarily an isometric embedding. It may even map two distinct observations to the same point. Exact preservation in a lower-dimensional subspace is possible when all differences between the data points belong to the retained subspace; otherwise, distortion must be evaluated.

    3. The mathematical construction of PCA

    We use a consistent convention: Xc is the centered matrix, S is its covariance matrix with divisor n−1, and vj is a unit direction vector. When the variables are standardized, their covariance matrix is the correlation matrix of the original data.

    S=XcTXcn−1,tj=Xcvj,Var(tj)=vjTSvj
    (3) Scores tⱼ describe the observations along a direction vⱼ.

    The first direction maximizes projected variance among all unit directions. Subsequent directions maximize the remaining variance subject to orthogonality to the previous ones. Without the norm constraint, multiplying the coefficients by an arbitrarily large constant would make the maximum undefined.

    maxvTv=1vTSv⟹Svj=λjvj,λ1≥⋯≥λp≥0
    (4) The stationary condition follows from Lagrange multipliers; the maximum corresponds to the largest eigenvalue.

    Singular value decomposition provides a direct and numerically convenient calculation. If Xc=UΣVT, the columns of V are the principal directions, the scores are T=XcV=UΣ, and the eigenvalues of S are λj=σj2/(n−1). A singular value of the data matrix is not simply the square root of an eigenvalue of its covariance matrix: the divisor matters. The function prcomp() uses SVD and this sample convention (R Core Team, n.d.-c).

    X^c,k=XcVkVkT,‖Xc−X^c,k‖F2=(n−1)∑j>kλj
    (5) The optimal rank-k reconstruction leaves an error equal to the sum of discarded variances multiplied by n−1.

    Maximizing retained variance and minimizing this squared error are equivalent formulations of the same problem. The equivalence follows because total variation decomposes into orthogonal projected and residual parts. It does not depend on separating a supposedly “analytical” methodology from a “numerical” one.

    Descriptive PCA does not require normally distributed data (Jolliffe & Cadima, 2016). Additional assumptions arise when making inferences, specifying probabilistic models, or setting detection thresholds. With repeated eigenvalues, the individual directions within their subspace are not unique; even without repetition, each direction may reverse sign without changing the solution.

    4. Eigenvalues, averages, and variance

    In linear algebra, an eigenvalue is the factor by which a transformation multiplies an eigenvector: Av=λv. In PCA, the transformation is the covariance or correlation matrix, and that factor acquires a precise statistical interpretation: the variance of the projection onto the corresponding unit direction.

    λj=vjTSvj=Var(vjTX)=E[(vjT(X−μ))2]
    (6) In this population expression, S = Cov(X), μ = E[X], and vⱼ has unit norm.

    An average therefore underlies the eigenvalue: the expectation of the squared, centered projections of the observations. Dispersion is measured along a direction defined by the eigenvector. This relationship allows the eigenvalue to be understood as a quantitative summary of variation in that direction.

    λj=1n−1∑i=1ntij2
    (7) Sample version, with centered scores and covariances calculated using n−1. If the divisor n is used, the entire convention must be changed consistently.

    This average of squared projections is not the average of the eigenvector’s coordinates. The coordinates are variable weights; the scores are values for observations; variance summarizes the dispersion of those scores. Confusing these three objects changes the meaning of the result.

    Counterexample: the same coordinate average can accompany different eigenvalues.
    Matrix S = diag(9, 1)Unit eigenvectorMean of its coordinatesEigenvalue
    First direction(1, 0)ᵀ0.59
    Second direction(0, 1)ᵀ0.51

    Furthermore, v and −v share an eigenvalue, while their coordinate averages change sign. Multiplying the entire matrix S by ten preserves its eigenvectors and multiplies its eigenvalues by ten. An eigenvalue depends jointly on the transformation and the direction; the direction alone does not determine its magnitude.

    The eigenvector determines how to project; the eigenvalue expresses how much variation the data contain in that projection.

    5. A mediated assessment of variable relevance

    An account of PCA limited to saying that it “creates new coordinates” leaves its interpretive role incomplete. The new coordinates are constructed from the original variables; by ranking the components and studying their composition, we can identify, through these mediations, which variables participate in the retained structure and to what extent.

    PCj=∑a=1pvaj(Xa−μa)
    (8) Each component combines original variables through specific coefficients. With standardization, X here denotes the variables after standardization.

    Three questions should be distinguished: which variables define a direction; what fraction of each variable’s variation is represented; and how much that direction contributes to total variation. Answering them jointly requires examining coefficients, variable–component correlations, contributions, and eigenvalues. A variable may have little relevance to PC1 and considerable relevance to PC2 or PC3.

    Corr(Xa,PCj)=λjvajSaa
    (9) Relationship between coefficient, eigenvalue, and correlation when Sₐₐ > 0 and λⱼ > 0.

    For standardized variables, the coordinates in the correlation circle are λjvaj. Their squares describe how well the variable is represented on each axis. In this standardized PCA, the conventional contribution of a variable to an axis is 100vaj2 and sums to 100% across variables.

    Ra(k)=∑j=1kλjvaj2,Qa(k)=Ra(k)Saa
    (10) Rₐ(k) is the reconstructed variance of variable a; Qₐ(k) is the fraction of its variance represented by the k components.

    These expressions formalize the mediation: both the ranking of components, given by their eigenvalues, and the participation of the variable in them are involved. Since Saa=∑j=1pλjvaj2, we have 0≤Qa(k)≤1. For standardized variables, Saa=1 and Ra(k)=Qa(k).

    The term loading follows different conventions across programs: it may designate eigenvector coefficients or coordinates scaled by the square root of the eigenvalue. This article always specifies the object being used. An observation’s squared cosine, in turn, concerns the representation of that observation rather than a variable’s contribution.

    6. A fully worked PCA example

    Consider four observations on two variables, with mean (3, 3). The example is constructed so that every step can be checked without relying on software output. We work with covariances, without standardizing.

    X=(12214554),Xc=(−2−1−1−21221),S=(10/38/38/310/3)
    (11) Data, centering, and sample covariances: each column’s sum of squares is 10, and the cross-product sums to 8.

    The characteristic polynomial is (10/3−λ)2−(8/3)2=0. It gives λ1=6 and λ2=2/3. We choose the directions v1=(1,1)T/2 and v2=(−1,1)T/2. They have unit norm, are orthogonal, and satisfy the eigenvector equation.

    Scores obtained by multiplying X꜀V, and reconstructions to which the mean is added back.
    ObservationCentered dataPC1PC2Reconstruction using PC1, in original units
    A(−2, −1)−3/√2 ≈ −2.12131/√2 ≈ 0.7071(1.5, 1.5)
    B(−1, −2)−3/√2 ≈ −2.1213−1/√2 ≈ −0.7071(1.5, 1.5)
    C(1, 2)3/√2 ≈ 2.12131/√2 ≈ 0.7071(4.5, 4.5)
    D(2, 1)3/√2 ≈ 2.1213−1/√2 ≈ −0.7071(4.5, 4.5)

    The PC1 scores sum to zero. Their squares sum to 18, so their sample variance is 18/3=6. The squared PC2 scores sum to 2, and their variance is 2/3. This shows directly where the average of squared scores defining each eigenvalue enters the calculation.

    PVE1=66+2/3=0.9,‖Xc−X^c,1‖F2=3(23)=2
    (12) PC1 retains 90% of total variation; reconstruction loses 2 units of sum of squares.
    Four observations projected onto PC1: two distinct pairs collapse to two coordinates while 90 percent of the variance is retained. −2 −1 0 1 2 Centered X1 −2 −1 0 1 2 Centered X2 A B C D Data, projections, and residuals −3 −2 −1 0 1 2 3 PC1 score A and B C and D Each pair shares one coordinate. 90% of the variance is retained. Reducing two dimensions to one
    Figure 1. Open squares mark the projections. A and B, originally separated by √2, map to the same point when PC2 is discarded. Retaining 90% of the variance does not guarantee preserving every distance or distinguishing every pair.

    For both variables, the reconstructed variance is 6(1/2)2=3. Since their original variance is 10/3, each is represented at 90%. Each contributes 50% to PC1. These percentages differ because they answer different questions: the composition of an axis and the representation of a variable.

    R · numerical example and algebraic checks

    X <- rbind(A=c(1,2), B=c(2,1), C=c(4,5), D=c(5,4))
    colnames(X) <- c("X1", "X2")
    Xc <- scale(X, center=TRUE, scale=FALSE)
    S <- cov(X)
    V <- cbind(PC1=c(1,1), PC2=c(-1,1))/sqrt(2)
    T <- Xc %*% V
    lambda <- diag(t(V) %*% S %*% V)
    Xc_hat <- T[,1,drop=FALSE] %*% t(V[,1,drop=FALSE])
    X_hat <- sweep(Xc_hat, 2, colMeans(X), "+")
    lambda
    T
    X_hat
    sum((Xc-Xc_hat)^2)
    stopifnot(max(abs(lambda-c(6,2/3))) < 1e-10,
              abs(sum((Xc-Xc_hat)^2)-2) < 1e-10,
              max(abs(t(V)%*%V-diag(2))) < 1e-10)

    7. How many components should be retained?

    The proportion of variance explained by component j is obtained by dividing its eigenvalue by the sum of all eigenvalues. The cumulative proportion measures how much a representation with k dimensions retains:

    PVEj=λj∑ℓ=1pλℓ,PVE1:k=∑j=1kλjtr(S)
    (13) In a PCA of p standardized variables, the eigenvalues sum to p.
    Dimension selection should report its criterion rather than hide it behind an automatic output.
    CriterionDecisionScope and limitations
    Cumulative varianceRetain components until a chosen percentage is reached.The threshold depends on the objective. Neither 80% nor 90% provides a universal guarantee.
    KaiserRetain eigenvalues greater than 1 in correlation-based PCA.Compares with the variance of one standardized variable; it should not be transferred unadjusted to arbitrary units.
    Scree plotLook for a change in the slope of the eigenvalues.A graphical aid whose interpretation can be ambiguous.
    Parallel analysisCompare eigenvalues with a reference lacking association between variables.The result depends on the reference, percentile, sample size, and simulation design.
    Out-of-sample reconstructionEvaluate error on data not used for fitting.Avoid leakage from centering and scaling; repeated splits are useful.
    Substantive objectiveRetain dimensions representing relationships of interest.Must be assessed alongside stability and interpretation; it does not replace statistical evidence.

    A rank-deficient matrix has zero eigenvalues. For centered data, the number of positive-variance components cannot exceed min(n−1, p). When p is large relative to n, a good description of the sample can coexist with unstable estimates of population directions. Consistency requires conditions on signal, noise, and the dimensional regime; comparing two integers alone does not settle it.

    Parallel analysis has an antecedent in Horn (1965). Sparse PCA imposes or encourages zero coefficients to obtain combinations with few active variables. “Sparse” here refers to the coefficient structure, not simply to having little data. It can support interpretation or regularization under specified assumptions; it does not by itself guarantee recovery of the true structure.

    8. Application: the ten decathlon events

    The decathlon2 dataset contains 27 athletes, ten events, and three additional columns: rank, overall points, and competition. Following the conventional example in the documentation, we use the first 23 athletes and first ten columns as active data; the remaining four rows can subsequently be projected as supplementary observations. The columns Rank, Points, and Competition do not enter the fit (Kassambara & Mundt, n.d.-a).

    The events use seconds, meters, and other performance measurements. Standardization prevents numerical scale from determining each column’s initial weight. In races, a lower time generally indicates better performance; in jumps and throws, a greater distance generally indicates better performance. The signs must be interpreted with this difference in mind.

    R · active data, PCA, contributions, and supplementary rows

    # First run only, if these packages are missing:
    # install.packages(c("factoextra", "cluster"))
    data("decathlon2", package="factoextra")
    deca_active <- decathlon2[1:23, 1:10]
    stopifnot(all(vapply(deca_active, is.numeric, logical(1))),
              !anyNA(deca_active), all(vapply(deca_active, sd, 0) > 0))
    pca_deca <- prcomp(deca_active, center=TRUE, scale.=TRUE)
    
    # Fix an orientation to simplify comparisons of signs.
    orient_pca <- function(p, anchor=1, sign=-1) {
      for (j in seq_len(ncol(p$rotation))) {
        a <- if (j==1) anchor else which.max(abs(p$rotation[,j]))
        target_sign <- if (j==1) sign else 1
        if (p$rotation[a,j]*target_sign < 0) {
          p$rotation[,j] <- -p$rotation[,j]
          p$x[,j] <- -p$x[,j]
        }
      }
      p
    }
    pca_deca <- orient_pca(pca_deca)
    lambda_deca <- pca_deca$sdev^2
    deca_eigenvalues <- data.frame(
      lambda=lambda_deca,
      percentage=100*lambda_deca/sum(lambda_deca),
      cumulative=100*cumsum(lambda_deca)/sum(lambda_deca))
    variable_pc_cor <- sweep(pca_deca$rotation, 2, pca_deca$sdev, "*")
    contribution <- 100*pca_deca$rotation^2
    representation_3 <- rowSums(variable_pc_cor[,1:3,drop=FALSE]^2)
    round(deca_eigenvalues, 4)
    round(cbind(variable_pc_cor[,1:3], Q3=representation_3), 4)
    
    # Supplementary projection using the fitted centering and scaling:
    supplementary_scores <- predict(pca_deca,
                                    newdata=decathlon2[24:27,1:10])
    supplementary_scores
    Recalculated results: correlation matrix of ten variables and 23 active observations.
    ComponentEigenvalueVariance (%)Cumulative (%)
    PC14.124241.2441.24
    PC21.838518.3959.63
    PC31.239112.3972.02
    PC40.81948.1980.21
    PC50.70167.0287.23
    PC60.42294.2391.46
    PC70.30263.0394.48
    PC80.27452.7497.23
    PC90.15521.5598.78
    PC100.12201.22100.00
    The first three decathlon components explain 72.02 percent; permutation parallel analysis retains one in this run. 1 2 3 4 5 6 7 8 9 10 Component 0 5 10 15 20 25 30 35 40 Variance explained (%) 41.2 18.4 12.4 Decathlon: scree plot 1 2 3 4 5 6 7 8 9 10 Component 0.0 0.5 1.0 1.5 2.0 2.5 3.0 3.5 4.0 Eigenvalue Kaiser and parallel analysis Observed eigenvalues 95th percentile of permutations
    Figure 2. The first three eigenvalues exceed one and together account for 72.02%. In the parallel analysis performed here, only the first eigenvalue exceeds its reference threshold. The parallel threshold comes from 500 independent column permutations, using the 95th percentile and seed 20261113.

    The eigenvalues 4.1242, 1.8385, and 1.2391 correspond to PC1, PC2, and PC3. Each component combines the ten events; its name is not replaced by that of one of the first three columns. In the chosen orientation, PC1 contrasts short-race times with several jumps and throws. PC2 combines, among other characteristics, pole vault and 1500 meters; because a longer time and a greater height have different sporting meanings, it should not automatically be converted into a single scale of “better performance.”

    Contribution and representation are distinct measures. Contributions to any one component sum to 100% across variables.
    VariableCorrelation with PC1Contribution to PC1 (%)Represented in PC1–PC3 (%)
    X100m-0.85117.5484.67
    Long.jump0.79415.2974.59
    Shot.put0.73413.0681.38
    High.jump0.6109.0269.76
    X400m-0.70211.9465.68
    X110m.hurdle-0.76414.1678.60
    Discus0.74313.3958.60
    Pole.vault-0.2171.1470.80
    Javeline0.4284.4569.74
    X1500m0.0040.0066.36

    The 100-meter event contributes 17.54% to PC1 and is represented at 84.67% when three components are retained. The 1500-meter event contributes almost nothing to PC1, but its correlation with PC2 is approximately 0.784 and its contribution to that axis reaches 33.47%. Pole vault contributes approximately 35.46% to PC2. These results show why a mediated assessment of variable relevance must consider more than one axis.

    Athlete scores and correlation circle for ten events: points represent individuals and arrows represent variables. −4 −2 0 2 4 PC1 · 41.24 % −2 −1 0 1 2 PC2 · 18.39 % CLAY SEBRLE BOURGUIGNON Scores for 23 athletes −1.0 −0.5 0.0 0.5 1.0 Correlation with PC1 −1.0 −0.5 0.0 0.5 1.0 Correlation with PC2 X100m Long.jump Shot.put High.jump X400m X110m.hurdle Discus Pole.vault Javeline X1500m Variables: correlation circle
    Figure 3. Points in the left panel are athletes, and their distances refer to the retained plane. Arrows in the right panel are correlations between variables and components. Selected athletes are labeled to preserve legibility; the full scores are available through pca_deca$x.
    Reproduce the comparison with parallel analysis

    R code

    set.seed(20261113)
    null_eigenvalues <- replicate(500, {
      permuted <- apply(deca_active, 2, sample)
      eigen(cor(permuted), symmetric=TRUE, only.values=TRUE)$values
    })
    threshold95 <- apply(null_eigenvalues, 1, quantile, probs=.95)
    data.frame(observed=lambda_deca, threshold95=threshold95,
               exceeds=lambda_deca > threshold95)
    sum(lambda_deca > 1)         # Kaiser: 3
    sum(lambda_deca > threshold95)  # Permutation parallel analysis: 1

    This procedure destroys association between columns while preserving their observed marginal distributions. Each ordered eigenvalue is compared with the 95th percentile of its reference distribution. This is an explicit methodological choice; another reference or rule may yield a different number of components.

    9. Reading the plots and Minitab output

    Software output represents different mathematical objects. Before interpreting it, identify what each point, arrow, percentage, and unit represents. This applies equally to R, Minitab, and other programs.

    Reading guide: similar-looking plots do not necessarily represent the same object.
    OutputObject representedInterpretation
    Scree plotEigenvalues or percentages, depending on the chosen scale.Assess how variation is distributed among components.
    ScoresCoordinates of observations on components.Examine patterns, separations, and distant observations; report how much variance the plane retains.
    Coefficients or loadingsVariable weights or variable–component correlations.Check the software convention first. These are not observation scores.
    Correlation circleCorrelations of variables with axes.Interpret angles as approximations to relationships when the variables are well represented in the plane.
    BiplotObservations and variables in a joint representation.State the scaling. Do not give the same meaning to every distance between different kinds of objects.
    ContributionsParticipation of observations or variables in an axis.Check which is displayed and which denominator is used.
    Squared cosineQuality of representation on retained axes.A low value indicates that the plane loses a substantial part of the object represented.

    In Minitab (Minitab, n.d.), select the active quantitative columns and choose between covariance and correlation analysis. To replicate the geometry of the decathlon example, use the correlation matrix and the same 23 rows. Request eigenvalues, coefficients, scores, and plots, and compare percentages and subspaces. Signs can reverse across programs without changing the solution; divisors and score scales should also be checked.

    In the financial example in the Minitab documentation, the first three eigenvalues are 3.5476, 2.1320, and 1.0447, accounting for approximately 84.1% cumulatively. Associations of PC1 with age, residence, employment, and savings support a proposed interpretation in terms of long-term financial stability; this label is a substantive reading of the coefficients and requires examining the variable definitions. Eigenvalues alone do not assign that meaning.

    Some Spanish Minitab output headings use “influencias” for loadings. Here this concerns component composition rather than a regression influence measure. Nor is a loading generally a causal derivative of a variable with respect to a response phenomenon. Ordinary PCA does not define a dependent variable.

    Di2=(xi−x¯)TS−1(xi−x¯)=∑j=1ptij2λj
    (14) Squared Mahalanobis distance, with invertible S and all components having positive variance.

    Mahalanobis distance weights coordinates by their dispersion and accounts for covariation. Retaining only some components changes this distance and can hide anomalies in discarded directions. If the covariance matrix is singular, the ordinary inverse does not exist; using a pseudoinverse or regularization changes the criterion and should be reported.

    PCA and least-squares regression also differ in their objectives. A simple regression of Y on X minimizes residuals in the response direction; the PCA line fit minimizes distances orthogonal to the line in the chosen geometry. Principal component regression adds a supervised stage after PCA and must be validated as a predictive model.

    10. Clusters and the k-means objective

    Clustering organizes observations using a similarity criterion and a research purpose. A statistical group depends on the variables, their scale, the dissimilarity, and the algorithm. The resulting organization should be justified through these decisions and knowledge of the object being studied.

    K-means seeks a partition of the observations into k groups and a centroid for each group. Its ordinary objective minimizes the sum of squared Euclidean distances to the centroids. The mean minimizes this criterion; absolute distances or other dissimilarities change the problem and do not automatically yield the same algorithm.

    Wk=∑g=1k∑i∈Cg‖zi−μg‖22,μg=1|Cg|∑i∈Cgzi
    (15) K-means objective in the variables or coordinates z chosen for the analysis.

    Common algorithms alternate assignments and updates or use other local improvements. Multiple starts reduce the risk of accepting a poor local solution, but do not certify a global minimum. In R, nstart controls how many initializations are tried when a number of centers is supplied (R Core Team, n.d.-b).

    TSS=Wk+Bk,Bk=∑g=1k|Cg|‖μg−z¯‖22
    (16) Total sum of squares decomposes into within-cluster and between-cluster variation.

    K-means is unsupervised learning: labels are constructed from the data rather than supplied as known training classes. Groups are disjoint and exhaustive when every observation receives a label. Hierarchical methods organize partitions at different levels; their groups are also disjoint when the tree is cut at a particular level.

    The connection with PCA arises because both can be formulated through quadratic approximations: PCA reconstructs through a linear subspace, and k-means through centroids and discrete assignments. Ding and He (2004) study this relationship through a continuous relaxation of membership indicators. The connection does not guarantee that PC1 separates the groups or that the methods produce the same solution.

    11. Application: USArrests and validation

    USArrests contains 50 US states and four variables. Murder, Assault, and Rape record arrests per 100,000 residents in 1973; UrbanPop gives the urban population percentage. These are aggregate records of arrests and urbanization, not a direct, complete measurement of every crime committed or of individual people’s characteristics (R Core Team, n.d.-d).

    We use the dataset included in R as distributed so that results are comparable with the historical example. Its documentation identifies a transcription error in Maryland’s urbanization value and provides additional rounding corrections. A substantive study should examine the corrected version and document sensitivity; the numbers below explicitly refer to the uncorrected built-in dataset.

    R · standardization, multiple starts, and evaluation of k

    library(cluster)
    data("USArrests", package="datasets")
    usa_z <- scale(USArrests)
    dist_usa <- dist(usa_z, method="euclidean")
    pca_usa <- orient_pca(prcomp(usa_z, center=FALSE, scale.=FALSE))
    
    fits <- lapply(2:6, function(k) {
      set.seed(20261113+k)
      kmeans(usa_z, centers=k, nstart=100, iter.max=100)
    })
    k_comparison <- do.call(rbind, lapply(seq_along(fits), function(j) {
      a <- fits[[j]]
      data.frame(k=j+1, W=a$tot.withinss, B=a$betweenss,
        silhouette=mean(silhouette(a$cluster, dist_usa)[,3]))
    }))
    km2 <- fits[[1]]
    round(k_comparison, 4)
    km2$size
    round(aggregate(USArrests, list(cluster=km2$cluster), mean), 3)
    stopifnot(abs(km2$totss-km2$tot.withinss-km2$betweenss) < 1e-8)
    summary(pca_usa)

    The first two components explain approximately 62.01% and 24.74%, respectively, totaling 86.75%. PC1 and PC2 are combinations of all four variables. The 62.01% is neither a state’s murder percentage nor an average proportion of crime types: it is the fraction of total standardized variance captured by the first axis.

    All silhouettes in this table use the same Euclidean distance in the four standardized variables.
    Number of clustersWithin-cluster sum WBetween-cluster sum BMean silhouette
    2102.862493.13760.4085
    378.3233117.67670.3094
    456.4032139.59680.3397
    548.9442147.05580.3031
    642.8330153.16700.2860

    For k=2, the groups have sizes 20 and 30, a within-cluster sum of 102.8624, and a between-cluster sum of 93.1376. The total sum is 196: each of the four standardized columns contributes n−1=49. The between-cluster proportion is 93.1376/196≈47.52%; this percentage concerns the clustering criterion and should not be confused with the variance explained by PC1.

    K-means on the four standardized USArrests variables, shown in two components; the mean silhouette in the original space is 0.4085. −3 −2 −1 0 1 2 3 PC1 · 62.01 % −2.5 −2.0 −1.5 −1.0 −0.5 0.0 0.5 1.0 1.5 PC2 · 24.74 % California Florida Alaska North Carolina Vermont New York Clusters fitted using four variables Cluster 1 Cluster 2 0.0 0.1 0.2 0.3 0.4 0.5 0.6 Silhouette calculated in four variables 1 2 Mean: 0.4085 Cohesion and separation for each state
    Figure 4. The partition was computed with four variables; the two coordinates in the left panel are used for visualization. The silhouette in the right panel uses all four variables, so it is not estimated from the two-dimensional drawing. Cluster numbers may be interchanged between equivalent runs.

    In this solution, the 20-state group has means of 12.165 for Murder, 255.250 for Assault, 68.400 for UrbanPop, and 29.165 for Rape. The 30-state group has means of 4.870, 114.433, 63.633, and 15.943. This description concerns the observed variables and historical period; it does not authorize causal inferences about urbanization or direct generalization to the present.

    11.1. Silhouette: cohesion and separation

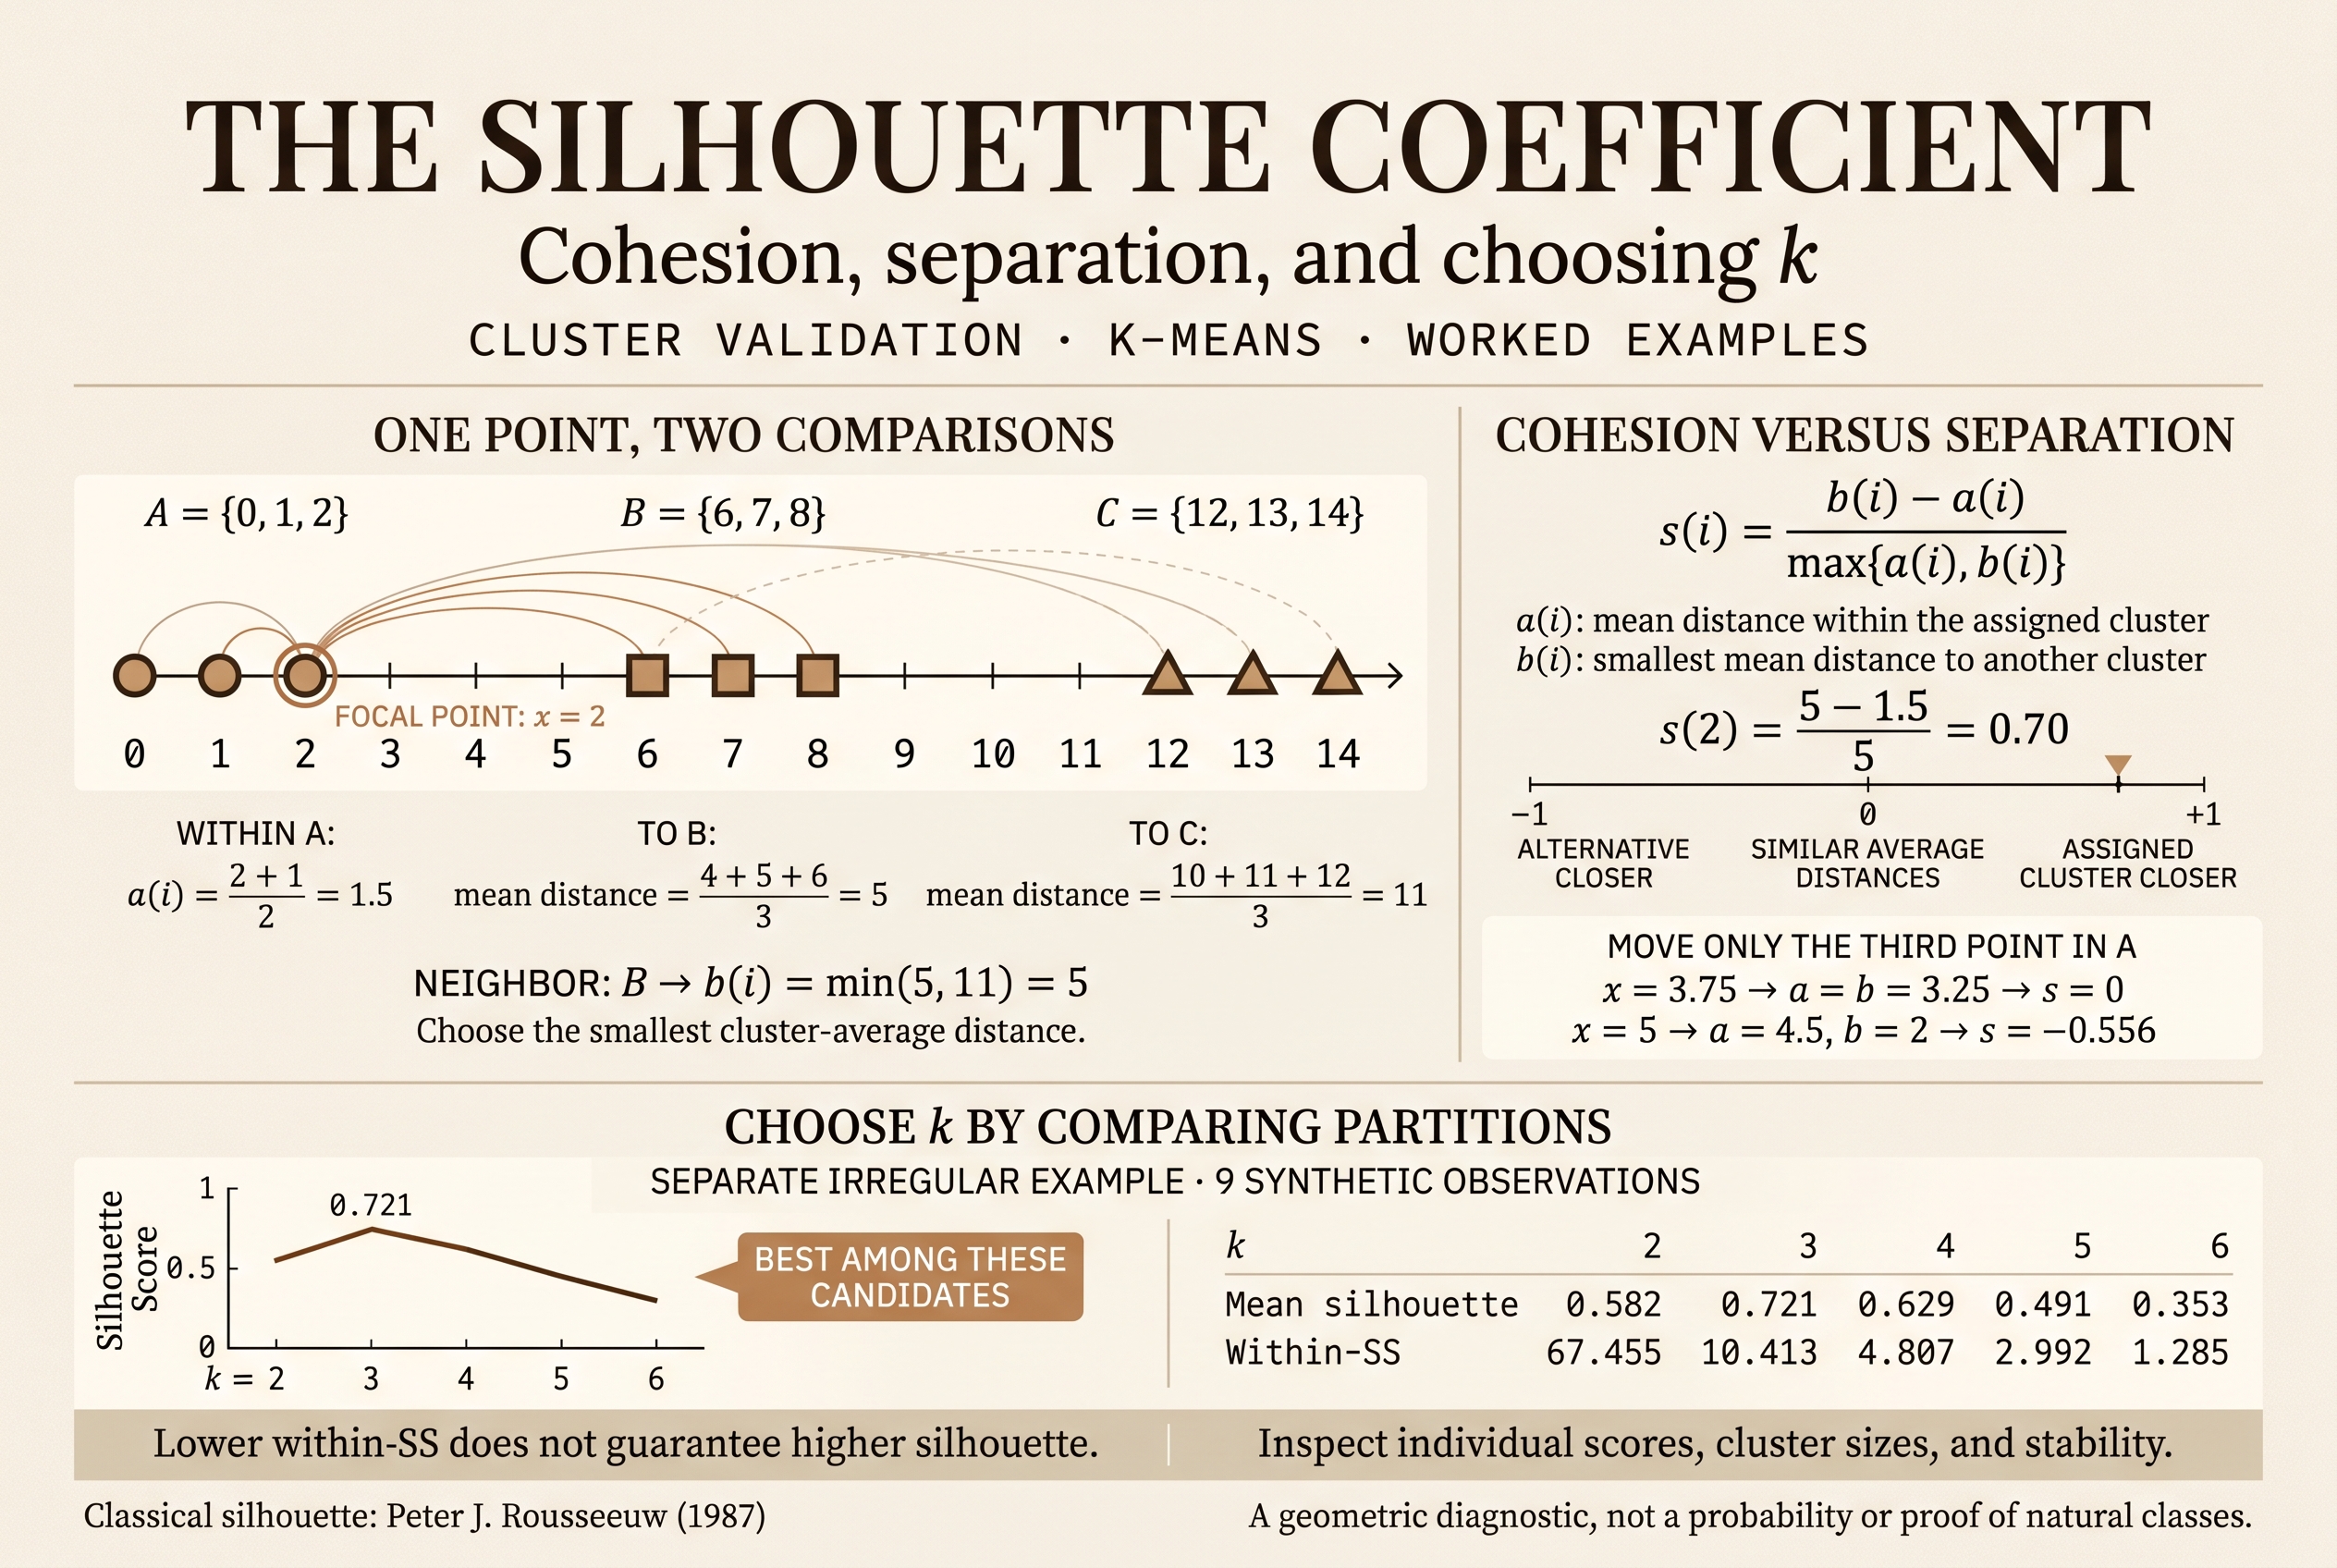
    For observation i, a(i) is its average dissimilarity to the other observations in its cluster. For each other cluster, calculate the average dissimilarity between i and its members; b(i) is the minimum of these averages. The silhouette compares the two quantities (Rousseeuw, 1987):

    s(i)=b(i)−a(i)max{a(i),b(i)},−1≤s(i)≤1
    (17) Set s(i)=0 for singleton clusters. The degenerate case a=b=0 also requires an explicit convention.

    A value near one indicates that the observation is comparatively closer to its own group; near zero, assignment is ambiguous under the chosen dissimilarity; a negative value suggests greater average proximity to another group. Their mean is a dimensionless index, not a distance between clusters. The ordinary silhouette is defined for solutions with at least two clusters and fewer clusters than observations.

    Among the examined solutions with two to six clusters, the highest mean silhouette is 0.4085 for two clusters. This is a relative comparison among those solutions and within that geometry. A moderate mean does not establish that every state is well assigned; inspect individual silhouettes and differences between groups.

    11.2. The gap statistic and its selection rule

    The gap statistic, proposed by Tibshirani et al. (2001), compares observed dispersion with dispersion under a reference distribution without cluster structure. Simulating that reference is different from resampling observations to study partition stability. The function clusGap() allows the number of simulations, reference space, and distance power to be specified (Maechler, n.d.).

    R · gap with 501 simulations and an explicit squared-distance setting

    set.seed(20261113)
    gap_usa <- clusGap(usa_z,
      FUNcluster=function(x,k) list(cluster=kmeans(x, centers=k,
                                      nstart=50, iter.max=100)$cluster),
      K.max=6, B=501, d.power=2, spaceH0="scaledPCA", verbose=FALSE)
    k_gap <- maxSE(gap_usa$Tab[,"gap"], gap_usa$Tab[,"SE.sim"],
                   method="Tibs2001SEmax")
    round(gap_usa$Tab, 4)
    k_gap  # 2 in the documented run
    k^=min{k:Gap(k)≥Gap(k+1)−sk+1}
    (18) The one-standard-error rule of Tibshirani and colleagues, applied to consecutive candidates.
    Silhouette and gap comparison: the one-standard-error rule selects two clusters even though the absolute gap maximum occurs at four. 2 3 4 5 6 Number of clusters 0.20 0.25 0.30 0.35 0.40 0.45 Mean silhouette From k = 2 to k = 6, k = 2 performs best 1 2 3 4 5 6 Number of clusters 0.3 0.4 0.5 0.6 Gap ± simulation error One-standard-error rule: k = 2
    Figure 5. The specified rule selects k=2. The absolute gap maximum occurs at k=4; simply reporting that “the software chose the optimum” would therefore conceal a relevant decision. Error bars represent SE.sim, which incorporates simulation variability according to R’s implementation.

    11.3. What “enhanced analysis” means in eclust()

    factoextra::eclust() combines fitting, selection of the number of clusters, and visualization. It returns an object containing results of the chosen method and additional components; this does not make it a second-order tensor. In its documentation, nboot controls gap-statistic simulations when k is estimated. Increasing it can reduce Monte Carlo variability, but does not guarantee consistency, representativeness, or cluster stability (Kassambara & Mundt, n.d.-b).

    R · optional interface; it does not replace explicit gap configuration

    # Convenient alternative for fitting and visualization:
    res_eclust <- factoextra::eclust(usa_z, FUNcluster="kmeans", k=2,
      nstart=100, iter.max=100, graph=FALSE, seed=20261115)
    factoextra::fviz_cluster(res_eclust, data=usa_z)
    factoextra::fviz_silhouette(res_eclust)
    # Here k is fixed: nboot does not enter its selection.
    # With k=NULL, specify k.max, nboot, and gap_maxSE, and check
    # the implementation settings before comparing results.

    12. Hierarchical clustering and dissimilarities

    An agglomerative procedure begins with one observation per cluster and merges clusters according to a criterion. The dendrogram records this sequence. Sets are nested across levels, and cutting the tree yields a partition of disjoint groups. Such nesting is different from simultaneous membership in overlapping groups at the same level.

    Distance between observations and linkage criterion are separate decisions.
    LinkageBetween-cluster criterionMeaning of height
    SingleMinimum dissimilarity between a pair of members of the two groups.Dissimilarity of the pair enabling the merge; can produce chaining.
    CompleteMaximum dissimilarity between members of the two groups.Criterion based on extreme separation between groups.
    AverageMean dissimilarity across pairs of members from the two groups.Average dissimilarity at the merge.
    WardIncrease in within-cluster sum of squares.Height associated with Ward’s criterion and the implementation’s scale, rather than a generic distance between centroids.

    In R, hclust() offers several linkages, and ward.D2 implements Ward’s criterion through a squared treatment of dissimilarities (R Core Team, n.d.-a). Here we supply ordinary Euclidean distances when using ward.D2; we do not square them beforehand. The call eclust(..., "hclust") has its own documented default, hc_method="ward.D2". BIRCH is another algorithm and does not describe this call.

    R · Euclidean Ward clustering and a comparison with correlated profiles

    hc_ward <- hclust(dist_usa, method="ward.D2")
    ward_groups <- cutree(hc_ward, k=2)
    plot(hc_ward, cex=.55, hang=-1)
    rect.hclust(hc_ward, k=2, border="saddlebrown")
    mean(silhouette(ward_groups, dist_usa)[,3])
    
    # Compare profile similarity using average linkage:
    profile_corr <- cor(t(usa_z), method="pearson")
    d_cor <- as.dist(1-profile_corr)
    hc_cor <- hclust(d_cor, method="average")
    corr_groups <- cutree(hc_cor, k=2)
    mean(silhouette(corr_groups, d_cor)[,3])
    Ward dendrogram on four standardized variables, with a cut producing two disjoint clusters. Alabama Louisiana Georgia Tennessee North Carolina Mississippi South Carolina Texas Illinois New York Florida Arizona Michigan Maryland New Mexico Alaska Colorado California Nevada South Dakota West Virginia North Dakota Vermont Idaho Montana Nebraska Minnesota Wisconsin Maine Iowa New Hampshire Virginia Wyoming Arkansas Kentucky Delaware Massachusetts New Jersey Connecticut Rhode Island Missouri Oregon Washington Oklahoma Indiana Kansas Ohio Pennsylvania Hawaii Utah 0 2 4 6 8 10 12 14 Merge height · Ward Cut producing two clusters USArrests · Euclidean distance and Ward criterion
    Figure 6. Heights correspond to Ward’s implementation on standardized variables. The indicated cut produces two clusters; it does not mean that each height is an original Euclidean distance between two states.
    Silhouettes are evaluated in different geometries; their magnitudes do not provide a universal ranking of algorithms. ARI compares labels on the same 50 observations.
    Configuration, k = 2Silhouette in its dissimilarityARI relative to Euclidean k-means
    Ward.D2 / Euclidean0.40480.9199
    Average / 1-r0.65650.1115

    Correlations between rows compare the relative shape of four values already standardized by column. This is not the correlation between the table’s variables, nor does it preserve each profile’s overall magnitude. With only four coordinates per state, this similarity warrants careful interpretation. The result may group similar profiles even when their absolute levels differ.

    Classification by axioms and domain avoids confusing similarity, distance, and geometric structure.
    MeasureProperty and domainCaution
    Euclidean and Minkowski with p ≥ 1Metrics on the corresponding vector space.Scales and weights determine the geometry.
    Correlation rAn association coefficient, usually between −1 and 1.Not a distance by itself.
    1 − rDissimilarity between profiles with defined correlation.Can violate the triangle inequality and assign zero to distinct original profiles.
    √(2(1 − r))Euclidean distance between centered profiles normalized to unit norm.A metric on those representations; on the original profiles, it identifies location and positive-scale transformations.
    Transformed Spearman or Kendall coefficientsCompare rankings; properties depend on the domain and handling of ties.Do not assume that every transformation of a correlation is a metric on the original data.
    PseudometricMay assign zero distance to distinct objects while retaining the other usual metric properties.The representation may identify differences considered irrelevant to the analysis.
    QuasimetricAllows asymmetry, according to the adopted axiomatic convention.Algorithms expecting a symmetric matrix require adaptation.

    Completeness means that every Cauchy sequence converges within the space; it is not part of the general definition of a metric. The Minkowski norm on an ℓp space and the indefinite tensor of pseudo-Riemannian geometry are distinct constructions. An indefinite metric tensor does not automatically generate a nonnegative distance usable by the algorithms above.

    13. PCA and clustering: a controlled comparison

    To study what changes under dimensionality reduction, we hold the standardized data, two clusters, 100 initializations, and the algorithm fixed. We fit k-means first with all four variables and then with one, two, three, and four components. We compare labels using the adjusted Rand index (ARI) and calculate silhouettes both in the fitting space and in the original variables.

    ARI adjusts for agreements expected by chance: 1 indicates identical partitions, apart from label names.
    Space used for clusteringVariance retained (%)Silhouette in that spaceSilhouette in 4 variablesARI versus original
    Four variables100.000.40850.40851.000
    PC162.010.64680.40851.000
    PC1-PC286.750.47580.40851.000
    PC1-PC395.660.43080.40851.000
    PC1-PC4100.000.40850.40851.000

    In this run, the five partitions are identical. However, the silhouette changes from 0.4085 in four variables to 0.6468 when measured only on PC1. The index improves because the geometry changes: assignments did not improve, because they did not change. With all components retained, distances and silhouettes are recovered, as required by a full orthogonal change of coordinates.

    R · separate representation effects from effects on labels

    ari <- function(a,b) {
      m <- table(a,b)
      c2 <- function(z) z*(z-1)/2
      n <- sum(m); A <- sum(c2(m))
      B <- sum(c2(rowSums(m))); C <- sum(c2(colSums(m)))
      expected <- B*C/c2(n)
      denominator <- (B+C)/2-expected
      if (abs(denominator) < 1e-12) return(1)
      (A-expected)/denominator
    }
    pca_comparison <- do.call(rbind, lapply(1:4, function(m) {
      Tm <- pca_usa$x[,seq_len(m),drop=FALSE]
      set.seed(20261115)
      fit <- kmeans(Tm, centers=2, nstart=100, iter.max=100)
      data.frame(components=m,
        variance=100*sum(pca_usa$sdev[seq_len(m)]^2)/sum(pca_usa$sdev^2),
        silhouette_reduced=mean(silhouette(fit$cluster, dist(Tm))[,3]),
        silhouette_original=mean(silhouette(fit$cluster, dist_usa)[,3]),
        ARI=ari(km2$cluster, fit$cluster))
    }))
    round(pca_comparison, 4)

    13.1. Retaining much variance can conceal a contrast

    Now construct two categories defined by Y=−1 and Y=1, both with X values −10, −6, −2, 2, 6, and 10. Cross-covariance is zero. Variation in X is much greater than variation in Y, so covariance-based PCA selects PC1=X and retains 560/572≈97.90% of the variation. The two categories overlap point for point.

    PC1 retains 97.90 percent of the variance of two horizontal bands but completely removes the category difference defined by Y. −10.0 −7.5 −5.0 −2.5 0.0 2.5 5.0 7.5 10.0 X: high dispersion −1.5 −1.0 −0.5 0.0 0.5 1.0 1.5 Y: contrast between categories Two categories defined by Y Category y = -1 Category y = 1 −10.0 −7.5 −5.0 −2.5 0.0 2.5 5.0 7.5 10.0 PC1 = X The two categories overlap point for point. PC1 retains 97.90% but loses the contrast
    Figure 7. Categories are defined beforehand by Y to study a specific contrast; they are not claimed to be the optimal k-means partition. The example shows that maximizing variance and preserving a substantive contrast can diverge.

    R · a low-variance contrast

    bands <- data.frame(
      X=rep(c(-10,-6,-2,2,6,10), 2),
      Y=rep(c(-1,1), each=6))
    pca_bands <- prcomp(bands, center=TRUE, scale.=FALSE)
    100*pca_bands$sdev[1]^2/sum(pca_bands$sdev^2)  # 97.9021
    cov(bands)
    # Standardization would give both columns variance 1 and change
    # the geometry: the choice of scale is part of the question.

    13.2. Partition stability

    Another question is whether assignment withstands perturbations of the data. In 200 subsamples of 40 states, drawn without replacement while keeping the original scaling, k-means was refitted with two groups and compared with the reference labels restricted to those states. Mean ARI was 0.9995, and the 5th, 50th, and 95th percentiles were 1 in the documented run. This is evidence of stability under that particular perturbation, not a population guarantee or causal validation.

    Reproduce the subsampling stability evaluation

    R code

    set.seed(20261113)
    stability <- replicate(200, {
      ix <- sort(sample(nrow(usa_z), 40, replace=FALSE))
      fit <- kmeans(usa_z[ix,], centers=2, nstart=50, iter.max=100)
      ari(km2$cluster[ix], fit$cluster)
    })
    mean(stability)
    quantile(stability, c(.05,.5,.95))
    range(stability)

    Here scaling is fixed to isolate partition sensitivity. Re-estimating preprocessing within each subsample evaluates a different perturbation. An observation bootstrap, with replacement, also requires handling duplicates and defining how partitions will be compared. Neither operation should be confused with simulating the gap reference distribution.

    14. Random projections and Johnson–Lindenstrauss

    PCA adapts directions to variation in the data. A normalized random projection asks another question: can all distances between a finite number of points be approximately preserved using far fewer coordinates? The Johnson–Lindenstrauss lemma gives an affirmative answer, with dimension depending on the number of points and the tolerated distortion.

    Consider N points in a Euclidean space, 0<ε<1, and a failure tolerance 0<δ<1. Random linear constructions exist for which a dimension of order m=O(ε−2log(N/δ)) suffices to preserve distances simultaneously with probability at least 1−δ. A common formulation controls squared distances:

    (1−ε)‖xi−xj‖22≤‖f(xi)−f(xj)‖22≤(1+ε)‖xi−xj‖22
    (19) The guarantee is required for every pair in the finite set. Taking square roots changes the factors to √(1−ε) and √(1+ε).

    The historical formulation with factors 1±ε on ordinary distances has the same dimensional order after adjusting constants. The Gaussian construction uses f(x)=Rx/m, with independent standard-normal entries of R. Randomness belongs to the projection matrix; the original observations need not follow a normal distribution (Johnson & Lindenstrauss, 1984; Matoušek, 2013).

    Three distinctions are decisive. Dependence is proportional to ε−2, not merely to the logarithm of ε−2. The guarantee holds with high probability for the specified construction and settings; it is not an exact isometry with probability one. Finally, preserving distances in a finite set does not mean preserving every direction of the ambient space when dimension is reduced.

    R · an experiment with 80 points, 800 original coordinates, and 120 projected coordinates

    set.seed(20261113)
    A <- matrix(rnorm(80*800), nrow=80)
    R <- matrix(rnorm(120*800), nrow=120)/sqrt(120)
    projected <- A %*% t(R)
    d_original <- as.vector(dist(A))
    d_projected <- as.vector(dist(projected))
    ratio <- d_projected/d_original
    range(ratio)
    max(abs(ratio-1))
    plot(d_original, d_projected, pch=16, cex=.35,
         col="saddlebrown", xlab="Original distance",
         ylab="Projected distance")
    abline(0,1,col="gray40")
    Gaussian projection from eight hundred to one hundred twenty dimensions for eighty points, comparing all 3,160 pairwise distances. 30 35 40 45 50 Original distance · 800 dimensions 30 35 40 45 50 Projected distance · 120 dimensions Gaussian projection: 80 points 0.7 0.8 0.9 1.0 1.1 1.2 Projected / original distance 0 50 100 150 200 250 300 350 Number of pairs Empirical distortion of 3,160 pairs
    Figure 8. In this realization, projected/original distance ratios range from 0.7217 to 1.2476. The maximum relative distance error is 27.83%. These are empirical results for 3,160 pairs, not proof that this dimension satisfies any chosen tolerance and probability.

    The experiment illustrates the phenomenon; the proof explains how dimension, error, and probability are related. A sufficient theoretical bound may be conservative. The absence of large distortion in one realization does not replace a guarantee for future random realizations.

    15. The scope of scientific interpretation

    PCA articulates observed relationships among variables and constructs a representation that ranks their variation. In this sense, it can participate in identifying essential relationships of the object: it locates regularities, contrasts, and combinations whose interpretation develops through further conceptual and empirical mediations. Reducing this role to a simple rotation of axes would leave out its scientific use.

    At the same time, variance is a particular criterion of relevance. It may capture structure, differences in measurement scale, measurement errors, or noise. A low-variance relationship can be decisive for a specific question, as the band example showed. Identifying essential determinations requires explaining why the variation examined expresses relationships relevant to the phenomenon and how it connects with its history, mechanisms, and other evidence.

    Clusters are likewise constructions mediated by a geometry and a criterion. Their stability shows whether certain decisions withstand perturbations; interpretation requires explaining what observations share and why that similarity matters. A group of states defined by arrests and urbanization does not, by itself, constitute a social class, a causal mechanism, or a complete historical typology.

    Dimensionality reduction makes a way of preserving relationships explicit. Scientific interpretation requires explaining why those relationships matter for the object being studied.

    16. Proofs and extensions

    The following extensions preserve the probabilistic and computational development of the original study with consistent notation. They can be read after the applied sections. Algebraic identities are derived here; general theorems and their antecedents are identified in the references.

    A. From maximum variance to eigenvectors and reconstruction

    For symmetric S, the Lagrangian is L(v,λ)=vTSv−λ(vTv−1). Differentiation with respect to v gives 2Sv−2λv=0. Writing a unit vector in an orthonormal eigenvector basis, v=∑jajvj with ∑jaj2=1, gives vTSv=∑jλjaj2≤λ1. Equality is attained along a direction of the largest eigenvalue. Subject to orthogonality to earlier directions, the same argument yields subsequent directions.

    Cov(Xcvi,Xcvj)=viTSvj=λjviTvj
    (20) Covariance is zero for i≠j and equals λⱼ for i=j.

    For any rank-k orthogonal projector P, orthogonality of its parts gives ‖Xc‖F2=‖XcP‖F2+‖Xc(I−P)‖F2. Maximizing the first term is equivalent to minimizing the second. The energy retained by a subspace of dimension k cannot exceed the sum of the k largest squared singular values; choosing P=VkVkT attains that bound.

    The identity XcTXc=VΣTΣVT directly connects SVD and eigendecomposition. Symmetry and positive semidefiniteness of the covariance matrix are essential: claims about eigenvectors of an arbitrary nonsymmetric matrix should not be transferred to it without qualification.

    B. Gaussian normalization, 2-stability, and sub-Gaussian tails

    The Gaussian density’s normalization constant can be obtained without an elementary antiderivative. Let I=∫−∞∞e−x2/2dx. Squaring and changing to polar coordinates:

    I2=∫R2e−(x2+y2)/2dxdy=2π∫0∞re−r2/2dr=2π
    (21) Since I>0, I=√(2π). The standard-normal density is e^(−x²/2)/√(2π).

    If Z1,…,Zp are independent standard-normal variables, the moment-generating function of Y=∑jajZj is:

    E[etY]=∏jE[etajZj]=∏jet2aj2/2=et2‖a‖22/2
    (22) The product of expectations uses independence. Linearity of expectation alone does not justify that step.

    Thus Y is normally distributed with mean zero and variance ‖a‖22. This stability under linear combinations explains why a Gaussian row of a random matrix produces a normal projection of any fixed vector without requiring normally distributed data.

    A sufficient condition for a centered variable to be sub-Gaussian is EetY≤eK2t2/2 for every real t. Applying Markov’s inequality to the exponential and minimizing over t>0 gives:

    Pr(Y≥u)≤inft>0exp(−tu+K2t2/2)=exp(−u2/(2K2))
    (23) Applying the same argument to −Y gives a two-sided bound with factor 2.

    Rademacher variables, taking +1 and −1 with probability 1/2 each, satisfy EetY=cosh(t)≤et2/2. Under independence, their combinations also have uniform bounds when the coefficient vector’s norm is fixed. A sub-Gaussian variable need be neither normal nor symmetric.

    C. Johnson–Lindenstrauss: Gaussian proof and sub-Gaussian extension

    Fix a nonzero vector x and a matrix R with m×p independent standard-normal entries. For f(x)=Rx/m, 2-stability implies that m‖f(x)‖22/‖x‖22 has a chi-squared distribution with m degrees of freedom.

    Eet(Z2−1)=e−t(1−2t)−1/2,t<1/2
    (24) Moment-generating function of a centered squared standard-normal variable. It controls a sum of m independent squares.

    Applying exponential Markov bounds to both tails and using logarithmic inequalities gives, for 0<ε<1, the bound:

    Pr(|‖f(x)‖22‖x‖22−1|>ε)≤2exp[−m(ε24−ε36)]
    (25) Control for a fixed vector. The zero vector satisfies preservation trivially.

    For the N(N−1)/2 difference vectors from a set of N points, the union bound multiplies this probability by the number of pairs. Independence between the pairs’ failure events is unnecessary. It therefore suffices to require:

    m≥log(N(N−1)/δ)ε2/4−ε3/6
    (26) A sufficient condition from this proof for failure probability at most δ. The bound is not asserted to be necessary.

    The overall success probability is at least 1−δ. If δ<1, some realization satisfies all the inequalities. This yields both an existence statement and a probabilistic construction. The proof concerns squared distances; the ordinary-distance formulation follows by taking square roots or adjusting the parameter.

    Extension: what changes with sub-Gaussian entries

    Now suppose entries are independent, centered, have variance one, and have a uniformly bounded sub-Gaussian parameter. For a unit vector a, each row produces Yi=∑jRijaj with mean zero, variance one, and a sub-Gaussian bound whose parameter does not depend on p. This follows by factoring the moment-generating function and using ∑jaj2=1.

    The next step controls Zi=Yi2−1. Integrating a two-sided tail bound Pr(|Yi|>t)≤2e−ct2 gives E|Yi|2q≤2q!c−q. Consequently, there is a uniform constant L such that E|Zi|q≤q!Lq for q≥2.

    EeuZi≤1+∑q≥2|u|qLq≤exp(2L2u2),|u|≤12L
    (27) The linear term vanishes exactly because E[Zᵢ]=0; the remaining series is bounded by a geometric series.

    Row independence allows these bounds to be multiplied for the sum of the Zi. Another Chernoff argument yields a failure probability bounded by 2e−c0mε2 for 0<ε<1, with constants depending on the sub-Gaussian parameter. The same union bound completes the extension. The crucial points are controlling both signs of u, keeping constants uniform, and distinguishing quantifiers: first a fixed vector, then all differences in the finite set.

    D. The spectral connection between PCA and k-means

    Let H be the normalized indicator matrix: its column for group g equals 1/|Cg| on group members and zero elsewhere. Then HTH=I, and reconstruction through centroids is HHTXc. Between-cluster explained variation equals tr(HTXcXcTH).

    Membership imposes a particular discrete structure on H. Relaxing constraints produces spectral problems related to principal components. Moreover, the matrix of centroids repeated for each observation has rank at most k−1 for centered data. Optimality of the reduced-rank approximation therefore gives:

    Bk≤(n−1)∑j=1k−1λj,Wk≥(n−1)∑j≥kλj
    (28) Add zero eigenvalues if needed. The bound concerns the objective and does not automatically identify the optimal partition.

    This relationship explains why leading directions may be useful for clustering without equating the two methods’ constraints. A general linear combination may have many nonzero coefficients; assignment to centroids uses membership indicators. The connection should be formulated through objectives and constraints, rather than turning “k-means is sparse PCA” into a general algorithmic identity.

    E. NIPALS, missing data, and computational choices

    NIPALS extracts components sequentially. A version for complete data starts with a residual matrix E and an initial score column t. It alternates v=ETt/(tTt), normalization of v, and the update t=Ev until convergence. It then deflates using E←E−tvT and seeks the next component. Component variance is obtained from tTt/(n−1).

    Variants use only observed entries when updating each coefficient, but “handling missing values” requires specifying the procedure and assumptions. Missingness patterns may bias results; inserting NA into any implementation is not enough. prcomp() uses SVD and should not be described as an implementation of NIPALS.

    If only a few components of a large matrix are needed, partial or randomized algorithms may be used. Their suitability depends on size, precision, and data structure. Comparisons must hold centering, scaling, retained dimension, and numerical tolerances fixed.

    F. Reproducibility and verification of calculations

    Tables and figures were recalculated for this revision. The numerical core was executed with R 4.2.2 Patched and cluster 2.1.4; the decathlon2 data were checked against the public distribution of factoextra. Vector figures represent those results rather than screenshots of old output. The factoextra visualization functions are offered as an optional alternative and may depend on additional package versions.

    R · verifiable identities and environment information

    # Checks on objects created in previous sections:
    stopifnot(abs(sum(lambda_deca)-ncol(deca_active)) < 1e-8)
    stopifnot(max(abs(cov(pca_deca$x)-diag(lambda_deca))) < 1e-8)
    stopifnot(max(abs(colSums(contribution)-100)) < 1e-8)
    stopifnot(all(representation_3 >= 0), all(representation_3 <= 1+1e-8))
    stopifnot(abs(sum(usa_z^2)-196) < 1e-8)
    stopifnot(max(abs(as.vector(dist(pca_usa$x))-
                      as.vector(dist_usa))) < 1e-8)
    sessionInfo()

    The R blocks follow the article’s reading order; some reuse previously created objects. Examples can be executed in the R console or through RStudio. Changes in version, precision, or initialization can interchange cluster labels or reverse axis signs. Compare partitions and subspaces in addition to printed numbers.

    References

    The original document is retained as an antecedent, alongside sources needed for the results developed here. Proofs and numerical examples in this revision provide explicit steps; technical references link to documentation maintained by those responsible for the software.

    Original document · 127 pages

    The historical manuscript preserves the 2022 version, published under the name Isadore Nabi. This page develops and revises its arguments.

    Read the original PDF

    End of study · Geometry, representation, and interpretation of data.

  • CLASSIFICATION OF DISSIMILARITY MEASURES BETWEEN DATA CLUSTERS ACCORDING TO THE METRIC STRUCTURE OF THE APPLICATION SAMPLE SPACE

    CLASSIFICATION OF DISSIMILARITY MEASURES BETWEEN DATA CLUSTERS ACCORDING TO THE METRIC STRUCTURE OF THE APPLICATION SAMPLE SPACE

    Marxist Philosophy of Science · Mathematical statistics

    Dissimilarity Measures and Metric Structures in Cluster Analysis

    Distances, correlations, pseudometrics, and quasi-metrics: foundations, worked examples, and application criteria.

    Originally published: April 27, 2022
    Revised: November 11, 2026

    Choosing a dissimilarity measure determines which differences matter and which geometry is assigned to the data. This revision develops the original table into an exposition linking axioms, calculations, and clustering decisions: from Euclidean distance to directional comparison, and from individual observations to entire sets.

    01 · What is compared, and what does “near” mean?

    A classification of dissimilarity measures starts by identifying the objects being compared. An observation may be represented by a feature vector x; a cluster by a set of observations; a distribution by a probability measure; and a function by a trajectory or profile. These objects call for different constructions. Producing a number is not sufficient for an expression to define a metric distance.

    Throughout, 𝒳 denotes the domain of objects, N the number of observations, and p the number of variables. The Minkowski exponent is written q to distinguish it from dimension. The symbol d is used for distances with an explicitly stated structure, δ for more general dissimilarities, and s for similarities. Smaller dissimilarities express greater proximity, whereas larger similarities usually express greater proximity.

    Strictly, the sample space Ω is the set of possible outcomes of a random experiment. The feature space 𝒳 contains the representations used in the analysis. The observed sample is a finite subset, or an indexed collection, of those representations. A data matrix does not automatically identify these three notions.

    02 · Metrics, completeness, and topology

    A metric is a finite, nonnegative function that separates points, is symmetric, and satisfies the triangle inequality:

    d:𝒳×𝒳⟶[0,∞)
    d(x,y)=0⟺x=y,d(x,y)=d(y,x)
    d(x,z)≤d(x,y)+d(y,z)(∀x,y,z∈𝒳)

    Identity requires both implications: a point is at zero distance from itself, and two points at zero distance must be the same point. The triangle inequality holds for every triple, including repeated points. It is not a generalization of the Pythagorean theorem, which states a particular equality in Euclidean geometry.

    Completeness is an additional property of the pair (𝒳,d). A sequence is Cauchy when its terms eventually become arbitrarily close to one another:

    ∀ε>0∃n0∀m,n≥n0:d(xm,xn)<ε

    The space is complete if every Cauchy sequence converges to an element of 𝒳. For example, ℝ with its usual distance is complete; ℚ with the inherited distance is not, since rational sequences may approach √2. A finite set of distinct points with a metric is complete: its smallest positive distance prevents a Cauchy sequence from continuing to jump between different points. Completeness is therefore not the main difficulty when clustering a finite sample.

    A metric generates open sets through balls. Nevertheless, topology does not determine distance values: d and 2d generate the same open sets. Completeness of a particular metric is not a topological invariant either: ℝ and (0,1) are homeomorphic, although their usual Euclidean metrics have different completeness properties. A homeomorphism preserves topological structure; an isometry preserves distances. These are elementary checks, not assumptions about an algorithm.

    03 · A classification by axioms

    ClassSymmetrySeparationTriangleExample
    MetricYesd(x,y)=0 ⇔ x=yYesEuclidean; Manhattan
    PseudometricYesMay failYes|x₁−y₁| on ℝ²
    Quasi-metric¹Not requiredd(x,y)=d(y,x)=0 ⇒ x=yYesmax{y−x,0}
    Semimetric²Yesδ(x,y)=0 ⇔ x=yNot required‖x−y‖₂²
    Dissimilarity³Definition dependentNot guaranteedNot guaranteed1−r

    ¹ The convention follows Stojmirović (2005): separation is required jointly in both directions. Other sources reserve “quasi-metric” for a stronger separation condition. A metric is also a quasi-metric under the inclusive convention: not requiring symmetry does not prohibit it.

    ² Here “semimetric” means a symmetric, nonnegative, point-separating function without a required triangle inequality. The term has several uses. McAuley (1956, p. 315, footnote 1) requires symmetry and compatibility with a topology through limit points; his definition must not be replaced by “asymmetric distance.” A function lacking the triangle inequality does not automatically support the same open-ball theory as a metric.

    ³ For the clustering examples, dissimilarities are finite, nonnegative, and zero on the diagonal; symmetric ones may be stored in a symmetric matrix. These conditions alone do not impose separation or the triangle inequality. The table lists requirements, not mutually exclusive classes.

    04 · Minkowski, scaling, and squared distance

    On ℝᵖ, the Minkowski family consists of metrics induced by norms:

    dq(x,y)=(∑j=1p|xj−yj|q)1/q,1≤q<∞
    d∞(x,y)=max1≤j≤p|xj−yj|

    The cases q=1, q=2, and q→∞ give Manhattan, Euclidean, and maximum distance. For q≥1, Minkowski’s inequality ‖u+v‖q≤‖u‖q+‖v‖q guarantees the triangle inequality. For 0<q<1, the same expression with the 1/q power is not a norm and may violate it. This differs from the sum without that outer power: ∑|xⱼ−yⱼ|q is a metric in that interval.

    Unit balls: Manhattan diamond, Euclidean circle, and maximum-norm square. −1 0 1 −1 0 1 Manhattan · q = 1 −1 0 1 −1 0 1 Euclidean · q = 2 −1 0 1 −1 0 1 Maximum · q = ∞
    Unit balls: Manhattan diamond, Euclidean circle, and maximum-norm square.

    For x=(1,2) and y=(4,6), the absolute coordinate differences are 3 and 4: Manhattan gives 7; Euclidean gives √(9+16)=5; maximum gives 4. All three answers are consistent with different geometric rules.

    The expression δ(x,y)=‖x−y‖₂² is squared Euclidean distance. It is symmetric and separates points, but it is not generally a metric. With x=0, y=1, and z=2, δ(x,z)=4 while δ(x,y)+δ(y,z)=2:

    Triangle-inequality counterexample: squared distances among 0, 1, and 2 are 1, 1, and 4. 0 1 2 1² = 1 1² = 1 2² = 4 > 1 + 1
    Triangle-inequality counterexample: squared distances among 0, 1, and 2 are 1, 1, and 4.

    Units matter. Measuring one variable in colones and another in thousands of colones changes their relative contributions. Standardizing columns by their standard deviations is one possible decision, not a universal requirement; it needs nonzero scales and a defensible interpretation. With strictly positive weights, d(x,y)=√∑wⱼ(xⱼ−yⱼ)² remains a metric. Zero weights can produce a pseudometric; negative weights no longer guarantee a real, nonnegative distance.

    The dist() implementation is documented by R Core Team (n.d.-b); its argument named p corresponds to the exponent q used in this article.

    05 · Pearson, Spearman, and Kendall: from association to dissimilarity

    Correlations measure association, not metric separation of original observations. They may be negative and equal 1, rather than 0, for a nonconstant profile compared with itself. They must be identified before being transformed.

    Pearson

    r(x,y)=∑i=1p(xi−x¯)(yi−y¯)∑i=1p(xi−x¯)2∑i=1p(yi−y¯)2

    Both profiles must vary. For x=(1,2,3) and y=(2,4,6), r=1 even though x≠y and their Euclidean distance is √14. Thus 1−r ignores level and positive scale differences. This can be desirable when comparing shapes, but not when absolute magnitude matters.

    Spearman

    ρs=r(R(x),R(y)),ρs=1−6∑i=1p(Ri−Si)2p(p2−1)

    The first equality defines Spearman correlation as Pearson correlation of ranks. The second is a simplification valid without ties. With ties, assign average ranks and use the first expression. Pearson’s numerator must sum paired products, rather than multiply two centered sums that would each be zero.

    Kendall

    τa=C−D(p2),τb=C−D(C+D+Tx)(C+D+Ty)

    For each pair of elements i<j, C counts concordances and D discordances. Tx and Ty count pairs tied only in x or only in y; pairs tied in both are excluded from those terms. Without ties, C+D=p(p−1)/2 and τa=(C−D)/(C+D). A tie does not mean that two judges assign the same rank to one person: it means equality within at least one ranking for a pair of people.

    Revisiting the original document’s twelve candidates: X=(1,2,…,12) and Y=(1,2,4,3,6,5,8,7,10,9,12,11). There are 66 pairs, five discordant and 61 concordant; hence τ=56/66≈0.848485. Squared rank differences sum to 10, so ρs=1−60/1716≈0.965035. These are different coefficients for the same comparison.

    A transformation does not guarantee a metric

    Consider centered profiles x=(1,−1,0), y=(1,0,−1), and z=(0,1,−1). Direct calculation gives r(x,y)=r(y,z)=1/2 and r(x,z)=−1/2. The dissimilarity 1−r gives 1/2, 1/2, and 3/2, violating the triangle inequality. Chordal distance is justified by normalization:

    u(x)=x−x¯1‖x−x¯1‖2,r(x,y)=u(x)𝖳u(y)
    ‖u(x)−u(y)‖22=2−2r(x,y),dch(x,y)=2(1−r(x,y))

    The identity proves that dch is Euclidean between normalized vectors. On the original profiles it is generally a pseudometric: profiles related by y=a·x+b·1 with a>0 have zero distance. It becomes a metric on the corresponding equivalence classes. Spearman admits the same construction after ranking and normalizing. This proof must not be extended automatically to every Kendall-based formula.

    R Core Team (n.d.-a) documents rank correlation and ties; Kendall (1938, 1945) distinguishes the original coefficient and its adjustment. The calculations and counterexample above are worked out explicitly here.

    06 · Pseudometrics: what information is lost

    A pseudometric retains nonnegativity, symmetry, and the triangle inequality while allowing distinct objects to have zero distance. If φ:𝒳→𝒴 and d𝒴 is a metric, then dφ(x,y)=d𝒴(φ(x),φ(y)) is a pseudometric; it is a metric when φ is injective. The triangle inequality is inherited directly from 𝒴.

    dπ((x1,x2),(y1,y2))=|x1−y1|

    Under π(x₁,x₂)=x₁, points P=(2,3) and Q=(2,5) have zero pseudodistance because the second coordinate was discarded. This is not a mathematical contradiction: it states precisely which information the representation has removed.

    P=(2,3) and Q=(2,5) coincide after projection onto the first coordinate; their pseudodistance is zero. 0 1 2 3 4 5 x₁ 0 1 2 3 4 5 6 x₂ P = (2,3) Q = (2,5) Distinct observations 0 1 2 3 4 5 x₁ π(P) = π(Q) = 2 Projection π(x) = x₁
    P=(2,3) and Q=(2,5) coincide after projection onto the first coordinate; their pseudodistance is zero.

    Further retained examples are d(f,g)=|f(t₀)−g(t₀)| for real functions on a domain containing t₀; d(x,y)=s(x−y) when s is a seminorm; and the trivial pseudometric d≡0. Each illustrates a different source of indistinguishability.

    x~y⟺d(x,y)=0,d¯([x],[y])=d(x,y)

    The relation ∼ is an equivalence relation: transitivity follows from the triangle inequality. Distance between classes is well defined because replacing a representative by another at zero distance does not change the result. The quotient 𝒳/∼ is a metric space. In data analysis, this distinguishes duplicate representations from substantively identical objects.

    07 · Quasi-metrics and directional comparisons

    A quasi-metric allows the cost of moving from x to y to differ from the cost of returning. Under the convention used here, q(x,x)=0, the directed triangle inequality holds, and q(x,y)=q(y,x)=0 implies x=y. Nonnegativity is part of the definition.

    q(x,y)=max{y−x,0},q*(x,y)=q(y,x)
    qs(x,y)=max{q(x,y),q(y,x)}=|x−y|

    For example, q(2,5)=3 but q(5,2)=0. One direction measures a required increase; the other has no increase to penalize. The triangle inequality follows from (a+b)₊≤a₊+b₊. The conjugate reverses direction, and the maximum of the two recovers a metric. For any quasi-metric with this joint separation condition, both max{q,q*} and q+q* are metrics.

    Directed balls depend on whether q(x,y) or q(y,x) is used; the associated topology must specify that choice. Quasi-metrics can model asymmetric transformation costs, but not every asymmetric cost satisfies the triangle inequality. The discrete metric, equal to 0 for identical points and 1 otherwise, is symmetric: it belongs to the broad quasi-metric class but does not illustrate asymmetry.

    08 · Set distances and linkage criteria

    Let A and B be nonempty finite clusters, and d a metric between their observations. Single linkage uses the nearest pair; complete linkage the farthest; and average linkage all pairs. Hausdorff compares the largest nearest-neighbor distance in both directions:

    Dmin(A,B)=mina∈A,b∈Bd(a,b),Dmax(A,B)=maxa∈A,b∈Bd(a,b)
    Davg(A,B)=1|A||B|∑a∈A∑b∈Bd(a,b)
    dH(A,B)=max{maxa∈Aminb∈Bd(a,b),maxb∈Bmina∈Ad(a,b)}

    Hausdorff is a metric on the nonempty finite subsets of a metric space, and extends to nonempty compact subsets. Separation follows because zero distance forces each point of either set to belong to the other; the triangle inequality follows by chaining nearest-neighbor approximations through the intermediate set.

    Linkage criteria are not automatically metrics on sets. Single linkage can be zero for different intersecting sets. Complete and average linkage may give D(A,A)>0. Centroid distance can be zero for different sets sharing the same center. These properties are separate from the usefulness of these rules for constructing a hierarchy.

    A complete example on ℝ: A={0,2}, B={5,9}. The four cross-distances are 5,9,3,7; the centroids are 1 and 7. From A, the largest nearest-neighbor distance to B is 5; from B to A it is 7. The results are:

    CriterionResultCalculation
    Single3min{5,9,3,7}
    Complete9max{5,9,3,7}
    Average6(5+9+3+7)/4
    Centroids6|1−7|
    Hausdorff7max{5,7}
    Ward: ΔW36(2·2/4)·(1−7)²

    Ward selects the merger that minimizes the increase in within-cluster sum of squares. Decomposing deviations around the merged center yields:

    ΔW(A,B)=|A||B||A|+|B|‖x¯A−x¯B‖22

    In this example, W(A)=2 and W(B)=8; the merged center is 4 and W(A∪B)=46, so ΔW=46−10=36. This increase is not the same quantity as centroid distance. Under the usual Euclidean Ward.D2 parameterization, height corresponds to √(2ΔW), rather than ΔW itself; the example would give √72≈8.4853.

    09 · Choosing a compatible measure and algorithm

    MethodCompatibility to check
    k-meansMinimizes squared Euclidean deviations from means. Replacing the distance changes the problem and the optimal center update.
    Ward.D2Use Euclidean distances; hclust squares them internally. Do not supply dist(X)^2 to Ward.D2 for the usual criterion.
    Single, complete, and average linkageAccept appropriate symmetric dissimilarities; successful execution does not establish that the input is metric or Euclidean.
    PAM / k-medoidsRepresentatives are observations. Dissimilarities can be used without arithmetic means; check implementation requirements.
    SilhouetteComputed using the stated dissimilarities; interpretation depends on them and on the partition. It does not certify metric axioms.

    Euclidean embeddability is stronger than the metric axioms. For a finite symmetric nonnegative matrix D with zero diagonal, it can be diagnosed through B=−½JD²J, where J=I−11ᵀ/N and D² denotes elementwise squaring. An exact Euclidean representation exists when B is positive semidefinite; substantial negative eigenvalues rule it out. A numerical tolerance only addresses rounding.

    Pearson correlation computed over a common set of coordinates allows chordal distance to be used as Euclidean input between normalized profiles. For Ward.D2, supply √[2(1−r)] without squaring it beforehand. This preserves the normalized geometry, not original magnitudes.

    Categorical and mixed variables require constructions that respect their scales. Coding nominal categories as 1,2,3 and using Euclidean distance imposes an order and separations that may be meaningless. Hamming, Jaccard, or Gower may be considered depending on the domain, with explicit rules for absences, weighting, and missing data. Such extensions still require checking the axioms of the specific variant.

    The minimum-variance criterion originates with Ward (1963); implementation differences are discussed by Murtagh and Legendre (2014) and R Core Team (n.d.-c).

    10 · A reproducible experiment with six observations

    This illustrative dataset is designed so that every calculation can be reconstructed; it is not an empirical sample from a population. Both variables are treated as comparable coordinates and are not standardized in this example:

    IDx₁x₂
    A00
    B10.2
    C0.32.4
    D3.53.1
    E5.21.3
    F5.94
    Euclidean distances, without standardization.
    IDABCDEF
    A0.00001.01982.41874.67555.36007.1281
    B1.01980.00002.30873.82884.34176.2008
    C2.41872.30870.00003.27575.02205.8241
    D4.67553.82883.27570.00002.47592.5632
    E5.36004.34175.02202.47590.00002.7893
    F7.12816.20085.82412.56322.78930.0000
    Four dendrograms for the same A-F data: heights and some merges change with distance and linkage; leaf order may vary without changing the hierarchy. C A B F D E 0 2 4 6 Height Euclidean · complete linkage C A B F D E 0.0 0.5 1.0 1.5 2.0 2.5 3.0 Height Euclidean · single linkage C A B E D F 0 2 4 6 8 10 Height Manhattan · complete linkage C A B F D E 0 2 4 6 8 Height Euclidean · Ward.D2
    Four dendrograms for the same A-F data: heights and some merges change with distance and linkage; leaf order may vary without changing the hierarchy.

    The first Euclidean merger joins A and B at √1.04≈1.019804. The final single-linkage height depends on a bridge between groups; complete linkage depends on the farthest pair. Manhattan distance changes coordinate contributions. Ward generates a sequence based on increases in dispersion. Agreement of a partition at one number of groups does not imply agreement of the entire hierarchy or its heights.

    MergeEuc. completeEuc. singleMan. completeWard.D2
    11.0198041.0198041.2000001.019804
    22.4186772.3086792.9000002.475884
    32.4758842.4758843.3000002.665833
    42.7892652.5632013.5000002.742870
    57.1281133.2756689.9000008.377151

    At three clusters, Euclidean complete linkage gives {A,B,C}, {D,E}, {F}; Manhattan complete linkage gives {A,B,C}, {D,F}, {E}. The rest of the procedure is unchanged: changing the measure changes a merger decision. Numeric cluster labels are arbitrary.

    11 · Functions, manifolds, and tensors: necessary distinctions

    The word “metric” appears in related but distinct settings. Minkowski distance between vectors is induced by a norm. For function spaces and 1≤q<∞, define:

    ‖f‖Lq=(∫|f|qdμ)1/q,d(f,g)=‖f−g‖Lq

    For functions considered pointwise, two functions differing only on a measure-zero set may have zero distance. Lᵠ spaces identify functions equal almost everywhere; on those equivalence classes the expression is a norm. Lᵠ spaces are complete for q≥1, but their definition requires a specified measure and integration domain.

    A smooth n-dimensional manifold is locally modeled on open subsets of ℝⁿ through compatible charts. The tangent space TₐM at a point a does not require the manifold to be compact. A Riemannian metric tensor smoothly assigns a positive-definite inner product to each tangent space:

    ga:TaM×TaM⟶ℝ,ga(u,v)=ga(v,u)

    Symmetry exchanges tangent vectors, not points of the manifold. Nondegeneracy means that gₐ(u,v)=0 for every v forces u=0; in coordinates, the component matrix is invertible. Positive definiteness is an additional requirement. On a connected Riemannian manifold, integrating √g(γ̇,γ̇) along curves and taking the infimum defines intrinsic distance between points.

    dg(a,b)=infγ:a→b∫01gγ(t)(γ˙(t),γ˙(t))dt

    A pseudo-Riemannian metric allows indefinite signature. For example, g(v,v)=−v₀²+v₁²+⋯+vₙ² can be positive, negative, or zero with v≠0. Such a form does not automatically yield a nonnegative dissimilarity suitable for the preceding algorithms. Minkowski spacetime geometry must be distinguished from the Minkowski norm family.

    Finally, tensor order and dimension are different concepts: an order-two tensor can have an n×n component matrix. Tensorial status requires a transformation law. For a covariant order-two tensor:

    gij(x)=∑a,b∂ξa∂xi∂ξb∂xjg~ab(ξ(x))

    In Cartesian Euclidean coordinates, g̃ₐᵦ=δₐᵦ, giving the special case gᵢⱼ=∑ₐ(∂ξᵃ/∂xⁱ)(∂ξᵃ/∂xʲ). A data matrix can represent different mathematical objects; rectangular arrangement alone does not identify it as a metric tensor. These distinctions preserve the connection to geometry without assigning a differential structure to a clustering problem before that structure has been constructed.

    The algebraic definitions of nondegeneracy and signature can be checked in SageMath Developers (n.d.). Distinguishing these structures from clustering criteria is part of this revision’s argument.

    12 · R code and checks

    The following program uses only packages included with R. It downloads no data and installs no dependencies. It rejects nonfinite inputs to maintain a common domain and produces tables, diagnostics, and a PDF containing four dendrograms. The audit_distance function checks all sample triples and explicitly has cubic cost.

    Show the complete R program
    # Dissimilarity measures: verifiable examples using base R.
    # Run: Rscript dissimilarity_reproducible_examples.R [output_directory]
    # Columns are comparable coordinates; they are not standardized in this example.
    args <- commandArgs(trailingOnly = TRUE)
    out_dir <- if (length(args)) args[1L] else "disimilaridad_resultados"
    dir.create(out_dir, recursive = TRUE, showWarnings = FALSE)
    
    audit_distance <- function(D, tol = 1e-10) {
      # Exhaustive finite-matrix audit: O(N^3) time.
      D <- as.matrix(D)
      if (!is.numeric(D) || nrow(D) != ncol(D) || nrow(D) < 1L ||
          any(!is.finite(D)) || length(tol) != 1L || !is.finite(tol) || tol <= 0) {
        stop("A finite square numeric matrix and tol > 0 are required.")
      }
      n <- nrow(D)
      eps <- tol * max(1, abs(D))
      diagonal_zero <- max(abs(diag(D))) <= eps
      nonnegative <- min(D) >= -eps
      symmetric <- max(abs(D - t(D))) <= eps
      separated <- if (n == 1L) TRUE else all(D[row(D) != col(D)] > eps)
      max_violation <- -Inf
      for (k in seq_len(n)) {
        max_violation <- max(max_violation, D - outer(D[, k], D[k, ], "+"))
      }
      triangle <- max_violation <= eps
      euclidean <- NA
      min_eigenvalue <- NA_real_
      if (nonnegative && diagonal_zero && symmetric) {
        J <- diag(n) - matrix(1 / n, n, n)
        B <- -0.5 * J %*% (D^2) %*% J
        eigenvalues <- eigen((B + t(B)) / 2, symmetric = TRUE,
                             only.values = TRUE)$values
        min_eigenvalue <- min(eigenvalues)
        euclidean <- min_eigenvalue >= -tol * max(1, abs(eigenvalues))
      }
      c(diagonal_zero = diagonal_zero, nonnegative = nonnegative,
        symmetric = symmetric, separated = separated, triangle = triangle,
        metric = diagonal_zero && nonnegative && symmetric && separated && triangle,
        max_triangle_violation = max(0, max_violation),
        euclidean = euclidean, min_gram_eigenvalue = min_eigenvalue)
    }
    
    X <- rbind(A = c(0, 0), B = c(1, 0.2), C = c(0.3, 2.4),
               D = c(3.5, 3.1), E = c(5.2, 1.3), F = c(5.9, 4.0))
    colnames(X) <- c("x1", "x2")
    stopifnot(all(is.finite(X)))
    D_e <- as.matrix(dist(X, method = "euclidean"))
    D_m <- as.matrix(dist(X, method = "manhattan"))
    D_i <- as.matrix(dist(X, method = "maximum"))
    stopifnot(isTRUE(all.equal(dist(X, method = "minkowski", p = 2),
                             dist(X), check.attributes = FALSE)))
    write.csv(X, file.path(out_dir, "observaciones.csv"))
    write.csv(D_e, file.path(out_dir, "distancias_euclidianas.csv"))
    
    # Counterexample 1: squaring can break the triangle inequality.
    D_line <- as.matrix(dist(matrix(0:2, ncol = 1)))
    check_squared <- audit_distance(D_line^2)
    stopifnot(check_squared["triangle"] == 0,
              abs(check_squared["max_triangle_violation"] - 2) < 1e-10)
    
    # Counterexample 2: 1-r can break the triangle inequality.
    profiles <- rbind(x = c(1, -1, 0), y = c(1, 0, -1), z = c(0, 1, -1))
    stopifnot(all(apply(profiles, 1, sd) > 0))
    R <- cor(t(profiles), use = "all.obs", method = "pearson")
    D_corr <- 1 - R
    D_chord <- sqrt(pmax(2 * D_corr, 0))
    dimnames(D_chord) <- dimnames(R)
    U <- profiles - rowMeans(profiles)
    U <- U / sqrt(rowSums(U^2))
    stopifnot(isTRUE(all.equal(unname(D_chord), unname(as.matrix(dist(U))),
                             tolerance = 1e-10)))
    stopifnot(audit_distance(D_corr)["triangle"] == 0,
              audit_distance(D_chord)["metric"] == 1)
    
    # Same normalized profile: distinct original objects, zero distance.
    x <- c(1, 2, 3)
    y <- c(2, 4, 6)
    stopifnot(abs(cor(x, y) - 1) < 1e-12,
              abs(sqrt(sum((x - y)^2)) - sqrt(14)) < 1e-12)
    
    # Pseudometric and quasi-metric: both directions are retained.
    P <- rbind(P = c(2, 3), Q = c(2, 5), S = c(4, 1))
    D_projection <- abs(outer(P[, 1], P[, 1], "-"))
    v <- c(2, 5, 8)
    Q <- outer(v, v, function(a, b) pmax(b - a, 0))
    Q_s <- pmax(Q, t(Q))
    stopifnot(audit_distance(D_projection)["separated"] == 0,
              Q[1, 2] == 3, Q[2, 1] == 0,
              audit_distance(Q)["triangle"] == 1,
              audit_distance(Q_s)["metric"] == 1)
    
    # Twelve candidates: five adjacent inversions, no ties.
    rank_x <- 1:12
    rank_y <- c(1, 2, 4, 3, 6, 5, 8, 7, 10, 9, 12, 11)
    pairs <- combn(12L, 2L)
    signs <- apply(pairs, 2, function(ij) {
      sign((rank_x[ij[1]] - rank_x[ij[2]]) *
             (rank_y[ij[1]] - rank_y[ij[2]]))
    })
    concordant <- sum(signs > 0)
    discordant <- sum(signs < 0)
    rho_s <- cor(rank_x, rank_y, method = "spearman")
    tau <- cor(rank_x, rank_y, method = "kendall")
    stopifnot(concordant == 61, discordant == 5,
              abs(tau - 56 / 66) < 1e-12,
              abs(rho_s - (1 - 60 / 1716)) < 1e-12)
    
    # With ties, Spearman is Pearson correlation of average ranks.
    tie_x <- c(1, 1, 3, 4)
    tie_y <- c(2, 3, 3, 5)
    stopifnot(isTRUE(all.equal(cor(tie_x, tie_y, method = "spearman"),
                              cor(rank(tie_x), rank(tie_y)))))
    
    # Clusters A={0,2}, B={5,9}: one-dimensional comparisons.
    cluster_A <- c(0, 2)
    cluster_B <- c(5, 9)
    cross <- abs(outer(cluster_A, cluster_B, "-"))
    hausdorff <- max(apply(cross, 1, min), apply(cross, 2, min))
    delta_W <- length(cluster_A) * length(cluster_B) /
      (length(cluster_A) + length(cluster_B)) *
      (mean(cluster_A) - mean(cluster_B))^2
    cluster_results <- c(single = min(cross), complete = max(cross),
                         average = mean(cross), centroid = abs(mean(cluster_A) -
                         mean(cluster_B)), Hausdorff = hausdorff, Ward_deltaW = delta_W)
    stopifnot(isTRUE(all.equal(unname(cluster_results), c(3, 9, 6, 6, 7, 36))))
    
    fits <- list(
      euclidean_complete = hclust(as.dist(D_e), method = "complete"),
      euclidean_single = hclust(as.dist(D_e), method = "single"),
      manhattan_complete = hclust(as.dist(D_m), method = "complete"),
      euclidean_wardD2 = hclust(as.dist(D_e), method = "ward.D2")
    )
    
    # Check every Ward.D2 height against the actual increase in W.
    hc <- fits$euclidean_wardD2
    groups <- vector("list", nrow(hc$merge))
    ward_check <- numeric(nrow(hc$merge))
    for (i in seq_len(nrow(hc$merge))) {
      get_group <- function(j) if (j < 0) -j else groups[[j]]
      a <- get_group(hc$merge[i, 1])
      b <- get_group(hc$merge[i, 2])
      delta <- length(a) * length(b) / (length(a) + length(b)) *
        sum((colMeans(X[a, , drop = FALSE]) - colMeans(X[b, , drop = FALSE]))^2)
      ward_check[i] <- sqrt(2 * delta)
      groups[[i]] <- c(a, b)
    }
    stopifnot(isTRUE(all.equal(hc$height, ward_check, tolerance = 1e-10)))
    
    diagnostics <- rbind(
      euclidean = audit_distance(D_e), manhattan = audit_distance(D_m),
      maximum = audit_distance(D_i), squared_line = check_squared,
      one_minus_r = audit_distance(D_corr), chordal = audit_distance(D_chord),
      projection = audit_distance(D_projection), directed = audit_distance(Q),
      symmetrized = audit_distance(Q_s)
    )
    write.csv(diagnostics, file.path(out_dir, "diagnosticos.csv"))
    write.csv(as.data.frame(cluster_results), file.path(out_dir, "criterios_conglomerados.csv"))
    write.csv(data.frame(concordant, discordant, rho_s, tau),
              file.path(out_dir, "rangos.csv"), row.names = FALSE)
    heights <- do.call(cbind, lapply(fits, function(h) h$height))
    colnames(heights) <- names(fits)
    write.csv(heights, file.path(out_dir, "alturas.csv"), row.names = FALSE)
    partitions <- do.call(cbind, lapply(fits, cutree, k = 3))
    write.csv(partitions, file.path(out_dir, "particiones_k3.csv"))
    for (name in names(fits)) {
      h <- fits[[name]]
      write.csv(data.frame(left = h$merge[, 1], right = h$merge[, 2], height = h$height),
                file.path(out_dir, paste0("fusiones_", name, ".csv")), row.names = FALSE)
    }
    
    pdf(file.path(out_dir, "dendrogramas.pdf"), width = 9, height = 7,
        bg = "#fffdf7", family = "serif", useDingbats = FALSE)
    par(mfrow = c(2, 2), mar = c(3, 4, 3, 1), col = "#2c2418",
        col.axis = "#2c2418", col.lab = "#2c2418", col.main = "#8b4513")
    titles <- c("Euclidean / complete", "Euclidean / single",
                "Manhattan / complete", "Euclidean / Ward.D2")
    for (i in seq_along(fits)) {
      plot(fits[[i]], main = titles[i], sub = "", xlab = "", ylab = "Height", hang = -1)
    }
    invisible(dev.off())
    capture.output(sessionInfo(), file = file.path(out_dir, "sessionInfo.txt"))
    print(round(diagnostics, 8))
    print(cluster_results)
    print(data.frame(concordant, discordant, rho_s, tau))
    print(round(heights, 8))
    print(partitions)
    cat("Checks completed. Results in:", normalizePath(out_dir), "\n")
    

    13 · References and scope of the revision

    The short proofs, counterexamples, and A–F dataset are instructional developments of this revision. References ground conventions and allow implementation checks; synthetic examples are not attributed to those authors.

    Kendall, M. G. (1938). A new measure of rank correlation. Biometrika, 30(1–2), 81–93. https://doi.org/10.1093/biomet/30.1-2.81

    Kendall, M. G. (1945). The treatment of ties in ranking problems. Biometrika, 33(3), 239–251. https://doi.org/10.1093/biomet/33.3.239

    McAuley, L. F. (1956). A relation between perfect separability, completeness, and normality in semi-metric spaces. Pacific Journal of Mathematics, 6(2), 315–326. https://doi.org/10.2140/pjm.1956.6.315

    Murtagh, F., & Legendre, P. (2014). Ward’s hierarchical agglomerative clustering method: Which algorithms implement Ward’s criterion? Journal of Classification, 31, 274–295. https://doi.org/10.1007/s00357-014-9161-z

    R Core Team. (n.d.-a). Correlation, variance and covariance (matrices) [R stats documentation]. Retrieved November 11, 2026, from https://stat.ethz.ch/R-manual/R-devel/library/stats/html/cor.html

    R Core Team. (n.d.-b). Distance matrix computation [R stats documentation]. Retrieved November 11, 2026, from https://stat.ethz.ch/R-manual/R-devel/library/stats/html/dist.html

    R Core Team. (n.d.-c). Hierarchical clustering [R stats documentation]. Retrieved November 11, 2026, from https://stat.ethz.ch/R-manual/R-devel/library/stats/html/hclust.html

    SageMath Developers. (n.d.). Pseudo-Riemannian metrics and degenerate metrics [SageMath reference manual]. Retrieved November 11, 2026, from https://doc.sagemath.org/html/en/reference/manifolds/sage/manifolds/differentiable/metric.html

    Stojmirović, A. (2005). Quasi-metrics, similarities and searches: Aspects of geometry of protein datasets [Doctoral dissertation, Victoria University of Wellington]. arXiv (2008 deposit). https://arxiv.org/abs/0810.5407

    Ward, J. H., Jr. (1963). Hierarchical grouping to optimize an objective function. Journal of the American Statistical Association, 58(301), 236–244. https://doi.org/10.1080/01621459.1963.10500845

    Additional R documentation: cor() · hclust().

  • CONSTRUCTION AND INTERPRETATION OF THE SILHOUETTE COEFFICIENT IN K-MEANS GROUPINGS

    CONSTRUCTION AND INTERPRETATION OF THE SILHOUETTE COEFFICIENT IN K-MEANS GROUPINGS

    Marxist Philosophy of Science · Quantitative methods

    Constructing and Interpreting the Silhouette Coefficient in k-means

    Cohesion, separation, and choosing the number of clusters: foundations, calculations, and reproducible diagnostics.

    Originally published:
    Revised:

    The quality of a clustering cannot be understood by counting its groups. It is examined through the relationships drawing each observation toward its assigned cluster and toward alternatives. The silhouette turns that comparison into an interpretable measure when its construction and limits are made explicit.

    01. What is being validated?

    Creating clusters and justifying them are different tasks. An algorithm can return a partition even when the data contain no clusters useful for the research question. The computational result, the geometric criterion used to assess it, and the interpretation of the phenomenon therefore need to be distinguished.

    The silhouette coefficient, introduced by Rousseeuw (1987), examines how close an observation is to its assigned cluster relative to an alternative. It diagnoses a partition under the chosen dissimilarities; it does not establish, on its own, that the groups represent natural classes.

    ApproachQuestionExample
    Internal validationWhat structure does the partition display under the data and dissimilarities?Silhouette; Calinski–Harabasz or Davies–Bouldin indices.
    External validationHow does the partition relate to an independent reference classification?Adjusted Rand index when comparable reference labels are available.
    Relative comparisonWhich solution is preferable among specified alternatives?Comparing silhouettes across candidate values of k.

    These perspectives can overlap: an internal measure can be used to compare solutions. External labels are not automatically the truth about the phenomenon, and their availability does not imply that the number of geometric clusters must match the number of classes.

    02. What k-means optimizes

    Let x1, …, xn be numerical vectors and C1, …, Ck a partition into nonempty clusters. In standard k-means, each center μg is the arithmetic mean of the observations assigned to its cluster. The objective is to reduce within-cluster sum of squares:

    W(k) = ∑g=1k ∑i∈Cg ‖xi − μg‖2,μg = (1 / |Cg|) ∑i∈Cg xi.

    Common algorithms can terminate at local optima. Multiple initializations reduce dependence on a single starting choice, but provide no universal guarantee of a global optimum. In R, nstart specifies how many initial sets of centers are tried (Hartigan & Wong, 1979; R Documentation, n.d.-b).

    The learned centroids should be distinguished from configuration choices: k, the initialization strategy, the number of attempts, and the iteration limit. The random seed controls reproducibility; it is not a substantive property of the data.

    Euclidean geometry is part of standard k-means. If another dissimilarity is needed, a compatible procedure must be justified, such as k-medoids for appropriate dissimilarity matrices. Evaluating an existing partition with a different dissimilarity is possible, but changes the diagnostic question and must be reported.

    03. Constructing the silhouette coefficient

    Fix a partition and a dissimilarity d(i, j) that is nonnegative, symmetric, and zero on the diagonal. The classical construction uses pairwise dissimilarities rather than replacing each cluster with its centroid. Here we use Euclidean distance, which reduces to the absolute difference in one dimension.

    1. Average within-cluster dissimilarity: a(i)

    If C(i) is the cluster containing observation i and contains at least two observations, average the dissimilarities from i to its other members. The self-distance is excluded:

    a(i) = ∑j∈C(i), j≠i d(i, j)|C(i)| − 1.

    2. Dissimilarity to each alternative cluster

    For every cluster C that does not contain i, calculate a separate average:

    d̄(i, C) = ∑j∈C d(i, j)|C|.

    3. Choosing the neighboring cluster: b(i)

    The smallest of those averages defines b(i). Average within each alternative cluster first, then take the minimum:

    b(i) = minC≠C(i) d̄(i, C).

    The neighboring cluster depends on observation i. It is not necessarily found by locating the nearest external point, the closest centroid, or the cluster closest to C(i) as a whole. If several alternatives tie for the minimum average, b(i) remains defined even though the neighbor label may not be unique.

    4. Normalization

    s(i) = b(i) − a(i)max{a(i), b(i)},   −1 ≤ s(i) ≤ 1.

    The numerator expresses the advantage of the current assignment over the alternative; the denominator places the values on a bounded scale. When the denominator is positive, an equivalent expression makes the sign explicit:

    ConditionEquivalent expressionReading
    a(i) < b(i)s(i) = 1 − a(i)/b(i)The assigned cluster is closer on average.
    a(i) = b(i) > 0s(i) = 0Equal average dissimilarity to the two options.
    a(i) > b(i)s(i) = b(i)/a(i) − 1The alternative cluster is closer on average.

    The formula and the singleton convention correspond to the classical silhouette implemented in cluster::silhouette() (R Documentation, n.d.-a).

    Multiplying every dissimilarity by the same positive constant leaves s(i) unchanged: the common factor cancels between numerator and denominator. Scaling individual features differently can change both the partition and its evaluation.

    04. A worked example: from distances to the score

    Consider nine one-dimensional observations and a fixed partition: A = {0, 1, 2}, B = {6, 7, 8}, and C = {12, 13, 14}. These are synthetic data with no empirical interpretation attached. We use d(i, j) = |xi − xj|.

    Hand-worked example: three groups on a lineA: 0, 1, 2. B: 6, 7, 8. C: 12, 13, 14. i = 2; a(i) = 1.5; b(i) = 5; s(i) = 0.70. 2026-11-11T17:01:32.009716 image/svg+xml Matplotlib v3.10.8, https://matplotlib.org/ 0 1 2 6 7 8 12 13 14 i = 2 A = {np.int64(0), np.int64(1), np.int64(2)} B = {np.int64(6), np.int64(7), np.int64(8)} C = {np.int64(12), np.int64(13), np.int64(14)}
    Figure 1. Positions of the nine observations. Marker shapes distinguish clusters; the arrow identifies observation x = 2.

    For x = 2, the assigned cluster is A. The table contains every relevant distance:

    DestinationObservationsDistances from x = 2Average
    A, excluding itself0, 12, 1a(i) = (2 + 1)/2 = 1.5
    B6, 7, 84, 5, 6d̄(i, B) = 15/3 = 5
    C12, 13, 1410, 11, 12d̄(i, C) = 33/3 = 11
    b(i) = min{5, 11} = 5,s(i) = (5 − 1.5)/5 = 0.70.

    The observation has lower average dissimilarity to its assigned cluster than to B, the closest alternative. The score 0.70 expresses that normalized relationship; it is neither a membership probability nor an accuracy of 70%.

    How zero and negative scores arise

    Now change only the third point in A: A = {0, 1, t}. B and C retain their values. Each row below represents a different modified dataset, with labels held fixed:

    ta(t)b(t)s(t)
    21.550.700000
    3.753.253.250.000000
    54.52−0.555556
    s(5) = (2 − 4.5)/4.5 = −5/9 ≈ −0.555556.

    At t = 3.75, the two relevant average dissimilarities are equal. At t = 5, B is closer on average than A. These cases diagnose specified partitions; they are not presented as outcomes of refitting k-means.

    05. Individual, cluster-level, and overall interpretation

    An s(i) close to 1 indicates high relative cohesion compared with the neighboring cluster; around zero, the average dissimilarities are similar; a negative score indicates that the alternative is closer on average. These readings depend on the data, features, and chosen dissimilarity.

    A negative silhouette invites closer examination. It does not, by itself, prove a programming error or require reassignment: the k-means objective and the silhouette criterion differ. Nor does it establish that the observation is an outlier.

    s̄g = (1 / ng) ∑i∈Cg s(i),s̄ = (1 / n) ∑i=1n s(i)= ∑g=1k (ng / n) s̄g.

    The overall mean weights each cluster by its size. Taking an unweighted average of cluster means answers another question and agrees with the overall mean only in particular cases, such as equally sized clusters.

    Table 3. Complete results for the original hand-worked example.
    xClustera(i)b(i)s(i)
    0A1.57.00.785714
    1A1.06.00.833333
    2A1.55.00.700000
    6B1.55.00.700000
    7B1.06.00.833333
    8B1.55.00.700000
    12C1.55.00.700000
    13C1.06.00.833333
    14C1.57.00.785714

    The cluster means are s̄A = 0.773016, s̄B = 0.744444, and s̄C = 0.773016. Because each cluster contains three observations, s̄ = 481/630 ≈ 0.763492.

    Individual silhouettes sorted within clustersReference mean = 0.763492; moving the third point to x = 5 gives s(5) = -0.555556. Dashed lines indicate each partition mean. Each horizontal bar represents one observation. 2026-11-11T17:01:32.105839 image/svg+xml Matplotlib v3.10.8, https://matplotlib.org/ −1 0 1 s(i) A · 1 A · 0 A · 2 B · 7 B · 8 B · 6 C · 13 C · 14 C · 12 Mean = 0.76349 Reference partition −1 0 1 s(i) A · 1 A · 0 A · 5 B · 7 B · 8 B · 6 C · 13 C · 14 C · 12 Mean = 0.56036 Moved point: x = 5
    Figure 2. Silhouettes sorted within each cluster. Left: the reference partition. Right: the modified dataset with x = 5. Each bar represents an observation; dashed lines indicate the mean of each partition.

    Read the plot by examining bar lengths, negative scores, cluster sizes, and differences between clusters. The display reveals the distribution summarized by a single mean (Rousseeuw, 1987).

    06. Comparing k without treating the maximum as truth

    For a candidate set K, one can select the partition with the largest mean silhouette:

    k̂ ∈ arg maxk∈K s̄(k).

    This selection is relative to K, the data, preprocessing, and fitting procedure. It neither confirms that clusters exist nor assesses k = 1. When several solutions score similarly, retain them for graphical and substantive examination.

    To avoid the symmetric ties in the hand-worked example, now use a different synthetic dataset: {0, 0.8, 2, 6, 7.3, 8, 12, 13.2, 15.5}. All values share one unit. The table reports solutions minimizing W(k) for this small one-dimensional problem; the code includes an exhaustive check over contiguous partitions.

    Table 4. Second example: these scores must not be confused with the hand-worked mean of 0.763492.
    kW(k)Mean silhouetteMinimum sizeSingleton clusters
    267.4550000.58209830
    310.4133330.72121130
    44.8066670.62866111
    52.9916670.49125612
    61.2850000.35336413
    Comparing k: silhouette and sum of squaresFor the irregular nine-point example, mean silhouettes for k = 2, 3, 4, 5, 6 are 0.582098, 0.721211, 0.628661, 0.491256, 0.353364. Within-cluster sum of squares decreases throughout. 2026-11-11T17:01:32.286744 image/svg+xml Matplotlib v3.10.8, https://matplotlib.org/ 2 3 4 5 6 k 0.0 0.2 0.4 0.6 0.8 1.0 Mean silhouette k = 3 0.72121 2 3 4 5 6 k 0 10 20 30 40 50 60 70 Within-cluster sum of squares
    Figure 3. In the second example, W(k) decreases as k increases, while the mean silhouette reaches its maximum among the candidates at k = 3, with a score of 0.721211.

    For k = 3, the clusters are {0, 0.8, 2}, {6, 7.3, 8}, and {12, 13.2, 15.5}. Here, further reductions in W(k) from splitting the data are not accompanied by higher silhouettes. Singleton clusters in later solutions contribute zero silhouette by convention.

    CriterionWhat it examinesHow to use it
    Elbow in W(k)Marginal improvement as the number of centroids increases.Look for slope changes; a distinct elbow may be absent.
    SilhouetteRelative cohesion against the best alternative cluster.Compare means and within-cluster distributions.
    Initialization sensitivityVariation when random seeds change.Repeat complete fits while keeping preprocessing fixed.
    Sampling stability and interpretationPersistence and relevance of clusters for the problem.Examine resampling, profiles, and domain knowledge.

    These criteria provide complementary evidence. Sensitivity to the seed and stability under changes to the sample are different properties: repeating random seeds does not estimate sampling uncertainty.

    07. A reproducible, audited implementation in R

    The following script contains the data, an independent implementation of the formula, checks of the hand-worked example, fitting with multiple initializations, and comparison of k = 2, …, 6. For each k, kmeans() retains the best fit according to within-cluster sum of squares, not silhouette (R Documentation, n.d.-b).

    The code also checks the minimum sum of squares by enumeration for this small univariate case. That audit exploits n = 9 and the ordered line; it should not be generalized into an efficient strategy for large multivariate problems. Numerical cluster labels can be permuted without changing the partition.

    # Silhouette coefficient: worked examples and k-means comparison
    # Original article: 2022-04-21 | Revision: 2026-11-11
    # Dependency: install.packages("cluster") if it is not already available.
    if (!requireNamespace("cluster", quietly = TRUE)) {
      stop('Install the cluster package first: install.packages("cluster")')
    }
    
    # Independent calculation from a complete dissimilarity matrix.
    silhouette_manual <- function(labels, D) {
      D <- as.matrix(D)
      n <- length(labels)
      stopifnot(n >= 3L, !anyNA(labels), is.numeric(D),
                all(dim(D) == c(n, n)), all(is.finite(D)),
                all(D >= 0), max(abs(D - t(D))) < 1e-10,
                max(abs(diag(D))) < 1e-10)
      groups <- unique(labels)
      stopifnot(length(groups) >= 2L, length(groups) <= n - 1L)
      s <- numeric(n)
      for (i in seq_len(n)) {
        own <- which(labels == labels[i])
        if (length(own) == 1L) {
          s[i] <- 0
          next
        }
        a <- mean(D[i, setdiff(own, i)])
        other <- groups[groups != labels[i]]
        means <- vapply(other, function(g) mean(D[i, labels == g]), numeric(1))
        b <- min(means)
        s[i] <- if (max(a, b) == 0) 0 else (b - a) / max(a, b)
      }
      s
    }
    
    # 1. Exact hand-worked example; distances are absolute differences.
    x_hand <- matrix(c(0, 1, 2, 6, 7, 8, 12, 13, 14), ncol = 1)
    labels_hand <- rep(1:3, each = 3)
    D_hand <- dist(x_hand, method = "euclidean")
    s_hand <- cluster::silhouette(labels_hand, D_hand)
    stopifnot(max(abs(silhouette_manual(labels_hand, D_hand) -
                      s_hand[, "sil_width"])) < 1e-12,
              abs(s_hand[3, "sil_width"] - 0.7) < 1e-12,
              abs(mean(s_hand[, "sil_width"]) - 481 / 630) < 1e-12)
    print(data.frame(x = x_hand[, 1], cluster = labels_hand,
                     silhouette = round(s_hand[, "sil_width"], 6)))
    
    # Moving only the third point creates positive, zero and negative examples.
    for (t in c(2, 3.75, 5)) {
      xt <- x_hand
      xt[3, 1] <- t
      actual <- cluster::silhouette(labels_hand, dist(xt))[3, "sil_width"]
      a <- mean(abs(t - c(0, 1)))
      b <- min(mean(abs(t - c(6, 7, 8))), mean(abs(t - c(12, 13, 14))))
      expected <- (b - a) / max(a, b)
      stopifnot(abs(actual - expected) < 1e-12)
      cat(sprintf("t = %.2f; a = %.2f; b = %.2f; s = %.6f\n", t, a, b, actual))
    }
    
    # Check singleton, coincident-point and zero-denominator conventions.
    for (case in list(
      list(x = c(0, 1, 10), labels = c(1L, 1L, 2L)),
      list(x = c(0, 0, 0, 0), labels = c(1L, 1L, 2L, 2L)),
      list(x = c(0, 0, 10, 10), labels = c(1L, 1L, 2L, 2L))
    )) {
      dd <- dist(matrix(case$x, ncol = 1))
      reference <- cluster::silhouette(case$labels, dd)[, "sil_width"]
      stopifnot(all(is.finite(reference)),
                max(abs(silhouette_manual(case$labels, dd) - reference)) < 1e-12)
    }
    
    # 2. Irregular synthetic data: avoids the ties of the hand-worked example.
    x <- matrix(c(0, 0.8, 2, 6, 7.3, 8, 12, 13.2, 15.5), ncol = 1,
                dimnames = list(paste0("P", 1:9), "x"))
    stopifnot(is.numeric(x), all(is.finite(x)), nrow(unique(x)) >= 6L)
    # All observations use one common unit. No scaling is needed here.
    # For multivariate data, justify feature selection and scaling before fitting.
    # x <- scale(x)  # Optional; do not standardize constant columns.
    D <- dist(x, method = "euclidean")
    ks <- 2:6
    models <- vector("list", length(ks))
    silhouettes <- vector("list", length(ks))
    rows <- vector("list", length(ks))
    for (j in seq_along(ks)) {
      k <- ks[j]
      set.seed(20220421L + k)
      fit <- kmeans(x, centers = k, nstart = 100, iter.max = 100,
                    algorithm = "Hartigan-Wong")
      if (!is.null(fit$ifault) && fit$ifault != 0L) stop("k-means did not converge")
      s <- cluster::silhouette(fit$cluster, D)
      stopifnot(max(abs(silhouette_manual(fit$cluster, D) -
                        s[, "sil_width"])) < 1e-12)
      models[[j]] <- fit
      silhouettes[[j]] <- s
      rows[[j]] <- data.frame(k = k, within_ss = fit$tot.withinss,
                              mean_silhouette = mean(s[, "sil_width"]),
                              negative_fraction = mean(s[, "sil_width"] < 0),
                              smallest_cluster = min(fit$size),
                              singleton_clusters = sum(fit$size == 1L))
    }
    results <- do.call(rbind, rows)
    print(results, digits = 7, row.names = FALSE)
    best <- which.max(results$mean_silhouette)
    cat("Selected k among the candidates:", results$k[best], "\n")
    print(summary(silhouettes[[best]]))
    
    # Audit the small ONE-DIMENSIONAL example against all contiguous partitions.
    # This is feasible only because n = 9; it is not a general-purpose workflow.
    # For sorted univariate squared-error k-means, a global optimum is contiguous.
    x_sorted <- sort(x[, 1])
    exact_sse <- vapply(ks, function(k) {
      cuts <- combn(seq_len(length(x_sorted) - 1L), k - 1L)
      min(apply(cuts, 2, function(cut) {
        starts <- c(1L, cut + 1L)
        ends <- c(cut, length(x_sorted))
        sum(vapply(seq_len(k), function(g) {
          z <- x_sorted[starts[g]:ends[g]]
          sum((z - mean(z))^2)
        }, numeric(1)))
      }))
    }, numeric(1))
    stopifnot(max(abs(results$within_ss - exact_sse)) < 1e-10,
              results$k[best] == 3L,
              abs(results$mean_silhouette[best] - 0.7212109713028838) < 1e-12)
    
    # 3. Repeat the entire fitting procedure with different seeds.
    # These ranges describe initialization sensitivity, not sampling uncertainty.
    seeds <- 1:20
    stability <- do.call(rbind, lapply(ks, function(k) {
      means <- vapply(seeds, function(seed) {
        set.seed(seed)
        fit <- kmeans(x, centers = k, nstart = 100, iter.max = 100)
        mean(cluster::silhouette(fit$cluster, D)[, "sil_width"])
      }, numeric(1))
      data.frame(k = k, minimum = min(means), median = median(means),
                 maximum = max(means))
    }))
    print(stability, digits = 7, row.names = FALSE)
    
    # 4. Export the complete analysis to the current working directory.
    write.csv(results, "silhouette_k_comparison.csv", row.names = FALSE)
    write.csv(stability, "silhouette_initialization_sensitivity.csv", row.names = FALSE)
    write.csv(data.frame(id = rownames(x), x = x[, 1],
                         cluster = models[[best]]$cluster,
                         silhouette = silhouettes[[best]][, "sil_width"]),
              "silhouette_individual_results.csv", row.names = FALSE)
    paper <- "#fffdf7"
    ink <- "#2c2418"
    copper <- "#8b4513"
    pdf("silhouette_diagnostics.pdf", width = 7, height = 6, bg = paper)
    par(col = ink, col.axis = ink, col.lab = ink, col.main = ink,
        fg = ink, bg = paper)
    plot(results$k, results$mean_silhouette, type = "b", pch = 19,
         col = copper, xlab = "Number of clusters (k)",
         ylab = "Mean silhouette", ylim = c(0, 1))
    plot(silhouettes[[best]], col = copper, border = NA,
         main = paste("Silhouette | k =", results$k[best]))
    abline(v = results$mean_silhouette[best], lty = 2, col = ink)
    plot(results$k, results$within_ss, type = "b", pch = 19,
         col = copper, xlab = "Number of clusters (k)",
         ylab = "Within-cluster sum of squares")
    dev.off()
    writeLines(capture.output(sessionInfo()), "silhouette_session_info.txt")
    

    In addition to the displayed tables, the script writes three CSV files, a PDF containing diagnostic plots, and a session-information file. Files are created in R’s current working directory. The twenty-seed repetition describes initialization sensitivity in this example; it is not a confidence interval.

    08. Limitations and choices that must be reported

    The silhouette tends to favor convex, separated clusters under the chosen geometry. Elongated, chained, or density-defined structures may score poorly even when they matter for the problem. Comparing algorithms therefore requires a shared interpretation of what constitutes a cluster (scikit-learn developers, n.d.).

    • Features and scales. Units and weights change dissimilarities. Standardization is an analytical choice, not an automatic correction appropriate for every problem.
    • Outliers and unequal sizes. Examine their effect on averages and small clusters. Report cluster means, sizes, and problematic observations alongside the overall mean.
    • High dimensionality. Assess whether the selected distances retain useful contrasts. A projection used for visualization does not replace the geometry used to fit and evaluate the model.
    • Candidates and comparability. Use the same observations and dissimilarity for a direct comparison; document any changes.
    • Computational cost. A full distance matrix requires memory of order n². Sampling can reduce the diagnostic cost, but specify whether averages use only the subsample or all observations as references.
    • Absence of structure. Examine suitable reference scenarios or stability before assigning meaning to a maximum. An available partition is not equivalent to confirmed empirical structure.

    When using resampling, describe observation selection, refitting, and the comparison between partitions. Cluster labels are arbitrary: directly comparing their numerical values does not measure stability.

    09. Mathematical note: cluster geometry and topology

    This revision preserves the mathematical interest of Nabi (2022) while clarifying its vocabulary. Similar terminology does not justify identifying different definitions.

    In clusteringIn topology or algebraNecessary distinction
    Geometric cohesion or compactnessCompactness: every open cover has a finite subcover.Every finite set is compact, even when its points are far apart.
    Separation between clustersSeparability: existence of a countable dense subset.It does not quantify between-cluster distance; ℝᵖ is separable in its usual topology.
    Neighborhood connectivityConnectedness: absence of a separation into disjoint nonempty relatively open sets.A neighbor graph and the topology of the observed point set are different constructions.
    A subset of observationsVector subspace: contains zero and is closed under addition and scalar multiplication.An arbitrary cluster of observations need not satisfy these conditions.

    Two examples make the difference explicit. {0, 1} and {0, 1000} are compact subsets of ℝ, although their diameters are 1 and 1000. Every finite set of distinct points in ℝᵖ also has the discrete relative topology: a sufficiently small ball isolates each point. With more than one point, the set is disconnected even when it looks like a very tight cloud.

    For a subset C of a topological space, a relevant separation would be C = U ∪ V, where U and V are nonempty, disjoint, relatively open subsets of C: U ∩ V = ∅. Their union reconstructs C; their intersection records shared elements. C is connected when no such separation exists.

    An open Euclidean ball contains points whose distance from its center is less than its radius; the sphere consists of points at exactly that distance. Neither definition alone turns a statistical cluster into a connected region.

    These distinctions use definitions of metric spaces and compactness ({cite(‘lebl’,’Lebl, n.d.’)}). Rigorous links to topology require explicitly defining an additional structure, such as a graph or a union of balls, and then studying its properties.

    10. How to report the result

    A useful report identifies the data and features, preprocessing, algorithm and options, evaluation dissimilarity, candidate values of k, and sensitivity of the result. It accompanies the overall mean with cluster sizes and cluster-level diagnostics.

    For nine synthetic one-dimensional observations, k = 2, …, 6 were compared using k-means and Euclidean distance. The largest mean silhouette among the candidates was 0.721211 at k = 3. This choice was interpreted alongside within-cluster sum of squares, cluster sizes, and individual diagnostics.

    The conclusion states which evidence supports the selected solution and under what conditions. Its ultimate usefulness depends on whether the clusters help answer the research question.

    11. References

  • ALGEBRAIC STRUCTURES: AN ANALYSIS FROM THE MARXIST PHILOSOPHY OF SCIENCE

    ALGEBRAIC STRUCTURES: AN ANALYSIS FROM THE MARXIST PHILOSOPHY OF SCIENCE

    Marxist philosophy of science · Mathematics notebook

    Algebraic Structures

    Structure, invariance, and transformation from the standpoint of dialectical materialism

    Originally published:
    Revised and expanded edition:

    Abstract

    A mathematical structure is identified through the relations it organizes and the transformations that preserve them. This essay examines operations, groups, rings, and fields; connects algebras of sets with measure and probability; and develops a dialectical-materialist interpretation of essence as the articulation of structural layers. The discussion of quantity, quantum, degree, and measure culminates in two applications: qualitative transformation in a dynamical system and the construction of σ-additive functions associated with additive genetic models. In each case, the objects, assumptions, and scope of inference are specified.

    Concepts: abstract algebra · isomorphism · essence · invariants · σ-algebra · measure · quantitative genetics · dialectical materialism

    I · The problem

    Knowing an object means investigating its relations

    A collection of elements does not exhaust our knowledge of a system. What matters includes the relations among its components, the operations that can be performed on them, and the conditions under which the whole preserves or transforms its organization. The difference between an inventory and a structure raises a question shared by abstract algebra and materialist philosophy: what determines that something is the system it is?

    Algebra answers by specifying operations and axioms. Concrete scientific investigation must also explain how its objects acquire those relations, which processes reproduce them, and under what conditions they change. Dialectical materialism provides an orientation here: to study objects through their connections, motion, and historical determinations. Mathematical formalization makes aspects of those connections precise and allows the consequences of explicit assumptions to be proved.

    From this perspective, historical materialism provides categories for investigating the organization and transformation of societies, while dialectical materialism guides reflection on the more general relations among structure, process, and knowledge. An algebraic identity can contribute to a social model; its explanatory relevance depends on historical mediations and investigation of the object. The social content of a relation of production requires determinations that cannot be obtained from its formal expression alone.

    In the introduction of 1857, Marx develops the problem of intellectually reconstructing a concrete whole comprising multiple determinations. We take up that orientation to ask what each structure abstracts and what must be restored to understand a concrete system (Marx, 1973, Introduction, § 3). The exposition proceeds from elementary operations to questions of measure and modeling, maintaining three questions: what is defined, what is proved, and what interpretation is proposed.

    II · Language and operations

    From operands to composition laws

    2.1. Function, operation, operator, and symbol

    A function f: A → B assigns a unique element of its codomain B to each element of its domain A. The arrow indicates this assignment between sets. It should be distinguished from logical implication, usually written ⇒. The domain, codomain, and assignment rule are part of the specification of a function.

    An operation combines inputs to produce an output. Its inputs are called operands; the sign used to represent it is its symbol. In a + b, the operands are a and b, and + represents addition. The same notation may denote different operations on numbers, matrices, or functions; its meaning comes from the specified structure.

    The term operator depends on context. In functional analysis it often denotes a map between function spaces or vector spaces, frequently a linear one. A linear operator on V is a linear endomorphism T: V → V. The word map is a general term for function, even when its domain and codomain differ. Identifying an operator with its symbol is insufficient when studying its mathematical properties.

    2.2. Internal operations

    An internal binary operation on a set A is a function of two arguments whose values belong to A:

    ∗: A × A → A,   (a,b) ↦ a ∗ b.Each ordered pair has a unique result in A.

    The symbol A × A represents the Cartesian product: the set of ordered pairs of elements of A. Closure is built into the codomain. Integer addition is internal to ℤ; division does not define a total internal operation on ℤ, because some quotients are not integers and division by zero is excluded.

    A function A × B → C is generally a two-argument operation with possibly different input and output types. An internal operation on a single set is obtained only when these three roles are appropriately identified. Distance between points in the plane, for example, has type d: ℝ2 × ℝ2 → [0,∞): it produces a number from two points. This function is not a group operation on the points of the plane.

    2.3. Left and right external operations

    An external operation relates elements of sets playing different roles. For a scalar set K and a set V, the usual forms are:

    K × V → V,   (λ,v) ↦ λv,V × K → V,   (v,λ) ↦ vλ.Left and right actions, respectively.

    Input and output types must remain consistent. Furthermore, a map of this type becomes a group action or scalar multiplication for a module or vector space when it satisfies the corresponding axioms. The function type alone is insufficient. “External” describes the structural roles of the operands; it does not require their underlying sets to be disjoint.

    2.4. What an algebraic structure contains

    In the elementary case, an algebraic structure consists of a nonempty set with specified operations, together with axioms determining the class under consideration. We may write (A,∗) or (A,+,·,0,1). A tuple records the data; the axioms express their relations. There are also structures with several underlying sets, such as a vector space and its scalar field.

    This observation raises a philosophical question: structural identity depends on the relations selected. The same set of integers can be studied as a set, an additive group, a ring, or an ordered set. Each choice preserves information and abstracts from other determinations. Scientific knowledge requires a justification of why those relations are relevant to the problem being investigated.

    III · Fundamental structures

    Groups, rings, fields, and vector spaces

    3.1. Groups and abelian groups

    A group (G,∗) has an associative internal binary operation, an identity element, and an inverse for every element. For any a,b,c ∈ G:

    (a ∗ b) ∗ c = a ∗ (b ∗ c),e ∗ a = a ∗ e = a,a ∗ a-1 = a-1 ∗ a = e.

    Identity and inverse are defined with respect to an operation. In (ℤ,+), the identity is 0 and the inverse of a is −a. In (ℝ ∖ {0},·), they are 1 and 1/a. A group is abelian if it also satisfies a ∗ b = b ∗ a.

    The bijections of a set onto itself form a group under composition. Composition allows the inverse to be interpreted as an operation that reverses another transformation. In noncommutative groups, composition order affects the result; certain rotations of three-dimensional space provide an example. This dependence on order can model aspects of concrete processes when the operations and their conditions have been identified.

    3.2. Rings and semirings

    We adopt the convention that a ring R is associative and has a multiplicative identity. Its addition forms an abelian group; its multiplication is associative; and the operations are related by the distributive laws:

    a(b + c) = ab + ac,(a + b)c = ac + bc.

    In particular, a + 0 = 0 + a = a, whereas a + (−a) = 0. A ring is commutative when its multiplication is commutative. Rings without identity are also studied; they will be explicitly identified when they appear. Such conventions must remain consistent throughout an exposition (Milne, 2022, “Rings” section).

    The integers form a commutative ring: (ℤ,+,·). Square matrices of size n ≥ 2 with real entries form a generally noncommutative ring. Distributive compatibility allows two kinds of operation to be combined on the same underlying set. A ring has an underlying additive group; multiplication adds structure.

    An algebraic semiring, under the usual convention with identity, replaces the additive group with a commutative monoid: it retains associative addition, zero, and commutativity, but does not require additive inverses. Multiplication is associative with identity, distributes over addition, and has zero as an absorbing element. (ℕ0,+,·) is an example. We will later encounter a semiring of sets, a term used in measure theory with a specific definition.

    3.3. Fields, division rings, and algebras

    A field F is a commutative ring with 1 ≠ 0 in which every nonzero element has a multiplicative inverse. Equivalently, (F,+) and (F ∖ {0},·) must be abelian groups compatible through distributivity. The rational, real, and complex numbers are examples.

    In a division ring, nonzero elements are invertible and multiplication may be noncommutative. The quaternions provide an example. An algebra over a field additionally incorporates a vector-space structure and a bilinear multiplication. A division algebra is defined in that context; the scalar field and associativity conventions should therefore be specified, rather than using all these names interchangeably.

    An additional operation changes the questions we can ask
    StructureOperations and requirementsExample
    Abelian groupOne internal operation with associativity, identity, inverses, and commutativity.(ℤ,+)
    RingAn additive abelian group and an associative, distributive multiplication; here, with identity.ℤ; matrices M2(ℝ)
    FieldA commutative ring, 1 ≠ 0, and multiplicative inverses for nonzero elements.ℚ, ℝ, ℂ
    Vector spaceAn additive abelian group and external multiplication by a field, satisfying the compatibility axioms.ℝ2 over ℝ

    3.4. Vector spaces, modules, and Hilbert spaces

    A vector space V over F has internal addition and external scalar multiplication. For scalars λ,η and vectors u,v:

    λ(u + v) = λu + λv,   (λ + η)v = λv + ηv,(λη)v = λ(ηv),   1v = v.

    Multiplication of two vectors is not part of those axioms. A field is a vector space over itself and, more generally, over any of its subfields; this expresses a relation between specified structures. A module generalizes scalar multiplication by replacing the field with a ring, with distinctions between left and right modules when multiplication is noncommutative.

    An inner product allows the norm ‖v‖ = √⟨v,v⟩ and distance d(u,v) = ‖u−v‖ to be defined. A Hilbert space is an inner-product space complete in that norm: every Cauchy sequence converges in the space. It may be finite- or infinite-dimensional; separability is an additional property. In finite dimensions, a real Euclidean space with its inner product is a special case.

    IV · Preservation and history

    Isomorphisms and the formation of the concept of structure

    4.1. What a homomorphism preserves

    A group homomorphism f: G → H preserves the operation:

    f(a ∗ b) = f(a) ⋆ f(b).∗ and ⋆ are the operations of G and H.

    If it is bijective, it is a group isomorphism. Its inverse also preserves the operation. A ring isomorphism must preserve both operations and, under our convention, the identity. An automorphism is an isomorphism of a structure onto itself; an endomorphism is a homomorphism from a structure to itself.

    “Classification up to isomorphism” means identifying structures that are equivalent with respect to the type of structure under consideration. For example, a group isomorphism preserves the order of each element and commutativity. It need not preserve an additional distance that is not part of the algebraic data. For more general relational structures, preservation and reflection of relations must also be specified.

    Three related concepts should be distinguished: the inverse of an element with respect to an operation, the inverse of a function, and an isomorphism as a structure-preserving correspondence. Inverse functions satisfy f-1 ∘ f = id; isomorphisms add preservation requirements. This precision allows the philosophical relation between reversibility and identity to be developed without making the entire notion of structure depend on a single kind of inverse.

    4.2. Example: transforming addition into multiplication

    Consider f(x) = ex from the real numbers with addition to the positive real numbers with multiplication:

    exp: (ℝ,+) → (ℝ>0,·),exp(x + y) = exp(x) exp(y),exp(0) = 1,   exp(−x) = exp(x)-1.

    The exponential is bijective on these domains, with the logarithm as its inverse. The two groups are therefore isomorphic. Addition on one side corresponds to multiplication on the other: symbols and elements differ, but the composition law is transported exactly. This equivalence concerns the group; it does not assert that the exponential preserves Euclidean distance.

    4.3. A history involving several mediations

    The modern notion of structure emerged through interactions among algebraic, geometric, physical, and philosophical problems. Timmermans’s historical study reconstructs connections among crystallography, transformation groups, and philosophy; it also shows that the historical meaning of “isomorphism” was not uniform. Correspondences called holohedral and merihedral cannot simply be translated into current terminology (Timmermans, 2012).

    This development includes Leibniz’s ideas of similarity, the study of crystal symmetries, and the subsequent elaboration of groups and composition relations. Weyl connected structure with isomorphism in a text of 1927; in the twentieth century, Bourbaki systematized a perspective in which the type of structure determines its admissible correspondences. This history requires distinguishing the first appearance of a word, the study of particular cases, and the formulation of a general definition.

    Crystallography is particularly significant for a materialist interpretation: spatial arrangements and symmetry operations provided problems that stimulated structural abstraction. When applied to other domains, abstraction preserves selected relations and makes new consequences available for investigation. Its emergence and application in turn require specific historical inquiry.

    In the Soviet philosophical tradition, the entries “Structure” and “Isomorphism” connect the stability of relations with modeling and knowledge of the object. The 1984 reworking emphasizes the multiplicity of structures within a single system and the transformation of its relations (Rosental & Iudin, 1965; Frolov, 1984). This perspective makes it possible to move from abstract structure to the question of how its determinations are materially articulated.

    V · Essence and determinations

    Essence as the articulation of structural layers

    5.1. A unity with several determinations

    The analysis of essence can be organized through mathematical layers specifying constitutive relations and invariants. This formulation, developed in the manuscript Geometry, History, and Lawfulness, allows the same object to be investigated through distinct, articulated determinations (Gómez Julián, 2026, §§ 1.2–1.8). The algebraic layer is central here: it identifies operations and compatibilities that cannot be reduced to the number of elements or to a geometric outline.

    A layer expresses an aspect of the object’s organization and the type of transformation under which it is preserved. Articulating layers requires dependencies to be specified: a Riemannian metric is defined on a smooth manifold; an algebraic structure can be studied with or without a compatible topology; the history of a process may require additional information about causality and inherited constraints. The same system is thus investigated through different levels of determination.

    Layers, preservation, and research questions
    LayerWhat is specified and preservedRelevant transformation
    Set-theoreticCorrespondence between elements and cardinality.Bijection.
    AlgebraicOperations and composition relations.Isomorphism of the relevant algebraic type.
    TopologicalOpen sets, continuity, connectedness, and compactness.Homeomorphism.
    DifferentiableSmooth structure and compatible differential calculus.Diffeomorphism.
    MetricDistances; in Riemannian geometry, the metric tensor, lengths, and angles.Isometry.
    OperationalComposition of admissible transformations and symmetries.Automorphisms; groups and actions when their axioms hold.
    Historical and dynamicalCausal relations, inherited constraints, and the law of evolution.Maps preserving historical data and intertwining the specified dynamics.

    In this interpretation, preserved properties help delimit what counts as identity at a given level. The choice of level arises from the object and the problem. Comparing concrete phenomena requires establishing which essential aspects the model captures and which remain outside its representation. An isolated invariant may be informative without completely classifying a structure: equal cardinality does not determine equal topology or an identical operation.

    5.2. Preserving more structure restricts transformations

    On a fixed smooth manifold M, equipped with a Riemannian metric g, the following inclusions hold:

    Isom(M,g) ⊆ Diff(M) ⊆ Homeo(M) ⊆ Bij(M).The underlying object and its structures remain specified.

    A Riemannian isometry is a diffeomorphism preserving the metric tensor; every diffeomorphism is a homeomorphism; and every homeomorphism is a bijection. If one begins with a bijection preserving Riemannian distance, its smoothness is a regularity result, not a consequence obtained simply by writing derivatives of a function not yet known to be differentiable.

    The inclusions can be strict, but this must be checked for the object under consideration. Adding structure does not automatically generate a new space through an arrow: a bijection does not produce a topology, nor does a homeomorphism by itself add a differentiable structure. The definitions of manifolds and smooth maps rely on explicit data and compatibilities (Meinrenken, 2001, § 1).

    Three transformations of the real line

    Dilation: f(x)=2x is a diffeomorphism of ℝ with inverse x/2, but it doubles Euclidean distances. It also preserves addition, so it is an automorphism of the additive group.

    Cubic map: h(x)=x3 is a homeomorphism of ℝ. Its inverse, the cube root, is not differentiable at zero; hence h is not a diffeomorphism. It does not preserve addition either.

    Swapping points: the bijection that swaps 0 and 1 and fixes every other real number is discontinuous. It preserves cardinality, but not the usual topology.

    These examples show that preservation depends on the relations considered. A metric variation can leave topological identity intact; modifying the composition law can change algebraic identity on the same underlying set. Qualitative transformation must be located in the determination that actually changes.

    5.3. Operational essence and history

    The automorphisms of a structure form a group under composition. This group organizes reversible transformations preserving the specified data and provides a formalization of operational essence. Adding a smooth structure and compatibility with multiplication and inversion may produce a Lie group. The Lie-group condition must be established; an abstract automorphism group does not possess it automatically (Meinrenken, 2002, § 10).

    History introduces another question: how were the relations that now admit those symmetries formed? In a dynamical model, a transformation h is compatible with the evolution Φt when h ∘ Φt = Φt ∘ h. When two different dynamics are compared, the corresponding equation is a conjugacy or an intertwining relation between their evolutions. Preserving the instantaneous metric is insufficient to preserve an additional law of motion.

    Processes involving memory, accessibility constraints, or information loss may require an enlarged state space or the use of semigroups, categories, or groupoids. That choice is justified by examining composition, identity, and invertibility. A layered formulation allows preservation and transformation to be investigated without assuming that every historical evolution is a symmetry group.

    VI · Algebra of sets

    The power set and its operations

    6.1. From elements to subsets

    The power set of X is the collection of all its subsets, written ℘(X) or 2X. For a finite set with n elements, it contains 2n subsets: each element can independently be included or excluded.

    X = {a,b},℘(X) = {∅, {a}, {b}, {a,b}},   |℘(X)| = 22 = 4.

    The empty set is a subset of every set. This does not imply that it is an element of every set: ∅ ⊆ X and ∅ ∈ X are different statements. By contrast, ∅ ∈ ℘(X) always holds. This distinction between membership and inclusion is indispensable when studying systems whose elements are themselves sets.

    6.2. Symmetric difference as addition

    The symmetric difference consists of the elements belonging to one of two sets but not to both:

    A △ B = (A ∖ B) ∪ (B ∖ A).

    On ℘(X), symmetric difference is associative and commutative, has identity ∅, and makes every set its own inverse: A △ A = ∅. Thus (℘(X),△) is an abelian group. Adding intersection as multiplication gives a commutative ring with identity X.

    A ∩ (B △ C) = (A ∩ B) △ (A ∩ C),A ∩ X = A,   A ∩ A = A.The ring is Boolean: every element is multiplicatively idempotent.

    Union is recovered through A ∪ B = (A △ B) △ (A ∩ B), and difference through A ∖ B = A △ (A ∩ B). These identities explain the connection between set operations and ring structure. Union does not play the role of addition with inverses in this ring.

    6.3. Rings, semirings, and algebras of sets

    A ring of sets is a nonempty family closed under finite union and difference. Equivalently, it is closed under symmetric difference and intersection. It may fail to contain the ambient set X: the family of all finite subsets of an infinite set is an example. As a Boolean ring, it may have no identity of its own.

    An algebra of sets on X contains X and is closed under complements relative to X and finite unions. Closure under intersection follows from De Morgan’s laws. Its identity is the greatest element of the family under inclusion, since it contains every member.

    A semiring of sets contains ∅, is closed under intersections, and allows the difference of two members to be written as a finite disjoint union of members of the family. Bounded half-open intervals [a,b), together with the empty set, provide an example on ℝ. This decomposition permits measures to be constructed from elementary pieces, as studied by Kolmogórov and Fomin (1978, chap. I, § 5).

    VII · Order relations

    Partial order, extremal elements, and generation

    7.1. Ordering does not always make everything comparable

    A partial order ≤ is a reflexive, antisymmetric, and transitive relation. Reflexivity means a ≤ a; antisymmetry means that a ≤ b and b ≤ a imply a=b; transitivity means that a ≤ b ≤ c implies a ≤ c. Set inclusion is a partial order.

    In a total order, any two elements are comparable. A well-order additionally requires every nonempty subset to have a least element. The real numbers with their usual order are totally ordered but not well-ordered: the interval (0,1) has no least element. For finite sets, every total order is a well-order.

    Extremal elements in a partially ordered set P
    ConceptCondition
    Greatest element ma ≤ m for every a ∈ P.
    Maximal element mIf m ≤ a, then a = m.
    Least element mm ≤ a for every a ∈ P.
    Minimal element mIf a ≤ m, then a = m.

    Every greatest element is maximal; the converse can fail. The family {{a},{b}}, ordered by inclusion with a≠b, has two maximal elements and no greatest element. The family {∅,{a},{b},{a,b}} does have a greatest element: {a,b}. Greatest and least elements, when they exist, are unique. In a total order, a maximal element is greatest, but there need not be any.

    7.2. The smallest system containing specified data

    This precision is useful when constructing a generated structure. Fix an ambient set X and a family 𝒞 ⊆ ℘(X). The σ-algebra generated by 𝒞 is the intersection of all σ-algebras on X containing it:

    σX(𝒞) = ⋂ {Σ : Σ is a σ-algebra on X and 𝒞 ⊆ Σ}.

    The family being intersected is nonempty, because ℘(X) is a σ-algebra containing 𝒞. Its intersection preserves the axioms. The result is the least σ-algebra under inclusion containing the generators, not merely a minimal element among the candidates (Viaclovsky, 2003, Proposition 0.3).

    Older expositions may distinguish a family with no points outside the union of its generators from the smallest closed family containing them. The first issue fixes the ambient set; the second fixes the collection of admissible subsets. This distinction avoids importing concepts of “minimal algebra” from other fields as though they were equivalent to a generated σ-algebra.

    VIII · Events and topology

    σ-algebras, Borel sets, and probability

    8.1. The three axioms

    A σ-algebra Σ on X is a collection of subsets with the following properties:

    X ∈ Σ;A ∈ Σ ⇒ X ∖ A ∈ Σ;A1,A2,… ∈ Σ ⇒ ⋃n=1∞ An ∈ Σ.

    These axioms imply membership of the empty set and closure under countable intersections and differences. “Countable” here refers to the sequence of sets being operated on. It does not require each set to have countably many points, nor does it require the σ-algebra itself to be a countable collection.

    De Morgan’s identities provide the connection among complements, unions, and intersections:

    X ∖ (⋃n An) = ⋂n (X ∖ An),X ∖ (⋂n An) = ⋃n (X ∖ An).

    A σ-ring is a ring of sets closed under countable unions; a δ-ring is closed under countable intersections. When the ring contains the ambient set and therefore relative complements, these two closure properties are connected by those identities. Duality transforms one operation into another through complementation: it does not identify union with intersection.

    8.2. What makes a σ-algebra a Borel σ-algebra

    If (X,τ) is a topological space, its Borel σ-algebra is generated by its open sets:

    ℬ(X) = σX(τ).

    It can also be generated by the closed sets. The definition depends on the chosen topology and applies to general spaces, not only to the real line. On ℝ with its usual topology, it contains intervals and many other sets of points. A Borel set can be uncountable: [0,1] is an example.

    Some historical texts use “B-algebra” or “Borel algebra” in a broader sense close to an abstract σ-algebra. This edition uses the current distinction: Σ denotes a σ-algebra; ℬ(X) denotes the σ-algebra generated by a topology. This preserves the historical reading of Kolmogórov and Fomin without attributing an unspecified topology to every σ-algebra.

    8.3. Sample space and probability

    A probability space is a triple (Ω,Σ,ℙ): Ω contains the possible outcomes, Σ contains the measurable events, and ℙ assigns them probabilities σ-additively, with ℙ(Ω)=1. The sample space may describe physical outcomes, sequences, or system configurations; it need not be a Euclidean region or a totally ordered set (Kolmogorov, 1956).

    An observed sample is a realization or a collection of observations from an experiment. It should be distinguished from the space of all possible outcomes. Choosing Σ is part of modeling; inference may estimate distributions or parameters, but the algebra of events is not automatically obtained by “estimating” the power set of the data.

    Uncountable spaces do admit measures and probabilities. The Lebesgue measure of an interval and continuous distributions are central examples. The problem of nonmeasurable sets concerns compatibility between the domain of definition and the properties required of the measure. Measuring length or probability does not require enumerating points one by one.

    Finite example · A fair die

    Take Ω={1,2,3,4,5,6}, Σ=℘(Ω), and ℙ(A)=|A|/6. For the disjoint events A={2,4,6} and B={1,3}, we have ℙ(A∪B)=5/6=3/6+2/6. The collection Σ has 64 events, including the empty set.

    IX · Philosophical categories

    Quantity, quantum, degree, and measure

    9.1. Singular, particular, and universal

    A singular object possesses relations and properties that may be shared with other objects. The particular allows determinations specific to a class or configuration to be studied; the universal expresses general connections realized in concrete cases. From the standpoint of dialectical materialism, these categories guide investigation of how lawfulness manifests itself under determinate conditions. Their articulation must be reconstructed in the object and in cognitive practice.

    A concrete operation such as 2+3=5, the additive group of integers, and general group theory provide different levels of abstraction. Their connection is established through definitions and results: one verifies that the integers satisfy the axioms and deduces properties applicable to their operations. This relation illustrates an ascent toward general determinations and a return to particular cases, with specific procedures of justification.

    In empirical science, this movement includes observation, conceptualization, and testing. A statistical regularity may suggest a relation; its causal explanation requires additional information about the process. The unity of the singular, particular, and universal acquires content by showing how a law is realized, under what conditions, and with what variations.

    9.2. Pure quantity and quantitative determination

    In Hegel’s logic, quantity, quantum, and degree are developed within an investigation of the determinations of being. Pure quantity considers quantitative determination in its abstraction; quantum is determinate quantity; degree expresses an intensive determination. Measure articulates quantity and quality. These categories are moments of a philosophical exposition whose meaning must be explained before they are connected with mathematical constructions (Hegel, 1830/1975, §§ 99–111).

    We may call the aspect of quantity considered independently of a determinate value a general quantitative structure, and a concrete quantum a particular quantitative determination. Interpreting degree as intensive determination allows us to investigate how a magnitude is expressed in a singular state. This terminology is an interpretive elaboration: a degree remains a form of quantum, so the terms do not constitute three mutually exclusive classes.

    The philosophical relation between continuity and discreteness raises questions about the conditions of unity and differentiation within a multiplicity. In mathematics, “discrete” and “continuous” require specification: a discrete topology, an integer-valued variable, a continuous function, and an atomless measure denote different properties. Conceptual reconstruction becomes more precise when these properties are identified in each example.

    9.3. Extension, intensity, and relations

    In appropriate physical contexts, extensive quantities are related to the composition of parts: mass and volume can be added under specified assumptions. Intensive quantities such as temperature or pressure characterize a state and are not added in the same way when systems are combined. The relation between the two depends on the constitutive laws and regime under consideration. These physical categories provide examples for philosophical discussion without exhausting its meaning.

    In statistics, a correlation coefficient, a variance inflation factor, and an information criterion serve different purposes. The first summarizes standardized linear association; the VIF quantifies variance inflation under the corresponding regression model; AIC and BIC compare models using specific criteria. Calling them “intensities” is informative only if the quantified relation and the interpretation of its scale are specified.

    A numerical value acquires meaning within a structure of relations. An angle requires directions and a geometry; a distance requires a metric; a probability requires events and a measure. This relational character develops the thesis that the quantitative is qualitatively determined: measuring presupposes what is taken as an object, what is compared, and by what rule.

    9.4. Philosophical measure and transformation

    The philosophical category of measure investigates the unity of qualitative and quantitative determination: a system admits variations compatible with an organization, and certain modifications can transform that organization. A mathematical formulation must specify variables, parameters, admissible states, and a criterion of change. A threshold may arise from a bifurcation, a material constraint, or a phase transition; each mechanism requires its own analysis.

    A layered account of essence helps locate transformation. The cardinality of the components may remain constant while their organization of connections changes; a topology may persist while a metric or the stability of a dynamics changes. The qualitative leap is investigated by attending to the layer and regime that change, together with their repercussions for the remaining determinations.

    The history of mathematical investigation is also part of this reflection. The abstraction of magnitudes and operations develops through practices of calculation, proof, and modeling. Formalist, intuitionist, and constructivist traditions debate, among other issues, which procedures justify existence and construction. Assessing these positions requires their arguments and contexts; a philosophical preference does not follow automatically from a formula or a mathematician’s nationality.

    X · Approximation and regime change

    Limits and qualitative transformation

    10.1. The ε–δ definition, step by step

    Let f: D ⊆ ℝ → ℝ, and let a be an accumulation point of D. To assert that f(x) tends to L as x tends to a means:

    ∀ ε > 0, ∃ δ > 0, ∀ x ∈ D:0 < |x−a| < δ ⇒ |f(x)−L| < ε.

    First fix any positive tolerance ε for the function’s value. A neighborhood of radius δ must then be found that guarantees this tolerance for every admissible point distinct from a. The choice of δ may depend on ε. The value f(a), when it exists, does not by itself determine the limit (Massachusetts Institute of Technology, n.d.).

    Absolute value expresses distance on ℝ. For example, |3|=3. Bounding a difference requires an additional inequality. The equivalence |u|<ε ⇔ −ε<u<ε turns the tolerance condition into an interval, but does not by itself establish that the condition holds.

    Proof · A linear limit

    Let f(x)=2x+1. We want to prove that its limit at a is L=2a+1. Given ε>0, choose δ=ε/2. If 0<|x−a|<δ, then:

    |f(x)−L| = |2x+1−(2a+1)|= 2|x−a| < 2δ = ε.

    This explicit choice of δ verifies every case required by the definition.

    10.2. One-sided limits, sequences, and the squeeze theorem

    When the domain permits approach from both sides, the two-sided limit exists if both one-sided limits exist and agree. The squeeze theorem is a separate result: if two functions bounding a third converge to the same value, the intermediate function also converges to it. That theorem should be distinguished from merely writing a tolerance interval.

    On ℝ, the sequential criterion states that the limit L exists exactly when every sequence xn ∈ D ∖ {a} converging to a satisfies f(xn) → L. This result connects approximation through discrete indices with a function’s local behavior. It does not imply that all functions are continuous: continuity at a additionally requires f(a)=L.

    The Hegelian notion of limit and the ε–δ definition can be brought into dialogue through questions of determination and variation. The philosophical category does not replace the order of quantifiers in the analytical definition. Conversely, proving a particular limit does not by itself establish a general theory of the relation between quantity and quality.

    10.3. An explicit example of qualitative change

    Consider the scalar dynamical system with real parameter r:

    dx/dt = Fr(x) = rx − x3.

    Equilibrium states satisfy x(r−x2)=0. For r<0, zero is the only real equilibrium. For r>0, two more appear: ±√r. Their local stability is determined from Fr′(x)=r−3x2.

    Calculating a supercritical pitchfork bifurcation
    ParameterEquilibriaLocal stability
    r < 0x = 0Fr′(0)=r<0: stable and attracting.
    r = 0x = 0Nonhyperbolic; dx/dt=−x3 still attracts toward zero.
    r > 0x = 0; x = ±√rZero is unstable; at ±√r, Fr′=−2r<0: stable and attracting.

    The state set remains ℝ, and its usual topology stays fixed. The number of equilibria and their stability relations change. Here qualitative transformation is located in the dynamical layer. The equation makes it possible to specify a threshold and verify the mechanism of change; applying it to a natural or social phenomenon requires justification of the equation and the meaning of its variables.

    Other variables and laws may be involved in physical transitions. The correlation function and correlation length are distinct objects: the latter characterizes a spatial decay scale of the former. At a critical point, that scale can diverge in the thermodynamic limit. Renormalization studies how a description changes with scale; connecting it philosophically to measure requires specifying what is rescaled and which behavior remains invariant.

    XI · Measure theory

    Measure, σ-additivity, and subadditivity

    11.1. Three structures that must be specified

    A metric space (X,d) assigns distances to pairs of points. A measurable space (X,Σ) selects a σ-algebra of subsets. A measure space (X,Σ,μ) adds a function measuring those sets. A metric can generate a topology and, through it, a Borel σ-algebra; obtaining a measure still requires an appropriate function to be specified.

    A positive measure takes values in [0,∞], satisfies μ(∅)=0, and is σ-additive. Allowing the value infinity matters: the total length of ℝ is infinite. Length, area, volume, and probability are different realizations of the concept; measuring a set is not equivalent to calculating a distance between two points.

    11.2. The σ-additivity condition

    For every sequence of pairwise disjoint measurable sets, the requirement is:

    Ai ∩ Aj = ∅   if i ≠ j,μ(⋃n=1∞ An) = ∑n=1∞ μ(An).

    The argument of μ is a set; the operation in the domain is disjoint union. This property differs from additivity of a function on vectors, T(u+v)=T(u)+T(v). The two can be connected through explicit representations. For example, indicator functions satisfy 1A∪B=1A+1B when A and B are disjoint, and μ(A)=∫1A dμ.

    This constructs a connection between measure and functions. Linearity of an integral and σ-additivity of a measure concern related objects; passing to infinite unions requires convergence results. On a finite set, a sequence of disjoint subsets has only finitely many nonempty members, so a finitely additive set function that vanishes on the empty set is already σ-additive.

    11.3. Why a positive measure is subadditive

    A positive measure satisfies countable subadditivity for measurable sets, even when they overlap:

    μ(⋃n=1∞ An) ≤ ∑n=1∞ μ(An).

    To prove this, construct B1=A1 and Bn=An ∖ (A1∪⋯∪An−1). The Bn are disjoint, have the same union as the An, and satisfy Bn⊆An. The σ-additivity and monotonicity of a positive measure give μ(⋃An)=∑μ(Bn)≤∑μ(An). If also S⊆⋃An, monotonicity yields μ(S)≤∑μ(An).

    Example · Overlapping intervals

    For length measure, A=[0,2] and B=[1,3] satisfy μ(A)=μ(B)=2. Their union has length 3:

    μ(A∪B)=3 < 4=μ(A)+μ(B).

    The inequality arises because the shared segment is counted twice in the sum. The measure remains σ-additive on disjoint families.

    An outer measure is a function on all subsets of X that vanishes on the empty set, is monotone, and is countably subadditive. Measure theory studies how to select measurable subsets on which σ-additivity is recovered. “Subadditive” describes a property; by itself, it does not identify a positive measure defined on a σ-algebra.

    11.4. Signed measures

    When contributions can be negative, signed measures enter the picture. A finite signed measure is a real-valued set function that is σ-additive and vanishes on the empty set. Its total variation controls the positive and negative contributions (Varadhan, n.d., Part III).

    Positivity is decisive for monotonicity and for the subadditivity inequality above. If ν({a})=−1 and A=B={a}, then ν(A∪B)=−1, whereas ν(A)+ν(B)=−2. The inequality ν(A∪B)≤ν(A)+ν(B) fails. The following genetic application will use precisely this distinction.

    XII · Application and proof

    Genetics: constructing the σ-additive connection

    12.1. From phenotypic value to its components

    Quantitative genetics studies variation in measurable traits and its relations to genetic and environmental differences. An elementary decomposition is P=G+E, where P is phenotypic value, G is the genotypic value defined by the model, and E is environmental deviation. If G is defined as the average phenotype for a genotype within a specified population and environmental distribution, E is the deviation from that average.

    Centering E so that its expectation is zero fixes a statistical reference point. It neither eliminates environmental effects nor implies that the environment has no influence on gene expression, development, or evolution. If the distribution of environments changes, the mean value associated with each genotype can change; genotype–environment interactions require their own modeling.

    For variances, Var(P)=Var(G)+Var(E)+2Cov(G,E). The sum of the two variances is obtained only under a condition making the covariance vanish. This distinction shows that writing an additive decomposition of values does not automatically authorize the addition of all measures of dispersion.

    12.2. One locus, two alleles, and dominance

    A locus is a position in the genome; an allele is a variant at that locus. In a diploid organism, a homozygote has two copies of the same allele at the locus considered, whereas a heterozygote has different alleles. The distinction concerns allelic variants, not a difference in chromosome number. With two alleles A1 and A2, we can assign the following values:

    Parameterization of a diploid biallelic locus
    GenotypeCopies of A1: nGenotypic value G
    A2A20−a
    A1A21d
    A1A12+a

    The origin of this scale is the midpoint between the two homozygotes. If A1 is chosen as the allele increasing the value, we take a > 0. The ratio d/a expresses the degree of dominance when a ≠ 0. The parameter d measures the heterozygote’s deviation from that midpoint. If d=0, the three values lie on a straight line as a function of allele dosage. If d=+a or d=−a, the heterozygote coincides with one of the homozygotes. Values outside the interval between them express a deviation beyond their values.

    In the absence of dominance, the formula is G(n)=−a+an. This is an affine relation in n; once the baseline −a is separated, the contribution an is linear. This parameterization connects genetic effects with quantitative models (Falconer & Mackay, 1996, chap. 7; Huang & Mackay, 2016).

    0 copies−2A2A2
    1 copy0A1A2
    2 copies+2A1A1
    Figure 1. Example with a = 2 and d = 0: each additional copy of A1 increases the value by 2 units. The heterozygote is the midpoint.

    12.3. A set function associated with the additive model

    Consider a finite set of loci I={1,…,m} and a fixed genotype g. For each locus, ni(g)∈{0,1,2} counts copies of the coded allele, and βi is its per-copy effect under the model. The additive value is written:

    Gad(g) = b + ∑i=1m βi ni(g).

    After separating the baseline b, define a function whose argument is indeed a set of loci:

    νg: ℘(I) → ℝ,νg(S) = ∑i∈S βi ni(g).The genotype remains fixed; S selects the contributions to be aggregated.

    The distinction between domains is substantive. Gad assigns values to genotypes; νg assigns contributions to subsets of loci for a given genotype. The functions are related by Gad(g)=b+νg(I). The baseline is kept outside ν, since a measure must vanish on the empty set.

    Proposition · σ-additivity on the finite set of loci

    For each fixed genotype g, the function νg is a finite signed measure on (I,℘(I)).

    Proof. The sum over the empty set is zero. If S1,S2,… are disjoint subsets of I, each locus belongs to at most one of them. Therefore:

    νg(⋃k=1∞ Sk)= ∑i∈⋃kSk βi ni(g)= ∑k=1∞ ∑i∈Sk βi ni(g)= ∑k=1∞ νg(Sk).

    Since I is finite, only finitely many Sk can be nonempty. The equality does not require an uncontrolled interchange of infinite series. Total variation is |νg|(I)=∑i|βi ni(g)|<∞. This proves the proposition. ∎

    If all contributions βini(g) are nonnegative, νg is a positive measure and satisfies the corresponding subadditivity. When contributions have both signs, it retains σ-additivity on disjoint sets and must be treated as a signed measure.

    Worked example · Three loci

    Take β=(2,−1,3) and n(g)=(2,1,0). The contributions are (4,−1,0). For the disjoint sets S={1} and T={2,3}:

    νg(S)=4,   νg(T)=−1,νg(S∪T)=3=4+(−1).

    The total value is Gad(g)=b+3, and the measure’s total variation is 4+1+0=5. A negative effect decreases the trait value relative to the chosen reference; it does not represent a negative probability.

    12.4. What changes when infinitely many loci are idealized

    If I=ℕ, a sufficient condition for defining a finite signed measure through the same construction is:

    ∑i=1∞ |βi ni(g)| < ∞.

    Absolute convergence allows summation over any subset and regrouping into disjoint families while preserving the result. If the weights are nonnegative, a positive measure with values in [0,∞] can be defined even when its total mass is infinite. For weights of both signs without convergence control, the formula does not guarantee a well-defined measure on the entire power set.

    Finiteness of the underlying set and convergence of series are explicit mathematical assumptions. In a concrete biological model, the meaning of a locus, the coding adopted, and the estimation or derivation of effects must also be justified. The preceding construction establishes the formal connection that permits us to speak of σ-additive functions associated with an additive genetic model.

    12.5. Dominance, epistasis, and the aggregation domain

    Specifying the domain reveals a further point. A per-locus dominance contribution such as di 1{ni(g)=1} can also be aggregated locus by locus. If, for fixed g, it is incorporated into a weight ci(g) and we define νg(S)=∑i∈Sci(g), the function remains σ-additive on a finite set. Additivity over subsets of loci and linearity with respect to allele dosage therefore answer different questions.

    An interaction between loci can be examined by specifying another function: the value of a subset that retains only terms whose loci are present. For two loci, define:

    Wg(S) = ∑i∈S βini(g)+ γ n1(g)n2(g) 1{{1,2} ⊆ S}.

    The final indicator equals one if S contains both loci, and zero otherwise. Then:

    Wg({1,2}) − Wg({1}) − Wg({2})= γ n1(g)n2(g).

    When this term is nonzero, Wg is not additive over the original loci. For example, if n1=n2=1, β1=2, β2=3, and γ=4, the joint value is 9 and the sum of individual values is 5. If γ is negative, the joint contribution may be smaller than the sum; an inequality in one case does not by itself prove subadditivity for every family.

    The atoms can be redefined to include interactions, or interactions can be distributed through an attribution rule. This changes the domain or the interpretation of the weights. The absence of causal interactions between loci does not follow from an additive representation obtained after such redistribution.

    12.6. Additive variance and causal architecture

    Additive genetic variance describes a statistical component defined relative to a population and its coding. A large component does not demonstrate that all underlying mechanisms are additive. Huang and Mackay show that different parameterizations can capture a substantial share of variation even when they differ from the gene actions that generated the data (2016).

    The contribution measure νg should likewise be distinguished from a probability distribution over genotypes. A probability on genotype space allows G to be treated as a random variable and its expectation to be calculated when it is integrable. That probability is σ-additive whether G contains additive effects or interactions; the functional form of G must be examined separately.

    The σ-additive proof and causal investigation are thus connected precisely. The former describes how contributions aggregate under a fixed model and domain. The latter investigates whether the material system’s effects, dependencies, and interactions correspond to that representation. For a dialectical interpretation, the relation between part and whole acquires mathematical content here: one can identify what aggregation preserves and which terms express joint dependence.

    XIII · Synthesis

    Structure, history, and knowledge

    Algebraic structures allow operations and compatibilities to be studied independently of the particular nature of their elements. This abstraction makes it possible to transport results between isomorphic representations. Investigation of the concrete object must specify which relations have been preserved, how they were formed, and under what conditions they are transformed.

    Essence as an articulation of layers offers a way to organize that task. Sets, operations, topology, differentiability, metric, and dynamics pose different questions about a system. Identity may persist in some determinations and change in others. These relations are investigated by specifying structures and invariants and examining their material articulation.

    The examples developed establish three results. The exponential transports a group structure exactly. The bifurcation changes the organization of equilibria on a fixed topological space. The genetic contribution function, once the genotype is fixed and the baseline separated, is a σ-additive signed measure on subsets of a finite set of loci. In each case, the conclusion follows from identifiable assumptions.

    A dialectical-materialist interpretation gains explanatory strength by reconstructing the mediations between those formal properties and the processes they model. Mathematics proves consequences of a model; empirical investigation establishes its adequacy to the object; historical reconstruction explains its emergence and transformations. The unity of these tasks requires their specific criteria of justification to be maintained.

    Essence is investigated through the articulation of relations constituting a system, the transformations preserving them, and the processes modifying its organization.

    Synthetic proposition of this edition

    In this sense, scientific knowledge of a structure involves studying both its invariants and the conditions of its modification. Analysis of the parts leads to the whole through verifiable relations; analysis of the whole returns to the parts to understand their function and dependence. Formalization contributes to this movement by making explicit what is assumed, what is preserved, what changes, and what remains to be investigated.

    Sources · Bibliography

    References

    The references distinguish original works, the editions consulted, and the unpublished manuscript used to expand the discussion of structural layers. The mathematical expositions and calculations in this edition are presented as the author’s own developments; the references identify their conceptual frameworks and sources used for comparison.

    Falconer, D. S., & Mackay, T. F. C. (1996). Introduction to quantitative genetics (4th ed.). Longman. Publisher’s record.

    Frolov, I. T. (Ed.). (1984). Diccionario de filosofía [Dictionary of philosophy] (O. Razinkov, Trans.). Progreso. Edition and bibliographic information; entries “Structure” and “Isomorphism and homomorphism”.

    Gómez Julián, J. M. (2026). Geometría, historia y legalidad: Fundamentos dialéctico-materialistas de los espacios con estructura métrica [Geometry, history, and lawfulness: Dialectical-materialist foundations of spaces with metric structure] [Unpublished manuscript, version supplied by the author].

    Hegel, G. W. F. (1975). Hegel’s logic (W. Wallace, Trans.). Clarendon Press. (Text of the 1830 Encyclopaedia; translation originally published in 1873). Digital edition and provenance; quantity, §§ 99–106; being and measure.

    Huang, W., & Mackay, T. F. C. (2016). The genetic architecture of quantitative traits cannot be inferred from variance component analysis. PLOS Genetics, 12(11), e1006421. https://doi.org/10.1371/journal.pgen.1006421

    Kolmogorov, A. N. (1956). Foundations of the theory of probability (N. Morrison, Trans.; 2nd English ed.). Chelsea Publishing Company. (Original work published 1933).

    Kolmogórov, A. N., & Fomin, S. V. (1978). Elementos de la teoría de funciones y del análisis funcional [Elements of the theory of functions and functional analysis] (C. Vega, Trans.; 3rd ed.). Mir.

    Marx, K. (1973). Grundrisse: Foundations of the critique of political economy (Rough draft) (M. Nicolaus, Trans.). Penguin Books and New Left Review. (Manuscripts of 1857–1858). Introduction and the method of political economy.

    Massachusetts Institute of Technology. (n.d.). Formal definition of limit. Open Learning Library, Calculus 1A: Differentiation. Course resource.

    Meinrenken, E. (2001). Differentiable manifolds [Lecture notes]. University of Toronto. Full text.

    Meinrenken, E. (2002). Riemannian geometry [Lecture notes]. University of Toronto. Full text.

    Milne, J. S. (2022). Fields and Galois theory (Version 5.10) [Lecture notes]. Full text.

    Nabi, I. (2022). Estructuras algebraicas: Un análisis desde la filosofía marxista de la ciencia [Algebraic structures: An analysis from the Marxist philosophy of science] [Original manuscript]. Marxist Philosophy of Science. Original PDF. Isadore Nabi is the pseudonym under which this work was published.

    Rosental, M. M., & Iudin, P. F. (Eds.). (1965). Diccionario filosófico [Philosophical dictionary]. Pueblos Unidos. Entries “Structure” and “Isomorphism”, reproduced in Filosofía en español.

    Timmermans, B. (2012). Prehistory of the concept of mathematical structure: Isomorphism between group theory, crystallography and philosophy. The Mathematical Intelligencer, 34(3), 41–54. https://doi.org/10.1007/s00283-012-9290-3. Manuscript in the institutional repository.

    Varadhan, S. R. S. (n.d.). [Real analysis notes, Part III: Signed measures] [Lecture notes]. Courant Institute of Mathematical Sciences, New York University. Full text.

    Viaclovsky, J. (2003). Measure and integration: Lecture 1 [Lecture notes]. Massachusetts Institute of Technology. Full text.

    Historical document · 52 pages

    The PDF preserves the original 2022 formulation. This edition incorporates conceptual and mathematical revision, proofs, and expansions.

    Read the original manuscript ↗

    Marxist Philosophy of Science
    Mathematics · Philosophy · History

  • ON TENSORS: THEIR CONCEPTUAL INTERPRETATION

    ON TENSORS: THEIR CONCEPTUAL INTERPRETATION

    Marxist Philosophy of Science
    Mathematics · Philosophy of science

    On tensors · Part I

    Their Conceptual Interpretation

    Objects, components, and transformations: from multilinear algebra to geometry, mechanics, and data.

    Original publication ·
    Revised and expanded ·
    31 min approximate reading time · Includes R examples

    1. The object and its representations

    The same displacement can be described using different coordinates without changing the displacement itself. Likewise, the stress state of a material can be expressed by different matrices when the reference axes change. Understanding what remains the same and what transforms makes it possible to introduce tensors without reducing them to collections of numbers or attributing properties to them that their definition does not entail.

    The central idea is this: a tensor is a multilinear object whose identity is independent of the basis used to represent it. Its components depend on the basis; their transformation is determined by the kind of object involved. The array of numbers and the object represented therefore belong to related levels of explanation.

    Basis independence does not mean that all quantities are constant, that all observers obtain the same measurements, or that every transformation is a physical symmetry. It means that admissible representations are related consistently. The spaces, bases, and transformation must be specified, and a change of description must be distinguished from an actual modification of the system.

    The discussion begins with vectors and covectors, introduces the tensor product and transformation laws, and then examines the metric, curvilinear coordinates, the stress tensor, and data representation in R. It concludes with a dialectical materialist interpretation, including its mediations and limits. The mathematical formulation draws on the university lecture notes of Tong (n.d.) and Reall (n.d.).

    2. Vectors, bases, and components

    A basis of a vector space V of dimension n is a family of n linearly independent vectors that spans the entire space. Once a basis is chosen, each vector has a unique expression:

    v = ∑i=1n viei = viei.

    The numbers vi are its components; the vectors ei form the basis. The linear combination reconstructs the vector, not its magnitude. Obtaining a length requires additional structure, such as an inner product.

    A basis need not be orthogonal or consist of vectors of unit length. In a Euclidean space, an orthonormal basis satisfies ei · ej = δij: its vectors are unit vectors and mutually orthogonal. The standard basis of ℝn has this property with respect to the usual Euclidean inner product; the property must not be transferred automatically to an arbitrary metric.

    In an orthonormal basis, a component is obtained by taking the inner product with the corresponding basis vector. In an oblique basis, this procedure does not generally recover the expansion coefficients. The appropriate tool is the dual basis, introduced below.

    The same vector in an oblique basis

    In ℝ², take the standard basis e1 = (1, 0), e2 = (0, 1), and the new basis e′1 = (1, 0), e′2 = (1, 1). The second basis is oblique, and its second vector has length √2. The matrix and its inverse are:

    P = 1101;   P−1 = 1−101.

    Because the new basis matrix is the old one multiplied by P, the component columns satisfy v = Pv′. For the vector whose original components are (3, 2):

    v′ = P−1v = 1−10132 = 12.

    Reconstruction confirms the result: v = 3e1 + 2e2 = e′1 + 2e′2 = (3, 2). The coefficients and the basis changed; the vector remained identical.

    The same vector v=(3,2) in a standard basis and an oblique basis e prime 1=(1,0), e prime 2=(1,1).
    Figure 1. The components (3, 2) and (1, 2) describe the same vector. Construction lines show the two decompositions. Original illustration for this edition.

    3. Covectors and the dual basis

    A covector is a linear map α: V → ℝ. It takes a vector and returns a scalar. The set of all covectors forms the dual space V*. The dual basis {ε1, …, εn} associated with a basis {e1, …, en} is defined by:

    εi(ej) = δij;   vi = εi(v).

    The delta equals one when the indices coincide and zero otherwise. Each covector of the dual basis extracts one coefficient. For the preceding oblique basis, ε′1(x, y) = x − y and ε′2(x, y) = y. Applying them to (3, 2) gives precisely 1 and 2.

    A covector is written α = αiεi, and its action on a vector is α(v) = αivi. If we also store the covector components as a column a, then α(v) = aTv. The superscript T denotes transposition.

    Why the transformations differ

    With our change-of-basis convention, vector components transform as v′ = P−1v, whereas covector components transform as a′ = PTa. Consequently:

    (a′)Tv′ = aTP P−1v = aTv.

    For α(x, y) = 2x − y, we have a = (2, −1) and a′ = (2, 1). Evaluation gives 2·3 − 1·2 = 4 in the old basis and 2·1 + 1·2 = 4 in the new one. Invariance belongs to the complete evaluation, not to each component separately.

    This difference underlies the terms contravariant and covariant. They are not two species of arrows identifiable by their orientation in a drawing: they express different positions within the tensor structure and the corresponding transformation rules. A metric provides a relation between vectors and covectors, but that relation must be specified (Reall, n.d.).

    4. The tensor product and multilinearity

    A map with two arguments is bilinear when it is linear in each argument separately. For vector spaces V and W, the tensor product V ⊗ W is a vector space equipped with a bilinear map sending (v, w) to v ⊗ w. It is characterized by a universal property: every bilinear map from V × W to another vector space factors uniquely through a linear map defined on V ⊗ W.

    The universal property explains its purpose: turning a bilinear problem into a linear one on a suitable space. It requires neither curvilinear coordinates, curvature, nor a manifold. Its defining relations include:

    (u + v) ⊗ w = u ⊗ w + v ⊗ w;
    v ⊗ (w + z) = v ⊗ w + v ⊗ z;
    (λv) ⊗ w = λ(v ⊗ w) = v ⊗ (λw).

    The map is linear in each input but not linear as a joint map of the pair: scaling both arguments simultaneously by λ multiplies the result by λ².

    Cartesian product, direct sum, and tensor product

    Different constructions on spaces of dimensions m and n
    ConstructionElements and structureDimension
    V × WPairs (v, w), with vector-space structure defined componentwise.m + n
    V ⊕ WExternal direct sum; for two factors, naturally the same vector space as the preceding product.m + n
    V ⊗ WLinear combinations of simple products, subject to bilinearity relations.m n

    If {ei} and {fj} are bases, the mn products ei ⊗ fj form a basis of the tensor product. This is why the dimensions multiply. It does not arise from a structure “behaving like addition” and mysteriously producing multiplication.

    A simple product and a tensor that is not simple

    Let u = (1, 2) and w = (3, 4). The coefficients of u ⊗ w are uiwj:

    [u ⊗ w] = 3468.

    This is a simple tensor. However, the tensor e1 ⊗ e1 + e2 ⊗ e2 cannot be written as a single u ⊗ w: its coefficient matrix is the 2 × 2 identity, with determinant one, whereas every matrix obtained as the outer product of two vectors has matrix rank at most one. General tensors are finite sums of simple products; not every tensor is a single product (Tong, n.d.).

    Products of u=(1,2) and w=(3,4), compared with the 2 by 2 identity.
    Figure 2. Each cell of the simple product contains uⁱwʲ. The identity requires two simple summands, although it also has two indices. Original illustration for this edition.

    5. Type, order, dimension, shape, and rank

    On a finite-dimensional real space V, a tensor of type (p, q) is an element of:

    Tpq(V) = V⊗p ⊗ (V*)⊗q.

    Equivalently, it is a multilinear map that takes p covectors and q vectors and returns a scalar. Each vector factor is evaluated against a covector; each dual factor is evaluated against a vector. This correspondence explains why the argument list reverses the roles of the factors.

    Its total order is p + q. Its components carry p upper indices and q lower indices. For example, a tensor of type (2, 1) has the expansion:

    T = Tijk ei ⊗ ej ⊗ εk.

    A scalar has type (0, 0); a vector, (1, 0); a covector, (0, 1); a bilinear form, (0, 2); and an endomorphism of V, (1, 1). The last two have order two and can be represented by matrices, but they obey different transformation laws.

    Terms that should be kept distinct
    TermQuestion answeredExample
    Type (p, q)How many vector and dual factors are involved?A metric: (0, 2).
    OrderHow many index positions are there?A metric has order 2.
    Dimension of VHow many vectors form a basis of V?For ℝ³, it is 3.
    Dimension of the tensor spaceHow many independent coefficients are there before imposing symmetries?np+q when all factors come from V and V*.
    Array shapeHow many entries are there along each axis?(2, 3, 4): three axes and 24 entries.
    Matrix rankWhat is the dimension of the image of a matrix?The 2 × 2 identity has rank 2.
    Tensor decomposition rankWhat is the minimum number of simple products whose sum is T, over the chosen field?The preceding identity requires two.

    In the TensorFlow documentation, rank denotes the number of array axes, that is, its order in that computational vocabulary (TensorFlow, n.d.). Some classical treatments also call the number of indices “rank.” To avoid ambiguity, we use order for that number and specify which kind of rank we mean.

    A third-order tensor is not literally a geometric volume. Drawing its components as a block helps visualize three indexing axes, but does not establish that those axes are spatial coordinates, share the same units, or possess a physically relevant Euclidean metric.

    6. The tensor transformation law

    The consistency of a tensor representation is expressed by a transformation rule for each index position. If e′a = eiPia, the components of a tensor of type (1, 1) transform as:

    A′ab = (P−1)ai AijPjb;
    A′ = P−1 A P.

    This formula follows from requiring the linear map to represent the same relation: if w = Av, then w′ = A′v′. It does not add a decorative condition to an array; it specifies how its representations are related.

    Transformations with e′ = eP
    ObjectTypeNew components
    Vector(1, 0)v′ = P−1v
    Covector, stored as a column(0, 1)a′ = PTa
    Endomorphism(1, 1)A′ = P−1AP
    Bilinear form(0, 2)B′ = PTBP
    Tensor with two vector factors(2, 0)C′ = P−1C(P−1)T

    In general, there is one factor P−1 for each upper index and one factor P for each lower index, with their indices placed appropriately (Reall, n.d.). For orthonormal bases related by an orthogonal matrix Q, we have Q−1 = QT; this is why some differences remain hidden in exclusively Cartesian treatments.

    The same matrix can represent different objects

    Consider the following matrix A as a representation of an endomorphism, and use the oblique basis from Section 2:

    A = 2113;   A′ = P−1AP = 1−114.

    For v = (3, 2), we obtain Av = (8, 9). Its new components are P−1(8, 9) = (−1, 9), and indeed A′(1, 2) = (−1, 9). The new matrix is no longer symmetric under ordinary transposition, although the map remains self-adjoint with respect to the Euclidean metric expressed in the new basis.

    If the same original numbers represented a bilinear form B, its new matrix would be PTBP = ((2, 3), (3, 7)), and it would remain symmetric. The original numerical table is not enough to determine which law to use: the object and its arguments must be known.

    Tensorial consistency requires transforming components, bases, and the operations relating the objects compatibly.

    A change of basis and a physical change

    The preceding examples are passive changes of representation. An active rotation of a body, a deformation, or a transition between physical observers may involve additional operations and laws. In relativity, different observers can measure different values of quantities derived from the same tensor. Tensor formulation makes the descriptions compatible; it does not eliminate those physical differences.

    7. The metric: lengths, angles, and curvilinear coordinates

    A Euclidean metric on a real vector space is a symmetric, positive-definite bilinear form g. It assigns a number to each pair of vectors and makes it possible to define lengths and angles. In a basis, its matrix is G = (gij), where gij = g(ei, ej).

    g(v, w) = vTG w;   ‖v‖² = vTG v;
    cos θ = g(v, w) / (‖v‖ ‖w‖),   v, w ≠ 0.

    In an orthonormal basis, G is the identity. In a general basis, adding the squares of the components can give an incorrect answer. Under the change of basis, G′ = PTGP, so that (v′)TG′v′ = vTGv.

    Length in the oblique basis

    In our example, G = I and:

    G′ = PTP = 1112;
    ‖v‖² = 3² + 2² = 13 = (1, 2) G′ 12.

    The new calculation gives 1² + 2·1·2 + 2·2² = 13. Incorrectly applying the orthonormal formula to the new components would give 1² + 2² = 5. The error would come from forgetting how the metric is represented in that basis.

    The metric also defines the covector associated with a vector: vi = gijvj. Its inverse enables the reverse operation, vi = gijvj. These procedures are called lowering and raising indices. In an orthonormal Euclidean basis the numerical values coincide, but the mathematical roles of the two kinds of components remain different.

    The Euclidean plane in polar coordinates

    The coordinates x = r cos θ, y = r sin θ describe the same Euclidean plane in a region where they form a valid chart. The coordinate basis vectors are obtained by differentiating the position:

    er = (cos θ, sin θ);   eθ = (−r sin θ, r cos θ);
    Gpolar = 100r²;   ds² = dr² + r²dθ².

    For r > 0, these vectors are orthogonal, but the second has length r. The angular coordinate basis vector is not the angular unit vector, which is obtained by dividing it by r. An angular increment of 0.01 radians at a radius of 2 m corresponds, to first order, to 0.02 m of tangential length.

    The dependence of the metric matrix on r does not mean the plane is curved: Euclidean curvature remains zero. Nor does it mean that matrix methods cease to be useful. Jacobian, metric, and transformation matrices remain essential; what changes is the structure that must be carried explicitly through the calculation.

    8. From a tensor at a point to a tensor field

    A differentiable manifold is a space that can locally be described using coordinates in ℝn, with smooth coordinate changes on overlaps. This local resemblance neither imposes a globally Euclidean geometry nor identifies the whole manifold with a single vector space.

    At each point p, a tangent space TpM is defined, and its dual is the cotangent space Tp*M. A tensor at that point belongs to the tensor space constructed from those factors. A tensor field assigns a tensor to each point, with the regularity required by the problem.

    Temperature can be modeled as a scalar field; velocity, as a vector field; and a metric or a stress distribution, as tensor fields. Differentiating tensor fields while preserving their tensorial character requires a connection: partial derivatives of their components do not generally transform as a tensor. In Riemannian geometry, the Levi-Civita connection is the unique connection that preserves the metric and has zero torsion.

    If coordinates change from xi to x′a, vector components obey v′a = (∂x′a/∂xi)vi. For a covector, the inverse Jacobian is used. This is the local version of the preceding change-of-basis rules; in those rules, Pia = ∂xi/∂x′a.

    Areas and volumes: what an arrow can represent

    In an oriented three-dimensional Euclidean space, an oriented area element can be identified with dS = ndS, where n is the unit normal. This identification uses the metric and the orientation; it is not a universal property of every area in every dimension.

    A three-dimensional volume does not possess a unique normal direction. Its oriented expression corresponds naturally to an alternating form of degree three; once the volume form is chosen, it can be described by a signed scalar coefficient. Exterior algebra organizes oriented areas and volumes without forcing them to be ordinary vectors. This distinction sets the limits of the arrow intuition.

    9. The stress tensor: a complete physical example

    In classical continuum mechanics, imagine a plane passing through a point in a material. The surface action exerted by the material on one side upon the other is described by the traction vector t(n): force per unit area on the plane oriented by its unit normal n.

    Under the assumptions of the classical continuum model, Cauchy’s theorem establishes a linear relationship between normal and traction. Here we adopt the column convention: the first index identifies the direction of the traction component, and the second identifies the normal component:

    t(n) = σn;   ti = ∑j=13 σijnj.

    This Cartesian formula uses conventional Euclidean subscripts. Geometrically, we can regard σ as the endomorphism that maps normals to tractions; its other versions with raised or lowered indices are related through the metric. Some sources reverse the index convention, so it must be fixed before multiplying matrices.

    The tensor does not divide the solid’s interior into three “regions” defined by basis vectors. At each point, it encodes how traction depends on the orientation of a plane. In a classical continuum without independent internal couples, angular momentum balance implies its symmetry. Models with couple stresses require a more general treatment (University of Alberta, n.d.).

    A stress state in megapascals

    σ = 210130004 MPa;   1 MPa = 106 N/m².

    For a plane with normal n1 = (1, 0, 0), the product gives t1 = (2, 1, 0) MPa. The traction has a normal component of 2 MPa and a tangential component of magnitude 1 MPa. For the inclined plane with n2 = (1, 1, 0)/√2:

    t2 = (3, 4, 0)/√2 MPa;
    σn = n2 · t2 = 7/2 MPa;
    ttangential = t2 − σnn2 = (−1, 1, 0)/(2√2) MPa;
    τ = ‖ttangential‖ = 1/2 MPa.

    In general, σn = n · σn is the signed normal stress, and τ = ‖σn − σnn‖ is the shear stress magnitude. A positive normal stress indicates tension under the adopted convention. Reversing the normal reverses the traction: t(−n) = −t(n).

    Two planes with normals n1=(1,0) and n2=(1,1) divided by the square root of two, their tractions, and normal and tangential decomposition.
    Figure 3. Section of the problem in the xy-plane. Normals are dimensionless and tractions are measured in MPa; their arrows use different graphical scales. Original illustration for this edition.

    Rotating the axes preserves the physical relationship

    For a passive rotation of the axes through 90° about z, use a new basis whose columns in the old basis form:

    Q = 0−10100001;   σ′ = QTσQ = 3−10−120004 MPa.

    In the new basis, n′2 = (1, −1, 0)/√2 and t′2 = (4, −3, 0)/√2 MPa. We verify that σ′n′2 = t′2. The normal stress remains 3.5 MPa and the tangential magnitude remains 0.5 MPa.

    The principal stresses are the eigenvalues of σ: (5 + √5)/2, (5 − √5)/2, and 4 MPa. The trace is 9 MPa and the determinant is 20 MPa³; both remain unchanged under this change of basis. Trace and determinant are invariants of the endomorphism. This statement must not be extended to the determinant of the matrix of any covariant tensor under arbitrary bases.

    10. Tensor operations and contraction

    Adding tensors requires compatible types. The tensor product combines factors and adds orders: if S has type (p, q) and T has type (r, s), then S ⊗ T has type (p + r, q + s), with a factor ordering that must remain explicit whenever relevant.

    Contraction evaluates a dual factor on a vector factor. In components, this amounts to summing over a compatible pair of indices, one upper and one lower, and reduces the total order by two. For example, the trace Aii of a tensor of type (1, 1) is a scalar.

    Composition of endomorphisms is another example: Cik = ∑jAijBjk. It can be obtained by contracting the tensor product of A and B. The tensor product of their arrays initially has four indices; matrix multiplication retains two after carrying out the sum.

    Summing over two lower indices is not a canonical contraction without additional structure. The inverse metric makes such an operation possible, for example gijBij. In orthonormal Euclidean bases, its coefficients can be hidden as deltas; in general bases, they must appear.

    Consequently, tensor product, elementwise multiplication, and matrix multiplication are not synonyms. Their resemblance in certain implementations does not remove their mathematical differences (Reall, n.d.).

    11. Representation and computation in R

    In R, an array is stored as a vector with a dim attribute and, optionally, dimension names. A matrix is an array with two dimensions. This structure can store tensor components, but does not itself include the tensor type, basis, units, or transformation law (R Core Team, n.d.-c).

    Once bases are chosen, a numerical array of shape (n1, …, nk) can be identified with the coefficients of an element of ℝn₁ ⊗ ⋯ ⊗ ℝnₖ. This mathematical identification is possible, but it does not automatically determine the physical or statistical meaning of its axes. Moreover, R arrays can contain characters or lists; not every array object is a numerical array over a field.

    11.1. Checking bases and the metric

    The following block reproduces the oblique-basis example. solve(P, v) solves the system Pv′ = v, avoiding the explicit construction of the inverse matrix.

    # Change of basis, covector, and metric: base R only
    P <- matrix(c(1, 0, 1, 1), nrow = 2)
    v <- c(3, 2)
    v_new <- drop(solve(P, v))
    G_new <- t(P) %*% P
    a <- c(2, -1)
    a_new <- drop(t(P) %*% a)
    
    v_new                           # 1 2
    G_new                           # rows: (1, 1), (1, 2)
    drop(t(v_new) %*% G_new %*% v_new) # 13
    sum(a * v)                      # 4
    sum(a_new * v_new)              # 4
    
    A <- matrix(c(2, 1, 1, 3), nrow = 2)
    A_new <- solve(P, A %*% P)
    A_new                           # rows: (1, -1), (1, 4)
    stopifnot(isTRUE(all.equal(
      drop(A_new %*% v_new), drop(solve(P, A %*% v))
    )))

    11.2. Simple products, matrix multiplication, and contraction

    With ordinary multiplication as its operation, outer() concatenates the axes of its arguments and multiplies every pair of entries; %o% is a shorthand. %*% performs matrix multiplication when the dimensions are compatible (R Core Team, n.d.-b, n.d.-d).

    u <- c(1, 2)
    w <- c(3, 4)
    outer(u, w)                     # rows: (3, 4), (6, 8)
    u %o% w                         # same result
    sum(u * w)                      # 11: usual inner product
    u * w                           # 3 8: elementwise product
    
    A <- matrix(c(1, 2, 3, 4), nrow = 2, byrow = TRUE)
    B <- matrix(c(5, 6, 7, 8), nrow = 2, byrow = TRUE)
    AB <- A %*% B                   # rows: (19, 22), (43, 50)
    
    # C[i,j,k,l] = A[i,j] * B[k,l]: four axes
    C <- outer(A, B)
    dim(C)                          # 2 2 2 2
    
    # D[i,l] = sum_j C[i,j,j,l]: contraction
    D <- matrix(0, nrow = 2, ncol = 2)
    for (i in seq_len(2)) {
      for (l in seq_len(2)) {
        for (j in seq_len(2)) D[i,l] <- D[i,l] + C[i,j,j,l]
      }
    }
    stopifnot(isTRUE(all.equal(D, AB)))

    The loop’s sum contracts the column index of A with the row index of B. Its intrinsic interpretation presupposes that these indices correspond to compatible dual factors, as in the composition of linear maps. Matching sizes alone does not justify a physical contraction.

    11.3. Shape, indexing, and permutation

    Positive indexing in R starts at 1. In its arrays, the first subscript varies fastest in storage. aperm() permutes the axes and relocates entries; changing only the shape of the stored vector is a different operation (R Core Team, n.d.-a).

    # The first index varies fastest in R storage
    X <- array(seq_len(24), dim = c(2, 3, 4))
    dim(X)                          # 2 3 4: shape
    length(dim(X))                  # 3: number of axes
    length(X)                       # 24: number of entries
    X[2, 3, 4]                      # 24
    X[, , 1]                        # rows: (1, 3, 5), (2, 4, 6)
    
    Y <- aperm(X, c(2, 1, 3))
    dim(Y)                          # 3 2 4
    stopifnot(Y[3, 2, 4] == X[2, 3, 4])
    
    # This instead preserves linear order and changes the shape
    Z <- array(as.vector(X), dim = c(3, 2, 4))
    Z[3, 2, 1]                      # 6
    Y[3, 2, 1]                      # 6: same value in this cell
    Z[1, 2, 1]                      # 4
    Y[1, 2, 1]                      # 2: the arrays differ

    11.4. Reproducing the stress example

    sigma <- matrix(c(2, 1, 0,
                      1, 3, 0,
                      0, 0, 4), nrow = 3, byrow = TRUE)
    n <- c(1, 1, 0) / sqrt(2)
    traction <- drop(sigma %*% n)
    normal <- sum(n * traction)
    shear <- traction - normal * n
    
    normal                          # 3.5 MPa
    sqrt(sum(shear^2))               # 0.5 MPa
    eigen(sigma, symmetric = TRUE)$values
    # 4.000000 3.618034 1.381966
    
    Q <- matrix(c(0, -1, 0,
                  1,  0, 0,
                  0,  0, 1), nrow = 3, byrow = TRUE)
    sigma_new <- t(Q) %*% sigma %*% Q
    n_new <- drop(t(Q) %*% n)
    traction_new <- drop(t(Q) %*% traction)
    stopifnot(isTRUE(all.equal(
      drop(sigma_new %*% n_new), traction_new
    )))

    12. Multidimensional data, statistics, and machine learning

    An array with three axes can organize sales by product, region, and month. With two products, three regions, and four months, its shape is (2, 3, 4), and it contains 24 entries. Each entry records a quantity defined by a combination of categories.

    Four 2 by 3 matrices, one per month, form an array of shape 2,3,4 with entries from 1 to 24.
    Figure 4. Each slice represents a month; rows represent products and columns represent regions. Entry order matches the R example X. Original illustration for this edition.

    In this context, a “dimension” usually means a classification perspective and can include hierarchies: months, quarters, and years; localities, provinces, and countries. These hierarchies add semantics to the data model. They are not consequences of the algebraic definition of a tensor.

    Aggregations also require interpretation. Adding units sold can make sense; adding market shares or average prices without weighting usually does not have the intended interpretation. If values are missing, the aggregation rule must specify whether they are omitted, imputed, or make the result indeterminate. Array shape does not resolve these decisions.

    A bridge to statistics

    A random vector X with finite second moments has covariance C = E[(X − μ)(X − μ)T]. Under a linear transformation Y = LX, covariance transforms as:

    Cov(Y) = L Cov(X) LT.

    For a passive change of components, L = P−1. Under this interpretation, covariance is a tensor of type (2, 0); as a bilinear form, it acts naturally on covectors. In practice, variables can have different units and scales: standardization or the introduction of a metric is a choice made in the analysis, not an automatic property of the data.

    In machine learning, the word tensor often denotes a computational structure of values with axes and a uniform data type. An image batch may have shape (batch, height, width, channels); that organization does not establish that all four axes are equivalent spatial dimensions. The TensorFlow documentation explicitly presents this array-based usage (TensorFlow, n.d.).

    A permutation of categories, a linear combination of variables, and a transformation of physical coordinates can be written using similar operations. Their meaning depends on what is represented. Robust analysis requires preserving that distinction alongside units, axis names, and model assumptions.

    13. A dialectical materialist interpretation

    The distinction between object and representation provides a starting point for a materialist interpretation: the process being investigated is not reducible to the coordinate system used to describe it. Establishing basis independence, however, is a formal result; demonstrating that a model adequately reconstructs a material process requires evidence, delimitation of the object, and validation of its relations.

    This philosophical interpretation, developed here as the author’s argument, is organized around three mediations: the objectivity of the process, the articulation of its determinations, and the historical or dynamical transformation of its states. None is exhausted by arranging numbers in an array.

    Objectivity and changes of description

    The coordinated transformation of bases and components illustrates how a description can vary while preserving specified relations. In the oblique-basis example, the components and metric matrix change, but the length remains the same. In the mechanical example, the stress matrix and the normal’s components change while the relation between plane and traction is preserved.

    This allows objectivity to be considered as the reconstruction of relations that do not depend on a particular representational choice. It does not require identifying every invariant with “the essence” of a process: a model may preserve one property while omitting other decisive material determinations. The relevance of its invariants must be assessed in relation to the problem under investigation.

    Totality and multiple determinations

    A stress tensor articulates normal and shear components within a joint relationship. This articulation offers a precise analogy for studying how determinations condition one another within a structure. Its content nevertheless depends on balance laws, material constitution, and the concrete conditions that make the array a representation of a physical state.

    In social processes, an array crossing sectors, territories, and periods can facilitate the investigation of relations of production, distribution, and accumulation. To contribute explanation, the categories, their mediations, sources, and causal or structural relations must be defined. Multiple axes alone do not demonstrate a dialectically reconstructed totality.

    Contradiction, forces, and movement

    Mechanical stresses can participate in processes of deformation, stability, or fracture. A dialectical interpretation can investigate how opposing actions are articulated and produce transformations under specific conditions. But a philosophical contradiction is not automatically identifiable with two components of opposite signs, two opposing arrows, or a negative entry.

    Nor does the term “tensor” guarantee that its object is a struggle of forces. A metric tensor, a covariance tensor, and a simple product belong to the same formal family but perform different functions. Supporting an interpretation involving opposites requires identifying the material tendencies, how they are related, and the mechanism through which they participate in the process’s development.

    Furthermore, transforming coordinates does not amount to describing evolution. A field σ(x, t) may vary over time, but knowing its tensor type does not provide its evolution equation. Material history, plasticity, memory, or irreversibility may require internal variables and additional constitutive laws. In the study of social processes, historical trajectories likewise cannot be deduced from the number of indices.

    Tensor form allows relations to be expressed independently of a basis; material explanation must justify which relations are represented, how they arise, and under what conditions they change.

    The contribution of dialectical materialism here lies in orienting these questions and examining the mediations between structure, conditions, and movement. Mathematical rigor delimits what the formalism allows us to assert; concrete investigation determines its explanatory scope.

    14. Recap and comprehension exercises

    The tensor concept connects three levels: a multilinear object, a representation by components, and a consistent transformation rule. Applications add a fourth level: the empirical or computational interpretation of those relations. Keeping these levels connected avoids confusing a storage structure with a theory of the phenomenon.

    Four distinctions to retain
    DistinctionPractical consequence
    Object / componentsWhen changing the basis, all compatible representations must be transformed.
    Order / dimension / rankAn array with three axes need not have decomposition rank three.
    Shape / metricThe sizes of the axes do not determine how to measure lengths or distances.
    Formal covariance / material explanationTensor rules do not replace physical laws, statistical assumptions, or historical investigation.
    Exercise 1 · Recovering components in the oblique basis

    Express w = (4, 1) in the basis of Section 2 and calculate its length using the transformed metric.

    Solution. w′ = (3, 1); reconstruction gives 3(1, 0) + (1, 1) = (4, 1). The squared length is 3² + 2·3·1 + 2·1² = 17, the same as 4² + 1².

    Exercise 2 · Distinguishing order and rank

    What is the order of the matrix ((3, 4), (6, 8)) interpreted as the coefficients of u ⊗ w? What are its matrix rank and decomposition rank?

    Solution. Order two, matrix rank one, and decomposition rank one. The tensor is nonzero and is already expressed as a single simple product.

    Exercise 3 · A plane perpendicular to the z-axis

    For σ in Section 9, calculate the traction when the normal is (0, 0, 1).

    Solution. The traction is (0, 0, 4) MPa; the normal stress is 4 MPa and the shear stress is zero. This normal coincides with a principal direction.

    Exercise 4 · Arrays and physical meaning

    Does a sales array of shape (2, 3, 4) make it possible, by itself, to calculate a physical length between its entries?

    Solution. No. It allows them to be indexed. Defining a distance requires specifying a comparison space, a measurement rule, units, and the interpretation of the axes. These choices must be justified by the purpose of the analysis.

    References

    The following sources support the definitions and operations used in this edition. “n.d.” indicates that a verifiable publication date is not specified for the cited resource. Retrieval dates are included for documentation and web materials that may change. The numerical examples, figures, and philosophical interpretation are original developments of this revision.

    R Core Team. (n.d.-a). Array transposition [R documentation: aperm]. Retrieved November 10, 2026, from https://stat.ethz.ch/R-manual/R-devel/library/base/html/aperm.html

    R Core Team. (n.d.-b). Matrix multiplication [R documentation: %*%]. Retrieved November 10, 2026, from https://stat.ethz.ch/R-manual/R-devel/library/base/html/matmult.html

    R Core Team. (n.d.-c). Multi-way arrays [R documentation: array]. Retrieved November 10, 2026, from https://stat.ethz.ch/R-manual/R-devel/library/base/html/array.html

    R Core Team. (n.d.-d). Outer product of arrays [R documentation: outer]. Retrieved November 10, 2026, from https://stat.ethz.ch/R-manual/R-devel/library/base/html/outer.html

    Reall, H. S. (n.d.). General relativity [Lecture notes]. University of Cambridge. https://www.damtp.cam.ac.uk/user/hsr1000/part3_gr_lectures.pdf

    TensorFlow. (n.d.). Introduction to tensors. Retrieved November 10, 2026, from https://www.tensorflow.org/guide/tensor

    Tong, D. (n.d.). Vector calculus [Lecture notes]. University of Cambridge. https://www.damtp.cam.ac.uk/user/tong/vc/vc.pdf

    University of Alberta. (n.d.). Cauchy stress tensor. Engineering at Alberta Courses. Retrieved November 10, 2026, from https://engcourses-uofa.ca/stress/cauchy-stress-as-a-linear-map/

    Original post · Spanish

    José Mauricio Gómez Julián
    Marxist Philosophy of Science · Mathematics and philosophy of science

  • ON THE KRUSKAL-WALLIS TEST

    ON THE KRUSKAL-WALLIS TEST

    Marxist Philosophy of Science · Mathematical statistics

    The Kruskal–Wallis Test: Foundations, Assumptions, Calculation, and Interpretation in R

    From pooled ranks to defensible inference: ties, Dunn comparisons, Holm adjustment, and effect size.

    JOSÉ MAURICIO GÓMEZ JULIÁN

    Originally published: March 25, 2022 · Revised: November 10, 2026

    01. Overview and method selection

    Comparing several groups requires deciding which difference matters: a difference in means, location, spread, or distributional structure. The Kruskal–Wallis test addresses part of this problem through the ordering of observations. Its appeal lies in constructing a test that does not require a normal response distribution, while retaining explicit assumptions.

    Kruskal and Wallis (1952) developed a procedure for independent samples based on ranks in the pooled data. Calling it a “nonparametric one-way ANOVA” is useful provided that replacing values with ranks also changes the information used and the interpretation of the test. Although usually applied to three or more groups, it can also be computed for two. Its relationship to Wilcoxon–Mann–Whitney in that case does not mean that every approximation and correction produces exactly the same p-value.

    Choose the method from the question and design
    SituationProcedure to considerNecessary qualification
    Means; independent groups; approximately normal errors and a common varianceClassical one-way ANOVANormality concerns within-group errors, rather than the distribution obtained by pooling every observation.
    Means; independent groups; approximately normal errors and different variancesWelch ANOVAA common variance is unnecessary; severe skewness, dependence, and influential values still require attention.
    A rank-based comparison; independent groupsKruskal–WallisA specific location or median interpretation requires comparable distributional shapes and spreads.
    The same subjects in every condition; complete blocks with one observation per cellFriedman, when the design permitsRepeated measurements cannot be treated as independent observations.
    A conditional median is the direct target, or covariates or a hierarchy are presentQuantile regression or models appropriate to the designDefine the target and dependence structure; these models are outside the scope of this article.

    The official documentation distinguishes these procedures: oneway.test(..., var.equal = FALSE) applies Welch, kruskal.test() uses ranks, and friedman.test() addresses unreplicated complete block designs (R Core Team, n.d.-b, n.d.-c, n.d.-d). Avoid turning a sequence of normality and variance tests into an automatic method selector: define the question and examine the design first.

    02. Hypotheses and interpretation

    Let X1, …, Xk be the population responses, with distribution functions Fi. A general formulation of the null hypothesis is:

    H0: F1(x) = F2(x) = ··· = Fk(x), for every x.

    The general alternative allows at least one distribution to differ. However, Kruskal–Wallis is not a universal detector of every distributional difference: its statistic summarizes differences in mean ranks. Some alternatives, including certain symmetric differences in spread, can leave these mean ranks approximately equal and yield low power.

    A specific location interpretation can be supported by a shift model:

    Xi = θi + ε,   ε ∼ F0.

    In this model, every group shares a distributional shape and spread, and only θi changes. Testing identical distributions then amounts to testing equal locations; if the median is unique, it also amounts to testing equal medians. Outside that framework, equal medians are insufficient to establish the null, and rejecting the null does not establish different medians.

    The NIST manual states the null in terms of identical populations, whereas the R documentation describes location parameters. These accounts connect through an explicitly stated shift model, rather than an unstated assumption (National Institute of Standards and Technology [NIST], n.d.; R Core Team, n.d.-c).

    Location and spread are different questionsTop: three normal curves with equal spread and different centers. Bottom: three normal curves with the same center and different spreads. Conceptual schematics, not the example data.Location and spread are different questionsSame shape and spread; different centersm1m2m3Same center; different spreadsCommon medianSchematic curves; arbitrary units
    Figure 1. Two different structures. Top: location shifts with equal spread. Bottom: unequal spreads with a common center. These schematic normal curves are unrelated to the numerical example. The lower panel does not imply that Kruskal–Wallis always detects variance differences.

    Describing data with medians does not turn a rank test into a test exclusively about medians.

    03. Assumptions and design

    Assumptions, decisions, and consequences
    AspectWhat needs justificationWhat is insufficient
    IndependenceEach unit contributes an independent observation, and groups are mutually independent.Equal sample sizes or successful software execution.
    Sampling or assignmentHow units were selected and which population is the target of generalization.A small p-value does not correct a biased sample.
    Measurement scaleResponses have a coherent ordering, with comparable measurement across groups.Arbitrary numerical labels do not turn nominal categories into an ordinal scale.
    Location interpretationComparable distributional shapes and spreads when interpreting medians.A nonsignificant variance test does not establish equivalent shapes.
    TiesAverage ranks and a tie correction; examine the frequency of repeated values.Ignoring repetition introduced by discretization or rounding.
    CalibrationAssess the asymptotic approximation or consider permutation calibration.A conventional minimum per group cannot guarantee accuracy in every setting.

    The procedure accommodates unequal group sizes and ordinal responses. It requires no normality assumption, but the ordering and observational units must support a defensible interpretation. Independence is not verified by a histogram: it depends on how the data were obtained (NIST, n.d.).

    In social research, people from the same household, students from the same classroom, or measurements from the same establishment can share conditions that create dependence. Counting them as independent replicates artificially increases the apparent information. Identify the sampling, observation, and assignment units before selecting the test.

    Missing data, exclusions, detection limits, and rounding also need documentation. Removing incomplete observations changes the analyzed sample and can introduce bias depending on the missingness mechanism. Extreme values warrant checking measurement and assessing sensitivity, rather than deleting observations to achieve significance. For ordinal scales with few categories, show category frequencies alongside summaries.

    04. Statistic and ties

    Let k denote the number of groups, ni their sizes, N = Σ ni the total sample size, rij an observation’s pooled rank, Ri the group rank sum, and R̄i = Ri/ni its mean rank. Rank all N observations together, rather than separately within each group. Tied observations receive the average of the positions they occupy.

    Huncorrected = 12N(N + 1) Σi=1k Ri2ni − 3(N + 1).

    If tℓ is the frequency of each distinct value in the pooled sample, the tie correction is:

    T = Σℓ(tℓ3 − tℓ),   C = 1 − TN3 − N,   H = HuncorrectedC.

    Values occurring once contribute zero to T. Without ties, C = 1. If all observations are identical, C = 0 and the test is undefined: no ordinal variability remains to compare. The corrected statistic must be used throughout, including effect-size calculation.

    H ≈ χ2k−1 under H0,   p = P(χ2k−1 ≥ Hobserved).

    The approximation does not make H exactly chi-squared for every sample. The p-value is a tail probability computed under the null and its conditions; it is not the probability that the null hypothesis is true. Distinguishing the statistic from its calibration will matter in the example.

    What ranking preserves

    A strictly increasing transformation applied to every group, preserving ties, leaves ranks and H unchanged. The tradeoff is lost distance information: moving from 10 to 11 and moving from 10 to 100 are very different on the original scale, but the statistic uses only the resulting pooled positions. This property explains both its usefulness and its limitations.

    05. Example data and ranks

    Consider processing time, in minutes, under three protocols A, B, and C. Each group represents six different units. The data are constructed for teaching; they are not research observations or evidence about an actual service. Rows are arranged for readability only and do not imply matching across groups.

    Complete data and ranks computed over N = 18
    RowA: minA: rankB: minB: rankC: minC: rank
    181115.51411.5
    292127.51513.5
    3103.5139.51615.5
    4103.5139.51615.5
    5115.51411.51717
    6127.51513.51818

    The value 10 occupies positions 3 and 4, so both observations receive rank 3.5. The value 11 occupies positions 5 and 6, receiving rank 5.5 even though one observation belongs to A and the other to B. This second case shows why groups must be pooled before assigning ranks.

    Descriptive statistics; linear-interpolated quartiles, R type 7
    GroupnMedianQ1Q3IQRRank sumMean rank
    A6109.2510.751.50233.833333
    B61312.2513.751.50579.500000
    C61615.2516.751.509115.166667

    IQR = Q3 − Q1. Interpolated quartiles are meaningful for these quantitative times; a purely ordinal scale would call for categories and an appropriate quantile convention. The samples intentionally share the same shifted empirical pattern, which establishes nothing about population distributional shapes.

    From observations to pooled ranksThree groups with six observations each. Equal observations receive the same average rank. Ranks are computed by pooling all three groups.From observations to pooled ranksOriginal valuesABC81012141618Time (minutes)Pooled ranksABC14710131618Rank in the pooled sample
    Figure 2. Observations and ranks from the same example. Each point represents one unit; repeated values within a group are stacked vertically. Position and labels distinguish A, B, and C in addition to ink tone. The axes differ: minutes above and ordinal positions below.

    06. Complete calculation

    Here k = 3, N = 18, and nA = nB = nC = 6. The rank sums are 23, 57, and 91. As a check, they sum to 171 = 18 × 19 / 2.

    Huncorrected = 1218 × 19 (2326 + 5726 + 9126) − 3 × 19
    = 13.52046784.

    Seven values occur twice each: 10, 11, 12, 13, 14, 15, and 16. Values 8, 9, 17, and 18 occur only once.

    T = 7(23 − 2) = 42,
    C = 1 − 42183 − 18 = 0.9927760578.
    H = 13.52046783630.9927760578 = 13.61884962,   df = 3 − 1 = 2.

    With two degrees of freedom, the chi-squared survival function simplifies to exp(−H/2). Therefore:

    pasymptotic = exp(−13.61884962 / 2)
    = 0.00110332734 ≈ 0.00110.

    At a prespecified α = .05, the global null is rejected using asymptotic calibration. The evidence concerns the group collection: it does not yet identify different pairs. Moreover, six units per group make a permutation check of the approximation worthwhile, without conflating the resulting p-values.

    07. Dunn comparisons and Holm adjustment

    Dunn comparisons locate differences while retaining the pooled sample ranks and incorporating a tie correction (Dunn, 1964). We declare a family of three two-sided comparisons: A–B, A–C, and B–C.

    Vr = N(N + 1)12 − T12(N − 1) = 28.29411765,
    zij = R̄i − R̄j√[Vr(1/ni + 1/nj)].

    The common standard error is √[28.29411765(1/6 + 1/6)] = 3.07105398. For A–C, the mean-rank difference is −11.33333333, giving z = −3.69037256. Unadjusted two-sided p-values are computed as 2Φ(−|z|).

    Two-sided Dunn: first group minus second group
    PairzUnadjusted pHolm pDecision, α = .05
    A–B−1.845186280.065010450.13002089Do not reject
    A–C−3.690372560.000223930.00067178Reject
    B–C−1.845186280.065010450.13002089Do not reject

    Holm sorts p-values from smallest to largest, applies multipliers 3, 2, and 1, then takes cumulative maxima to preserve ordering. Here this gives 3 × 0.00022392585 = 0.00067177756 and, for the other two pairs, 2 × 0.06501044574 = 0.13002089148. The last adjusted value stays at that cumulative maximum instead of falling to 0.06501045.

    Holm controls the family-wise error rate under arbitrary dependence among tests, provided the individual p-values are validly calibrated; Dunn uses a normal approximation here (Holm, 1979; R Core Team, n.d.-a). The adjustment therefore does not remove small-sample limitations.

    This exploratory strategy reports Dunn after global rejection. Prespecified contrasts can be organized under a different inferential plan; declare the comparison family and multiplicity control before selecting results. Pairwise Wilcoxon tests with their own reranking can form a different strategy, but should not be presented as Dunn comparisons.

    08. Effect size

    A difference can be statistically detectable yet practically small. Here the declared index is rank epsilon squared, using the convention E²R = H/(N − 1). It is a rank-based association measure, rather than a percentage change in minutes.

    ER2 = HN − 1 = 13.6188496217 = 0.80110880.

    Its descriptive meaning can be checked without an automatic “small” or “large” label. With r̄ = (N + 1)/2 = 9.5:

    SSbetween = Σi ni(R̄i − r̄)2 = 385.33333333,
    SStotal = Σi,j(rij − r̄)2 = 481,
    SSbetweenSStotal = 0.80110880 = ER2.

    The identity holds when H includes the tie correction. In this sample, the index equals the fraction of rank variability associated with the group partition. It does not mean that the protocol causally explains 80.1% of original processing times or reduces times by 80.1%. Generalizing the magnitude requires uncertainty assessment and a suitable design.

    Terminology varies across texts and software. A related index, η²H = (H − k + 1)/(N − k), equals 0.77458997 here. It is not interchangeable with E²R; it can even yield negative estimates when H is small. Functions in effectsize distinguish these conventions, and formulas should accompany any report (Ben-Shachar et al., 2020; easystats, n.d.).

    On the original scale, the medians are 10, 13, and 16 minutes; the descriptive C − A difference is 6 minutes. This difference between sample medians is not a Hodges–Lehmann shift estimate, and Dunn’s p-value does not provide a confidence interval for it.

    09. Reproducible R code

    The following code uses only base R and its included stats package. It constructs the data, prints descriptive statistics, computes H, checks agreement with kruskal.test(), performs two-sided Dunn comparisons with Holm adjustment, and verifies the effect-size identity.

    dat <- data.frame(
      group = factor(rep(c("A", "B", "C"), each = 6)),
      time = c(8, 9, 10, 10, 11, 12,
               11, 12, 13, 13, 14, 15,
               14, 15, 16, 16, 17, 18)
    )
    stopifnot(is.numeric(dat$time), all(is.finite(dat$time)),
              !anyNA(dat$group), nlevels(dat$group) >= 2)
    g <- droplevels(dat$group)
    x <- dat$time
    N <- length(x)
    k <- nlevels(g)
    n <- table(g)
    stopifnot(all(n > 0), N > k)
    r <- rank(x, ties.method = "average")
    Rsum <- tapply(r, g, sum)
    Rmean <- tapply(r, g, mean)
    desc <- t(vapply(split(x, g), function(v) {
      q <- quantile(v, c(0.25, 0.75), type = 7, names = FALSE)
      c(n = length(v), median = median(v), Q1 = q[1],
        Q3 = q[2], IQR = q[2] - q[1])
    }, numeric(5)))
    print(desc)
    print(data.frame(dat, rank = r))
    
    
    tied_n <- as.numeric(table(x))
    Tsum <- sum(tied_n^3 - tied_n)
    Ctie <- 1 - Tsum / (N^3 - N)
    if (Ctie <= 0) stop("All observations are tied")
    H_uncorrected <- 12 / (N * (N + 1)) * sum(Rsum^2 / as.numeric(n)) - 3 * (N + 1)
    H <- H_uncorrected / Ctie
    p_asymptotic <- pchisq(H, df = k - 1, lower.tail = FALSE)
    kw <- kruskal.test(time ~ group, data = dat)
    stopifnot(isTRUE(all.equal(H, unname(kw$statistic), tolerance = 1e-12)),
              isTRUE(all.equal(p_asymptotic, kw$p.value, tolerance = 1e-12)))
    print(kw)
    print(c(Tsum = Tsum, Ctie = Ctie, H_uncorrected = H_uncorrected,
            H = H, p_asymptotic = p_asymptotic))
    
    
    Vrank <- N * (N + 1) / 12 - Tsum / (12 * (N - 1))
    pairs <- combn(levels(g), 2)
    post <- do.call(rbind, lapply(seq_len(ncol(pairs)), function(j) {
      a <- pairs[1, j]
      b <- pairs[2, j]
      se <- sqrt(Vrank * (1 / n[a] + 1 / n[b]))
      z <- unname((Rmean[a] - Rmean[b]) / se)
      data.frame(pair = paste(a, b, sep = "-"), z = z,
                 p_raw = 2 * pnorm(abs(z), lower.tail = FALSE))
    }))
    rownames(post) <- NULL
    post$p_holm <- p.adjust(post$p_raw, method = "holm")
    print(post, digits = 9)
    
    
    epsilon_rank <- H / (N - 1)
    eta_H <- (H - k + 1) / (N - k)
    SS_between <- sum(as.numeric(n) * (Rmean - mean(r))^2)
    SS_total <- sum((r - mean(r))^2)
    stopifnot(isTRUE(all.equal(epsilon_rank,
                             unname(SS_between / SS_total), tolerance = 1e-12)))
    print(c(epsilon_rank = epsilon_rank, eta_H = eta_H,
            SS_between = SS_between, SS_total = SS_total))

    Reference results: H = 13.61884962; df = 2; p = 0.00110332734; E²R = 0.80110880. Holm-adjusted p-values, in A–B, A–C, B–C order, are 0.13002089, 0.00067178, and 0.13002089. The complete calculations were executed in R 4.6.0 and independently cross-checked with Python/SciPy; the last printed decimal places may vary.

    The block rejects missing and nonfinite values so that the analyzed sample is explicit. With other data, decide and document missing-data treatment before analysis. For ordinal responses, use numerical codes that respect the ordering, rather than arbitrary conversions of labels.

    10. Permutation calibration and uncertainty

    Permutation calibration

    Under the null of identical distributions and independent observations, group labels are exchangeable while their sizes are held fixed. Ranks can be permuted among group positions, keeping C fixed and recalculating H. If assignment is restricted or the design includes blocks or clusters, permutations must respect those restrictions; shuffling all labels is insufficient.

    The next block draws B = 99,999 random permutations with replacement across draws; each draw redistributes the N observations without replacement. If b simulated statistics are at least as extreme as the observed statistic, use (b + 1)/(B + 1), including the observed configuration. This avoids reporting zero merely because few simulations were run (Phipson & Smyth, 2010).

    pMC = b + 1B + 1,   SEMC ≈ √[pMC(1 − pMC)/B].

    Run this block after the preceding code. The 10−10 tolerance prevents floating-point rounding from excluding numerical ties. The second part exhaustively enumerates partitions of this balanced example; its restriction to three groups of six observations is checked explicitly in the code.

    set.seed(20261110)
    B <- 99999L
    H_perm <- replicate(B, {
      rp <- sample(r, N, replace = FALSE)
      sp <- tapply(rp, g, sum)
      (12 / (N * (N + 1)) * sum(sp^2 / as.numeric(n)) - 3 * (N + 1)) / Ctie
    })
    b <- sum(H_perm >= H - 1e-10)
    p_MC <- (b + 1) / (B + 1)
    MCSE <- sqrt(p_MC * (1 - p_MC) / B)
    print(c(B = B, b = b, p_MC = p_MC, MCSE = MCSE))
    
    stopifnot(N == 18L, k == 3L, all(n == 6L))
    r2 <- as.integer(2 * r)
    target <- sum((2 * Rsum)^2)
    A_choices <- combn(2:18, 5)
    B_template <- combn(2:12, 5)
    extreme <- 0
    total <- 0
    for (j in seq_len(ncol(A_choices))) {
      ia <- c(1L, A_choices[, j])
      rest <- r2[-ia]
      sa <- sum(r2[ia])
      sb <- rest[1] + colSums(matrix(rest[B_template], nrow = 5))
      sc <- sum(r2) - sa - sb
      extreme <- extreme + sum(sa^2 + sb^2 + sc^2 >= target)
      total <- total + length(sb)
    }
    p_exact <- extreme / total
    stopifnot(total == 2858856, extreme == 43)
    print(c(partitions = total, extreme_partitions = extreme,
            labeled_allocations = 6 * total, p_exact = p_exact))

    The first part of the output gives B, b, the Monte Carlo p-value, and its approximate standard error. That error describes simulation variability only, rather than the study’s sampling uncertainty. Monte Carlo provides an alternative calibration of the same H; it need not equal the asymptotic value 0.00110332734, and the smaller of the two should not be selected. The preceding Dunn comparisons remain asymptotic.

    An exhaustive check for this example

    Equal group sizes make H invariant to exchanging group names. The code fixes the first unit in A and the first remaining unit in B, enumerating each unlabeled partition once. There are 2,858,856 partitions, equivalent to 17,153,136 labeled allocations, six per partition. Tied observations remain distinct units with equal values, preserving allocation probabilities.

    Exactly 43 partitions have H at least as large as observed: pexact = 43/2,858,856 = 258/17,153,136 = 0.00001504098. The comparison doubles the ranks and uses integer arithmetic to count extremes without floating-point ambiguity. Because enumeration includes every configuration and the observed one, no further unit is added to the numerator.

    With the stated seeds, R 4.6.0 produced b = 3 and pMC = 0.00004000, with SEMC ≈ 0.00002000. Only three exceedances mean poor relative precision: this short simulation cannot estimate such a small value closely. Exhaustive enumeration does determine its exact conditional value. All three calibrations reject at .05, but their magnitudes differ substantially. Enumeration is preferred in this example because it is feasible and avoids approximation and Monte Carlo error, rather than because it yields the smallest p-value.

    Effect-size uncertainty

    The next supplement computes an exploratory 95% percentile interval for E²R. It resamples within each group, holds group sizes fixed, and recomputes ranks in every replicate. This addresses a different question from permutation: assessing variability around the observed empirical distributions without imposing identical groups.

    set.seed(20261111)
    B_boot <- 3999L
    xb <- split(x, g)
    epsilon_boot <- replicate(B_boot, {
      samples <- lapply(xb, function(v) sample(v, length(v), replace = TRUE))
      y <- unlist(samples, use.names = FALSE)
      if (length(unique(y)) < 2L) return(NA_real_)
      as.numeric(kruskal.test(samples)$statistic) / (N - 1)
    })
    CI_percentile <- quantile(epsilon_boot, c(0.025, 0.975),
                              na.rm = TRUE, type = 7)
    print(CI_percentile)
    print(c(valid_bootstrap = sum(is.finite(epsilon_boot))))
    sessionInfo()

    With only six observations per group, bootstrap sampling reproduces highly discrete empirical distributions. Coverage can be poor and index bias can remain; the interval is not a guarantee of population precision. In R 4.6.0, all 3,999 replicates were valid and yielded the exploratory interval [0.6908765, 0.9104320]. Exclusion of zero must not be used as a test for the presence or absence of association: for bounded indices, bootstrap intervals can exclude zero even under the null (easystats, n.d.). The code prints the number of valid replicates, and sessionInfo() records the environment. Confirmatory conclusions about magnitudes or equivalence require planning the estimand, interval procedure, and sample size specifically.

    11. Reporting the result

    A report should connect design, descriptive statistics, calibration, multiplicity, and limitations. For this constructed example, one possible report is:

    If only Monte Carlo calibration is available, replace the exact value with its corresponding output and report the number of draws, seed, and a measure of simulation precision. A value computed from a random sample of permutations should not be described as “exact” without exhaustive enumeration.

    Interpretive errors and defensible statements
    AvoidDefensible statement
    “The probability that H₀ is true is .00110.”“Under H₀ and the test conditions, the probability of an H at least this extreme is approximately .00110.”
    “All three groups differ.”“The global null is rejected; Dunn with Holm provides evidence for A–C.”
    “A and B are equal because p > .05.”“There was insufficient evidence to reject that comparison; equivalence was not established.”
    “The effect explains 80.1% of processing time.”“Rank epsilon squared is .801; its scale and denominator are stated explicitly.”
    “The median in C is causally six minutes higher.”“The descriptive difference between sample medians in C and A is six minutes; causality depends on design.”

    Medians and IQRs are often informative, but do not prohibit adding means, standard deviations, or other summaries when useful. Descriptive choices should follow the measurement scale, distribution, and question, rather than an automatic obligation imposed by a test name.

    12. Methodological scope

    Ranks are an abstraction from data: they preserve order relations while discarding some distance information. That abstraction is appropriate only in relation to the research object and question. For waiting times, identifying who tends to wait longer may matter; for public budgets, an absolute monetary difference can be decisive and insufficiently represented by ordering.

    Likewise, a statistical category does not itself explain the mechanism producing its differences. Rank comparisons among establishments, sectors, or territories cannot replace investigation of resources, work organization, participant selection, and historical conditions. A test contributes evidence about an observed structure under explicit assumptions; explanation requires theory, contextual knowledge, and a design capable of supporting it.

    A defensible workflow is concrete: define the unit and question; examine distributions and measurement; choose a test coherent with the design; verify calculations; quantify uncertainty; and match conclusions to the available information. Used this way, Kruskal–Wallis becomes a precise tool rather than an automatic response to any ANOVA assumption violation.

    13. References

    Ben-Shachar, M. S., Lüdecke, D., & Makowski, D. (2020). effectsize: Estimation of effect size indices and standardized parameters. Journal of Open Source Software, 5(56), Article 2815. https://doi.org/10.21105/joss.02815

    Dunn, O. J. (1964). Multiple comparisons using rank sums. Technometrics, 6(3), 241–252. https://doi.org/10.1080/00401706.1964.10490181

    easystats. (n.d.). Effect size for rank based ANOVA [effectsize package documentation]. Retrieved November 10, 2026, from https://easystats.github.io/effectsize/reference/rank_epsilon_squared.html

    Holm, S. (1979). A simple sequentially rejective multiple test procedure. Scandinavian Journal of Statistics, 6(2), 65–70. https://www.jstor.org/stable/4615733

    Kruskal, W. H., & Wallis, W. A. (1952). Use of ranks in one-criterion variance analysis. Journal of the American Statistical Association, 47(260), 583–621. https://doi.org/10.1080/01621459.1952.10483441

    National Institute of Standards and Technology. (n.d.). Kruskal Wallis. Dataplot reference manual. Retrieved November 10, 2026, from https://www.itl.nist.gov/div898/software/dataplot/refman1/auxillar/kruskwal.htm

    Phipson, B., & Smyth, G. K. (2010). Permutation p-values should never be zero: Calculating exact p-values when permutations are randomly drawn. Statistical Applications in Genetics and Molecular Biology, 9(1), Article 39. https://doi.org/10.2202/1544-6115.1585

    R Core Team. (n.d.-a). Adjust p-values for multiple comparisons [R documentation]. Retrieved November 10, 2026, from https://stat.ethz.ch/R-manual/R-devel/library/stats/html/p.adjust.html

    R Core Team. (n.d.-b). Friedman rank sum test [R documentation]. Retrieved November 10, 2026, from https://stat.ethz.ch/R-manual/R-devel/library/stats/html/friedman.test.html

    R Core Team. (n.d.-c). Kruskal-Wallis rank sum test [R documentation]. Retrieved November 10, 2026, from https://stat.ethz.ch/R-manual/R-devel/library/stats/html/kruskal.test.html

    R Core Team. (n.d.-d). Test for equal means in a one-way layout [R documentation]. Retrieved November 10, 2026, from https://stat.ethz.ch/R-manual/R-devel/library/stats/html/oneway.test.html

    Welch, B. L. (1951). On the comparison of several mean values: An alternative approach. Biometrika, 38(3–4), 330–336. https://doi.org/10.2307/2332579

    Documentation pages are changing resources; accessed November 10, 2026. Letters a–d follow alphabetical title order. For computational definitions of E²R and η²H, see also the official effectsize documentation. Formulas are stated explicitly to avoid naming ambiguity.

  • SELECTING EXPLANATORY VARIABLES IN STATISTICAL MODELS

    SELECTING EXPLANATORY VARIABLES IN STATISTICAL MODELS

    Mathematical statistics · Philosophy of science

    Selecting Explanatory Variables in Statistical Models

    Parsimony, structure, prediction, and methodological critique

    25 MAR 2022 · REVISED 08 NOV 2026

    Selecting a model requires deciding which relationships to preserve and how to test their consequences. This exposition connects philosophical discussion of parsimony with a reproducible comparison of 128 regressions for the fifty U.S. states. It presents selection criteria, derives PRESS, distinguishes influence from prediction error, and validates the entire procedure. Its central result—four predictors and an outer RMSE of 0.793 years under AIC selection—remains conditional on the model family, historical data, and analytical purpose.

    1. Select for a specific question

    A statistical model organizes relationships among observed quantities through assumptions about a population or process. Selecting explanatory variables means delimiting a representation: deciding which terms to retain, what information they contribute, and what uncertainty the decision introduces. The goal is more than shortening a list of columns. The scientific question, measurement quality, design structure, and intended use all matter.

    Three tasks should be distinguished. Description summarizes associations within the data. Prediction approximates responses for observations that did not participate in fitting. Causal explanation identifies what would change under an intervention, requiring additional substantive and identification assumptions. An observational regression selected by AIC does not automatically answer that last question.

    PurposeCentral decisionRequired evidence
    DescriptionSummarize relationships clearlyMeasurement, fit, and diagnostics
    PredictionReduce out-of-sample lossValidation of the entire procedure
    CausalityIdentify a defined effectDesign, temporal order, and confounding control

    The word explanatory, commonly used to denote a predictor, does not guarantee a mechanistic explanation. A predictive variable may proxy other conditions; a confounder may need to remain even when its coefficient fails a conventional threshold. Before automation, define the candidate universe and any variables that scientific reasoning requires retaining.

    2. Parsimony, abstraction, and material structure

    The principle of parsimony discourages unnecessary complications when several representations are adequate for a purpose. Its historical connection to Occam’s razor does not make simplicity a guarantee of truth or the exclusive property of one probabilistic school. Adequacy must be justified: a short description may omit a decisive relationship, while a long one may capture noise.

    From the standpoint of Dialectical Materialism, scientific abstraction can be understood as a conceptual reconstruction of objective, historically determined relationships. Particular and general determinations are connected: concepts do not exist independently of all material activity, but their content is not merely an arbitrary collection of names. Within this framework, variable reduction should be assessed by the determinations it preserves and the mediations it removes. This is a philosophical interpretation of modelling, not a selection theorem.

    The distinction between outward appearance and internal connection is central to Marx’s critique of representations of economic relations in Capital, volume III, chapter 48 (Marx, 1894/1999). Carefully applied to statistics, it encourages questions about why an association appears and under which conditions it recurs. It does not justify inferring a social cause from a coefficient’s sign or declaring the shortest model true.

    The economy of a representation must remain subordinate to the adequacy of the relationships it represents.

    Four meanings of complexity should be separated: the complexity of a material phenomenon, the parameter count of a representation, an algorithm’s execution cost, and the difficulty of interpreting its output. An efficient algorithm can search a large model family; a small parameter set can describe a complex process. Analogies across these levels are useful when their limits are explicit.

    A rigorous critique of nominalism or subjectivism requires its own arguments. Associating Occam’s name with a penalty formula is insufficient, as is treating every prior distribution as an arbitrary choice. Practical objectivity is strengthened by explicit assumptions, tests of consequences, and sensitivity analysis in both frequentist and Bayesian procedures.

    3. Linear models, assumptions, and hierarchy

    Consider the conditional mean model y = Xβ + ε. The design matrix X has n rows and p columns; p includes the intercept. With full column rank and n > p, the ordinary least squares estimator and projection matrix are:

    β̂ = (XᵀX)−1Xᵀy   ·   ŷ = Hy   ·   H = X(XᵀX)−1Xᵀ

    The formula describes the algebraic solution; unbiased estimation of β requires E(ε | X) = 0. The classical variance σ²(XᵀX)−1 requires Var(ε | X) = σ²I. Conditional normality gives exact t and F distributions for a specification fixed in advance. A selection algorithm does not establish these conditions. Numerical implementation should use QR, as lm() does, rather than explicitly forming an inverse.

    Term hierarchy should be distinguished from multilevel models. In the former sense, a specification containing xz usually retains x and z; one containing x² usually retains x. This is a construction and interpretation rule, especially useful under changes of origin and scale. Substantive restrictions may justify exceptions. In the latter sense, hierarchy describes levels of variation, such as people within regions, often with random effects.

    E(Y | x, z) = β₀ + β₁x + β₂z + β₃xz   ;   E(Y | x) = β₀ + β₁x + β₂x²

    A fixed-degree polynomial regression remains parametric and linear in its coefficients even though its response curve is nonlinear in x. Centering can reduce some collinearity; orthogonal bases re-express the same fitted space when degree is held fixed. Orthogonal columns do not establish statistical independence of the original variables. Transformation constants must be retained for prediction, and unjustified extrapolation should be avoided (Kutner et al., 2005).

    4. What each criterion measures

    RSS denotes the residual sum of squares and TSS the total sum of squares around the mean. R² increases or stays unchanged when columns are added to a nested model fitted on the same observations. Its adjusted version penalizes consumed degrees of freedom:

    R² = 1 − RSS/TSS   ;   R̄² = 1 − [RSS/(n − p)]/[TSS/(n − 1)]

    Mallows’ subset comparison uses a common estimate of residual variance from the full model, s²full. Seeking a small Cp near p presumes that this reference is reasonable. Cp < p is not a test proving absence of bias; the statistic fluctuates and depends on the reference model (Mallows, 1973).

    Cp = RSS/s²full − n + 2p

    For likelihood-based criteria, K denotes the total number of estimated parameters. In Gaussian regression with unknown variance, K = p + 1. AIC estimates a predictive discrepancy through an adjustment to fit; BIC corresponds to an asymptotic evidence approximation under regularity conditions. Their goals are not interchangeable (Akaike, 1974; Schwarz, 1978).

    AIC = −2ℓ(θ̂) + 2K
    BIC = −2ℓ(θ̂) + K log(n)
    AICc = AIC + 2K(K + 1)/(n − K − 1)

    The stated AICc expression applies to Gaussian linear regression and requires n > K + 1; it should not be transferred indiscriminately to every model family. It is relevant when K is not negligible relative to n (Hurvich & Tsai, 1989).

    CriterionPreferred directionInterpretive limit
    Adjusted R²HigherPenalized in-sample fit
    CpSmall; assess relation to pDepends on full-model variance estimate
    AIC / AICcLowerRelative comparison, not a diagnostic
    BICLowerAssumption-dependent approximation
    PRESS / LOOCV RMSELowerPrediction with a fixed formula

    Comparisons require compatible responses, scales, observations, and likelihood treatment. Absolute values from AIC() differ from extractAIC(), used by step(), through constants and variance parameter counting. Across comparable Gaussian models with the same n, these differences do not change the ordering. All tables here use AIC() and BIC() (R Core Team, n.d.-c).

    5. The fifty-state example

    The example uses datasets::state.x77, a matrix included in R containing eight variables for the fifty U.S. states in alphabetical order. R’s documentation traces the information to U.S. Bureau of the Census publications from 1977. This reconstructs the originally described case without private files or machine-specific paths. The following numbers refer to this public dataset, not to an inspection of the unpublished Vida.Rdata file (R Core Team, n.d.-e).

    Name usedMeasurementTime reference
    lifeLife expectancy, years1969–1971
    popPopulation, thousands of residents1 July 1975
    incomePer capita income, dollars1974
    illiteracyIlliteracy, percent1970
    murderMurder and non-negligent manslaughter per 100,000 residents1976
    hsgradHigh-school graduation, percent1970
    frostMean days with minimum below 32 °F (0 °C), capital or large city1931–1960
    areaLand area, square milesGeographic measure

    murder does not measure crime in general. frost measures the frequency of days below freezing, not mean temperature. Measurements also refer to different periods: some covariates postdate the response. This is a retrospective association comparison, not a prospective prediction exercise using information available in 1969.

    base <- as.data.frame(datasets::state.x77)
    names(base) <- c("pop", "income", "illiteracy", "life",
                     "murder", "hsgrad", "frost", "area")
    stopifnot(nrow(base) == 50L, !anyNA(base))
    full <- lm(life ~ ., data = base)

    6. Exhaustive search and results

    Seven numeric predictors and a mandatory intercept produce 2⁷ = 128 subsets, including the intercept-only model; 127 contain at least one predictor. This family excludes interactions, polynomials, and additional transformations. Its best candidate is therefore best within that universe, not among every conceivable representation.

    Branch-and-bound can locate best subsets by size without naively fitting every combination. However, the returned table depends on how many candidates per size are requested. leaps() and regsubsets() are search tools; choosing a size and evaluating the result remain additional decisions. Nor does retaining only the lowest RSS per size guarantee the minimum PRESS, which also depends on leverage. All 128 candidates were fitted here to check every criterion (Lumley, n.d.).

    Top eight by AIC; all models include an intercept.
    #PredictorspR̄²CₚAICBICPRESS
    1pop + murder + hsgrad + frost50.71262.020115.733127.20529.648
    2pop + income + murder + hsgrad + frost60.70614.009117.720131.10431.322
    3pop + illiteracy + murder + hsgrad + frost60.70614.013117.724131.10831.053
    4pop + murder + hsgrad + frost + area60.70604.018117.731131.11534.284
    5murder + hsgrad + frost40.69393.740117.974127.53431.197
    6income + murder + hsgrad + frost50.68945.411119.614131.08632.695
    7illiteracy + murder + hsgrad + frost50.68925.430119.634131.10732.721
    8pop + income + illiteracy + murder + hsgrad + frost70.69936.002119.712135.00832.953

    The model containing pop + murder + hsgrad + frost maximizes adjusted R² and minimizes Cp, AIC, AICc, BIC, and PRESS. It has p = 5 regression coefficients and K = 6 parameters including variance. Its values are RSS = 23.308; R² = 0.7360; adjusted R² = 0.7126; AICc = 117.686; and Cp = 2.020. Agreement among six criteria is a feature of this example, not a general equivalence.

    Two plots of delta AIC and delta BIC against number of predictors, with their minima at four predictors.
    Figure 1. Differences from each criterion’s minimum across 128 candidates. The diamond identifies the selected model. Reference line at Δ = 2; this is not a hypothesis test. Original calculations.

    The three-predictor candidate murder + hsgrad + frost has BIC = 127.534, only 0.330 above the minimum. This supports acknowledging uncertainty about whether population is needed rather than declaring a decisive victory. Adding income, illiteracy, or area barely reduces RSS while consuming additional parameters.

    7. PRESS: prediction with one observation omitted

    Let ei = yi − ŷi be the ordinary residual and hii the corresponding diagonal entry of H. When the formula stays fixed and deletion fits retain full rank, the prediction residual obtained by excluding observation i is:

    di = yi − ŷi(i) = ei/(1 − hii)
    PRESS = Σi=1ndi²   ;   RMSELOOCV = √(PRESS/n)

    This identity avoids refitting the same model n times. PRESS sums squared prediction errors; dividing by n gives the LOOCV mean squared error, and taking its square root restores the response unit. If d is a column vector, dᵀd is its squared Euclidean norm, a scalar. It is not obtained by taking a determinant of d.

    In the income-only model, Alaska has an observed life expectancy of 69.310 years and a fitted value of 72.275. When Alaska is excluded, its predicted response rises to 73.068 years. The ordinary residual is −2.965, hii = 0.210875, and the deleted residual is −3.758. The relevant error compares the prediction to the observed response, rather than subtracting the two predictions from each other (R Core Team, n.d.-d).

    dAlaska = −2.965474/(1 − 0.210875) = −3.757926
    Income and life-expectancy scatterplot with two regression lines; Alaska lies below both.
    Figure 2. Regression of life expectancy on income using all fifty states and excluding Alaska. The vertical line shows Alaska’s prediction residual when it does not participate in fitting. Original calculations.

    A high PRESS does not establish that a particular observation has greater influence. The statistic aggregates errors over all units and combines residuals with design geometry. Attributing influence to Alaska or another state requires individual quantities, such as Cook’s distance or changes in coefficients.

    8. Compare models with visible results

    The table combines specifications from the original exercise with the selected candidate. The original four predictors are population, income, illiteracy, and area. The selected four are population, murder, high-school graduation, and frost. Every value uses the same fifty observations and includes an intercept.

    ModelRSSR̄²PRESSRMSE LOOCV
    Intercept only88.2990.000091.9401.356
    Income78.0760.097489.3221.337
    Population + murder30.4450.640534.0660.825
    Original four55.6020.314391.4271.352
    Selected four23.3080.712629.6480.770
    Seven predictors23.2970.692241.3220.909
    Comparison of six models; the selected four yield RMSE 0.770 years and the full model 0.909.
    Figure 3. LOOCV RMSE for each fixed formula. Bars correspond to the table and do not include repeating variable selection within each partition. Original calculations.

    Compared with the selected model, the full model reduces RSS from 23.308 to 23.297, a negligible fitting improvement, but increases PRESS from 29.648 to 41.322. Additional terms can improve the description of the sample while worsening prediction. This does not establish that omitted variables lack historical, health-related, or causal relevance; within this model family and dataset, including them fails to improve the compared criteria.

    9. Stepwise selection and partial tests

    Forward selection starts with mandatory terms and adds candidates; backward elimination starts with a larger model and removes terms; bidirectional search allows both operations. These are local traversals of a model family. They can stop at different solutions and do not guarantee a global optimum. They should not be confused with Gaussian elimination, which solves linear systems rather than comparing specifications.

    In this example, forward and backward AIC searches reach the same candidate as exhaustive search. The trajectories below use the numerical convention of AIC(). Printed step() tables have different absolute values, while preserving the differences and ordering here.

    DirectionStepTermsAIC
    Backward0pop + income + illiteracy + murder + hsgrad + frost + area121.709
    1pop + income + illiteracy + murder + hsgrad + frost119.712
    2pop + income + murder + hsgrad + frost117.720
    3pop + murder + hsgrad + frost115.733
    Forward01174.329
    1murder129.285
    2murder + hsgrad123.968
    3murder + hsgrad + frost117.974
    4pop + murder + hsgrad + frost115.733

    For a partial test between nested models, let q be the rank difference, RSSR the reduced model’s residual sum of squares, and RSSF that of the larger model, which has pF coefficients. Under the null that the removed block contributes nothing and classical Gaussian assumptions:

    F = [(RSSR − RSSF)/q] / [RSSF/(n − pF)]   ∼   Fq, n−pF

    A large F indicates greater loss of fit under the restriction. The p-value is the probability, under H₀ and the assumptions, of a statistic at least as extreme; it is not the probability that H₀ is true. drop1(model, test = "F") tests each term against the current model. A factor with several categories may involve multiple coefficients. For one coefficient, F = t² and the F-test and two-sided t-test p-values agree.

    Removing terms with large p-values is an exploration rule, not proof of irrelevance. A threshold of α = 0.15 needs justification, and repeated tests do not automatically preserve a global Type I error rate of 0.15. Under AIC or BIC, a search proceeds while the criterion decreases; the aim is not to increase AIC. In step(), k = 2 gives AIC, while k = log(n) gives the BIC-penalized search (R Core Team, n.d.-a, n.d.-b).

    10. Coefficients and diagnostics answer different questions

    The selected model estimates the following conditional mean, in years. Population is measured in thousands of people; high-school graduation in percentage points; murder per 100,000 residents; and frost in days.

    ŷ = 71.02713 + 0.00005014·pop − 0.30015·murder
    + 0.04658·hsgrad − 0.005943·frost
    Termβ̂SEtp-value
    Intercept71.027130.9528574.542< 0.0001
    pop0.00005010.00002511.9960.0520
    murder-0.300150.03661-8.199< 0.0001
    hsgrad0.046580.014833.1420.0030
    frost-0.005940.00242-2.4550.0180

    Holding other covariates fixed, a ten-percentage-point difference in graduation is associated with 0.466 years in the fitted mean. This is not an educational policy effect. Population’s p-value is about 0.052 even though AIC retains it; different decision rules can disagree without a logical contradiction.

    In diagnostics, leverage describes location in predictor space; an outlying residual describes vertical discrepancy; and influence describes how much the fit changes when an observation is removed. High hii alone does not establish influence. Internally and externally studentized residuals differ as follows:

    s² = RSS/(n − p)   ;   ri = ei/[s√(1 − hii)]
    s²(i) = [RSS − ei²/(1 − hii)]/(n − p − 1)
    ti = ei/[s(i)√(1 − hii)]

    With a fixed formula, independent normal errors, and constant variance, ti follows a t distribution with n − p − 1 degrees of freedom. This supports observation diagnostics; it is not the justification for the t-test on β. Cook’s distance combines residual size and leverage to assess influence:

    Di = [ei²/(p s²)] · hii/(1 − hii)²
    StatehᵢᵢtᵢCook D
    Hawaii0.23982.5430.3638
    Washington0.1717-1.4900.0896
    Maine0.0642-2.2010.0613
    South Carolina0.1029-1.6460.0599
    Arizona0.1443-1.3080.0568
    Residual plot with Hawaii and Maine labelled and Cook’s-distance plot peaking at Hawaii.
    Figure 4. Residuals versus fitted values and Cook’s distances for the selected model. The 4/n line is a screening guide, not an automatic exclusion threshold. Original calculations.

    Hawaii has the largest Cook’s D (0.364), followed by Washington. This calls for contextual examination and sensitivity analysis, not deleting states to improve the result. Selected-model VIFs range from 1.190 to 1.728, giving no indication of severe collinearity among these four predictors. They do not establish correct specification. Functional form, residual spread, normal quantiles, and geographic dependence also require examination; a set of plots does not certify every assumption.

    11. Validate the selection procedure

    LOOCV for a formula chosen using all data does not reproduce a procedure that first selects and then predicts. The omitted observation’s response has already affected the initial selection. To evaluate the procedure, exclude each state before selecting: fit all 128 candidates on the remaining 49, choose the minimum AIC or BIC, and predict the held-out state. Aggregate the fifty errors. When internal selection uses validation to tune hyperparameters, an additional inner loop is required; here internal choice uses an information criterion.

    ProcedureSum of squared errorsRMSE, years
    Formula selected on all data, followed by LOOCV29.6480.770
    Exhaustive AIC selection within each partition31.4760.793
    Exhaustive BIC selection within each partition36.2550.852

    Although AIC and BIC choose the same formula using all fifty states, their procedures have different errors when retrained. The decision path matters. These values describe a leave-state-out experiment within this candidate family; they establish neither universal AIC superiority nor performance in future years.

    Stability can also be summarized by counting inclusions across the fifty training sets. Under AIC, population, murder, and graduation appear in 50/50; frost appears in 49/50. Under BIC, population appears in 38/50, murder and graduation in 50/50, and frost in 49/50. Income, illiteracy, and area never appear. These are local sensitivity frequencies under single-unit deletion, not posterior inclusion probabilities or independent population resamples.

    Cawley and Talbot (2010) demonstrate that optimizing an estimated criterion can overfit model selection itself. Consequently, imputation, standardization, learned transformations, and term choice should occur within the relevant training set. Choosing between AIC, BIC, and other strategies after inspecting these outer results introduces another selection layer requiring independent evaluation.

    12. Bayesian complexity: evidence, BIC, and DIC

    A Bayesian model M specifies a likelihood p(y | θ, M) and a prior distribution p(θ | M). Marginal evidence integrates the likelihood with respect to that distribution:

    p(y | M) = ∫ p(y | θ, M) p(θ | M) dθ

    Evidence averages fit over the allowed parameter space. It can therefore disfavor a flexible model that fits extremely well in a small region while assigning much of its prior mass to regions poorly compatible with the data. The Occam factor describes this effect under particular decompositions or approximations; it should not simply be equated with K log(n). BIC approximates −2 log p(y | M), apart from lower-order terms, under asymptotic and regularity assumptions. Priors matter and may require sensitivity analysis (Bishop, 2006).

    DIC uses the posterior distribution. In the formulation of Spiegelhalter et al. (2002), effective complexity pD compares posterior mean deviance with deviance evaluated at the posterior mean:

    D(θ) = −2 log p(y | θ) + C
    pD = E[D(θ) | y] − D(E[θ | y])
    DIC = E[D(θ) | y] + pD

    Its relationship to AIC does not make DIC foreign to Bayesian analysis, nor identical to BIC. Interpretation can be problematic with multimodal posteriors, unsuitable parameterizations, or latent structures. Difficulty constructing a universal complexity measure does not imply absence of mathematical definitions or impossibility of formalization in set theory.

    The published discussion remains instructive. Brooks questions the posterior summary; Smith examines priors and compatible parameterizations; Plummer challenges parts of the justification; Robert and Titterington discuss data use. Nelder emphasizes reviewing distribution, link, and predictor; Atkinson stresses diagnostics. These are specific, varied objections, not a single refutation of all Bayesian inference.

    The stack loss example in that discussion illustrates a broader issue: an observation can appear outlying under one specification and cease to do so after a justified change of family or link. Removing observations is not always the answer. Selecting columns is only one part of selecting structure.

    WAIC and LOO cross-validation provide other tools for Bayesian predictive evaluation, each with conditions and diagnostics. Vehtari et al. (2017) study their computation and assessment. This article does not fit a Bayesian model or calculate DIC or WAIC for the states: these concepts are introduced to distinguish problems rather than treat different criteria as one universal scale.

    13. Alternatives and extensions

    Discrete selection changes a formula abruptly: a coefficient stays or disappears. Regularization controls complexity gradually. Ridge shrinks coefficients with a quadratic penalty; lasso can produce exact zeros with an absolute-value penalty; elastic net combines both. The intercept is usually unpenalized. Predictor scales and the choice of λ matter (Friedman et al., 2010).

    β̂λ = arg minβ { RSS(β)/(2n)
    + λ[α Σj≥1|βj| + (1 − α)Σj≥1βj²/2] }

    Setting α = 0 gives ridge and α = 1 gives lasso. Choosing λ or α belongs inside training for each outer evaluation. Standardization must also be estimated there. With correlated predictors, inclusion stability can remain limited; penalization neither identifies causes nor fixes measurement problems.

    Other extensions include sets of plausible models, predictive averaging, additive models for justified curvature, regional effects, and validation in geographic blocks. Specialized methods exist for post-selection inference, but validity depends on the procedure and target; applying ordinary intervals to the winner is insufficient. For a confirmatory question, prespecification or independent inference data may be preferable.

    Once factors, interactions, or spline bases are introduced, selecting variables and selecting columns no longer coincide. A categorical variable can occupy several columns; an interaction may require retaining lower-order terms. Search should operate on blocks and restrictions consistent with the scientific meaning of the terms.

    14. A reasoned selection protocol

    1. Define purpose and unit of analysis. Specify whether the target is association, prediction, or a causal effect, and the population or situation of intended generalization.
    2. Audit measurement and timing. Examine units, missingness, errors, predictor availability, and dependence among observations.
    3. Delimit candidates and restrictions. Justify mandatory terms, blocks, interactions, and transformations before evaluating results.
    4. Compare against a simple reference. Use the same observations, a common parameter-counting convention, and compatible criteria.
    5. Validate the entire procedure. Repeat selection and learned transformations inside training; reserve outer evaluation.
    6. Assess diagnostics and stability. Examine residuals, influence, functional form, and sensitivity to reasonable decisions.
    7. Interpret with explicit scope. Distinguish association from mechanism, acknowledge selection uncertainty, and document limitations.

    For the fifty states, four predictors provide a favorable fit–prediction compromise within the additive family studied. Agreement among criteria, the nearby three-variable candidate, and different AIC/BIC stability patterns should be communicated together. The scientific result is more than a winning formula: it includes its scope, the decisions that produced it, and the conditions that might require revision.

    Rigorous selection preserves relevant relationships, checks consequences, and makes the uncertainty of reduction visible.

    Appendix A. Complete code and checks

    The following script reproduces the search, tables, estimates, direct PRESS calculation, stepwise paths, VIFs, and evaluation with selection inside each training set. Its core uses only base R. The leaps block is optional and runs only if that package is installed. Variable names are identical in both languages to facilitate comparison.

    It was executed in R 4.3.3, and the principal quantities were also checked through an independent QR calculation. Analytic PRESS was compared with explicit refits; stopifnot() checks detect unexpected numerical changes. No random simulation is involved. Article figures were generated from the same quantities; plot(chosen) supplies additional R diagnostics.

    # Run blocks in their displayed order. All core calculations use base R.
    base <- as.data.frame(datasets::state.x77)
    names(base) <- c("pop", "income", "illiteracy", "life",
                     "murder", "hsgrad", "frost", "area")
    xvars <- setdiff(names(base), "life")
    stopifnot(nrow(base) == 50L, !anyNA(base))
    subsets <- c(list(character(0)), unlist(lapply(seq_along(xvars), function(j) {
      combn(xvars, j, simplify = FALSE)
    }), recursive = FALSE))
    forms <- lapply(subsets, function(v) {
      if (length(v)) reformulate(v, response = "life") else life ~ 1
    })
    fits <- lapply(forms, lm, data = base)
    full <- lm(life ~ ., data = base)
    sigma2_full <- deviance(full) / df.residual(full)
    score <- function(m, sigma2_ref = sigma2_full) {
      n <- nobs(m)
      p <- m$rank                  # regression coefficients, including intercept
      K <- attr(logLik(m), "df")   # p + residual variance for Gaussian lm
      press <- sum((residuals(m) / (1 - hatvalues(m)))^2)
      c(p = p, K = K, RSS = deviance(m),
        adjR2 = summary(m)$adj.r.squared,
        Cp = deviance(m) / sigma2_ref - n + 2 * p,
        AIC = AIC(m), BIC = BIC(m),
        AICc = AIC(m) + 2 * K * (K + 1) / (n - K - 1),
        PRESS = press, RMSEloo = sqrt(press / n))
    }
    tab <- as.data.frame(t(vapply(fits, score, numeric(10))))
    tab$terms <- vapply(subsets, function(v) {
      if (length(v)) paste(v, collapse = " + ") else "Intercept only"
    }, character(1))
    stopifnot(nrow(tab) == 128L)
    best_id <- which.min(tab$AIC)
    chosen <- fits[[best_id]]
    tab[order(tab$AIC), c("terms", "p", "adjR2", "Cp", "AIC", "BIC", "AICc", "PRESS")][1:8, ]
    # All six criteria choose the same candidate in this particular search.
    stopifnot(length(unique(c(best_id, which.min(tab$BIC),
      which.min(tab$AICc), which.min(tab$Cp), which.min(tab$PRESS),
      which.max(tab$adjR2)))) == 1L)
    stopifnot(abs(deviance(chosen) - 23.308042796884) < 1e-8,
              abs(score(chosen)["PRESS"] - 29.648232954953) < 1e-8)
    
    # Direct exhaustive search using leaps (optional; core code above needs no package).
    if (requireNamespace("leaps", quietly = TRUE)) {
      search <- leaps::regsubsets(life ~ ., data = base,
                                 nvmax = 7, nbest = 1, method = "exhaustive")
      summary(search)$which
      summary(search)$adjr2
    }
    
    # PRESS and the Alaska deletion example.
    income_model <- lm(life ~ income, data = base)
    i <- match("Alaska", rownames(base))
    without_i <- lm(life ~ income, data = base[-i, , drop = FALSE])
    c(observed = base$life[i], fitted = fitted(income_model)[i],
      heldout = predict(without_i, newdata = base[i, , drop = FALSE]),
      deleted = residuals(income_model)[i] / (1 - hatvalues(income_model)[i]))
    press_fast <- sum((residuals(chosen) / (1 - hatvalues(chosen)))^2)
    press_direct <- sum(vapply(seq_len(nrow(base)), function(i) {
      m <- lm(formula(chosen), data = base[-i, , drop = FALSE])
      (base$life[i] - predict(m, newdata = base[i, , drop = FALSE]))^2
    }, numeric(1)))
    stopifnot(isTRUE(all.equal(unname(press_fast), unname(press_direct), tolerance = 1e-10)))
    
    # Stepwise candidates: same data, explicit scopes and directions.
    lower <- lm(life ~ 1, data = base)
    scope <- list(lower = formula(lower), upper = formula(full))
    back_aic <- step(full, scope = scope, direction = "backward", trace = 0)
    fwd_aic <- step(lower, scope = scope, direction = "forward", trace = 0)
    back_bic <- step(full, scope = scope, direction = "backward",
                     k = log(nrow(base)), trace = 0)
    drop1(full, test = "F")
    add1(lower, scope = formula(full), test = "F")
    
    # Estimates and diagnostics; conventional inference conditions on a fixed formula.
    coef(summary(chosen))
    confint(chosen)
    diag_tab <- data.frame(state = rownames(base),
      leverage = hatvalues(chosen), rstudent = rstudent(chosen),
      Cook = cooks.distance(chosen),
      deleted = residuals(chosen) / (1 - hatvalues(chosen)))
    diag_tab[order(-diag_tab$Cook), ][1:5, ]
    selected_vars <- attr(terms(chosen), "term.labels")
    vif <- vapply(selected_vars, function(v) {
      others <- setdiff(selected_vars, v)
      1 / (1 - summary(lm(reformulate(others, response = v), data = base))$r.squared)
    }, numeric(1))
    vif
    # Optional plotting in an interactive R session:
    # par(mfrow = c(2, 2)); plot(chosen); par(mfrow = c(1, 1))
    
    # Outer leave-one-state-out validation of the entire exhaustive AIC/BIC search.
    # No held-out response is used to choose the candidate in its training partition.
    outer_errors <- matrix(NA_real_, nrow(base), 2,
                           dimnames = list(rownames(base), c("AIC", "BIC")))
    inclusions <- matrix(0L, length(xvars), 2,
                         dimnames = list(xvars, c("AIC", "BIC")))
    for (i in seq_len(nrow(base))) {
      train <- base[-i, , drop = FALSE]
      local_fits <- lapply(forms, lm, data = train)
      for (criterion in colnames(outer_errors)) {
        criterion_fun <- get(criterion, mode = "function")
        id <- which.min(vapply(local_fits, criterion_fun, numeric(1)))
        winner <- local_fits[[id]]
        outer_errors[i, criterion] <- base$life[i] -
          predict(winner, newdata = base[i, , drop = FALSE])
        v <- attr(terms(winner), "term.labels")
        inclusions[v, criterion] <- inclusions[v, criterion] + 1L
      }
    }
    colSums(outer_errors^2)
    sqrt(colMeans(outer_errors^2))
    inclusions
    stopifnot(abs(sqrt(mean(outer_errors[, "AIC"]^2)) - 0.793422289702) < 1e-8,
              abs(sqrt(mean(outer_errors[, "BIC"]^2)) - 0.851525323981) < 1e-8)
    # Local inclusion frequencies are sensitivity summaries, not posterior probabilities.
    cat("All numerical checks passed.\n")
    sessionInfo()

    Appendix B. Data used

    All fifty records are embedded below. English state names preserve correspondence with R row names. Units are specified in section 5.

    View all 50 states and eight variables
    Statepopincomeilliteracylifemurderhsgradfrostarea
    Alabama361536242.169.0515.141.32050708
    Alaska36563151.569.3111.366.7152566432
    Arizona221245301.870.557.858.115113417
    Arkansas211033781.970.6610.139.96551945
    California2119851141.171.7110.362.620156361
    Colorado254148840.772.066.863.9166103766
    Connecticut310053481.172.483.1561394862
    Delaware57948090.970.066.254.61031982
    Florida827748151.370.6610.752.61154090
    Georgia49314091268.5413.940.66058073
    Hawaii86849631.973.66.261.906425
    Idaho81341190.671.875.359.512682677
    Illinois1119751070.970.1410.352.612755748
    Indiana531344580.770.887.152.912236097
    Iowa286146280.572.562.35914055941
    Kansas228046690.672.584.559.911481787
    Kentucky338737121.670.110.638.59539650
    Louisiana380635452.868.7613.242.21244930
    Maine105836940.770.392.754.716130920
    Maryland412252990.970.228.552.31019891
    Massachusetts581447551.171.833.358.51037826
    Michigan911147510.970.6311.152.812556817
    Minnesota392146750.672.962.357.616079289
    Mississippi234130982.468.0912.5415047296
    Missouri476742540.870.699.348.810868995
    Montana74643470.670.56559.2155145587
    Nebraska154445080.672.62.959.313976483
    Nevada59051490.569.0311.565.2188109889
    New Hampshire81242810.771.233.357.61749027
    New Jersey733352371.170.935.252.51157521
    New Mexico114436012.270.329.755.2120121412
    New York1807649031.470.5510.952.78247831
    North Carolina544138751.869.2111.138.58048798
    North Dakota63750870.872.781.450.318669273
    Ohio1073545610.870.827.453.212440975
    Oklahoma271539831.171.426.451.68268782
    Oregon228446600.672.134.2604496184
    Pennsylvania118604449170.436.150.212644966
    Rhode Island93145581.371.92.446.41271049
    South Carolina281636352.367.9611.637.86530225
    South Dakota68141670.572.081.753.317275955
    Tennessee417338211.770.111141.87041328
    Texas1223741882.270.912.247.435262134
    Utah120340220.672.94.567.313782096
    Vermont47239070.671.645.557.11689267
    Virginia498147011.470.089.547.88539780
    Washington355948640.671.724.363.53266570
    West Virginia179936171.469.486.741.610024070
    Wisconsin458944680.772.48354.514954464
    Wyoming37645660.670.296.962.917397203

    References

    Akaike, H. (1974). A new look at the statistical model identification. IEEE Transactions on Automatic Control, 19(6), 716–723. https://doi.org/10.1109/TAC.1974.1100705

    Bishop, C. M. (2006). Pattern recognition and machine learning. Springer. https://www.microsoft.com/en-us/research/publication/pattern-recognition-machine-learning/

    Cawley, G. C., & Talbot, N. L. C. (2010). On over-fitting in model selection and subsequent selection bias in performance evaluation. Journal of Machine Learning Research, 11, 2079–2107. https://jmlr.org/papers/v11/cawley10a.html

    Friedman, J., Hastie, T., & Tibshirani, R. (2010). Regularization paths for generalized linear models via coordinate descent. Journal of Statistical Software, 33(1), 1–22. https://doi.org/10.18637/jss.v033.i01

    Hurvich, C. M., & Tsai, C.-L. (1989). Regression and time series model selection in small samples. Biometrika, 76(2), 297–307. https://doi.org/10.1093/biomet/76.2.297

    Kutner, M. H., Nachtsheim, C. J., Neter, J., & Li, W. (2005). Applied linear statistical models (5th ed.). McGraw-Hill/Irwin.

    Lumley, T. (n.d.). leaps: Regression subset selection [Package manual]. https://cran.r-universe.dev/leaps/doc/manual.html

    Mallows, C. L. (1973). Some comments on Cp. Technometrics, 15(4), 661–675. https://doi.org/10.1080/00401706.1973.10489103

    Marx, K. (1999). Capital (Vol. III, Chap. 48, “The trinity formula”). Marxists Internet Archive. (Original work published 1894). https://www.marxists.org/archive/marx/works/1894-c3/ch48.htm

    R Core Team. (n.d.-a). Add or drop all possible single terms to a model [Documentation]. https://stat.ethz.ch/R-manual/R-devel/library/stats/html/add1.html

    R Core Team. (n.d.-b). Choose a model by AIC in a stepwise algorithm [Documentation]. https://stat.ethz.ch/R-manual/R-devel/library/stats/html/step.html

    R Core Team. (n.d.-c). Extract AIC from a fitted model [Documentation]. https://stat.ethz.ch/R-manual/R-devel/library/stats/html/extractAIC.html

    R Core Team. (n.d.-d). Regression deletion diagnostics [Documentation]. https://stat.ethz.ch/R-manual/R-devel/library/stats/html/influence.measures.html

    R Core Team. (n.d.-e). US state facts and figures [Dataset documentation]. https://stat.ethz.ch/R-manual/R-devel/library/datasets/html/state.html

    Schwarz, G. (1978). Estimating the dimension of a model. The Annals of Statistics, 6(2), 461–464. https://doi.org/10.1214/aos/1176344136

    Spiegelhalter, D. J., Best, N. G., Carlin, B. P., & van der Linde, A. (2002). Bayesian measures of model complexity and fit. Journal of the Royal Statistical Society: Series B (Statistical Methodology), 64(4), 583–639. https://doi.org/10.1111/1467-9868.00353

    Vehtari, A., Gelman, A., & Gabry, J. (2017). Practical Bayesian model evaluation using leave-one-out cross-validation and WAIC. Statistics and Computing, 27, 1413–1432. https://doi.org/10.1007/s11222-016-9696-4

  • ON THE MARXIST VIEW OF EXISTENCE AS A MATERIAL TOTALITY (DRAFT)

    ON THE MARXIST VIEW OF EXISTENCE AS A MATERIAL TOTALITY (DRAFT)

    Marxist Philosophy of Science

    Dialectical Materialism · Philosophy of Science

    Existence As a Material Totality

    Organic Structure, Universal Interconnection, and Mathematical Layers of Essence

    Originally published:
    Revised:

    Abstract

    Existence is examined as a material totality whose parts are constituted, reproduced, and transformed through objective relations. This thesis brings universal interconnection and reciprocal action into dialogue with a conception of essence articulated through six layers of mathematical determination: set-theoretic, topological, differentiable, metric, operational, and historical-dynamical. The discussion connects this framework with coupled systems, bifurcations, critical phenomena, fractality, dissipation, and self-organized criticality. A computational example shows that spatial symmetry and a stationary distribution can coexist with irreversible dynamics. A materialist interpretation requires identifying concrete mechanisms, specifying the equivalences employed, and testing representations through observation, intervention, and reproducible calculation.

    1. Existence as a material totality

    Material existence exhibits forms of organization in which components acquire properties and possibilities for transformation through their relations. A molecule, an organism, or a social formation is a determinate reality: it has a composition, an internal organization, conditions of reproduction, and a history. Understanding such realities requires investigating both their parts and the mediations that articulate them. The analysis of components and the reconstruction of the totality are complementary moments of knowledge.

    We shall call an objective organic structure an organization of material relations through which components reciprocally condition one another and participate in the reproduction or transformation of a delimited totality. Structure designates the articulation of relations and constraints; organic indicates constitutive dependence among differentiated moments; objective expresses the fact that this organization and its effects exist independently of whether a subject knows them adequately.

    In social systems, this objectivity includes relations produced by human activity. Money, property, and the state depend on historical practices and institutions, yet their effects exceed each individual’s understanding and will. Independence from an individual consciousness is compatible with a relation’s social genesis.

    Organic organization also encompasses conflicts, asymmetries, antagonisms, and failures of reproduction. An organization may sustain itself through relations that undermine its own conditions of existence. Its investigation must therefore address relative stability, the accumulation of tensions, and the possibility of qualitative transformation. The concept is used here in a relational and historical sense, without attributing a conscious purpose or a biological organization to every system.

    A material totality achieves unity through the articulation of its differences: the relations that reproduce it also delimit the conditions of its transformation.

    The essay’s thesis

    Selecting a totality of reference is a methodological step that requires justification. Investigating a cell, a watershed, or a circuit of capital reproduction involves delimiting components, exchanges, scales, and relevant variables. This delimitation is revisable: its consequences must be confronted with the object’s behavior. An open system can be a legitimate unit of analysis, provided that the decisive exchanges with its environment are represented.

    2. Marxist foundations: relations, genesis, and reproduction

    In the 1857 introduction to the Grundrisse, Marx examines production as the activity of socially determined individuals. General abstractions identify shared features, but knowledge of a historical organization requires reconstructing its specific determinations. The concrete totality reproduced in thought results from articulating those determinations; its conceptual representation must be distinguished from the real process to which it refers (Marx, 1973a).

    In the chapter on capital, Marx characterizes the developed bourgeois system as an organization whose relations mutually presuppose one another. Its constitution as a totality involves producing or subordinating the elements it needs to reproduce itself (Marx, 1973b). Two problems are thereby articulated: how an organization arises and how it operates once constituted. Its present mechanisms of reproduction can transform the historical conditions that initially made the system possible.

    This relationship between genesis and functioning makes it possible to understand that a structure has a history even when it reproduces itself regularly. Present regularity may depend on institutions, infrastructures, habits, and distributions of power produced through earlier processes. Historical dependence must be investigated through identifiable mechanisms: material accumulation, learning, irreversible investment, institutional change, or modifications of the conditions of reproduction.

    In his notes on the dialectics of nature, Engels places reciprocal action at the center of the examination of matter in motion and relates causal analysis to the delimitation of processes within a broader interconnection (Engels, 1925/1974). The later systematizations of Rosental and Iudin (1965) and Frolov (1984) condense this orientation into the principle of universal interconnection. Their formulations belong to specific developments within the Marxist tradition and should be read alongside the primary works.

    The philosophical application that follows develops this orientation through contemporary mathematical tools. The use of manifolds, operators, or probabilistic models requires definitions and proofs appropriate to those tools. Their value for dialectical materialism depends on whether they make real determinations knowable and explain concrete transformations.

    3. Universal interconnection and reciprocal action

    Universal interconnection expresses an ontological orientation: material realities exist through conditions, relations, and processes that connect them with other realities. Its methodological consequence is to investigate the mediations relevant to each problem. A relation may be direct or indirect, persistent or transient, constitutive or circumstantial; its importance may also change with the scale or historical regime.

    Several senses of relation should be distinguished. A causal interaction involves mechanisms of production or modification; a structural dependence determines which configurations are possible; a statistical correlation describes an association between variables; a formal correspondence relates mathematical representations. Confusing these senses produces apparent explanations: an association may arise from a common cause, and an algebraic resemblance may occur in materially different processes.

    Reciprocal action requires identifying how effects are linked and with what delays. It can be represented, for example, by a coupled system:

    Equation 1dxdt=F(x,y,u;θ),dydt=G(x,y,u;θ).

    Here, x and y represent states or sets of variables; u, external conditions; and θ, model parameters. Reciprocity is made concrete in the dependencies of F and G. If both functions are differentiable, cross-derivatives help investigate local influence, although a causal dependence also requires justification through the mechanism and research design.

    An interaction may be reciprocal and profoundly asymmetric. Nor must it be instantaneous: delays, memory, and accumulation modify its effects. In political economy, for example, productive organization conditions state power, while legal and political decisions alter the conditions of accumulation. An explanation must specify actors, resources, institutions, and sequences, rather than stopping at an assertion of mutual influence.

    The objectivity of laws is compatible with contingency and probabilistic models. A regularity can operate through distributions, tendencies, or constraints without uniquely determining every event. Investigating necessity and contingency requires specifying the conditions under which a regularity holds and the processes that may modify those conditions.

    4. Essence as the unity of mathematical layers

    Essence is understood here as the articulated unity of the structural determinations that constitute a system, make its identity intelligible, and condition its transformation. Its mathematical formalization unfolds through layers: each specifies which relations are treated as constitutive, which variations are admissible, and under which correspondences the structure is preserved. This development follows the framework of Geometry, History, and Lawfulness (Gómez Julián, 2026), specifying the conditions of preservation.

    The unity of essence admits multiple determinations. A property that may vary when studying one layer can be decisive in another. The length of a circle is irrelevant to establishing its topological equivalence to another circle, but it is constitutive of its intrinsic metric geometry. The level of abstraction depends on the question and must preserve the determinations relevant to answering it.

    Table 1. Six layers of determination of one essence
    LayerStructure consideredRelevant preservationDetermination captured
    Set-theoreticSet XBijectionCardinality and correspondence between elements.
    Topological(X, τ)HomeomorphismContinuity, neighborhoods, connectedness, and compactness.
    DifferentiableSmooth manifold (M, 𝒟)DiffeomorphismStructure of smooth variations and tangent spaces.
    MetricRiemannian manifold (M, g)IsometryLengths, angles, and induced distances.
    OperationalSpecified operations, constraints, and symmetry actionIsomorphism compatible with the operations and actionComposition of operations and the relations they preserve.
    Historical-dynamicalSpecified precedence, transitions, trajectories, or evolutionOrder isomorphism, appropriate categorical equivalence, or dynamical conjugacy, depending on the objectSequences, accessibility, memory, and transformation rules.

    The layers are enriched by adding structure. Choosing a topology on a set and choosing a metric on a manifold are acts of specification. By contrast, a bijection, a homeomorphism, or an isometry compares objects that are already structured. This distinction prevents the construction of an object from being confused with the criterion of equivalence between objects.

    For a fixed smooth Riemannian manifold, the relevant automorphism groups satisfy:

    Equation 2Isom(M,g)⊆Diff(M)⊆Homeo(M)⊆Bij(M).

    A Riemannian isometry is a diffeomorphism that preserves the metric tensor; a diffeomorphism preserves the underlying topological structure. The inclusions express increasing restrictions on transformations. Whether they are strict depends on the space considered. Riemannian definitions and their relationship with curvature are developed in Lee (1997). Moreover, preserving certain invariants is a necessary condition in many problems, but it may be insufficient to establish a complete equivalence.

    The operational layer requires specifying what is preserved. If a group G acts on M through ρ and another group G′ acts on M′ through ρ′, an equivalence of actions requires a correspondence φ between the groups and a correspondence f between the spaces satisfying:

    Equation 3f(ρ(a,x))=ρ′(φ(a),f(x)).

    This condition must be accompanied by appropriate regularity and invertibility properties. The abstract group, its action, and the preserved structure are distinct pieces of information. Symmetries may be discrete or continuous; a structure may have only the identity symmetry. Lie groups are particularly useful for regular continuous symmetries, but they do not exhaust the possible forms of operational organization.

    In a dynamical formulation, if Φt and Ψt represent evolutions, a conjugacy preserving the time parameter satisfies:

    Equation 4f∘Φt=Ψt∘f.

    The equivalence changes if changes in the time scale are allowed, if only orbits are compared, or if the evolution is stochastic. The philosophical question of the persistence of essence must be translated into an explicit preservation criterion appropriate to the process under investigation.

    One essence · multiple determinations

    The layers formalize aspects of the object’s constitution. Their articulation requires compatibility between structures and a material interpretation of their terms. Equivalence at one layer leaves differences at the others unresolved.

    5. An example: two circles and two dynamics

    Consider a circle of radius r and another of radius R, each equipped with its intrinsic arc-length metric. Their angular parametrizations allow us to write:

    Equation 5gr=r2dϑ2,gR=R2dϑ2.

    If the radii are positive, the two circles have the same cardinality and are homeomorphic and diffeomorphic. Their total lengths, however, are 2πr and 2πR. When r ≠ R, there is no global isometry between the circles with the specified metrics: an isometry would preserve total length. This difference directly illustrates how one topological determination admits different metric determinations.

    The abstract isometry group of each circle remains isomorphic to O(2). Knowing only the abstract group is therefore also insufficient to recover the radius. The metric and the relevant action are required. The operational layer provides information about admissible transformations without replacing the full set of structural data.

    Now fix a single circle and compare two angular evolutions:

    Equation 6ϑ˙=ω,ϑ˙=−κsinϑ,ω>0, κ>0.

    The first describes uniform rotation without equilibrium points; the second has equilibria at 0 and π, with different stability properties. Although the space and its metric are the same, the dynamical vector fields differ. The existence of equilibria prevents these evolutions from being conjugate through a dynamics-preserving bijection.

    The example establishes a central consequence: the geometry of state space does not, by itself, determine the law of evolution. Specifying a system may require adding potentials, vector fields, forces, constraints, boundary conditions, or probabilistic rules. Investigating how a material organization produces its lawfulness requires representing precisely these data and their relations.

    6. Coupling, history, and the composition of the totality

    For several components to form a totality, they must interact through relations compatible with their material nature. These relations can be represented through networks, differential equations, jump processes, flow balances, or combinations of such tools. The use of a system of equations must be justified by the question and the object’s properties.

    A formulation incorporating memory can be written schematically as:

    Equation 7x˙(t)=F(x(t),u(t))+∫0tK(t,s)G(x(s))ds.

    The kernel K(t,s) determines how earlier states exert an influence; u(t) represents external inputs. In an equation with memory, specifying only the instantaneous state may be insufficient. Assumptions concerning the functions and kernel must support the existence, uniqueness, and stability of solutions within the domain employed.

    History can also be formalized as a set of events I with a causal precedence relation ≼. A partial order admits incomparable events and requires reflexivity, transitivity, and antisymmetry. Its past function can be defined by:

    Equation 8H(i)={j∈I:j⪯i}.

    The order is recovered through i ≼ j if and only if i ∈ H(j). Conversely, a past function recovers a partial order when, in addition to reflexivity and transitivity, mutual precedence is required to imply identity. Without this last condition, one generally obtains a preorder.

    A partial order can be represented by a category with exactly one morphism from i to j whenever i ≼ j. A general transition category admits more information: it may contain several transformations between the same states. Reducing it to accessibility forgets differences between transitions; identifying it with a partial order requires additional conditions, such as being thin and skeletal (Riehl, 2016).

    Path homotopy preserves a different kind of information. Two paths with the same endpoints may be continuously deformed into one another while passing through different states, consuming different resources, or activating irreversible mechanisms. Their homotopy class does not automatically reconstruct the causal order or the complete material history. If a process returns to the same observable state, the return events must be distinguished to preserve the historical sequence.

    Path dependence can be represented by enlarging the state to incorporate relevant memory. This enlargement is a modeling decision: it requires establishing which records of the past affect the future and testing their predictive contribution. Information accumulation, causal precedence, and irreversibility are related notions whose connections require specific conditions.

    7. Contradiction, emergence, and qualitative transformation

    Dialectical categories guide the investigation of processes in which an organization reproduces itself through relations that can also transform it. Their fruitfulness requires connecting philosophical interpretation with mechanisms and observable criteria. A social contradiction, a dynamical instability, and a logical contradiction belong to different registers; establishing their relationships requires a specific argument.

    The unity and struggle of opposites makes it possible to investigate constitutive dependencies containing opposing tendencies. An analysis of a concrete process must identify which poles presuppose one another, which conditions sustain their unity, and which mechanisms intensify or modify their relationship. The existence of feedback alone does not resolve these questions.

    The transformation of quantity into quality finds one possible representation in changes to a system’s stability or organization. Consider the normal form of a supercritical pitchfork bifurcation:

    Equation 9x˙=μx−x3.

    The equilibria satisfy x(μ − x²) = 0. For μ < 0, the only real equilibrium is x = 0, which is asymptotically stable. For μ > 0, the stable equilibria x = ±√μ appear, while the origin becomes unstable. A continuous variation in the parameter qualitatively changes the organization of equilibria.

    This result belongs to the model and its assumptions, including the symmetry expressed by the normal form. Identifying a bifurcation in a real phenomenon requires estimating parameters, observing changes, and considering alternatives. Moreover, qualitative transformation does not always require a discontinuous jump in the observed variable: in this example, the new branches emerge continuously from the origin.

    The negation of the negation can contribute to examining processes in which a transformation supersedes an earlier organization while preserving certain relations in a new configuration. Its application requires reconstructing what is abolished, what is preserved, and what emerges. The sequence must be established through the material process, without imposing a repetition of stages or a necessary outcome in advance.

    Emergence designates properties of organization whose investigation requires considering relations between components and scales. One must specify whether the term refers to a collective property, a reduction that is impossible under certain constraints, or a new causal capacity. Nonlinearity may promote collective behavior, but linear couplings also generate collective modes and global constraints. The relationship between totality and parts requires defining the observable and the criterion of composition.

    Complexity and chaos should likewise be distinguished. Deterministic chaos refers to properties of certain dynamics, including sensitivity to initial conditions within the regime considered. A complex system need not be chaotic. For smooth autonomous flows in planar regions with bounded orbits and under the relevant assumptions, the Poincaré–Bendixson theorem restricts limiting behaviors; this restriction cannot simply be transferred to forced systems, discrete maps, or delay systems.

    8. Critical phenomena, scales, and renormalization

    The physics of critical phenomena makes it possible to investigate how microscopic interactions produce collective regularities. In the liquid–gas transition, phase coexistence occurs along a line ending at a critical point. As that endpoint is approached, the density difference between the phases disappears. Ordinary coexistence and criticality are related but conceptually distinct phenomena (Tong, n.d.-a).

    In a model of a continuous transition, a common description of the correlation length is:

    Equation 10ξ~ξ0|ϵ|−ν,ϵ=T−TcTc.

    The quantity ξ measures a spatial correlation scale; ξ₀ is an amplitude; and ν is a critical exponent. The relation is asymptotic and describes an approach to the critical point within the specified regime. In a finite sample, system size limits observation of the ideal divergence.

    The thermodynamic limit considers increasing the number of components and the volume while maintaining an appropriate density. It makes it possible to formulate singularities that do not arise in the same way in regular finite systems. A threshold is a reference value of a variable or parameter; the two concepts perform different explanatory functions.

    Renormalization constructs effective descriptions by changing scale and examining how the relevant parameters transform. Near suitable fixed points, different microscopic systems can share exponents and scaling relations. This universality must be delimited through dimension, symmetries, the range of interactions, and other relevant properties (Wilson, 1983; Lesne & Laguës, 2012).

    A renormalization group acts on effective descriptions and should not automatically be confused with an invertible physical symmetry of each microscopic state. Averaging may discard information. Comparison across scales therefore encompasses both preserved regularities and degrees of freedom that have been eliminated.

    The philosophical contribution lies in showing how a material unity admits levels of description with effective lawfulness. Sharing a universality class identifies collective regularities within a regime; it leaves open chemical, biological, and historical differences that are decisive for other questions. Structural comparison gains explanatory force when it specifies both what is preserved and the domain of validity.

    9. Fractals, measures, and multifractal spectra

    Fractal geometry provides tools for describing organizations whose spatial occupancy exhibits scaling behavior. Exact self-similarity, statistical self-similarity, and approximate regularities over finite intervals must be distinguished. In natural materials, observational resolution and characteristic scales restrict the interval over which a scaling law is defensible (Lesne, 1998).

    For box counting, let N(ε) be the number of boxes of side length ε needed to cover a bounded set. When the relevant limit exists:

    Equation 11DB=limε→0logN(ε)log(1/ε).

    This defines the box-counting dimension. Hausdorff dimension is constructed through coverings and Hausdorff measures; its equality with DB requires conditions. An exponent estimated over a finite range likewise does not establish the existence of the ideal limit.

    The ternary Cantor set provides a calculable example. At stage n, there are 2ⁿ intervals of length 3⁻ⁿ. Its self-similarity dimension satisfies:

    Equation 122(13)D=1,D=log2log3≈0.630930.

    In this case, that dimension coincides with the Hausdorff and box-counting dimensions; its topological dimension is zero. The example distinguishes the number of components in an approximation, topological organization, and metric scaling behavior. A fractal dimension does not, by itself, characterize the entire structure.

    Introducing a distribution on a space requires a measure. A measure space is a triple (X, Σ, μ), where Σ is a sigma-algebra and μ is a measure. For disjoint measurable sets, countable additivity states:

    Equation 13μ(⋃n=1∞An)=∑n=1∞μ(An),An∩Am=∅ (n≠m).

    Disjointness is a relation between sets. A metric space, by contrast, is defined through a distance d. Metric and measure can be articulated—for example, when studying balls and their measures—but they represent different data (Viaclovsky, 2003).

    For a multifractal measure, a local exponent can describe, when the limit exists, the behavior of mass around a point:

    Equation 14h(x)=limε→0logμ(Bε(x))logε,f(h)=dimH{x:h(x)=h}.

    The spectrum f(h) records the dimension of sets with a given local exponent. Its definition is different from an operator’s eigenvalue spectrum. Multifractal formalization can represent scaling heterogeneity, provided that the measure and estimation procedure are appropriate.

    10. Dissipation, coherence, and Vitiello’s case

    Open systems exchange energy or matter with their environment. Under appropriate conditions, these exchanges sustain persistent organizations far from equilibrium. The theory of dissipative structures investigates such mechanisms and their stability conditions; the production of local organization is compatible with entropy production in the relevant whole (Prigogine, 1977).

    Vitiello (2014) investigates a correspondence between an electrodynamic representation under specific conditions, damped and amplified oscillators, squeezed coherent states, and self-similar fractal structures. His construction uses a constant magnetic field and a harmonic scalar potential. The result provides a delimited case of formal articulation between physical descriptions.

    Part of the mechanism can be examined through the pair of equations:

    Equation 15mq¨+γq˙+kq=0,mz¨−γz˙+kz=0.

    With appropriate parameters, one term represents damping and the other amplification. Combined coordinates relate this representation to the coupled equations used in the construction. The correspondence shows the importance of including the degrees of freedom and exchanges with the environment required by the model.

    For the damped oscillator considered in isolation, with m, k, γ > 0, the mechanical energy satisfies:

    Equation 16Eq=m2q˙2+k2q2,dEqdt=−γq˙2≤0.

    The second equality follows by multiplying the oscillator’s equation by its velocity. It identifies a loss of mechanical energy from the subsystem; its physical interpretation requires a balance with the environment. An enlarged representation may conserve a global quantity even though one of its parts exhibits dissipation.

    The proposed philosophical interpretation treats these results as examples of how lawfulness becomes intelligible through the reconstruction of relations and conditions. Extending a correspondence to other objects would require specifying new maps, verifying what they preserve, and testing their consequences. The case supports a relational mode of investigation; the universal scope of an ontology requires a further argument.

    11. Self-organized criticality and 1/f-type noise

    Bak, Tang, and Wiesenfeld (1987) proposed self-organized criticality as a mechanism for investigating the emergence of scaling behavior in extended dynamical systems. Investigating a particular model requires specifying the driving, dissipation, local rules, and relationships between driving and relaxation times. Avalanches provide observables whose size and duration can be compared across scales.

    Self-organized criticality is a mechanistic hypothesis that must be tested for each system. Self-organization encompasses broader processes, while chaos, fractality, and criticality refer to distinct properties. An observed power law admits alternative mechanisms; identification requires dynamical evidence and model comparisons.

    In a time series, a 1/f-type noise relation is formulated through the power spectral density:

    Equation 17S(f)∝f−α,fmin≤f≤fmax.

    The case α ≈ 1 is commonly called pink noise within the interval studied. The spectrum describes the distribution of power across frequencies. An ideal model proportional to 1/f at all frequencies presents integrability problems, so cutoffs or limits of the observed regime must be specified.

    An event-size distribution is a different object. For an ideal continuous power-law tail density:

    Equation 18p(s)=(τ−1)sminτ−1s−τ,s≥smin>0,τ>1.

    Normalization requires τ > 1; its mean is finite when τ > 2, and its variance is finite when τ > 3. These conditions follow by integrating the moments over a tail without an upper cutoff. With a finite cutoff, those moments may exist even when they diverge in the idealization.

    The spectral exponent α and the size exponent τ are not interchangeable. Nor can the absence of a mean be inferred merely from the presence of a power law. The empirical design must establish which variable is measured, over which domain, and with what uncertainty.

    Table 2. Related concepts and distinct questions
    ConceptMain questionRelevant evidence
    FractalityHow does spatial occupancy change with scale?Dimensions and stability of fit over a justified interval.
    Deterministic chaosHow do trajectories separate, and how is their evolution organized?Dynamical diagnostics and comparison with alternative stochastic processes.
    CriticalityWhich regularities arise near a critical transition?Correlations, finite-size scaling, control parameters, and exponents.
    Self-organized criticalityWhich mechanism leads to the critical regime?Driving, relaxation, dissipation, and the model’s scaling relations.
    1/f noiseHow is power distributed across frequencies?Spectral estimation, frequency intervals, and alternatives.

    12. From concepts to statistical investigation

    Materialist research must connect the proposed determinations with operations of observation and testing. Each layer requires specifying the object, the available data, the equivalence criterion, and the admissible error. This requirement makes the relationship between a philosophical claim and its scientific representation assessable.

    At the set-theoretic layer, counting depends on rules for identifying units and distinguishing repeated observations. At the topological layer, an observed network depends on how connections are detected and which relations remain unrecorded. At the metric layer, a distance must justify its units, weightings, and sensitivity. The historical layer requires records that allow events to be ordered or transitions to be estimated. These choices condition one another and must be documented.

    12.1. Information geometry and the statistical metric

    A regular family of distributions p(x; θ) can be equipped with Fisher information:

    Equation 19gij(θ)=Eθ[∂ilogp(X;θ)∂jlogp(X;θ)].

    Under conditions of regularity and local identifiability, this matrix defines a Riemannian metric on the parameter domain considered. If it is singular, restrictions or a different formulation are required. Its interpretation is statistical: it measures the local distinguishability of distributions within the model.

    For the normal family with parameters (μ, σ), where σ > 0, direct calculation of the moments of the score vector gives:

    Equation 20g(μ,σ)=(σ−2002σ−2),ds2=dμ2+2dσ2σ2.

    The same absolute change in the mean is statistically more distinguishable when dispersion is smaller. The formula expresses a determination of the probabilistic model. Interpreting it as the geometry of a physical or social process requires justifying the link between parameters, observables, and mechanisms. Locating this structure at the metric layer does not remove that interpretive requirement.

    An intrinsic Fréchet mean minimizes expected or empirical squared distance. Its existence and uniqueness depend on the geometry and the distribution. On a finite-dimensional Hadamard manifold, a distribution with finite second moment admits a unique mean; other geometries may admit multiple minima. The choice of an intrinsic estimator should be compared with appropriate competitors, using criteria external to the procedure whenever possible (Gómez Julián, 2026).

    12.2. Scaling laws: estimation and comparison

    Evaluating a power-law tail calls for estimating its lower threshold, fitting the model with an appropriate method, quantifying uncertainty, and comparing alternatives such as a lognormal or a power law with a cutoff. A straight-looking logarithmic plot is insufficient. If observations are dependent, a procedure based on independence must be adapted and justified (Clauset et al., 2009).

    12.3. A protocol for testing across layers

    Table 3. From structural interpretation to testing
    StepOperationEvaluation criterion
    DelimitDefine the system, environment, scale, events, and variables.The delimitation represents decisive exchanges.
    FormalizeSpecify structures and relations to be preserved.Equivalences have explicit definitions and assumptions.
    IdentifyExamine whether observables distinguish the proposed structures.Observationally equivalent models are recognized.
    EstimateFit parameters and quantify error.Uncertainty accounts for dependence, bias, and resolution.
    CompareUse alternative models and held-out data.The advantage persists under a common, relevant criterion.
    InterveneModify conditions when the design permits.Responses agree with the proposed causal mechanism.
    ReproducePublish code, versions, parameters, and available data.The calculation can be repeated and its limits are identified.

    Synthetic experiments can verify a procedure when the generating process is known. If the evaluation favors the chosen geometry by construction, success establishes adequacy only within that scenario. A claim about real objects requires external data, appropriate controls, and sensitivity analysis. Discretization error, algorithmic tolerances, and finite-size effects are also part of the evaluation.

    13. Reproducible calculation: spatial symmetry and irreversibility

    Consider three states {0, 1, 2} with the discrete topology and distance one between distinct states. This geometry is symmetric under every permutation. Define a discrete-time Markov chain through a transition matrix whose rows indicate the starting state:

    Equation 21P=(0.10.70.20.20.10.70.70.20.1).

    All entries are positive, and each row sums to one. The chain is irreducible and aperiodic. The columns also sum to one, so the uniform distribution π = (1/3, 1/3, 1/3) is stationary. Cyclic rotation of the labels preserves the dynamics; a reflection reversing the cycle exchanges the probabilities 0.7 and 0.2 and is no longer a dynamical symmetry of P.

    The stationary current between two states is defined as:

    Equation 22Jij=πiPij−πjPji.

    For the oriented edges 0 → 1, 1 → 2, and 2 → 0, the result is J = (0.7 − 0.2)/3 = 1/6. The distribution remains stationary while a current circulates. Stationary reversibility would require detailed balance, namely πiPij = πjPji for each pair; that condition fails.

    The divergence between forward and backward pair fluxes provides a per-step indicator of irreversibility:

    Equation 23I=∑i,jπiPijlogπiPijπjPji=12log(3.5)≈0.626381.

    This quantity is a nonnegative Kullback–Leibler divergence, expressed in nats per step. Its interpretation as physical entropy production requires additional assumptions connecting transitions with thermodynamic exchanges. The purely probabilistic calculation already establishes asymmetry in trajectory probabilities in the stationary regime.

    Compare this with Q = (P + Pᵀ)/2. Its diagonal entries are 0.1 and its off-diagonal entries are 0.45. It preserves the same space, distance, and stationary distribution, but satisfies detailed balance. All its currents and its irreversibility indicator are zero.

    Table 4. Exact results for two constructed models
    PropertyChain PChain Q
    Space, topology, and distanceThree states; discrete distanceThe same
    Stationary distributionUniformUniform
    Detailed balanceNoYes
    Dynamical symmetry under permutationsCyclic rotationsAll permutations
    Current 0 → 10.1666670
    Irreversibility 𝓘0.626381 nats/step0

    13.1. Complete verification code

    The following calculation uses only the Python 3 standard library. It checks normalization, stationarity, and the analytical results. The matrices are models constructed for this example; they are not presented as estimates from empirical data.

    from math import log, isclose
    from itertools import permutations
    
    P = [[0.1, 0.7, 0.2],
         [0.2, 0.1, 0.7],
         [0.7, 0.2, 0.1]]
    Q = [[(P[i][j] + P[j][i]) / 2 for j in range(3)]
         for i in range(3)]
    pi = [1 / 3] * 3
    
    for name, A in [("P", P), ("Q", Q)]:
        assert all(isclose(sum(row), 1.0) for row in A)
        assert all(value > 0 for row in A for value in row)
        stationary = [sum(pi[i] * A[i][j] for i in range(3))
                      for j in range(3)]
        assert all(isclose(a, b) for a, b in zip(stationary, pi))
        J = [[pi[i] * A[i][j] - pi[j] * A[j][i]
              for j in range(3)] for i in range(3)]
        irr = sum(pi[i] * A[i][j] *
                  log((pi[i] * A[i][j]) / (pi[j] * A[j][i]))
                  for i in range(3) for j in range(3))
        symmetries = [s for s in permutations(range(3))
                      if all(isclose(A[s[i]][s[j]], A[i][j])
                             for i in range(3) for j in range(3))]
        expected_J = 1 / 6 if name == "P" else 0.0
        expected_I = log(3.5) / 2 if name == "P" else 0.0
        assert isclose(J[0][1], expected_J, abs_tol=1e-12)
        assert isclose(irr, expected_I, abs_tol=1e-12)
        assert len(symmetries) == (3 if name == "P" else 6)
        print(f"{name}: J01={J[0][1]:.6f}; "
              f"I={irr:.6f}; symmetries={len(symmetries)}")
    

    Verified output

    P: J01=0.166667; I=0.626381; symmetries=3
    Q: J01=0.000000; I=0.000000; symmetries=6

    13.2. What the example identifies

    The stationary distribution alone does not distinguish these two dynamics. Transition frequencies and trajectory probabilities do. With a finite trajectory, transitions would have to be estimated and error quantified while accounting for temporal dependence. Unobserved events, state aggregation, and sampling intervals can conceal currents.

    The conclusion is structural in scope: a symmetric metric is compatible with irreversible dynamics. Irreversibility does not, by itself, require replacing distance with an asymmetric function. It may reside in the evolution operator and trajectory probabilities. A geometry of directed costs or a nonreversible Finsler formulation may be useful for other problems, but requires additional justification.

    The three-state model is a finite space and does not require a positive-dimensional Riemannian manifold. This also shows that the layers form an adaptable analytical framework: each object requires the structures that actually apply to it.

    14. Nature and society: material unity and specificity

    Investigating universal relations must preserve differences of organization. A biological system requires consideration of metabolism, regulation, development, and evolution; a social relation requires incorporating practices, institutions, conflict, and historical conditions. Physical exchanges constitute material conditions, while each level’s explanatory capacities depend on its specific mechanisms.

    In the cardiovascular system, tissue heterogeneity and flow distribution require investigating functionally differentiated organizations. Sharma (2009) examines dynamical behaviors and tools from complexity research within this domain. A scaling exponent or a temporal irregularity must be interpreted alongside physiology and measurement conditions. Variability may perform different functions depending on the process and its regime.

    In political economy, the unity of production, circulation, and social reproduction includes property and class relations. Access to means of production, wage labor, credit, and state power condition one another through determinate institutions. A network representation or a system of equations must incorporate these differences if it is to explain accumulation, crises, or social transformation.

    The historical analysis of an institution distinguishes the conditions of its emergence, its mechanisms of reproduction, and the possibilities for superseding it. Reconstructing the genesis of slavery, for example, requires investigating coercion, property, and concrete productive relations. Explaining it does not imply morally justifying it or postulating a universal succession of stages through which every society must pass.

    A relation can facilitate certain productive capacities while imposing suffering, domination, or the destruction of other capacities. Historical judgments about progress therefore require explicit criteria, identifiable actors, and comparative evidence. Understanding a social totality includes the conflicts through which its members reproduce or transform their conditions of existence.

    15. Synthesis: essence, lawfulness, and history

    The materialist conception of existence as an objective organic structure holds that determinate realities are constituted through relations, maintain a relative unity, and transform under material conditions. Knowing them requires reconstructing components and connections, distinguishing scales, and examining mechanisms of reproduction and change.

    Essence can be formalized as a unity of set-theoretic, topological, differentiable, metric, operational, and historical-dynamical determinations. Each layer establishes a domain of relations and a preservation criterion. Investigating an object requires determining which layers are relevant, how they are articulated, and which variations modify its identity with respect to the question posed. The persistence of certain relations may coexist with decisive transformations in others.

    The components of a totality may thus have different natures and participate in a common organization through compatible relations. Their mathematical integration requires specifying couplings, domains, constraints, and conditions of evolution. The system’s unity is expressed through this organization and its capacities, without requiring a universal isomorphism among all its components. Shared structures acquire explanatory scope when one establishes what they preserve and why they are materially relevant.

    Critical phenomena, fractal structures, and the correspondences investigated by Vitiello provide precise problems for investigating relationships between scales and formalizations. History adds constraints that are not automatically captured by a topology, a distance, or an abstract group. The Markov example makes this difference visible: the same space and distribution admit different currents and different degrees of irreversibility.

    Symmetries reveal structural regularities, but their connection to conserved quantities requires dynamical conditions. Within a variational framework, Noether’s theorem connects continuous symmetries of the action with conservation laws under its corresponding assumptions (Tong, n.d.-b). Determining a complete lawfulness requires incorporating the data that specify the process, in addition to its geometric organization.

    The cognitive strength of dialectical materialism resides here in a practice of inquiry: reconstructing material unity through its differentiated determinations, following its historical formation, and subjecting its representations to testing. The universality of connections becomes concrete by explaining which operate, how they operate, and under which conditions they transform the totality.

    Glossary of precise terms

    Automorphism. An invertible correspondence from a structure to itself that preserves the specified relations and operations.

    Dynamical conjugacy. An invertible correspondence intertwining two evolutions with the chosen regularity criterion and time parametrization.

    Essence. The articulated unity of the object’s constitutive determinations; formalizing it requires specifying the relevant layers and relations.

    Invariant. A property or quantity preserved under an explicit class of transformations. A partial set of invariants may be insufficient to classify objects.

    Isomorphism. An invertible equivalence preserving the structure of a specified category. The term requires identifying the objects and relations being compared.

    Lawfulness. The organization of regularities, constraints, and transformation rules of the process considered. Its representation may be deterministic or probabilistic.

    Riemannian metric. A smooth field of positive-definite inner products on a manifold’s tangent spaces. It may exist globally even when curvature prevents its reduction to a Euclidean metric through local coordinates on an open region.

    Symmetry. A transformation preserving a specified structure or law. The symmetry of a space, an equation, and a solution are different pieces of information.

    Totality. A delimited organization of components and relations with conditions of reproduction and transformation. Its methodological delimitation requires material justification.

    References

    Bak, P., Tang, C., & Wiesenfeld, K. (1987). Self-organized criticality: An explanation of the 1/f noise. Physical Review Letters, 59(4), 381–384. https://doi.org/10.1103/PhysRevLett.59.381

    Clauset, A., Shalizi, C. R., & Newman, M. E. J. (2009). Power-law distributions in empirical data. SIAM Review, 51(4), 661–703. https://doi.org/10.1137/070710111

    Engels, F. (1974). Notes and fragments: Dialectics. In Dialectics of nature (C. Dutt, Trans.; 6th printing). Progress Publishers. https://www.marxists.org/archive/marx/works/1883/don/ch07c.htm (Original work published 1925; English translation 1934).

    Frolov, I. T. (Ed.). (1984). Diccionario de filosofía [Dictionary of philosophy] (O. Razinkov, Trans.). Progreso. Entry “Universal interconnection of phenomena,” reproduced in Filosofía en español.

    Gómez Julián, J. M. (2026). Geometría, historia y legalidad: Fundamentos dialéctico-materialistas de los espacios con estructura métrica [Geometry, history, and lawfulness: Dialectical-materialist foundations of spaces with metric structure] [Unpublished manuscript; R Markdown file provided by the author].

    Lee, J. M. (1997). Riemannian manifolds: An introduction to curvature. Springer. https://webhomes.maths.ed.ac.uk/~v1ranick/papers/leeriemm.pdf

    Lesne, A. (1998). Renormalization methods: Critical phenomena, chaos, fractal structures (L. Schneps, Trans.). Wiley.

    Lesne, A., & Laguës, M. (2012). Scale invariance: From phase transitions to turbulence. Springer. https://doi.org/10.1007/978-3-642-15123-1

    Marx, K. (1973a). Introduction. In Grundrisse: Foundations of the critique of political economy (rough draft) (M. Nicolaus, Trans.). Penguin Books. https://www.marxists.org/archive/marx/works/1857/grundrisse/ch01.htm (Original manuscript written 1857).

    Marx, K. (1973b). The chapter on capital: Notebook II. In Grundrisse: Foundations of the critique of political economy (rough draft) (M. Nicolaus, Trans.). Penguin Books. https://www.marxists.org/archive/marx/works/1857/grundrisse/ch05.htm (Original manuscripts written 1857–1858).

    Prigogine, I. (1977, December 8). Time, structure and fluctuations [Nobel lecture]. NobelPrize.org. https://www.nobelprize.org/uploads/2018/06/prigogine-lecture.pdf

    Riehl, E. (2016). Category theory in context. Dover Publications. https://emilyriehl.github.io/files/context.pdf

    Rosental, M. M., & Iudin, P. F. (1965). Diccionario filosófico [Philosophical dictionary] (A. Vidal Roget, Trans.). Pueblos Unidos. Entry “Universal interconnection of phenomena,” reproduced in Filosofía en español.

    Sharma, V. (2009). Deterministic chaos and fractal complexity in the dynamics of cardiovascular behavior: Perspectives on a new frontier. The Open Cardiovascular Medicine Journal, 3, 110–123. https://doi.org/10.2174/1874192400903010110

    Tong, D. (n.d.-a). Phase transitions. In Statistical physics [Lecture notes]. University of Cambridge. https://www.damtp.cam.ac.uk/user/tong/statphys/statmechhtml/S5.html

    Tong, D. (n.d.-b). The Lagrangian formalism. In Classical dynamics [Lecture notes]. University of Cambridge. https://www.damtp.cam.ac.uk/user/tong/dynamics/dynhtml/S2.html

    Viaclovsky, J. (2003). Measure and integration [Lecture notes prepared by E. Brown]. MIT OpenCourseWare. https://ocw.mit.edu/courses/18-125-measure-and-integration-fall-2003/pages/lecture-notes/

    Vitiello, G. (2014). On the isomorphism between dissipative systems, fractal self-similarity and electrodynamics. Toward an integrated vision of nature. Systems, 2(2), 203–216. https://doi.org/10.3390/systems2020203

    Wilson, K. G. (1983). The renormalization group and critical phenomena. Reviews of Modern Physics, 55(3), 583–600. https://doi.org/10.1103/RevModPhys.55.583

    Note on sources

    References to the Grundrisse point to the sections of Martin Nicolaus’s translation available online; the explanations in this essay are paraphrases. Gómez Julián’s manuscript is identified by its title and the date in its metadata, without attributing a publication status or external validation to it. The integrative formulations and constructed examples belong to this essay’s argument.

    JOSÉ MAURICIO GÓMEZ JULIÁN · MARXIST PHILOSOPHY OF SCIENCE
  • ON THE MARXIST THEORY OF KNOWLEDGE AND ESSENCE (DRAFT)

    ON THE MARXIST THEORY OF KNOWLEDGE AND ESSENCE (DRAFT)

    Marxist Philosophy of Science · Philosophy and Method

    JOSÉ MAURICIO GÓMEZ JULIÁN

    Marxist Theory of Knowledge and Essence

    Abstraction, Totality, and the Reconstruction of the Concrete

    Originally published:
    Revised:

    Abstract

    How can we know the essential relations of a historical reality without confusing that reality with its conceptual reconstruction? This essay develops an answer from the standpoint of dialectical materialism: inquiry begins with a reality independent of thought, produces determinate abstractions, and reconstructs their connections within an explanatory totality, subject to revision through evidence and praxis. Essence is understood here as an articulation of constitutive, historical, and transformable relations. The essay distinguishes essence, content, form, phenomenon, and appearance; examines the relations between inquiry and exposition, logic and history, necessity and contingency; and assesses connections with statistics, algebra, and quantum mechanics. A study of relations between the United States and El Salvador in 2020–2022 shows how to compare explanations without turning a political hypothesis into a predetermined conclusion.

    Key concepts: dialectical materialism; historical materialism; scientific abstraction; essence and phenomenon; the concrete in thought; totality; praxis.

    01 The problem: knowing a reality that thought does not produce

    Knowing a society requires more than listing events, recording opinions, or accumulating indicators. A wage, a law, an investment decision, and a protest belong to the same historical reality, but their coexistence does not yet explain the relations connecting them. The problem of knowledge consists in reconstructing those relations: identifying what makes a process possible, how it reproduces itself, what it depends on, and under what conditions it can be transformed.

    The materialist starting point is the priority of reality over our knowledge of it. A social relation can exist and produce effects without those participating in it understanding its structure. Scientific thought works on representations, concepts, and evidence to develop an explanation; its constructive activity has an object that is not identical with that construction. The objectivity of the object is compatible with the elaborated character of knowledge.

    Three questions should be distinguished. The ontological question concerns the relations and processes that exist; the epistemological question concerns how we know them and justify our claims about them; and the logical question concerns the articulation, consistency, and development of conceptual determinations. Their connection allows the same object to be investigated through complementary dimensions. No correspondence among them guarantees in advance that a category adequately describes reality.

    Within this framework, historical materialism provides a historiographical and sociological theory of social formations, whose methodological grounding is developed in the philosophy of dialectical materialism. This relationship does not replace historical inquiry with deduction from general principles. It requires studying how the material production and reproduction of life are organized through determinate social relations, and how these are articulated with institutions, conflicts, practices, and forms of consciousness.

    The position adopted in this essay is a materialist reconstruction of essence. It engages with Hegel, Marx, Dussel, Rosental, and Zubiri while distinguishing their problems and vocabularies. Its operational formulations are interpretive proposals whose usefulness depends on what they make it possible to explain and on their capacity to address objections.

    02 Abstraction, ascent, and the return journey

    2.1. The difference between the real concrete and the concrete in thought

    The 1857 introduction to the Grundrisse distinguishes social reality from the way thought appropriates it. A population may seem to provide a sufficiently concrete starting point; naming it without determining its divisions, activities, and relations, however, yields a representation that remains inadequate. Inquiry must analyze that totality and reconstruct its mediations. The conceptual result is not society generated by thought, but its intellectual appropriation (Marx, 1973, introduction, section 3).

    The real concrete is the actually existing process, with both known and unknown determinations. The concrete in thought is a conceptual reconstruction of its relations. It may be richer and more precise than an initial representation, but it remains partial and revisable. Its degree of concreteness is measured by the relevant mediations it articulates, rather than by the number of details it accumulates.

    2.2. Abstraction as determinate separation

    To abstract is to consider a determination under certain conditions while provisionally setting others aside. Studying real wages may require distinguishing nominal wages from the price level; studying the wage relation additionally requires considering property, hiring, the reproduction of labor power, and the organization of the labor process. Each operation addresses a question and establishes a scope.

    An abstraction becomes impoverished when it forgets the conditions of its construction and presents itself as a sufficient explanation of the entire object. It can also fail by omitting a constitutive relation. If ownership of the means of production is relevant to the problem, excluding it to simplify the exposition changes what we are trying to know. Exclusions and the reasons justifying them must therefore be made explicit.

    2.3. To ascend is to reconstruct mediations

    The ascent from the abstract to the concrete articulates progressively richer determinations. An isolated category acquires content through its connection with others: wage labor, capital, competition, credit, and the state cannot be treated as independent pieces that can be added without changing the explanation. Introducing a new mediation may transform the meaning of previously established determinations.

    Dussel systematizes this problem by distinguishing levels of representation, abstraction, and explained totality. His schema allows an initially constructed totality to be distinguished from a more determinate historical reconstruction. The attribution matters: this organization of levels belongs to an interpretation of Marx developed by Dussel, rather than to a universal protocol exhaustively formulated in the 1857 manuscript (Dussel, 2010, chap. 2).

    Reality, representation, abstraction, and reconstructionReality is the referent of an initial representation. Analysis produces abstract determinations; their articulation yields a concrete reconstruction in thought. Testing and praxis allow representations and categories to be revised. Conceptual reconstruction does not produce the real object. CONCRETE REALITYObject and historical conditions of inquiry INITIAL REPRESENTATIONData, experience, documentsand available categories CONCRETE IN THOUGHTRelations and mediationsarticulated in an explanation AnalysisSynthesis ABSTRACT DETERMINATIONSDelimited relations and explicit conditions TESTING AND PRAXIS → REVISING DATA AND CATEGORIES Thought reconstructs its object; praxis intervenes upon it.
    Figure 1. A schema developed for this essay. Arrows represent operations of knowing and testing; material transformation belongs to praxis.

    2.4. Return and revision

    In Marx’s passage, the return journey toward an enriched totality is connected with the ascent from abstract determinations. Interpretations that distinguish an ascent from a subsequent descent must specify what they mean by each movement. Operationally, it is useful to distinguish analyzing determinations, reconstructing their articulation, and evaluating the explanation in historical situations. These tasks recur and correct one another.

    Returning to the object means asking what the reconstruction explains, what it leaves unresolved, and what evidence might require changing it. Totality is a requirement to articulate relevant relations. Conceiving it as possession of every possible fact would turn a methodological orientation into a claim to omniscience.

    03 Inquiry, exposition, and historical order

    Inquiry requires examining materials, comparing situations, and developing hypotheses, often through advances, corrections, and unsuccessful paths. Exposition requires organizing results so that their connections can be understood and discussed. Marx distinguishes these tasks in the 1873 afterword to the second German edition of Capital. A well-articulated exposition may appear to be a deduction preceding experience, even though it presupposes prolonged research (Marx, 1873).

    The order of exposition must be justified by the dependencies within the object and the results of inquiry. Chronology, by contrast, establishes when processes occurred. Explaining a present structure may usefully begin with relations that emerged relatively late in its history. This expository choice retains the obligation to explain their genesis and avoids projecting them backward as if they had always existed.

    Table 1. Three related orders
    OrderQuestionRequirement
    HistoricalHow were the relations constituted and transformed?Establish documented dates, conditions, and sequences.
    InquiryHow was knowledge obtained and revised?Make sources, operations, and inferences traceable.
    ExpositionIn what order is the explanation best understood?Justify dependencies among categories and results.

    The treatment of merchant capital illustrates the problem: its historical existence before capitalist industry does not automatically determine the place it should occupy in an explanation of developed capitalism. Its function depends on the social formation under examination. Rosental devotes part of his analysis of Capital to this relationship between logical and historical order (Rosental, 1961, pp. 366–377). Temporal priority, explanatory priority, and causal importance are different determinations.

    Another example is the relationship among value, average profit, and the price of production. Analyzing a more determinate category requires reconstructing mediations and recognizing the assumptions of the presentation. Marx defines the price of production in terms of cost-price and average profit; this does not warrant identifying it directly with the individual value of each commodity (Marx, 1894, chap. 9). A complete assessment of the transformation problem requires a separate study. Its methodological significance here is to show that adding mediations changes the quantitative and conceptual relations under consideration.

    04 Essence as an articulation of relations

    4.1. Shared properties and constitutive relations

    That several objects share a property allows them to be classified, but does not establish that the property explains their constitution. Two institutions may use similar technologies while reproducing different labor relations. Conversely, the same relation of domination may be organized through different technical and legal arrangements. Observable similarity provides a starting point for inquiry; its explanatory importance must be established.

    Here, essence is understood as the articulation of relations whose reproduction makes the determinate identity of a process intelligible, and whose transformations help explain changes in that identity. The definition refers to an object, a scale, and a question. A relation may be decisive in explaining the wage-based character of a productive organization yet insufficient to explain the distribution of occupational disease within it.

    The tradition of Rosental and Iudin emphasizes the connection between essence, relatively stable relations, and variable manifestations. It also recognizes that essence changes. This approach is fruitful when stability is investigated as the reproduction of relations under determinate conditions, and when every attribution of essentiality is accompanied by an explanation of its scope (Rosental & Iudin, 1971, entries “Essence” and “Essence and Phenomenon”).

    4.2. A unity with multiple determinations

    The unity of a process can be investigated through several structural dimensions. The following complementary questions are developed here for use when the object calls for them. Their articulation concerns the same reality examined through different relations; their selection must be justified in each study.

    Table 2. One unity, multiple structural determinations
    DimensionResearch questionExample in a productive organization
    CompositionWhich elements and positions participate?Workers, means of production, owners, and suppliers.
    ConnectionsHow are they related, and through which dependencies?Hiring, coordination of work, and supply chains.
    MagnitudesWhich proportions and quantitative limits matter?Working hours, productivity, remuneration, and costs.
    OperationsWhich practices reproduce or alter the organization?Investment, hiring, negotiation, and control.
    Variations and invariantsWhat changes and what is preserved when conditions vary?Persistence of the wage relation after a task is automated.
    Genesis and dynamicsHow did the structure emerge, and how can it change?Formation of property relations, conflicts, and productive reorganization.

    Connections can be formalized as a network; a measurement may require a metric structure; continuous change may be studied through differential equations. Adopting each tool requires defining its objects and conditions of application. Sharing an essence or belonging to a totality does not establish an isomorphism among components. An exact structural correspondence requires specifying the operations or relations preserved and demonstrating that the mapping satisfies the relevant properties.

    4.3. Identity, contradiction, and reproduction

    The identity of a process can be sustained through transformations of its components. An organization replaces machinery and personnel while maintaining certain relations of property and command. Its continuity requires activities, rules, material flows, and decisions that reproduce it. Investigating these conditions makes both its stability and its vulnerability intelligible.

    A dialectical contradiction here designates an opposition between tendencies or relations that require and place pressure on one another within the process being investigated. We must show what is opposed, through which mechanisms, and with what effects. The word “contradiction” loses explanatory force when applied indiscriminately to a verbal inconsistency, a disagreement, a negative correlation, and any social conflict.

    The relative autonomy of an institution forms part of this inquiry. The reproduction of a social formation depends on legal, political, and ideological mediations that have material effects. Engels’s letter to Bloch warns against turning economic determination into an exclusive explanation of every event (Engels, 1890). Establishing which mediations are decisive requires studying their reciprocal action in concrete situations.

    Relations and operations in the reproduction of a capitalist organization Four connected moments: property and access to means, hiring and organization of work, production and realization, and appropriation and investment. Their connections reproduce or transform the initial conditions. Rules, conflict, and external conditions intervene throughout the process. PROPERTY AND ACCESSPositions and availablematerial means HIRING AND COMMANDOrganization of workand cooperation PRODUCTION AND REALIZATIONMaterial transformationand exchange APPROPRIATION AND INVESTMENTDistribution of the outcomeand new conditions REPRODUCTIONOR TRANSFORMATION RULES · CONFLICT · HISTORY · EXTERNAL CONDITIONS
    Figure 2. Relations and operations in a reproduction schema developed for this essay. Connections indicate dependencies to investigate; their outcomes depend on institutional mediations, conflicts, and historical conditions.

    4.4. Hegel, Marx, and the dialogue with Zubiri

    In the Science of Logic, Hegel develops essence through relations of reflection, negativity, and ground. Its identity includes mediation and difference; reducing it to the formal identity of an object with itself removes precisely the problem he seeks to develop (Hegel, n.d.-b, §§ 807–816). A materialist appropriation must distinguish that development from the status it assigns to the relationship between thought and reality.

    Zubiri offers his own examination of essence and of different historical ways of understanding it (Zubiri, 1985). His vocabulary can serve as a point of dialogue, provided the relevant passages are identified and a Marxist philosophy is not attributed to him. Moving between authors requires reconstructing arguments and differences; the recurrence of a term does not guarantee that its concept is identical.

    The proposal developed here locates objective essence in the relations of the object, and the conceptual elaboration of that essence in the activity of knowing. Inquiry transforms concepts; praxis can transform the relations being studied. Distinguishing these operations makes it possible to explain their connection without making the existence of a process depend on someone conceiving it.

    05 Essence, content, form, phenomenon, and appearance

    These categories intersect, but their differences should be preserved. The following table establishes their use in this essay. It functions as an analytical tool while recognizing that translations and philosophical traditions may employ the terms differently.1

    Table 3. Operational distinctions
    CategoryProposed useExample: the wage relation
    EssenceConstitutive relations explaining an identity and its reproduction.Social conditions making it possible to sell and purchase labor power.
    ContentActual elements, relations, and processes considered within the unity under study.Labor, remuneration, property, cooperation, command, and conflict.
    FormMode of organizing and articulating content, with effects of its own.Contract, working-time arrangements, and the institutional organization of payment.
    PhenomenonActual manifestation through which a process presents itself and can be investigated.Wage changes, payments, turnover, and labor disputes.
    AppearanceMode of presentation that can express and simultaneously conceal relations.The representation of wages as payment for all the labor performed.

    Form organizes and conditions content. A contract establishes obligations and possibilities for action; a form of property shapes decisions and appropriation. Calling a relation “formal” therefore does not establish that it is superficial or causally irrelevant. Forms can stabilize a process, open possibilities, or block transformations.

    A phenomenon need not coincide with what is immediately visible to the naked eye. Instrumental records, archives, and statistical procedures allow mediated manifestations to be investigated. The distinction between observation and explanation recognizes the need to elaborate relations; it does not divide reality into an accessible exterior and an absolutely inaccessible interior.

    Appearance can be sustained by objective relations. In Marx’s analysis of fetishism, the problem concerns how social relations present themselves through things and acquire practical efficacy in exchange (Marx, 1867, chap. 1, section 4). Understanding this presentation requires explaining its social conditions and reproduction, alongside examining individual representations.

    An adequate explanation of essence must account for its forms of manifestation. Claiming that a datum is misleading requires showing how it was produced, which relation it expresses, and why it leads to an inadequate interpretation. Otherwise, invoking the essential would become a means of shielding theory from any test.

    The depth of an explanation is expressed in its capacity to reconstruct what is observable, its mediations, and its conditions of transformation.

    A methodological proposition of this essay

    06 Determinate negation and dialectical sublation

    The German verb aufheben combines the senses of abolishing and preserving that Hegel regards as philosophically decisive. What is sublated loses its immediate independence and is preserved as a moment of a transformed relation (Hegel, n.d.-a, §§ 184–187). The term requires specifying which determination ceases to hold, what is preserved, and within which new articulation it acquires meaning.

    Consider a hypothesis that interprets an increase in nominal wages as an improvement in purchasing power. Incorporating prices may show that the conclusion was incorrect. The wage datum is preserved, its sufficiency as a measure of purchasing power is negated, and its relationship to inflation is reconstructed. The initial information acquires a different place within a more determinate explanation.

    Real wage = nominal wage / price index

    For an index with a base of 100, use the index divided by 100 in the denominator.

    A nominal wage rising from 100 to 110 and a price index rising from 100 to 120 yield a real wage of 110/1.20 ≈ 91.67 in base-period units. The nominal increase of 10% coexists with an approximate decline of 8.33% in the real wage. The calculation illustrates reinterpretation through additional relations; it does not, by itself, demonstrate a universal philosophical logic.

    In inquiry, the sublation of an explanation may preserve results that remain valid under more restricted conditions. It may also require abandoning a premise. Its assessment requires argument and evidence: the mere succession of theories or combination of two positions does not constitute dialectical sublation.

    Determinate negation is incompatible with automatically discarding inconvenient facts. A discordant observation may reveal a measurement error, an omitted condition, an explicable exception, or a structural limit of the theory. Each possibility requires investigation. The category of appearance does not authorize making an interpretation immune to criticism.

    07 Universality, singularity, and parsimony

    7.1. Generalizing while preserving differences

    The universal, the particular, and the singular express relations of generality and determination. A law with a defined scope may be realized differently under particular conditions, and each singular case may reveal combinations that require refining that scope. The singular enters inquiry through evidence, comparison, and the testing of limits.

    The problem of universals is likewise not resolved by declaring concepts less real than things. A conceptual formulation has a different mode of existence from a machine or a property relation. It can adequately represent objective relations, prove mistaken, and exercise material effects by guiding practices. The epistemological question concerns its adequacy and justification; the ontological question requires identifying the kind of entity and relation being discussed.

    A critique of nominalism must address specific historical positions and be distinguished from a general critique of any use of names or classifications. Economy of assumptions, for its part, can be useful from different philosophical perspectives. Its use does not, by itself, establish that a scientific procedure belongs to a particular ontological school.

    7.2. Simplicity, fit, and explanation

    Parsimony counsels avoiding complexity that is unjustified relative to the purpose of a study. A compact model may be inadequate if it omits a relevant mechanism. A more extensive model may improve fit to observed data while impairing generalization. Moreover, predicting a response, identifying a causal effect, and explaining a historical formation are different tasks.

    A general modeling schema can be written as follows:

    J(M) = L(M; D) + λ C(M),   λ ≥ 0

    M: model; D: data; L: loss or lack of fit; C: complexity; λ: penalty weight. This is an illustrative schema, not a law of knowledge.

    The definition of each term depends on the problem. Counting coefficients can provide a measure of complexity, but constraints and regularization modify effective complexity. Nor is there a general equivalence between fewer coefficients and fewer variables: a categorical variable, a transformation, or an interaction may introduce several terms.

    Comparing explanations requires establishing what is held constant: available information, task, evaluation conditions, and scope. A compact formula may conceal strong assumptions; a more detailed representation may make them explicit. Simplicity must be assessed together with empirical adequacy, coherence, and the proposed mechanism.

    7.3. Transforming data while retaining the problem

    Logarithms can help stabilize increasing variance or express multiplicative relations when the conditions permit. Choosing a transformation requires knowledge of the process and diagnosis of the data; the adequacy of the resulting model must then be checked (National Institute of Standards and Technology [NIST], n.d.).

    If Y = exp(Xβ + ε) is proposed, taking logarithms gives log Y = Xβ + ε for positive responses. The variation under study now belongs to the logarithmic scale. Returning to the original scale requires attending to the estimation target, because exponentiating a mean on the logarithmic scale does not generally yield the original arithmetic mean.2

    The useful methodological analogy consists in making operations explicit and assessing what they preserve or modify. Transforming data does not automatically eliminate historical contingencies, nor does it demonstrate that the object follows a particular dialectical structure.

    08 Necessity, contingency, and transformation

    Explaining a process requires distinguishing what is necessary under established conditions from what can vary within them. A structural relation delimits possibilities and exerts pressures, but reconstructing an outcome requires considering mediations and actions. A historical result cannot simply be deduced from the identification of a contradiction.

    The oak example helps clarify the problem. An acorn contains material conditions for a possible biological development; germination requires specific circumstances and may fail. Continuity among seed, tree, and fruit must be investigated through organization, metabolism, reproduction, and environment. The future tree does not already exist fully realized within the seed.

    In social processes, agents’ purposes form part of causality: a policy may pursue a goal and produce consequences different from those intended. Identifying that purpose requires evidence about decisions and practices. Attributing a goal to the historical process as a whole is an additional thesis requiring independent justification.

    Metaphors of a spiral, center of gravitation, attractor, or fixed point can help formulate questions, but their technical meanings must be preserved. In a discrete system xt+1 = F(xt), a fixed point satisfies F(x*) = x*; its stability requires additional conditions. An attractor may be a more complex set and requires specifying both the dynamics and a notion of approach.

    The reproduction of a social relation does not, by itself, demonstrate the existence of a mathematical attractor. Establishing one would require constructing the state space, dynamic rules, and stability criterion, and assessing their adequacy. Without such a formalization, it is preferable to speak of reproduction, tendency, or relative stability, according to what the evidence supports.

    09 El Salvador, 2020–2022: hypotheses and mediations

    Tensions between the United States and El Salvador offer a useful case for examining the difference between recording events and explaining their articulation. The period considered runs from 2020 through March 21, 2022. The analysis uses information from that period and assesses hypotheses without using later outcomes as retrospective proof.

    9.1. Constructing the object and ordering the evidence

    “Diplomatic tension” requires observable indicators: official statements, changes in cooperation, sanctions, financial conditions, and shifts in institutional exchanges. These phenomena involve different actors and mechanisms. An IMF decision should not automatically be attributed to the U.S. government or confused with a bilateral diplomatic statement.

    Table 4. Milestones and the scope of the evidence
    DateEvent or documentAnalytical scope
    February 2020Security forces enter the Legislative Assembly during a conflict between the executive and legislative branches.An institutional antecedent within the period. Its reception and specific effects require study.3
    May 2, 2021Blinken expresses concern over the removal of judges and the attorney general the previous day.Documents a diplomatic objection preceding the Bitcoin Law (U.S. Department of State, 2021b).
    June 8–9, 2021Issuance and publication of Decree 57, the Bitcoin Law.Establishes the legislative decision and distinguishes it from implementation (Asamblea Legislativa de la República de El Salvador, 2021).
    September 5, 2021The United States challenges the presidential reelection ruling and judicial changes.Documents another front of institutional conflict (U.S. Department of State, 2021a).
    September 7, 2021Bitcoin begins to be used as legal tender alongside the U.S. dollar.Monetary coexistence prevents automatically equating the measure with de-dollarization (International Monetary Fund [IMF], 2022a).
    January 25, 2022The IMF publishes its Executive Board assessment and recommends removing Bitcoin’s legal tender status.Documents a conflict over monetary policy and financial risks (IMF, 2022b).

    The chronology establishes that documented diplomatic objections preceded the legislative decision on Bitcoin. This observation limits an explanation attributing the exclusive origin of all tensions to the cryptocurrency. It remains possible to investigate whether its adoption intensified existing conflicts or opened a specific front of financial negotiation.

    9.2. Comparing hypotheses and mechanisms

    Table 5. Hypothesis matrix
    HypothesisProposed mechanismWhat requires investigation
    Institutional conflictDecisions concerning the judiciary and checks on power alter cooperation and political interests.Connections among decisions, official responses, and actual changes in cooperation.
    Diplomatic realignmentA change in the U.S. administration modifies priorities and channels.Differences among agendas, decisions, and the continuity of commitments.
    Financial conflict over BitcoinMonetary policy opens disputes over risks, regulation, and financing.Negotiating conditions, technical documents, and the measure’s differentiated effects.
    Articulation of contradictionsPolitical and financial conflicts reinforce one another within preexisting dependencies.Temporal interactions, actors, decisions, and outcomes that an isolated cause cannot explain.

    Hypotheses can coexist and carry different weights depending on the outcome being explained. Identifying material interests requires reconstructing actors, resources, positions, and decisions. Expressions such as “Washington” or “international capital” can be useful shorthand, but they must be disaggregated when a concrete action is attributed.

    U.S. support for authoritarian regimes in other periods can ground a critique of the consistency of its discourse. To explain this episode, that critique must be connected to evidence about the relevant decision-making mechanisms. Selective application of a declared principle and its possible causal efficacy in a particular conjuncture are different questions. Assuming that an institution never acts for a reason because it disregarded that reason in other cases introduces a conclusion that historical comparison alone does not establish.

    9.3. Financial dependence and institutional influence

    The IMF’s January 2022 statement identifies financial, fiscal, and consumer-protection risks and recommends removing Bitcoin’s legal tender status. It is a primary source for the institution’s stated position. Assessing the sufficiency of those reasons requires additional studies; inferring an exclusively geopolitical intention likewise requires specific evidence (IMF, 2022b).

    U.S. influence within the IMF must be examined through quotas, votes, rules, and blocking power. The institutional handbook explains the effect of special 85% majorities and the U.S. capacity to block those decisions (Ramlogan & Fritz-Krockow, 2007, chap. 9). This position confers power, but it is not equivalent to exclusive ownership and does not establish a U.S. order behind every decision of the institution.

    Bitcoin’s legal tender status coexisted with that of the dollar during the period studied. The thesis of a break with the dollar system therefore requires additional indicators: actual payment use, contract denomination, saving, credit, reserves, and external financing. Legal innovation and a substantial change in monetary dependence are distinct outcomes that must be measured.

    9.4. What can be concluded

    The documentation examined identifies several fronts of tension and situates Bitcoin within a specific financial conflict. It does not establish that this conflict is the sole or fundamental cause of all bilateral tensions. The most productive materialist interpretation frames an inquiry into the relations among financial dependence, institutional reorganization, and political interests, specifying mechanisms and evidence that can discriminate among explanations.

    In this case, abstraction preserves relevant facts and reconstructs their relations. Declaring an institutional decision secondary requires specifying the outcome, period, and grounds of that judgment. Causal hierarchy is a revisable result of inquiry.

    10 Algebra and physics: the scope of analogies

    Interdisciplinary connections are fruitful when they respect the definitions of each domain. It is useful to distinguish analogy, which guides a comparison; formalization, which constructs a mathematical representation; and proof, which derives a conclusion from defined assumptions. A verbal coincidence between disciplines does not, by itself, establish any of these relations.

    10.1. Rings and ideals

    A ring has an additive abelian-group structure and an associative multiplication that distributes over addition; conventions concerning a multiplicative identity must be stated. A field is a commutative ring with an identity distinct from zero in which every nonzero element has a multiplicative inverse. A two-sided ideal I of a ring R must be an additive subgroup satisfying:

    ∀ r ∈ R, ∀ x ∈ I:   rx ∈ I   and   xr ∈ I.

    Absorption asserts membership in the ideal and does not imply the equality rx = xr. An example developed here is 2M2(ℤ), the set of 2-by-2 integer matrices with even entries, within M2(ℤ): evenness of the entries is preserved under multiplication by integer matrices, without imposing commutativity.

    10.2. Annihilators: two constructions

    For a left module M over a commutative ring R and a subset S ⊆ M, the annihilator is:

    AnnR(S) = {r ∈ R : rs = 0 for every s ∈ S}.

    The condition must hold for every element of S. For example, in the ℤ-module ℤ/6ℤ, the element 2̅ has annihilator 3ℤ, because 2r is divisible by 6 exactly when r is divisible by 3. This is an exact algebraic condition, independent of a philosophical interpretation of the word “annihilation.”

    In linear algebra, if W is a subspace of a vector space V over a field K, its annihilator in the dual is:

    W∘ = {φ ∈ V* : φ(w) = 0 for every w ∈ W}.

    If V = ℝ² and W is the horizontal axis, the functionals φ(x,y) = by form W∘. They retain information about the transverse direction while vanishing on W. This construction differs from the ideal of scalars annihilating elements of a module. Definitions of ideals and modules can be found in Altman and Kleiman (2013, chaps. 1 and 4).

    Unique factorization of ideals requires assumptions. In a Dedekind domain, every nonzero proper ideal factors uniquely, up to order, into nonzero prime ideals; this claim does not hold for an arbitrary ring (Altman & Kleiman, 2013, chaps. 24–25). Uniqueness is a property relative to a defined structure and operation. It does not, by itself, establish a unique historical genesis of the object.4

    10.3. Creation and annihilation operators

    For the quantum harmonic oscillator, with dimensionless operators and normalized states, the relevant relations are (Meunier, n.d., chap. 7):

    a|n⟩ = √n |n−1⟩,   n ≥ 1;   a|0⟩ = 0

    a†|n⟩ = √(n+1) |n+1⟩

    [a,a†] = aa† − a†a = 𝕀,   N = a†a

    𝕀 is the identity operator; N is the number operator; n = 0, 1, 2, …

    The commutator expresses the difference between two compositions of operators. Lowering by one quantum corresponds to the action of a on a state; the commutator’s result 𝕀 does not mean neutralization through the multiplicative identity. Moreover, a|0⟩ = 0 yields the zero vector, which must be distinguished from the vacuum state.

    In quantum field theory, operators describe excitations of modes, and interaction processes require a specific dynamical description. Electron–positron annihilation can yield photons, with energy, momentum, and charge conserved in the process (Tong, n.d., section 6). Photons are physical entities carrying energy and momentum; the process does not convert matter into an immaterial substance called energy.

    These examples let us ask what is preserved and what changes under precise operations. Comparison with dialectical sublation has heuristic value when its differences are delimited. Algebraic theorems and physical equations must be justified within their respective domains; their philosophical interpretation is a further task.

    Table 6. Related terms, distinct operations
    DomainOperation or relationWhat must be avoided
    ModulesScalars whose action yields zero on a set.Confusing the resulting zero with physical disappearance.
    Quantum operatorsActions on states and commutation relations.Identifying the commutator with particle–antiparticle annihilation.
    DialecticsDeterminate negation and transformed preservation.Presenting a terminological analogy as a universal proof.

    11 A research procedure

    The usefulness of these categories becomes apparent when they are translated into research decisions. The following procedure is an operational proposal that can be revised according to the object. Its tasks feed back into one another and accommodate qualitative, quantitative, and mixed methods when relevant.

    1. Delimit the process. Specify the object, unit of analysis, period, scale, and outcome to be explained. “The state,” “the economy,” and “artificial intelligence” require further determinations to become researchable objects.
    2. Build the empirical record. Identify documents, observations, measurements, and gaps. Distinguish data, actors’ claims, and the researcher’s inferences.
    3. Propose constitutive relations. Explain why certain relations would be necessary to the identity or reproduction of the process and which conditions allow them to operate.
    4. Compare mechanisms and hypotheses. Establish alternative explanations, interactions, and evidence capable of supporting or weakening them.
    5. Reconstruct mediations. Articulate institutions, practices, magnitudes, conflicts, and temporalities while preserving relevant differences.
    6. Return to the cases. Assess chronologies, counterexamples, variation across situations, and observable consequences.
    7. Revise the explanation. Specify its limits, modify categories, and document the uncertainties that remain.
    Table 7. Questions for critical assessment
    CriterionQuestion
    Object and scopeWhich process is explained, and within which conditions?
    ArticulationHow are the proposed relations connected, and through which mechanisms?
    ManifestationWhy do these relations produce or condition the observed phenomena?
    HistoryHow did the relations emerge, and what evidence permits reconstructing their change?
    ObjectionsWhich finding would require revising the explanation?
    PraxisWhat can the explanation guide, and which consequences of its use must be examined?

    Praxis connects knowledge and social intervention. In the Theses on Feuerbach, Marx places the question of truth in relation to practical activity (Marx, 2002, thesis II). This orientation requires investigating what is done, under which conditions, and with what results. The immediate success of an intervention may depend on mechanisms other than those assumed by its proponents; its analysis requires comparison and revision.

    Objectivity is a social task: making operations explicit, allowing criticism, and testing results independently of the political convenience of the conclusions. Class position and interests can influence the questions asked and the uses of knowledge. Identifying them allows those conditions to be examined; justifying a claim additionally requires relevant argument and evidence.

    12 Knowing essence to understand transformation

    A materialist theory of knowledge studies how a socially situated subject reconstructs relations within a reality that precedes it and of which it is part. Abstraction makes it possible to determine relations; synthesis articulates their mediations; returning to historical situations allows the explanation to be assessed and revised.

    Essence thus acquires a researchable content: constitutive relations, modes of reproduction, contradictions, and conditions of transformation. Knowledge of essence advances by explaining why a process manifests itself in certain ways, what it preserves through its variations, and under what circumstances it ceases to reproduce its identity.

    The link between essence and phenomenon requires preserving evidence; the relationship between logic and history requires explaining mediations and genesis; and the connection between theory and praxis exposes knowledge to material consequences that must themselves be interpreted critically. The strength of the method lies in sustaining these requirements throughout concrete research.

    Understanding a historical relation makes it possible to recognize both the conditions of its persistence and its possibilities of transformation. Such knowledge requires precise concepts, testable explanations, and a continuing readiness to revise what the analysis itself regards as fundamental.

    Notes

    1. The correspondences among Schein, Erscheinung, “appearance,” and “phenomenon” depend on the translation and passage. Nor are “form,” “existence,” “reality,” and “actuality” interchangeable. Interpreting a text requires reconstructing their contextual use. ↩

    2. If log Y = μ + ε and ε is normally distributed with mean zero and variance σ², then the conditional median of Y is exp(μ), whereas its conditional mean is exp(μ + σ²/2). This equality illustrates why retransformation depends on the distribution and estimation target. It is a result of the specified lognormal model. ↩

    3. The February 2020 event is an antecedent of the period’s institutional conflict. For its context and the subsequent evolution of that conflict, see the report by Seelke (2021). Reconstructing specific effects requires identifying actions and responses, alongside preserving the event’s date. ↩

    4. Over an integral domain, a finitely generated torsion module has a nonzero annihilator: if rᵢ ≠ 0 annihilates the generator mᵢ, the finite product of the rᵢ is nonzero and annihilates the entire module. “Finitely generated” must be distinguished from “finite” as a set. The assumptions are decisive; a torsion module without finite generation may have a zero annihilator, as does ℚ/ℤ over ℤ. ↩

    References

    Citations refer to chapters, sections, or numbered paragraphs when a digital edition has no stable pagination. Source titles are retained in their language of publication, with English translations supplied for titles in Spanish. Conceptual formulations and examples identified as developed here form part of the essay’s argument.

    Altman, A., & Kleiman, S. (2013). A term of commutative algebra. Worldwide Center of Mathematics. https://web.mit.edu/18.705/www/13Ed-2up.pdf

    Asamblea Legislativa de la República de El Salvador. (2021, June 8). Ley Bitcoin [Bitcoin Law] (Legislative Decree No. 57). Diario Oficial, 110, vol. 431, June 9, 2021. https://www.asamblea.gob.sv/leyes-y-decretos/view/4530

    Dussel, E. (2010). La producción teórica de Marx: Un comentario a los Grundrisse [Marx’s theoretical production: A commentary on the Grundrisse]. Fundación Editorial El perro y la rana. Full text

    Engels, F. (1890, September 21). Engels to J. Bloch [Letter]. Marxists Internet Archive. https://www.marxists.org/archive/marx/works/1890/letters/90_09_21.htm

    Hegel, G. W. F. (n.d.-a). Science of logic: Book one. The doctrine of being. Marxists Internet Archive. https://www.marxists.org/reference/archive/hegel/works/hl/hlbeing.htm

    Hegel, G. W. F. (n.d.-b). Science of logic: Book two. The doctrine of essence. Marxists Internet Archive. https://www.marxists.org/reference/archive/hegel/works/hl/hlessenc.htm

    International Monetary Fund. (2022a). El Salvador: Staff report for the 2021 Article IV consultation—Informational annex. IMF Country Report, 22/20. Informational annex

    International Monetary Fund. (2022b, January 25). IMF Executive Board concludes 2021 Article IV consultation with El Salvador (Press Release No. 22/13). Official statement

    Marx, K. (1867). Capital: Volume I. Chapter 1. Commodities. Marxists Internet Archive. Digital chapter text

    Marx, K. (1894). Capital: Volume III. Chapter 9. Formation of a general rate of profit (average rate of profit) and transformation of the values of commodities into prices of production. Marxists Internet Archive. Digital chapter text

    Marx, K. (1973). Introduction. In Grundrisse: Foundations of the critique of political economy (rough draft) (M. Nicolaus, Trans.). Penguin Books; New Left Review. Digital introduction text. (Original manuscript written in 1857).

    Marx, K. (2002). Theses on Feuerbach (C. Smith, Trans.). Marxists Internet Archive. https://www.marxists.org/archive/marx/works/1845/theses/index.htm. (Original manuscript written in 1845).

    Meunier, V. (n.d.). Chapter 7: The linear harmonic oscillator. In Introduction to quantum mechanics, self guided course. Pennsylvania State University. https://sites.esm.psu.edu/~vfm5153/IQM/chapter7.html

    National Institute of Standards and Technology. (n.d.). Accounting for non-constant variation across the data. In NIST/SEMATECH e-Handbook of statistical methods (section 4.4.5.2). https://www.itl.nist.gov/div898/handbook/pmd/section4/pmd452.htm

    Ramlogan, P., & Fritz-Krockow, B. (2007). International Monetary Fund handbook: Its functions, policies, and operations. International Monetary Fund. Chapter 9: Governance and decision-making

    Rosental, M. (1961). Los problemas de la dialéctica en “El Capital” de Marx [Problems of dialectics in Marx’s Capital]. Ediciones Pueblos Unidos.

    Rosental, M. M., & Iudin, P. F. (1971). Diccionario filosófico [Philosophical dictionary]. Tecolut. Digital text

    Seelke, C. R. (2021, December 23). El Salvador: Authoritarian actions and U.S. response (IN11658). Congressional Research Service. https://www.congress.gov/crs-product/IN11658

    Tong, D. (n.d.). Quantum field theory [Lecture notes]. University of Cambridge. Section 6: Quantum electrodynamics

    U.S. Department of State. (2021a, September 5). Salvadoran re-election ruling undermines democracy. Archived official statement

    U.S. Department of State. (2021b, May 2). Secretary Blinken’s call with Salvadoran President Bukele. Archived official communication

    Zubiri, X. (1985). Sobre la esencia [On essence] (5th ed.). Alianza Editorial. (Original work published in 1962).

  • QUALITATIVE PREDICTORS AND INTERACTIONS IN R: APPLICATIONS FOR THE INSURANCE MARKET AND STRENGTH OF MATERIALS

    QUALITATIVE PREDICTORS AND INTERACTIONS IN R: APPLICATIONS FOR THE INSURANCE MARKET AND STRENGTH OF MATERIALS

    Marxist Philosophy of Science
    Mathematical statistics · Regression · Experimental design

    Qualitative Predictors and Interactions in R

    Insurance, textile strength, and the geometry of comparisons
    JOSÉ MAURICIO GÓMEZ JULIÁN
    Originally published: December 2, 2021
    Comprehensively revised: November 4, 2026

    01 · What changes when a predictor is qualitative

    An insurance company may be mutual or stock-owned; a fiber may be manufactured with different cotton percentages. These differences enter statistical analysis through decisions about what to compare and which relationships to allow. Coding categories represents those decisions: which group supplies the reference, whether slopes must coincide, and whether the relationship between a quantity and the response depends on group membership.

    The discussion connects two applications. Insurance data link time to innovation adoption with firm assets and ownership form. Materials data compare tensile strength across five textile compositions. Both cases connect regression, analysis of covariance, and analysis of variance within the general linear model. A model is linear in its parameters; it may contain products of predictors or powers of a variable.

    02 · Insurance: question, units, and complete data

    Let Y be the elapsed number of months until innovation adoption and X the insurer’s size, measured by assets in millions of dollars. Ownership distinguishes mutual and stock companies. Fewer months indicate faster adoption; because the analyzed response is time, a negative coefficient means a shorter expected waiting time. These teaching data come from the example in Kutner, Nachtsheim, Neter, and Li (2005, pp. 313–318), reproduced in the author’s paper [1–2].

    The observational unit is the firm: there are 20 companies, 10 of each type. Recording three attributes does not multiply sample size. Innovation, competition, and profitability provide the economic motivation, while these data support the study of conditional associations. A diffusion mechanism between firms would require temporal or network information, and a causal effect would require additional design and identification assumptions.

    Insurance data dictionary
    Symbol / codeDefinitionUnit / levels
    Y / monthsTime to adoptionMonths
    X / assetsFirm assetsMillion dollars
    typeOwnership formMutual / Stock
    DIndicator for stock company0 = mutual; 1 = stock
    The 20 observations used in every insurance fit
    FirmMonthsAssetsTypeD
    117151Mutual0
    22692Mutual0
    321175Mutual0
    43031Mutual0
    522104Mutual0
    60277Mutual0
    712210Mutual0
    819120Mutual0
    94290Mutual0
    1016238Mutual0
    1128164Stock1
    1215272Stock1
    1311295Stock1
    143868Stock1
    153185Stock1
    1621224Stock1
    1720166Stock1
    1813305Stock1
    1930124Stock1
    2014246Stock1

    The zero-month observation is retained. Its operational meaning—immediate adoption, rounding, or another measurement convention—matters in an actual application. The response is not log-transformed, and no arbitrary constant is added to accommodate zero.

    insurance <- data.frame(
      id = 1:20,
      months = c(17,26,21,30,22,0,12,19,4,16,
                 28,15,11,38,31,21,20,13,30,14),
      assets = c(151,92,175,31,104,277,210,120,290,238,
                 164,272,295,68,85,224,166,305,124,246),
      type = factor(rep(c("Mutual", "Stock"), each = 10),
                    levels = c("Mutual", "Stock"))
    )
    contrasts(insurance$type) <- contr.treatment(levels(insurance$type), base = 1)
    stopifnot(nrow(insurance) == 20L, !anyNA(insurance),
              all(table(insurance$type) == 10L))
    insurance$D <- as.integer(insurance$type == "Stock")

    03 · Indicator functions, factors, and the design matrix

    Di = 𝟙{typei = Stock}
    D(Stock) = 1;  D(Mutual) = 0

    An indicator assigns 1 when a condition holds and 0 otherwise. Zero represents non-membership in the indicated group and remains a valid datum. NA denotes a missing value and NULL a null R object: they are not interchangeable. Factor labels are categories; internal integer codes implement storage. The design matrix contains the columns actually used to fit the model [3–4].

    Yi = β0 + β1Xi + β2Di + εi;  xiT = [1, Xi, Di]

    With an intercept and treatment coding, a factor with c observed levels contributes c − 1 columns. Including both an intercept and all c indicators produces an exact dependency because the indicators sum to the column of ones. With two groups, 1 = DMutual + DStock. This concerns independent columns, rather than a general prohibition on including multiple binary variables.

    With a full-rank matrix, least-squares coefficients are uniquely identifiable. Under rank deficiency, multiple coefficient vectors may generate the same fitted values: projection onto the column space remains unique. Identification must be assessed in the complete matrix; absent categories or redundant combinations may also cause problems. lm() uses QR decomposition and allows inspection of rank and non-estimable coefficients [5].

    contrasts(insurance$type)
    X <- model.matrix(~ assets + type, data = insurance)
    head(X)
    stopifnot(qr(X)$rank == ncol(X))
    X_bad <- with(insurance, cbind(Intercept = 1,
      Mutual = as.integer(type == "Mutual"), Stock = D))
    c(columns = ncol(X_bad), rank = qr(X_bad)$rank)

    04 · Assumptions: estimation, inference, and design

    The model specifies a conditional mean, E(Y | X, D), with E(ε | X, D) = 0. Classical Gauss–Markov results require full rank and conditional covariance matrix σ²I: constant variance and uncorrelated errors. Conditional normality of errors provides exact finite-sample distributions for classical t and F tests and intervals. Neither the predictors nor the marginal response must be normally distributed.

    Companies may share markets, shocks, or ownership links. Such possibilities require substantive information about data collection; a residual plot cannot establish independence. In the textile case, run order, randomization, batches, and machines affect interpretation of the error term. A good numerical fit does not replace a description of the design.

    05 · Additive model: differences between parallel lines

    E(Y | X, D) = β0 + β1X + β2D

    For mutual companies, D = 0 and the mean is β0 + β1X. For stock companies, D = 1 and it is (β0 + β2) + β1X. The common slope is a testable restriction; the shift β2 compares ownership groups at the same size. This is also a form of analysis of covariance: comparing groups while adjusting for a continuous covariate.

    m_size <- lm(months ~ assets, data = insurance)
    m_add <- lm(months ~ assets + type, data = insurance)
    summary(m_add)
    confint(m_add)
    anova(m_size, m_add)
    c(n = nobs(m_add), rank = m_add$rank, df = df.residual(m_add),
      SSE = deviance(m_add), MSE = sigma(m_add)^2,
      residual_SD = sigma(m_add), R_squared = summary(m_add)$r.squared)
    Additive-model estimates; classical inference
    TermEstimateStandard error95% CIp
    Intercept / β₀33.8740691.813858[30.047163, 37.700976]9.145e-13
    Assets / β₁-0.1017420.008891[-0.120501, -0.082983]2.075e-09
    Stock − Mutual / β₂8.0554691.459106[4.977025, 11.133913]3.742e-05
    ŶMutual = 33.874069 − 0.101742X
    ŶStock = 41.929538 − 0.101742X

    An additional million dollars in assets is associated with 0.1017 fewer months to adoption, holding ownership type fixed. An increase of 100 million corresponds to 10.1742 fewer months within the linear approximation. At the same size, stock companies have an estimated mean adoption time 8.0555 months longer than mutual companies; the 95% interval for that difference is 4.9770 to 11.1339 months. The intercept refers to X = 0, outside the observed asset range, so it primarily serves as a geometric parameter.

    The fit gives SSE = 176.386665, MSE = 10.375686 months², residual standard deviation s = 3.221131 months, and R² = 0.895058. R² summarizes explained variation within this sample; it measures neither causality nor out-of-sample predictive performance. Intervals are two-sided 95% intervals, and p-values use the classical assumptions stated above.

    06 · Interaction: allowing slopes to differ

    E(Y | X, D) = β0 + β1X + β2D + β3XD

    The product XD allows the size–time association to depend on ownership type. The mutual-company slope is β1; the stock-company slope is β1 + β3. Thus β3 estimates the difference in slopes. Retaining X and D alongside XD respects model hierarchy and interprets the interaction in a complete parameterization. The expression assets * type expands the two main terms and their interaction [5].

    m_int <- lm(months ~ assets * type, data = insurance)
    summary(m_int)
    confint(m_int)
    anova(m_add, m_int)
    linear_contrast <- function(model, L, level = 0.95) {
      stopifnot(length(L) == length(coef(model)), !anyNA(coef(model)))
      estimate <- drop(L %*% coef(model))
      se <- sqrt(drop(L %*% vcov(model) %*% L))
      q <- qt(1 - (1 - level)/2, df.residual(model))
      c(estimate = estimate, SE = se,
        lower = estimate - q * se, upper = estimate + q * se)
    }
    linear_contrast(m_int, c(0, 0, 1, 150))
    ŶMutual = 33.838369 − 0.101531X
    ŶStock = 41.969620 − 0.101948X

    The estimated slope difference is −0.000417 months per million dollars; its 95% CI is [−0.039278, 0.038443]. Testing H₀: β3 = 0 gives F(1,16) = 0.000518 and p = 0.982126. These data provide very little evidence against a common slope. The interval also conveys uncertainty: a large p-value does not establish exact equivalence of slopes.

    image/svg+xml Matplotlib v3.10.8, https://matplotlib.org/ 50 100 150 200 250 300 Assets (million dollars) 0 5 10 15 20 25 30 35 Months to adoption Common slope Mutual Stock 50 100 150 200 250 300 Assets (million dollars) Months to adoption Group-specific slopes Mutual Stock
    Figure 1. Points are the 20 original records. Left: additive model; right: interaction model. Each line is drawn within the asset range observed for its group. Separately estimated slopes are nearly identical.

    07 · Changing the reference and centering assets

    Changing the reference group changes the coordinates of the representation. In the additive model with stock companies as the reference, the intercept becomes 41.929538 and the mutual-company coefficient becomes −8.055469; the slope remains −0.101742. Fitted values, residuals, SSE, and R² stay the same because the column space is unchanged. relevel() reorders levels; under treatment coding the first is the reference.

    With interaction, the group coefficient compares companies at X = 0. It is more useful to center assets at 150 million, a value within both groups’ observed ranges. Defining Xc = X − 150 makes the group coefficient compare firms of that size and the intercept estimate the corresponding mutual-company mean time. Centering does not change the fitted curve.

    Δ(X) = E(Y | X, D = 1) − E(Y | X, D = 0) = β2 + β3X

    In the original-response interaction model, Δ(150) = 8.068679 months, with 95% CI [4.651119, 11.486239]. Its variance combines the variances of β̂2 and β̂3 and their covariance. Adding their standard errors is insufficient. In general, for contrast vector L, the standard error is √(Lᵀ V̂ L), where V̂ is the coefficient covariance matrix.

    insurance$stock_ref <- relevel(insurance$type, ref = "Stock")
    contrasts(insurance$stock_ref) <- contr.treatment(
      levels(insurance$stock_ref), base = 1)
    m_ref <- lm(months ~ assets + stock_ref, data = insurance)
    insurance$assets_c <- insurance$assets - 150
    m_center <- lm(months ~ assets_c * type, data = insurance)
    coef(m_ref)
    coef(m_center)
    stopifnot(isTRUE(all.equal(unname(fitted(m_add)),
                              unname(fitted(m_ref)), tolerance = 1e-10)),
              isTRUE(all.equal(unname(fitted(m_int)),
                              unname(fitted(m_center)), tolerance = 1e-10)))

    08 · A teaching modification that makes interaction visible

    To see what happens when slopes change, define a response constructed from the original. The modification adds 0.05 months per million dollars of assets only to mutual companies. This is a deliberate teaching operation on the data; it adds no firms and does not represent another empirical study.

    Y* = Y + 0.05X(1 − D)
    β*0 = β0;  β*1 = β1 + 0.05;  β*2 = β2;  β*3 = β3 − 0.05

    Because D identifies stock companies, 1 − D identifies mutual companies. The value 0.05 has units of months per million dollars. It is neither a probability, a sampling weight, nor the proportion of mutual firms. In R, == compares values and returns a logical result; as.integer() explicitly converts it to 0 or 1.

    # Deliberately modified response: a teaching exercise, not new observations.
    insurance$months_demo <- with(insurance,
      months + 0.05 * assets * as.integer(type == "Mutual"))
    m_demo_add <- lm(months_demo ~ assets + type, data = insurance)
    m_demo_int <- lm(months_demo ~ assets * type, data = insurance)
    coef(m_demo_int)
    anova(m_demo_add, m_demo_int)
    linear_contrast(m_demo_int, c(0, 0, 1, 150))
    stopifnot(isTRUE(all.equal(unname(residuals(m_int)),
                              unname(residuals(m_demo_int)), tolerance = 1e-10)))
    Two different responses for the same 20 firms
    ScenarioMutual slopeStock slopeSlope differenceInteraction p
    Original response−0.101531−0.101948−0.0004170.982126
    Teaching response−0.051531−0.101948−0.0504170.014224

    Comparing the additive and interaction models for Y* gives F(1,16) = 7.564391 and p = 0.014224. The slope difference is detected in the scenario we just constructed. The fitted lines are Ŷ*Mutual = 33.838369 − 0.051531X and Ŷ*Stock = 41.969620 − 0.101948X. Their estimated crossing is around 161.28 million dollars: a property of this exercise, not a causally identified economic threshold.

    An instructive algebraic consequence follows. The added term lies in the full model’s column space, so some coefficients change while the full-model residuals remain identical to those from the original response. R² may change because the new response’s total variation also changes. Comparing R² between Y and Y* does not evaluate two models for the same response.

    image/svg+xml Matplotlib v3.10.8, https://matplotlib.org/ 50 100 150 200 250 300 Assets (million dollars) 10 15 20 25 30 35 Months to adoption Deliberately modified response Mutual Stock
    Figure 2. The mutual-company response increases by 0.05X. Slopes now visibly differ and the lines cross. Symbols distinguish groups without relying on color.
    image/svg+xml Matplotlib v3.10.8, https://matplotlib.org/ 100 150 200 250 300 Assets −10 −5 0 5 10 Difference: stock − mutual (months) Original data 100 150 200 250 300 Assets Teaching exercise
    Figure 3. Stock minus mutual by assets, within the overlapping range of 68–290 million. Shaded areas show pointwise 95% CIs, not a simultaneous band. At 150 million the contrast changes from 8.0687 to 0.5687 months; in the second scenario, the interval [−2.8489, 3.9862] includes zero.

    09 · Separate fits, degrees of freedom, and model comparison

    Fitting one line per group gives the same group-line coefficients and fitted values as the joint model with full interaction, provided the same records and unweighted least squares are used. Inference may differ: the classical joint fit estimates a common residual variance, while each separate regression estimates its own variance.

    group_models <- lapply(levels(insurance$type), function(g)
      lm(months ~ assets, data = insurance, subset = type == g))
    names(group_models) <- levels(insurance$type)
    sapply(group_models, coef)
    sapply(group_models, sigma)
    group_fit <- numeric(nrow(insurance))
    for (g in names(group_models)) {
      k <- insurance$type == g
      group_fit[k] <- predict(group_models[[g]], newdata = insurance[k, ])
    }
    stopifnot(max(abs(group_fit - fitted(m_int))) < 1e-8)
    SSE = Σ ei²;  glres / dfres = n − rank(X)
    MSE = SSE / dfres;  s = √MSE
    Dispersion and restrictions for the original response
    FitnParameters / rankResidual dfSSEs
    Original additive20317176.3866653.221131
    Original interaction20416176.3809573.320212
    Separate mutual1028111.0844073.726332
    Separate stock102865.2965502.856933

    Adding an independent column cannot increase SSE for the same sample and response. However, MSE and s may increase because residual degrees of freedom decrease. Here, adding interaction reduces SSE only minimally and increases s. The full model’s pooled variance is an average of group variances weighted by their residual degrees of freedom; it need not be smaller than both.

    F = [(SSER − SSEF) / (pF − pR)] / [SSEF / (n − pF)]

    R denotes the restricted model and F the full model; p is each design matrix’s rank. The numerator measures the average cost of imposing restrictions, and the denominator estimates the full model’s residual variance. With one restriction, F equals the corresponding coefficient’s squared t statistic. Comparison requires nested models, the same response, and the same records. anova(m_add, m_int) tests slopes; anova(m_int) produces a sequential decomposition that may depend on term order [6].

    10 · Diagnostics: residuals, leverage, and influence

    A residual ei = yi − ŷi measures vertical discrepancy from the fit. Leverage hii depends on predictors and the design matrix. Influence evaluates how much the fit changes when an observation is removed. A firm with extreme assets may have high leverage and a small residual; another may have a large residual with moderate leverage. Neither characteristic alone determines overall influence.

    H = X(XᵀX)−1Xᵀ;  ŷ = Hy;  ∂ŷi/∂yi = hii
    ri = ei / [s√(1 − hii)]
    Cooki = [ei² / (p s²)] · [hii / (1 − hii)²]

    These expressions assume full-rank least squares, p parameters, and estimable residual variance. Under homoscedasticity, Var(e | X) = σ²(I − H): raw residuals do not all have equal variance and are not independent, even when the errors satisfy the model. Standardization accounts for this geometric effect. rstudent() uses a dispersion estimate that excludes the observation being evaluated [7–8].

    Read each diagnostic according to its purpose
    PlotQuestion it addresses
    Residuals / fittedIs systematic mean structure left over?
    Normal Q–QIs residual shape compatible with normality?
    Scale–LocationDoes spread change with the fitted level?
    Residuals / leverageDo discrepancy and leverage combine?
    image/svg+xml Matplotlib v3.10.8, https://matplotlib.org/ 5 10 15 20 25 30 35 Fitted −6 −4 −2 0 2 4 6 Residual Residuals / fitted −2 −1 0 1 2 Theoretical quantiles −2.0 −1.5 −1.0 −0.5 0.0 0.5 1.0 1.5 2.0 Standardized residual Q–Q normal 5 10 15 20 25 30 35 Fitted 0.4 0.6 0.8 1.0 1.2 1.4 √|r| Scale / location 0.05 0.10 0.15 0.20 0.25 0.30 hᵢᵢ −3 −2 −1 0 1 2 3 Standardized residual 6 10 17 0.2 0.5 Residuals / leverage
    Figure 4. Diagnostics computed for the original additive model. The lower-right panel labels firms 6, 10, and 17; contours illustrate Cook distances of 0.2 and 0.5. Plots explore compatibility and sensitivity without certifying assumptions.
    Five largest Cook distances in the additive fit
    FirmResidualStandardized residualhᵢᵢCook
    6-5.6915-1.96230.18920.2995
    106.34062.11830.13650.2364
    17-5.0403-1.65530.10640.1087
    142.98891.05250.22270.1058
    34.93081.61380.10030.0968

    Firms 6 and 10 have Cook distances of about 0.2995 and 0.2364. The heuristic 4/n = 0.20 flags them for investigation; the threshold 2p/n = 0.30 flags no extreme leverage in this fit. These are exploratory rules, not tests or instructions to delete data. The largest Cook distance is below 0.5, which does not remove the need to examine measurement, provenance, and sensitivity of conclusions.

    diagnostics <- data.frame(id = insurance$id,
      residual = residuals(m_add), standardized = rstandard(m_add),
      studentized = rstudent(m_add), leverage = hatvalues(m_add),
      Cook = cooks.distance(m_add))
    diagnostics[order(diagnostics$Cook, decreasing = TRUE), ]
    influence.measures(m_add)
    hc3_vcov <- function(model) {
      Z <- model.matrix(model)
      stopifnot(qr(Z)$rank == ncol(Z))
      bread <- solve(crossprod(Z))
      u <- residuals(model)/(1 - hatvalues(model))
      bread %*% crossprod(Z, Z * as.vector(u^2)) %*% bread
    }
    cbind(estimate = coef(m_add), classical_SE = sqrt(diag(vcov(m_add))),
          HC3_SE = sqrt(diag(hc3_vcov(m_add))))
    # Sensitivity analysis: retain the original fit as the main analysis.
    sensitivity <- lapply(c(6L, 10L), function(k)
      coef(lm(months ~ assets + type, data = insurance,
              subset = id != k)))
    names(sensitivity) <- c("omit_6", "omit_10")
    sensitivity

    The laboratory adds HC3 standard errors as a heteroscedasticity sensitivity analysis. It computes (XᵀX)⁻¹ Xᵀ diag[eᵢ²/(1 − hᵢᵢ)²] X (XᵀX)⁻¹. OLS coefficients remain unchanged; their estimated covariance changes. HC3 does not repair a misspecified mean, causal confounding, or dependence between firms. With 20 observations, robust inference still requires care about small-sample approximation.

    Sensitivity of additive-model standard errors
    TermClassical SEHC3 SE
    Intercept1.8138581.311688
    Assets0.0088910.009051
    Stock − Mutual1.4591061.699138

    11 · A minimal sensitivity experiment

    Consider six points on y = x, with x = (1, 2, 3, 4, 5, 20). Increase y by four units first at x = 3 and then at x = 20, leaving the other observations unchanged. Perturbation size is identical; the point’s position in the design differs. The x = 20 point has leverage 0.9668, whereas x = 3 has leverage 0.1987.

    toy <- data.frame(x = c(1,2,3,4,5,20), y = c(1,2,3,4,5,20))
    toy$y_near <- toy$y
    toy$y_far <- toy$y
    toy$y_near[3] <- toy$y_near[3] + 4
    toy$y_far[6] <- toy$y_far[6] + 4
    toy_base <- lm(y ~ x, data = toy)
    toy_near <- lm(y_near ~ x, data = toy)
    toy_far <- lm(y_far ~ x, data = toy)
    data.frame(x = toy$x, leverage = hatvalues(toy_base))
    rbind(original = coef(toy_base), near = coef(toy_near), far = coef(toy_far))
    # The exact baseline has SSE=0: do not interpret Cook's D for that fit.
    image/svg+xml Matplotlib v3.10.8, https://matplotlib.org/ 0 5 10 15 20 x 0 5 10 15 20 25 y Base Change at x = 3 Change at x = 20
    Figure 5. Equal vertical perturbations at different positions. Changing the distant point alters the slope more. The baseline fit is exact, with SSE = 0: its Cook distance should not be interpreted using zero residual variance.

    The example demonstrates a geometric property of least squares. The distant point is not automatically invalid: it may be a valuable observation extending the study range. Applied assessment combines geometry, discrepancy, record quality, and knowledge of the process.

    12 · Prediction and uncertainty for a firm

    A conditional mean and a future observation have different uncertainties. For a design row x₀, a mean confidence interval uses s√[x₀ᵀ(XᵀX)⁻¹x₀]. An individual prediction interval uses s√[1 + x₀ᵀ(XᵀX)⁻¹x₀]: it adds variation of a new response around its mean. Both use the appropriate t quantile under the classical assumptions [9].

    new_firms <- data.frame(assets = rep(150, 2),
      type = factor(c("Mutual", "Stock"), levels = levels(insurance$type)))
    predict(m_add, newdata = new_firms, interval = "confidence")
    predict(m_add, newdata = new_firms, interval = "prediction")
    Firms with 150 million dollars in assets; times in months; additive model
    TypeEstimated mean95% mean CI95% individual PI
    Mutual18.6128[16.4349, 20.7906][11.4763, 25.7492]
    Stock26.6682[24.3600, 28.9765][19.4909, 33.8455]

    Observed assets range from 31 to 290 million for mutual companies and from 68 to 305 million for stock companies. Between-group comparisons have common support from 68 to 290 million. Far extrapolations may yield negative times, revealing a limitation of this approximation to a nonnegative duration. Censoring, unobserved adoption events, or strong asymmetry motivate duration models; a Gamma distribution with log link requires strictly positive responses and does not directly accommodate the zero observed here.

    13 · Materials: fiber composition and tensile strength

    The second case studies fibers in a blend containing cotton. The predictor is cotton percentage by weight: 15, 20, 25, 30, and 35%, with five strength measurements per level. The physical variable is quantitative; it can be represented as a factor when the aim is to estimate an unrestricted mean for each tested level. The data and their interpretation are verified against Penn State’s teaching example on textile strength [10].

    Complete data: five levels and 25 strength measurements
    Cotton (%)Strength observations (lb/in²)nMean
    157, 7, 15, 11, 959.8
    2012, 17, 12, 18, 18515.4
    2514, 18, 18, 19, 19517.6
    3019, 25, 22, 19, 23521.6
    357, 10, 11, 15, 11510.8

    The experimental unit is the fiber or material unit assigned a composition; a causal interpretation of treatment differences requires randomized execution, independent replicates, and control of other conditions. Five readings on one specimen would not equal five independent replicates. The identifier treatment denotes composition levels, rather than presupposing five different mechanical test types.

    cotton <- data.frame(
      percent = rep(c(15,20,25,30,35), each = 5),
      strength = c(7,7,15,11,9, 12,17,12,18,18,
                   14,18,18,19,19, 19,25,22,19,23, 7,10,11,15,11)
    )
    cotton$treatment <- factor(cotton$percent, levels = c(15,20,25,30,35))
    contrasts(cotton$treatment) <- contr.treatment(
      levels(cotton$treatment), base = 1)
    stopifnot(nrow(cotton) == 25L, !anyNA(cotton))
    aggregate(strength ~ treatment, data = cotton, FUN = mean)
    # Safe conversion of numeric-looking labels, not the internal factor codes:
    stopifnot(identical(as.numeric(as.character(cotton$treatment)),
                        cotton$percent))

    To recover numerical values from labels such as “15” and “20”, use as.numeric(as.character(factor)). Applying as.numeric() directly to the factor returns internal codes 1, 2, 3, 4, and 5. A factor represents one categorical variable with multiple levels; it needs no second variable in order to be created. Explicit coercion can convert numeric text to numbers, while unparseable strings produce missing values with a warning [4].

    14 · Five means, four indicators, and one fit

    Yij = μj + εij,  j = 1, …, 5;  i = 1, …, 5
    Y = α + δ20D20 + δ25D25 + δ30D30 + δ35D35 + ε

    The first form assigns a separate mean to each level. In the second, 15% is the reference: α = μ15 and δj = μj − μ15. Estimated coefficients are α̂ = 9.8, δ̂20 = 5.6, δ̂25 = 7.8, δ̂30 = 11.8, and δ̂35 = 1.0. Reconstruct a mean by adding the intercept and its corresponding difference; for example, μ̂30 = 9.8 + 11.8 = 21.6.

    Design rows: each pattern occurs five times
    LevelInterceptD₂₀D₂₅D₃₀D₃₅
    1510000
    2011000
    2510100
    3010010
    3510001

    The factor, four manual indicators, and five indicators without an intercept generate the same fitting space. They therefore yield the same fitted values, residuals, SSE, and R²; the last parameterization estimates the five means directly. The word class can denote a group here without imposing countability or a universal hierarchy. An indicator vector represents group membership; it does not create a new ontological class of observations.

    m_factor <- lm(strength ~ treatment, data = cotton)
    m_cell <- lm(strength ~ 0 + treatment, data = cotton)
    cotton$D20 <- as.integer(cotton$treatment == "20")
    cotton$D25 <- as.integer(cotton$treatment == "25")
    cotton$D30 <- as.integer(cotton$treatment == "30")
    cotton$D35 <- as.integer(cotton$treatment == "35")
    m_manual <- lm(strength ~ D20 + D25 + D30 + D35, data = cotton)
    m_linear <- lm(strength ~ percent, data = cotton)
    m_quadratic <- lm(strength ~ percent + I(percent^2), data = cotton)
    summary(m_factor)
    anova(m_factor)
    confint(m_factor)
    coef(m_cell)
    anova(m_linear, m_factor)       # linear lack of fit: 3 restrictions
    anova(m_quadratic, m_factor)    # quadratic lack of fit: 2 restrictions
    stopifnot(max(abs(fitted(m_factor) - fitted(m_manual))) < 1e-10,
              max(abs(fitted(m_factor) - fitted(m_cell))) < 1e-10)

    15 · ANOVA: partitioning variation to compare means

    SST = ΣjΣi(yij − ȳ)²
    SSB = Σj nj(ȳj − ȳ)²;  SSE = ΣjΣi(yij − ȳj)²
    SST = SSB + SSE;  F = [SSB / (c − 1)] / [SSE / (n − c)]

    SST measures variation around the overall mean; SSB captures differences between composition means; SSE captures variation within each composition. Under H₀: μ15 = μ20 = μ25 = μ30 = μ35, both mean squares estimate the same variance. Their ratio is compared with F(4,20) under the classical assumptions. Although the method analyzes variances, its central question concerns equality of population means.

    ANOVA of strength by cotton percentage
    SourceSum of squaresdfMean squareFp
    Composition475.764118.9414.7568249.128e−6
    Error161.20208.06——
    Total636.9624———

    The test rejects global equality of means at the 0.05 level. Residual standard deviation is √8.06 = 2.839014 lb/in² and R² = 0.746923. In this one-factor design, η² = SSB/SST = 0.746923 equals R² as a description of the sample. It is neither a percentage of a demonstrated causal mechanism nor a removal of estimation uncertainty.

    image/svg+xml Matplotlib v3.10.8, https://matplotlib.org/ 15 20 25 30 35 Cotton content (%) 7.5 10.0 12.5 15.0 17.5 20.0 22.5 25.0 Tensile strength (lb/in²) Mean and pointwise 95% CI
    Figure 6. All data, group means, and pointwise 95% intervals using the pooled ANOVA variance. Each mean has margin 2.648434 lb/in². Replicates are slightly separated horizontally to reveal overlapping observations.

    The largest observed mean occurs at 30% cotton. Claiming that it exceeds another level requires a comparison with uncertainty and attention to the number of comparisons performed. A significant global test does not establish a difference for every pair.

    16 · Percentage as a number or factor: different restrictions

    A straight line treats percentage increases as changes governed by a common slope. A quadratic admits curvature while remaining linear in its coefficients. The factor model permits five means without specifying a continuous shape between levels. The choice depends on the scientific question and whether the restrictions describe the data.

    E(Y | x) = a + bx
    E(Y | x) = a + bx + cx²
    E(Y | level = j) = μj
    Same response and same 25 observations
    ModelRankSSER²Lack-of-fit F vs. factorp
    Linear2603.3400000.05278218.285360 (3,20)5.967e−6
    Quadratic3260.1257140.5916146.136831 (2,20)0.008353
    Factor5161.2000000.746923——

    Five replicates per level allow pure error estimation through the factor model. A lack-of-fit test compares that error with the extra variation left by a restricted shape. Both the line and the parabola show detectable lack of fit at the 0.05 level. An unconvincing linear slope does not imply absence of a relationship: it may indicate that the proposed shape misses a substantial decline in strength.

    image/svg+xml Matplotlib v3.10.8, https://matplotlib.org/ 15.0 17.5 20.0 22.5 25.0 27.5 30.0 32.5 35.0 Cotton (%) 10 12 14 16 18 20 22 Mean strength Linear Quadratic Level means
    Figure 7. The straight line misses the rise and fall; the parabola approximates it but also leaves lack of fit. Connecting factor means is a visual guide: the model does not identify responses between untested levels.

    17 · Multiple comparisons and interval interpretation

    Five means generate ten pairwise comparisons. If the question concerns that entire family, Tukey adjusts inference to control the family-wise error rate under classical ANOVA. Simultaneous intervals have 95% joint coverage, unlike ten pointwise intervals treated as a single claim [11].

    cotton_aov <- aov(strength ~ treatment, data = cotton)
    TukeyHSD(cotton_aov, "treatment", conf.level = 0.95)
    mean_grid <- data.frame(treatment = factor(c(15,20,25,30,35),
                             levels = levels(cotton$treatment)))
    predict(m_factor, newdata = mean_grid, interval = "confidence")
    Complete family of Tukey comparisons
    Pair (% cotton)Difference (lb/in²)Simultaneous 95% CIAdjusted p
    20 − 155.60[0.2270, 10.9730]0.0385
    25 − 157.80[2.4270, 13.1730]0.002595
    30 − 1511.80[6.4270, 17.1730]1.901e-05
    35 − 151.00[-4.3730, 6.3730]0.9798
    25 − 202.20[-3.1730, 7.5730]0.7372
    30 − 206.20[0.8270, 11.5730]0.01889
    35 − 20-4.60[-9.9730, 0.7730]0.1163
    30 − 254.00[-1.3730, 9.3730]0.2101
    35 − 25-6.80[-12.1730, -1.4270]0.009065
    35 − 30-10.80[-16.1730, -5.4270]6.241e-05
    image/svg+xml Matplotlib v3.10.8, https://matplotlib.org/ −15 −10 −5 0 5 10 15 Mean difference; simultaneous 95% CI 20 − 15 25 − 15 30 − 15 35 − 15 25 − 20 30 − 20 35 − 20 30 − 25 35 − 25 35 − 30 Cotton (%)
    Figure 8. Mean differences and simultaneous Tukey intervals. Intervals crossing zero do not reject equality for that pair at the 5% family-wise level. All use the same strength units.

    The 30% − 25% contrast estimates 4.0 lb/in², with interval [−1.3730, 9.3730] and adjusted p = 0.2101. Thus the largest mean at 30% does not establish superiority over 25% under this adjustment. By contrast, 30% − 35% estimates 10.8 lb/in², with interval [5.4270, 16.1730] and adjusted p ≈ 0.0000624. Failing to reject a difference does not establish equivalence: equivalence requires margins and a procedure designed for that question.

    With heterogeneous variances, the validity of pooled ANOVA and Tukey comparisons should be reconsidered. Depending on design, Welch ANOVA with compatible comparisons, a variance model, or robust inference may be appropriate. Batches or repeated measurements require a dependence structure. No automatic correction replaces that substantive decision.

    18 · What the two cases support

    In insurance, assets are negatively associated with adoption time, and ownership form is associated with a size-adjusted level difference. The original data provide little evidence of different slopes. The teaching modification examines an explicitly introduced interaction and shows why interpretation must depend on the response actually analyzed.

    In materials, composition is associated with strength differences that a straight line does not adequately describe. The factor preserves five means and exposes the connection between regression and ANOVA. Multiple comparison distinguishes the largest observed average from a statistically supported difference for a specific pair.

    Both cases show that coding selects a testable representation. Changing the reference preserves predictions; imposing a common slope changes restrictions; transforming the response changes the analytical object. Scientific interpretation requires distinguishing those operations, examining uncertainty, and reconstructing the material conditions under which data were produced.

    19 · Reproducing the analysis and figures

    R blocks appear in execution order and use only base R and its standard packages. All data are included. Copy them sequentially into one script without additional input files. Group codes stay in English (Mutual, Stock) so both language versions execute exactly the same analysis. Reported numbers were recomputed using least squares and t, F, and studentized-range distributions; minor rounding differences do not change the conclusions.

    The following block saves data, diagnostics, PDF plots, and session information in a folder relative to the working directory. This article’s figures are drawn from the same data and models. Documenting a new study would additionally require provenance, a measurement protocol, software versions, and exclusion criteria before interpreting results.

    outdir <- "predictores_resultados"
    dir.create(outdir, showWarnings = FALSE)
    write.csv(insurance, file.path(outdir, "insurance.csv"), row.names = FALSE)
    write.csv(cotton, file.path(outdir, "cotton.csv"), row.names = FALSE)
    write.csv(diagnostics, file.path(outdir, "diagnostics.csv"), row.names = FALSE)
    pdf(file.path(outdir, "diagnostics.pdf"), width = 8, height = 8)
    par(mfrow = c(2,2))
    plot(m_add, which = c(1,2,3,5), ask = FALSE)
    plot(m_factor, which = c(1,2,3,5), ask = FALSE)
    dev.off()
    pdf(file.path(outdir, "cases.pdf"), width = 8, height = 6)
    plot(months ~ assets, data = insurance, pch = 16 + insurance$D,
         col = c("#8b4513", "#554637")[1 + insurance$D])
    b <- coef(m_add)
    abline(b[1], b[2], col = "#8b4513")
    abline(b[1] + b[3], b[2], col = "#554637", lty = 2)
    legend("topright", levels(insurance$type), pch = c(16,17),
           col = c("#8b4513", "#554637"), lty = c(1,2), bty = "n")
    plot(months_demo ~ assets, data = insurance, pch = 16 + insurance$D)
    b <- coef(m_demo_int)
    abline(b[1], b[2], col = "#8b4513")
    abline(b[1] + b[3], b[2] + b[4], col = "#554637", lty = 2)
    boxplot(strength ~ treatment, data = cotton, col = "#fffdf7",
            xlab = "Cotton percentage", ylab = "Tensile strength")
    plot(TukeyHSD(cotton_aov, "treatment"), las = 1)
    dev.off()
    capture.output(sessionInfo(), file = file.path(outdir, "sessionInfo.txt"))

    20 · References and documentation

    1. José Mauricio Gómez Julián (2021). Variables cualitativas e interacciones. 24-page paper, published under the pseudonym Isadore Nabi. Read.
    2. Kutner, M. H., Nachtsheim, C. J., Neter, J., & Li, W. (2005). Applied Linear Statistical Models, 5th ed. McGraw-Hill/Irwin. Chapter 8, pp. 313–318.
    3. R Core Team. model.matrix: constructing design matrices. Read.
    4. R Core Team. factor: levels, labels, and coercion. Read.
    5. R Core Team. lm: linear models and formulas. Read.
    6. R Core Team. anova.lm: sequential tables and nested comparisons. Read.
    7. R Core Team. plot.lm: diagnostic plots. Read.
    8. R Core Team. influence.measures: residuals, leverage, and case deletion. Read.
    9. R Core Team. predict.lm: confidence and prediction intervals. Read.
    10. Penn State, Department of Statistics. STAT 503, Lesson 03: Experiments with a Single Factor. Fiber-strength example with different cotton percentages. Read.
    11. R Core Team. TukeyHSD: simultaneous mean comparisons. Read.

    R references point to official documentation consulted on November 4, 2026. The insurance example preserves the observations in the source paper; the complete textile table is cross-checked against the university source listed above. The modified response is consistently identified as a teaching construction.