Espartaco

“Is that to say we are against Free Trade? No, we are for Free Trade, because by Free Trade all economical laws, with their most astounding contradictions, will act upon a larger scale, upon the territory of the whole earth; and because from the uniting of all these contradictions in a single group, where they will stand face to face, will result the struggle which will itself eventuate in the emancipation of the proletariat.”

Karl Heinrich Marx · Marx-Engels Collected Works, Vol. VI, p. 290

28,816 views since December 2020

28,816 visitas desde diciembre de 2020

EnglishEspañol

Category: Mathematics

  • THE CLASSICAL LINEAR REGRESSION MODEL IN R: A THEORETICAL AND APPLIED ANALYSIS FOR BIOSTATISTICS AND POLITICAL ECONOMY

    THE CLASSICAL LINEAR REGRESSION MODEL IN R: A THEORETICAL AND APPLIED ANALYSIS FOR BIOSTATISTICS AND POLITICAL ECONOMY

    Marxist Philosophy of Science · Statistics and political economy

    The Classical Linear Regression Model in R

    Foundations, calculation, and interpretation: from swimming speed to the rate of profit

    Originally published: December 1, 2021
    Revised and expanded: November 4, 2026

    01One scientific question, two fields of application

    Regression connects a question about the world with a mathematical representation of its regularities. Its scientific value depends on measurement quality, research design, the assumptions linking data to the model, and the historical and material interpretation of the phenomenon. Numerical fit is part of that process.

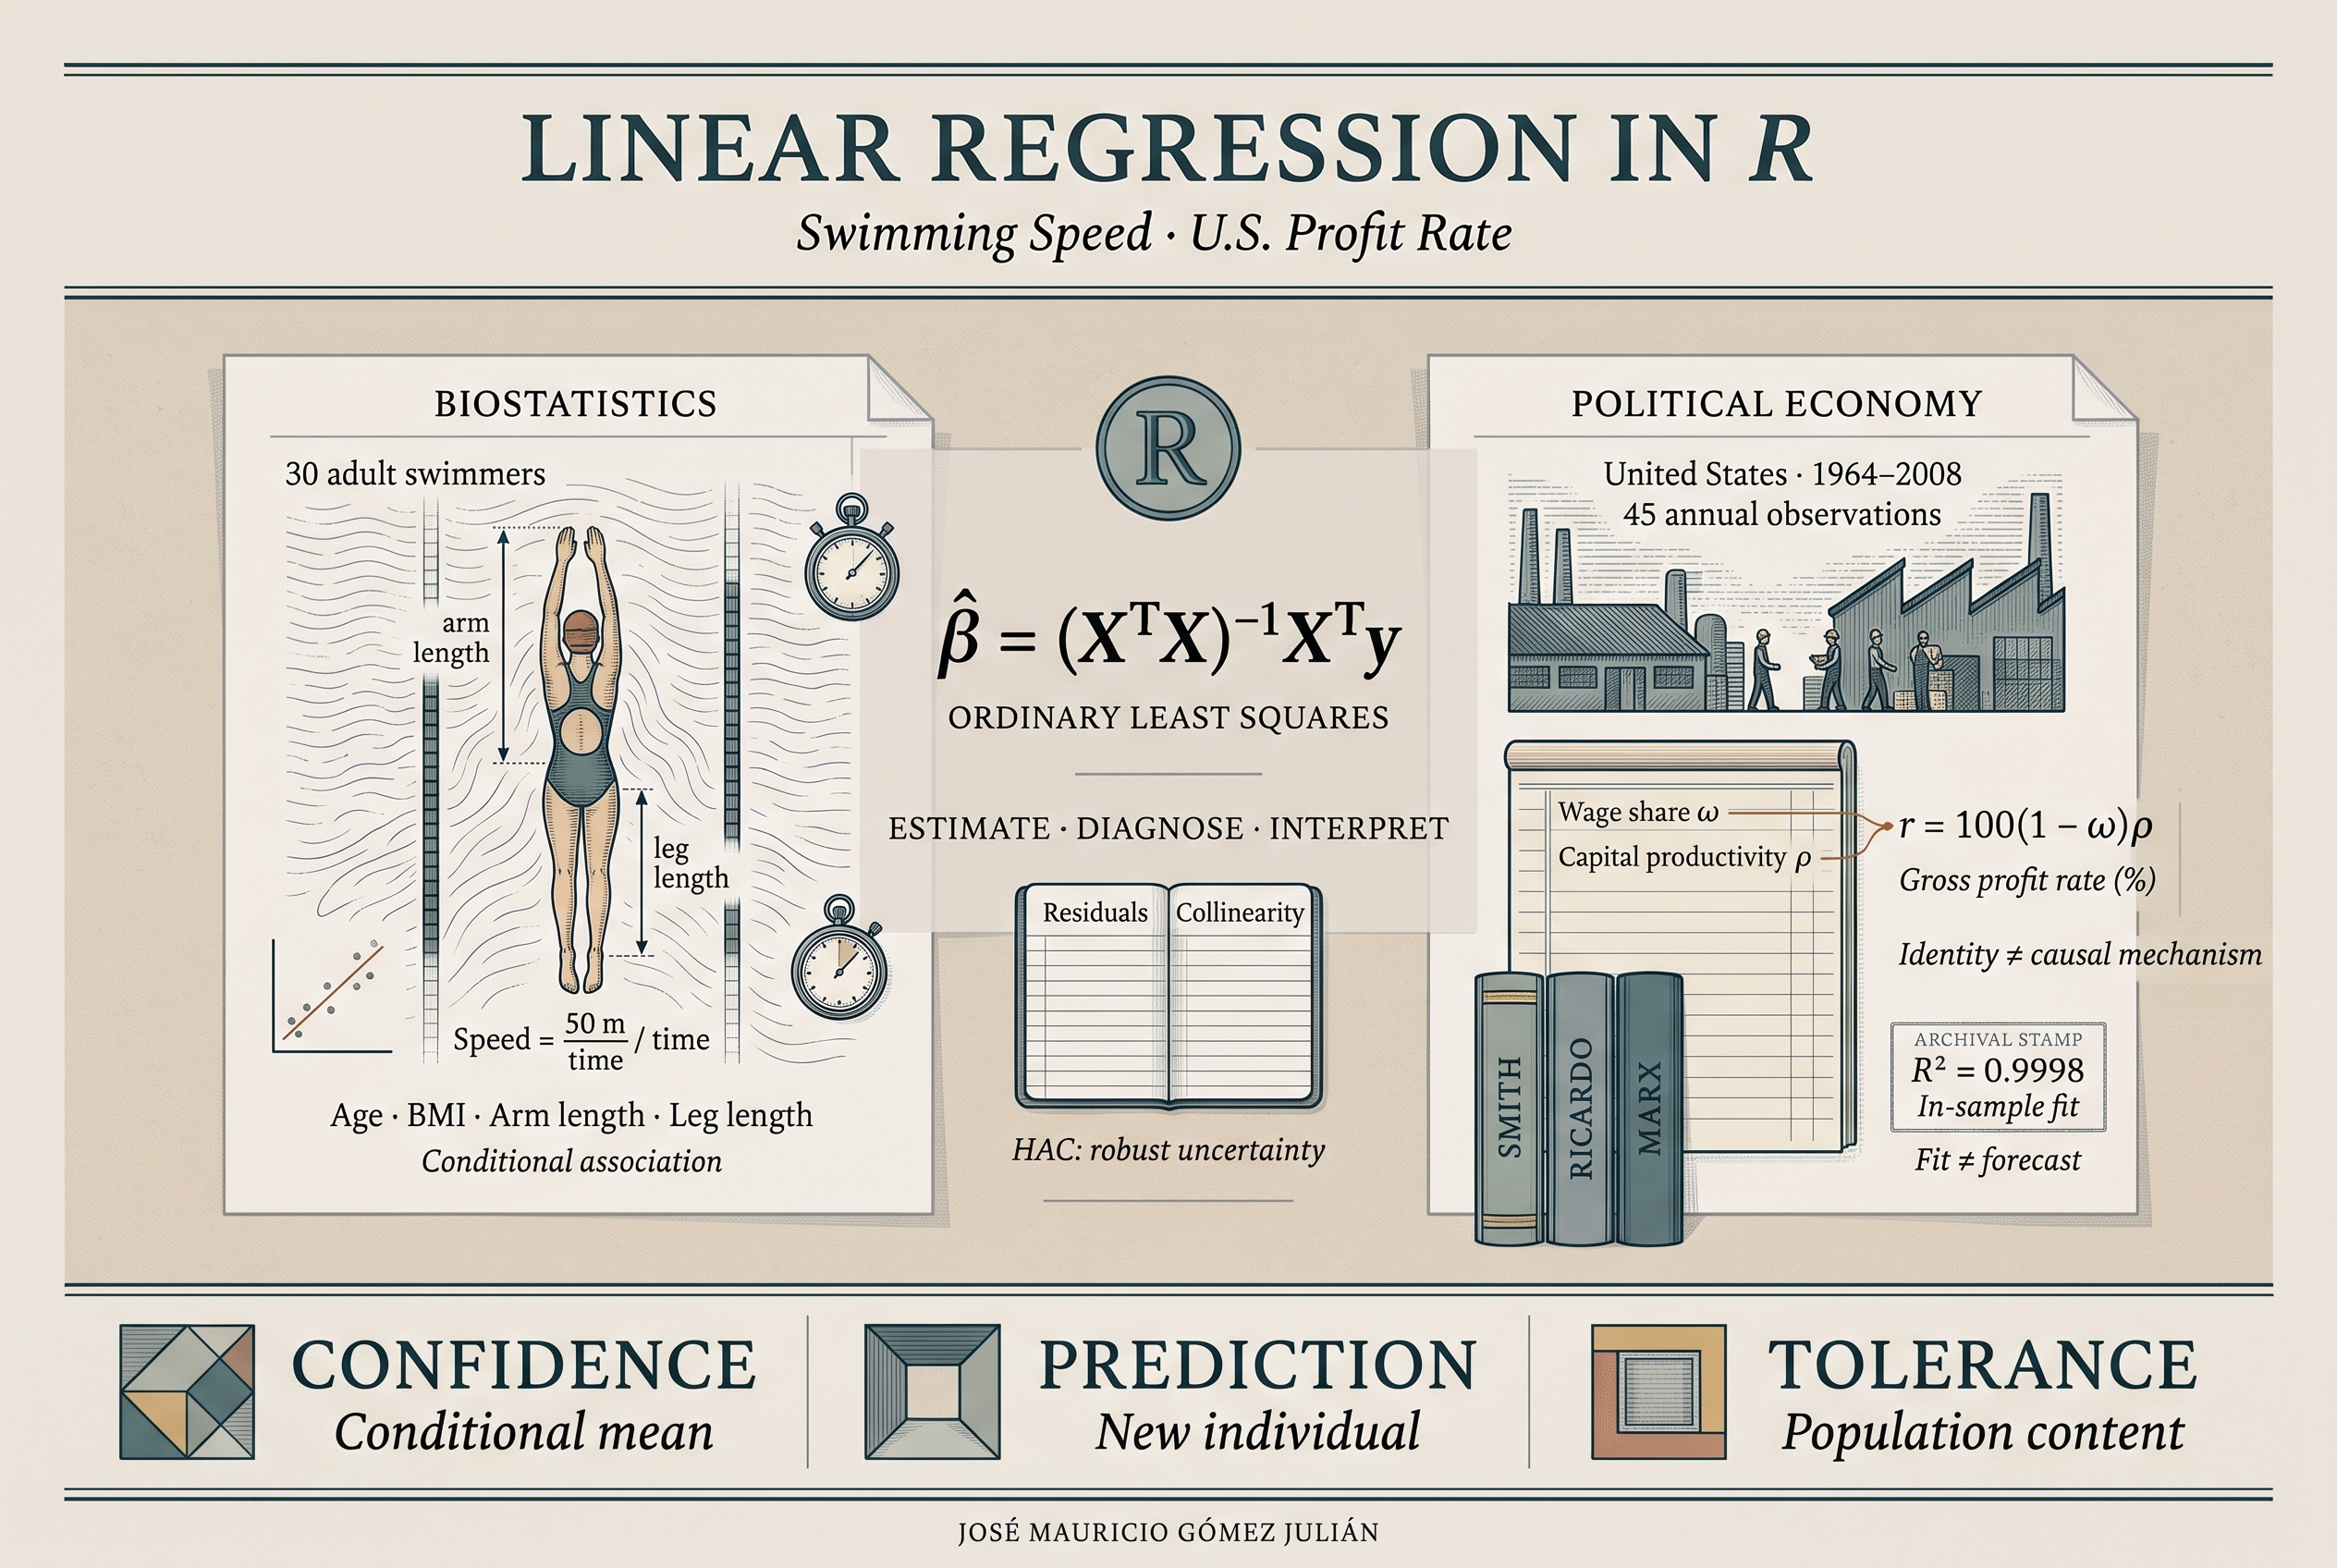
    This article examines the classical linear regression model through two applications: adult swimming speed and the gross rate of profit in the United States during 1964–2008. The first develops matrix calculations, standardisation, the decomposition of variability, and uncertainty. The second also requires examining how variables are constructed from accounting data, temporal dependence, and the relationships between distribution, productivity, and profitability.

    The exposition combines algebra, geometry, probability, R programming, and political economy. Equations are accompanied by interpretations, tables identify their provenance, and the final laboratory includes all the synthetic data needed to run it.

    02Population, sample, and notation

    Let Y be a response variable and X1, …, Xk the predictors. For observation i, the additive model with an intercept is:

    Yi = β0 + β1Xi1 + ··· + βkXik + ui.
    (1)

    β₀ is the intercept; βⱼ is a population slope; uᵢ captures the difference between the response and the part represented by the model.

    We use n for the number of observations and p = k + 1 for the number of coefficients, including the intercept. The design matrix X has n rows and p columns; its first column contains ones. Vector β has p components, and y contains the observed responses.

    y = Xβ + u;   E(Y | X = x) = xTβ, if E(u | X) = 0.
    (2)

    A random variable, its observed realisation, a population parameter, and its estimator are distinct objects. β̂ is an estimator before a sample is observed and a numerical estimate once the data are fixed. Similarly, ui is an unobserved population error; ei = yi − ŷi is a calculated residual.

    Expectation is a probabilistic operator; the arithmetic mean is a function of the data that can estimate an expectation under appropriate conditions. Distinguishing them does not sever their relationship. Nor should a marginal distribution automatically be equated with a Bayesian prior: the former integrates out conditioning variables, whereas the latter represents uncertainty about parameters before updating.

    03What makes the model linear

    Linearity refers to the coefficients. A model containing age and age squared is still linear in its parameters. So is a model containing an interaction between the wage share and capital productivity.

    E(Y | X, Z) = β0 + β1X + β2Z + β3XZ.
    (3)

    In this specification, the slope with respect to X is β1 + β3Z. Adding an interaction therefore changes the meaning of the individual slopes. Coefficient β1 describes the statistical effect of X when Z equals zero, subject to the model’s interpretation.

    Transforming the response also changes the quantity being estimated. When log speed is modelled, exponentiating the predicted mean of log speed does not generally recover mean speed: back-transformation requires considering the error distribution. Likewise, modelling travel time and then transforming through 50/time is not equivalent to directly fitting mean speed.

    04Least squares: optimisation and projection

    Ordinary least squares (OLS) chooses the coefficients that minimise the sum of squared residuals. Squared loss penalises large errors particularly strongly.

    S(b) = (y − Xb)T(y − Xb).
    (4)

    Differentiating with respect to b and setting the derivative equal to zero yields the normal equations XTXb = XTy. If the columns of X are linearly independent, the solution is unique:

    β̂ = (XTX)−1XTy.
    (5)

    Geometrically, ŷ is the orthogonal projection of y onto the space spanned by the columns of X. Residuals are orthogonal to that space: XTe = 0. With an intercept, residuals sum to zero apart from rounding error.

    This orthogonality of residuals to the design columns does not require predictors to be mutually orthogonal. The former is an algebraic property of the fit; the latter would be an additional property of the design.

    X <- model.matrix(~ edad + imc + pierna + brazo, data = bio)
    y <- bio$veloc
    # Teaching expression; requires full rank and good conditioning.
    beta_ecuaciones <- solve(crossprod(X), crossprod(X, y))
    # Preferred for numerical computation: QR decomposition.
    beta_qr <- qr.coef(qr(X), y)
    m_bio <- lm(veloc ~ edad + imc + pierna + brazo, data = bio)
    all.equal(unname(beta_qr), unname(coef(m_bio)))

    Inverting XTX is useful for deriving formulas. In computation, forming this product can worsen numerical conditioning; lm() uses QR. An exact mathematical identity and a floating-point operation involve different levels of representation: small discrepancies are assessed using explicit numerical tolerances.

    05What each assumption guarantees

    Assumptions, guarantees, and limits
    ConditionWhat it supportsWhat it does not establish
    Full column rank of XUnique identification of OLS coefficients.Stochastic independence between predictors.
    E(u | X) = 0Conditional unbiasedness of OLS, subject to the relevant existence conditions.Causality simply because a regression has been fitted.
    Var(u | X) = σ²IClassical covariance and OLS efficiency among linear unbiased estimators.Normality of errors.
    Conditional normality of uExact t and F distributions in a correctly specified classical model.Marginal normality of every predictor or of Y.
    Moment and weak-dependence conditionsRelevant laws of large numbers and asymptotic approximations.That 30 or 45 observations automatically constitute a large sample.
    Causal design and substantive identificationCausal interpretation under the design-specific assumptions.That a small p-value replaces identification.

    Normality is unnecessary for computing OLS or for the Gauss–Markov theorem. Heteroskedasticity does not, by itself, bias the coefficients if exogeneity holds, but it invalidates the conventional covariance formula. Consistency requires additional conditions on the generating process, its moments, and its dependence.

    Linear independence means that no column is an exact linear combination of the others. Stochastic independence concerns the factorisation of joint distributions. Orthogonality means a zero inner product. Zero correlation is another property and does not, in general, imply stochastic independence.

    I · Biostatistics

    06The swimming case: measurement and target population

    The application considers regular swimming-team members completing 50 metres. The documented tables contain 30 observations, with ages ranging from 18 to 51. Describing the sample as people aged 18 or older is more precise than describing everyone as strictly older than 18.

    speed (m/s) = 50 m / time (s).
    (6)
    Biostatistical case dictionary
    VariableDefinition and unitInterpretive caution
    velocSwimming speed, in metres per second.A higher value means faster swimming; using time reverses the direction.
    edadAge in completed years.The cross-sectional coefficient compares people; it does not automatically measure individual ageing.
    sexoDocumented coding: 0 women, 1 men.Document the coding rather than assigning it a single biological explanation.
    imcWeight in kg divided by squared height in metres: BMI.Not a direct measure of body composition.
    piernaMean length of both legs, in cm.May share variation with arm length and other body measurements.
    brazoMean length of both arms, in cm.Its adjusted association depends on the predictors included.

    The target population is shaped by recruitment: regular team membership does not represent the entire adult population. Training, technique, health, experience, and selection into participation can influence both observed characteristics and performance.

    Omitting sexo from some models does not establish identical mean speed across its categories. Such a model describes a relationship without explicit adjustment for that variable. Inclusion or exclusion should be discussed in terms of the question, design, and sample size, avoiding decisions based solely on marginal correlations.

    07Graphical exploration and correlations

    Scatterplots help examine approximate linearity, extreme observations, sparsely populated regions, and possible group differences. A fitted line summarises a trend; a smoother helps explore curvature. Plot bands must be interpreted according to the procedure producing them: they do not automatically represent a concentration region for errors.

    # With bio defined in the final laboratory:
    vars <- c("veloc", "edad", "imc", "pierna", "brazo")
    pairs(bio[vars], pch = 19, col = "#8b4513")
    round(cor(bio[vars]), 3)
    # Optional; the corresponding packages are required.
    # lattice::xyplot(veloc ~ edad, data = bio, type = c("p", "r"))
    # car::scatterplot(veloc ~ edad, data = bio)
    # car::scatterplotMatrix(~ veloc + edad + imc + pierna + brazo, data = bio)

    In xyplot(), type=c("p","r") requests points and a regression line. It is a plotting argument, not an instruction to change an object’s storage type. Trellis names a system of conditioning plots; using the lattice package does not imply constructing an algebraic lattice in the sense of order theory.

    The documented correlations with speed are approximately −0.65 for age, −0.01 for BMI, 0.21 for leg length, and 0.29 for arm length. These describe bivariate sample associations. A small marginal correlation does not establish irrelevance after adjusting for other variables, and a strong correlation does not identify a causal effect.

    Pearson’s coefficient is covariance divided by the product of standard deviations. It is unitless and describes linear association. It should be examined alongside the plot: outliers, mixed groups, or curvature can make its scalar summary misleading.

    08Comparable specifications and modelling decisions

    Model map for the swimming case
    Stable nameSpecificationQuestion
    m_dosveloc ~ edad + brazoAssociations adjusted for age and arm length.
    m_bioveloc ~ edad + imc + pierna + brazoConditional contributions of four characteristics.
    m_sin_edadveloc ~ imc + pierna + brazoWhat changes when age is omitted.
    m_mmveloc ~ edad + imc + pierna + brazommInvariance of fitted values after a unit change.
    m_edadveloc ~ edadWhat age describes by itself.
    m_nuloveloc ~ 1Reference based on a common mean.

    Model comparisons require retaining the same observations. If each fit removes different rows because of missing values, its sums of squares and information criteria cease to be directly comparable. The treatment of missingness must be defined and documented before comparison.

    Dropping leg length because it is highly correlated with arm length may reduce instability, but it also changes the question and can introduce omitted-variable bias if a necessary variable is removed. Examining rank, variance inflation, substantive knowledge, and stability provides a fuller assessment.

    m_dos <- lm(veloc ~ edad + brazo, data = bio)
    m_bio <- lm(veloc ~ edad + imc + pierna + brazo, data = bio)
    m_sin_edad <- lm(veloc ~ imc + pierna + brazo, data = bio)
    m_edad <- lm(veloc ~ edad, data = bio)
    m_nulo <- lm(veloc ~ 1, data = bio)
    stopifnot(nobs(m_bio) == nobs(m_edad), nobs(m_bio) == nobs(m_sin_edad))

    09Interpreting slopes and point predictions

    The documented age-and-arm-length specification yields approximately:

    ŷ = 0.29220247 − 0.01816942 · edad + 0.02141960 · brazo.
    (7)

    Comparing two people ten years apart in age, holding arm length fixed, is associated with a difference of −0.1816942 m/s in estimated mean speed. A five-centimetre difference in arm length, at a fixed age, is associated with +0.107098 m/s. These are conditional model comparisons; they do not necessarily describe how the same person would change after ten years or after an intervention.

    For age 24 and arm length 71 cm, the documented prediction is 1.376928 m/s. For age 34 with the same arm length, it is 1.195234 m/s. Keep the full coefficient precision during calculation and round for presentation: 1.38 and 1.20 m/s.

    # x0 builds a new predictor combination; it does not select rows.
    x0 <- c(1, 24, 71)
    # For the model fitted to the data currently in use:
    drop(x0 %*% coef(m_dos))
    predict(m_dos, newdata = data.frame(edad = 24, brazo = 71))

    The first component of x0 is the one multiplying the intercept. This model’s intercept corresponds to age zero and arm length zero, a scenario without an applied interpretation in the adult sample. Its algebraic role does not require assigning it a real biological state.

    10Units and standardised coefficients

    If a length is converted from centimetres to millimetres, its values are multiplied by ten and its slope is divided by ten. Predictions, residuals, and the residual sum of squares remain unchanged apart from rounding. Changing units adds no explanatory capacity.

    β̂j,std = β̂j · sXj / sY.
    (8)

    The fully standardised slope expresses differences in standard deviations of Y per one standard deviation of Xⱼ, holding the other variables fixed.

    In the documented four-predictor specification, standardised slopes are approximately −0.76 for age, 0.20 for BMI, −0.07 for leg length, and 0.50 for arm length. The comparison refers to that sample and that set of controls. Standard deviations incorporate features of the sample distribution, so the ordering of magnitudes is not a universal causal ranking.

    β̂std = RXX−1rXY.
    (9)

    Rₓₓ is the correlation matrix of centred and scaled predictors; rₓᵧ contains their correlations with the response. Rₓₓ must be invertible.

    In simple regression with an intercept, the fully standardised slope equals Pearson’s correlation. In multiple regression, it equals each predictor’s bivariate correlation if the standardised predictors are mutually orthogonal. Orthogonality can occur with continuous variables or with factors under suitable designs.

    vars <- c("veloc", "edad", "imc", "pierna", "brazo")
    bio_z <- as.data.frame(scale(bio[vars]))
    m_z <- lm(veloc ~ edad + imc + pierna + brazo, data = bio_z)
    beta_est <- coef(m_bio)[-1] * sapply(bio[vars[-1]], sd) / sd(bio$veloc)
    all.equal(unname(beta_est), unname(coef(m_z)[-1]))

    Fully standardised slopes

    −10+1
    Age
    -0.76
    BMI
    +0.20
    Leg
    -0.07
    Arm
    +0.50
    Rounded documented values for the same four-predictor specification (pp. 15–16). A common scale helps compare sample magnitudes; it does not establish causal importance.

    11Sums of squares and degrees of freedom

    For OLS with an intercept, total variability around the mean decomposes into variability explained by the fit and residual variability:

    SST = Σ(yi − ȳ)²;   SSR = Σ(ŷi − ȳ)²;   SSE = Σ(yi − ŷi)²;   SST = SSR + SSE.
    (10)

    We use SST for the total sum of squares, SSR for the regression sum of squares, and SSE for the residual error sum of squares. Some sources use different abbreviations, so each name should always be accompanied by its defining formula.

    s² = SSE / (n − p);   MSR = SSR / (p − 1);   R² = 1 − SSE/SST.
    (11)

    s² is the residual mean square and estimates σ² under the classical assumptions. MSR is the regression mean square for the set of slopes. Degrees of freedom are not identical for all terms: they depend on rank and the number of restrictions.

    The residual projection has dimension n − p. Estimating a mean imposes one restriction on residuals and leaves n − 1 degrees of freedom. More generally, degrees of freedom are explained by linear restrictions and rank, without needing to derive them from a physical principle of least action.

    Arithmetic verification: n = 30; SST = 1.730004; rounded published statistics
    Documented modelSSEs²R²Adjusted R²
    Four predictors0.645170.02580680.627070.56740
    Without age1.563360.06012920.09633−0.00794
    Age only0.990210.03536460.427630.40718

    The four-predictor model captures approximately 62.7% of sample variability; age alone captures 42.8%. Adding predictors to nested models on the same rows never reduces ordinary R². This mechanical property explains the need to consider complexity and validation.

    R²adj = 1 − [SSE/(n − p)] / [SST/(n − 1)].
    (12)

    A negative adjusted R² indicates that, under this penalty, the specification performs worse than a common-mean reference. Equality of two R² values after rounding does not establish the absence of overfitting.

    An estimator’s quadratic risk is a different object: MSE(θ̂) = Var(θ̂) + Bias(θ̂)². It should not simply be identified with the residual mean square. In predictive evaluation, RMSE usually uses the average squared error on test observations; its denominator serves a different purpose from estimating σ² using n − p.

    Explained and residual fractions of variability

    Complete
    62.7 %
    No age
    9.6 %
    Age only
    42.8 %
    Brown: explained fraction. Beige paper: residual fraction. Percentages reconstructed from published sums of squares; same response and n = 30.

    12Covariance, standard errors, and coefficient intervals

    Under Var(u | X) = σ²I, slope uncertainty depends on residual variability and the geometry of the design.

    Var(β̂ | X) = σ²(XTX)−1;   V̂ = s²(XTX)−1.
    (13)

    The diagonal contains estimated coefficient variances. Their square roots are standard errors. Off-diagonal elements are covariances between estimators and matter when calculating uncertainty for combinations of coefficients.

    CI1−α(βj) = β̂j ± t1−α/2, n−p · SE(β̂j).
    (14)
    Four-predictor model; 25 residual degrees of freedom. Document, pp. 24–25 and 49–50
    TermEstimateStandard errorDocumented 95% CI
    Intercept−0.1354220.602032[−1.3753, 1.1045]
    Age (edad)−0.0191720.003214[−0.0258, −0.0126]
    BMI (imc)0.0155320.010023[−0.0051, 0.0362]
    Leg length (pierna)−0.0025990.009907[−0.0230, 0.0178]
    Arm length (brazo)0.0262620.012982[−0.0005, 0.0530]

    For a five-year difference, holding the other characteristics fixed, the mean-difference interval is obtained by multiplying both endpoints of the age interval by five: approximately [−0.129, −0.063] m/s. Multiplying by a negative constant would also require reordering the endpoints.

    The precision of slopes measured in different units cannot be compared using the absolute widths of their intervals. An interval excluding zero concerns the corresponding two-sided test; it does not establish that the coefficient has the greatest scientific importance.

    13Conditional mean and new observation: two uncertainties

    For a combination of characteristics x0, the predicted mean is x0Tβ̂. Its estimated variance is a quadratic form:

    v̂mean = x0TV̂x0;   CI = ŷ0 ± t1−α/2,n−p√v̂mean.
    (15)

    A new observation adds its own individual variation. Under normality, homoskedasticity, and independence of the new error from the sample:

    PI = ŷ0 ± t1−α/2,n−p√(s² + v̂mean).
    (16)

    The additional s² term explains why the individual interval is wider. For age 22, BMI 20 kg/m², leg length 100 cm, and arm length 70 cm, the documented outputs are:

    Confidence and prediction for the same characteristics. Document, p. 30
    QuantityEstimate or intervalInterpretation
    Predicted mean1.33 m/sEstimated conditional mean speed.
    95% CI for the mean[1.22, 1.45] m/sUncertainty about the conditional mean.
    95% individual PI[0.98, 1.68] m/sPredictive coverage for a new observation under the model.
    0.8 m/s1.8 m/s
    Mean CI
    Individual PI
    Scaled representation of the documented intervals. The central mark represents the rounded value 1.33 m/s.
    nuevo <- data.frame(edad = 22, imc = 20, pierna = 100, brazo = 70)
    predict(m_bio, nuevo, interval = "confidence", level = .95)
    predict(m_bio, nuevo, interval = "prediction", level = .95)

    In a frequentist interpretation, the confidence level describes procedural coverage under repeated sampling. It does not mean that 95% of people fall within the interval for the mean, nor does it constitute causal evidence. The specific numbers above belong to the documented study; running the synthetic laboratory will produce different intervals.

    14Tolerance and Bayesian inference: a different question

    A tolerance interval seeks to cover at least a proportion P of a distribution with confidence 1 − α. Content and confidence are separate controls. A prediction interval for one future observation does not automatically provide the same guarantee about a population fraction.

    Prmustdras{ PrY[L(datos) ≤ Y ≤ U(datos)] ≥ P } ≥ 1 − α.
    (17)

    This expression states the frequentist content guarantee for a two-sided tolerance interval.

    For a marginal normal distribution, the usual form is ȳ ± ktols. The tolerance factor depends on sample size, confidence, content, and procedure. An equal-tailed interval additionally controls how the excluded content is distributed between the two tails.

    # Requires tolerance; synthetic marginal normal example.
    # Not a conditional interval from the swimming model.
    set.seed(20261106)
    y_normal_demo <- rnorm(60, mean = 1.4, sd = .16)
    # tolerance::normtol.int(y_normal_demo, alpha = .05, P = .95,
    #                        side = 2, method = "HE")

    Conditional regression tolerance requires a procedure incorporating covariates and their uncertainty. Applying a marginal procedure to all swimming speeds answers a different question.

    A conjugate Bayesian normal formulation can specify μ | σ² ∼ N(μ₀, σ²/n₀), together with a scaled inverse-chi-squared distribution for σ² with parameters m₀ and s₀². Here μ₀ is a prior location; n₀ controls relative precision for μ; m₀ and s₀² govern prior uncertainty about σ². Neither n₀ nor m₀ is another observed mean or variance.

    A normal likelihood and a prior distribution are distinct components. An approximately normal response histogram does not determine a prior over its parameters. Hyperparameters require external information, an explicit construction rule, or sensitivity analysis. In bayesnormtol.int(), one must also distinguish side=1, which produces one-sided limits, from side=2, which specifies a two-sided procedure.

    Arbitrary moment matching does not justify a prior. Convergence in distribution alone does not ensure convergence of moments: additional conditions, such as appropriate uniform integrability, are required. Every probability distribution has a characteristic function, even when its mean or variance is not finite. The normal distribution has all its moments, but the existence of a characteristic function is not proof that all moments exist.

    15Distributions, Q–Q, P–P, and normality tests

    A Q–Q plot compares observed quantiles with quantiles of a reference distribution. A P–P plot compares cumulative probabilities. The former often makes tail discrepancies more visible; the latter provides another view of distributional fit.

    In normal regression, the assumption concerns conditional errors. The marginal response may be skewed because it mixes groups or covariate values even when conditional errors are normal. Begin with residuals versus fitted values, residuals versus predictors, and a residual Q–Q plot.

    par(mfrow = c(2, 2))
    plot(m_bio)
    par(mfrow = c(1, 1))
    shapiro.test(residuals(m_bio))
    # A test on fitted residuals is interpreted as exploratory diagnostics;
    # residuals share restrictions and are not an iid sample of errors.

    The documented Shapiro–Wilk output for the swimming response gives p = 0.3454. This does not reject marginal normality at 5%, but neither establishes normality nor verifies all regression assumptions.

    A one-sample Kolmogorov–Smirnov test compares data with a fully specified distribution function. Its usual calibration does not apply when parameters are estimated from the same sample. Comparing the data with simulated normal observations having a different location and scale tests equality of distributions, rather than providing a general normal-shape diagnostic. A Lilliefors procedure or a properly designed simulation calibration addresses different issues and must be identified explicitly.

    Fitting normal, lognormal, and gamma distributions by maximum likelihood allows comparison of candidate marginal models on the same response and sample. A lower AIC or BIC expresses a relative preference within that set, not a proof of truth. Moreover, a suitable marginal family does not by itself determine a regression’s conditional family.

    ACI = −2ℓ(θ̂) + 2d;   BCI = −2ℓ(θ̂) + d log(n).
    (18)

    ℓ is the maximised log-likelihood, and d counts the parameters estimated for that probabilistic model. Comparison requires a compatible likelihood basis.

    With small datasets, considering corrected AIC may be appropriate if the formula matches the model family. Comparisons involving transformed responses must account for the transformation Jacobian; likelihood values defined on incompatible scales should not be compared directly.

    16Marginal effects and sequential sums of squares

    In an additive linear model, the partial derivative of the mean with respect to a continuous predictor is its slope:

    ∂E(Y | X)/∂Xj = βj.
    (19)

    Without interactions or transformations, the marginal effect is constant: the average marginal effect, the marginal effect at the means, and effects at representative values coincide. For a binary variable, calculate a discrete difference between predictions. None of these operations establishes causality without additional identification.

    The reduction in the residual sum of squares when a variable is introduced is a different quantity. In anova(m_bio), terms are added in formula order. Their contributions depend on what came before; reordering terms does not change the slopes of the complete additive model.

    Different questions produce different results
    Documented quantity for leg lengthValueComparison
    Sequential sum of squares after age and BMI0.21680Add leg length before including arm length.
    p-value of that ANOVA row0.007697Sequential test using the complete model’s residual mean square.
    Adjusted p-value for leg length in summary()0.7952Leg-length coefficient conditional also on arm length.
    Additional sum of squares after arm length, without other controls0.01660077Compare veloc ~ brazo with veloc ~ brazo + pierna.

    The difference between 0.007697 and 0.7952 is not a contradiction: the set of conditioning variables changes. The sequential test attributes to leg length variation it may share with arm length. To assess its contribution after all other terms, compare the complete model with one omitting only leg length, or use the equivalent t test for that single coefficient.

    17t and F tests: explicit hypotheses and manual calculation

    The p-value is the probability, under the null hypothesis and assumed model, of a test statistic at least as extreme as the observed one in the direction specified by the alternative. It is not the probability that the null is true, that the result is due to chance, or a general measure of a study’s reliability or importance.

    For two nested models, reduced R and complete C, fitted on the same rows, let q = pC − pR be the number of restrictions. The classical statistic is:

    F = [(SSER − SSEC)/q] / [SSEC/(n − pC)].
    (20)

    Under the null hypothesis and spherical normal errors, it follows an F distribution with q and n − pC degrees of freedom. Large values provide evidence against the restrictions. Reject at level α if the p-value is below α, with the threshold set before examining results.

    Reconstructed calculations using rounded published sums of squares. Document, pp. 47–54
    Documented testNull hypothesisApproximate FApproximate p-value
    Four predictors versus ageβ_BMI = β_leg = β_arm = 04.4567; df (3,25)0.012205
    Add age to the other threeβ_age = 035.5794; df (1,25)0.000003153
    Four predictors versus interceptAll four slopes are zero10.5092; df (4,25)0.00003906

    The first test indicates that the three additional variables, considered jointly, add information relative to the age-only model under classical assumptions. It does not establish that each is individually significant. Joint significance can coexist with inconclusive individual tests when predictors are correlated.

    tj = β̂j/SE(β̂j);   Funa rstdricción = tj².
    (21)

    The equality concerns the same restriction, the same covariance estimator, and the equivalent two-sided t test. It does not equate every F test with every t test. Under the same procedure, a two-sided interval and the test at the corresponding level agree on excluding or including the null value.

    anova(m_edad, m_bio)
    anova(m_sin_edad, m_bio)
    anova(m_nulo, m_bio)
    # Upper tail, more stable than calculating 1 - pf(...):
    F_doc <- ((.99021 - .64517) / 3) / (.64517 / 25)
    pf(F_doc, df1 = 3, df2 = 25, lower.tail = FALSE)

    18Diagnostics: form, leverage, and influence

    Residual analysis looks for patterns incompatible with the specification: curvature, fan-shaped dispersion, clusters, and dependence. A single plot neither verifies exogeneity nor removes the need to examine the design.

    The leverage of observation i is diagonal element hii of the projection matrix. It summarises how unusual its predictor combination is relative to the design. A large residual describes response discrepancy. Influence measures how much a fit changes when observations are perturbed. These concepts are related but distinct.

    H = X(XTX)−1XT;   Σhii = p;   Di = [ei²/(p s²)] · hii/(1 − hii)².
    (22)

    Cook’s distance combines residual size and leverage. Thresholds such as 4/n or multiples of the mean are investigative guides. Measurement quality, context, and sensitivity of conclusions should be examined, without automatically deleting observations that reflect real episodes.

    diagnostico <- data.frame(
      fila = seq_len(nobs(m_bio)),
      residuo = residuals(m_bio),
      residuo_studentizado = rstudent(m_bio),
      leverage = hatvalues(m_bio),
      Cook = cooks.distance(m_bio)
    )
    diagnostico[order(diagnostico$Cook, decreasing = TRUE), ]

    An HC3 standard error helps assess inferential sensitivity to heteroskedasticity in a cross-sectional sample under appropriate conditions. It does not correct omitted variables, measurement error, dependence between swimmers, or sample selection.

    II · Political economy

    19The rate of profit as a political-economy problem

    Profitability connects investment decisions, competition, distribution, and capital reproduction. Studying it requires defining the surplus being measured, the capital used as denominator, its valuation, and the statistic’s institutional coverage.

    Smith, Ricardo, and Marx give profits a central place, while offering different explanations of their movements and mediations. In Marx, surplus-value production, competition, the transformation of values into prices, and the formation of a general rate of profit belong to related levels of analysis. An aggregate national-accounts rate is a specific operationalisation; identifying it directly with a theoretical category requires an argument.

    The Cambridge controversies over heterogeneous capital and reswitching challenge particular parables of substitution and aggregate marginal productivity. Their results should be presented within their formal scope: they do not, by themselves, empirically validate any alternative econometric specification.

    Research on relationships between labour values and prices, and research on the determinants of profitability, share categories and sources but test different questions. A value–price correlation does not substitute for identifying the temporal mechanisms of a profit rate.

    The exercise considered here uses 45 annual United States observations from 1964 to 2008 and attributes the data to the Extended Penn World Tables compiled by Marquetti and Foley. The time span allows historical trajectories to be examined, although the number of years does not by itself guarantee accurate asymptotic approximations.

    20Define the variables before estimation

    Economic dictionary: final definitions must be checked against the file and EPWT edition used
    ColumnInterpretation to documentRequired check
    Mean_Gross_ProfitGross rate of profit, expressed as a percentage.Define surplus, denominator, and the difference between gross and net.
    K_ProductivityAverage capital productivity: output/capital.Verify prices, coverage, and stock valuation.
    L_ProductivityAverage labour productivity: output per employed person.Distinguish employment from hours and document the treatment of self-employment.
    Mean_w_shareLabour compensation as a share of output.Specify adjustments and consistency between numerator and denominator.
    Mean_wAverage real wage or compensation per worker.Confirm whether the column is a per-worker average; do not call it the total wage bill.
    RealGDPAggregate real output.Document currency, base year, purchasing power parity, and data vintage.
    K_Net_StockStandardised net fixed capital stock.Distinguish stock from flow, current valuation, and constant prices.
    DepreciationRateDepreciation rate.Check whether the unit is a proportion or percentage.
    YearCalendar year.Chronological order, no duplicates, and continuity of observations.

    Average capital productivity is not marginal capital productivity. The wage share is not the average wage, and the average wage is not the aggregate wage bill. Their changes can diverge: rising real remuneration can coexist with a falling wage share if productivity grows faster.

    National accounts incorporate conventions and estimates. Their constructed character does not make them arbitrary: it means comparability, adjustments, and the relationship between statistical and theoretical categories are part of the investigation. Changing database editions can alter the series; replication requires identifying the exact edition.

    21Accounting identities and shared relationships

    Let Q be output, W labour compensation, K the capital stock, and N employment, defined consistently. Then:

    ω = W/Q;   ρ = Q/K;   x = Q/N;   w = W/N;   w = ωx.
    (23)

    If gross surplus is defined as Q − W, the gross rate of profit satisfies:

    r = (Q − W)/K = (1 − ω)ρ;   r% = 100(1 − ω)ρ.
    (24)

    This construction of the gross rate appears explicitly in studies using EPWT 4.0. It must be checked against the exercise’s columns before concluding that it holds exactly: coverage, price, source, or rounding adjustments can change its numerical agreement. A net rate must incorporate depreciation consistently, using compatible units.

    When these identities hold, regressing profitability on the wage share and capital productivity uses components of the response itself. A strong association may follow from that construction. Its economic content also concerns how the components evolve and why; the identity alone does not determine their causal mechanisms.

    # Apply to empirical data only after confirming the definitions.
    identidad_r <- with(eco, 100 * (1 - Mean_w_share) * K_Productivity)
    identidad_w <- with(eco, Mean_w_share * L_Productivity)
    max(abs(eco$Mean_Gross_Profit - identidad_r))
    max(abs(eco$Mean_w - identidad_w))

    The profitability identity is multiplicative in ω and ρ. Written as a regression, it contains an interaction:

    r% = 100ρ − 100ωρ.
    (25)

    An additive regression can approximate it very closely over a limited range without its four slopes representing four independent mechanisms. Moreover, w = ωx generates nonlinear functional dependence between predictors. This need not be perfect linear collinearity, but it restricts economically possible combinations.

    Consequently, the partial derivative of a fit that holds the average wage and wage share fixed while changing labour productivity may describe a combination incompatible with these identities. A ceteris paribus interpretation must respect the set of admissible states.

    22The economic model and the meaning of its fit

    The documented four-predictor specification is:

    r̂% ≈ 71.532 − 118.76ω − 0.00039514x + 39.903ρ + 0.00065361w.
    (26)
    Published results for the United States additive fit. Document, pp. 64–65
    Documented resultValueAppropriate reading
    Observations45 yearsA historical series; years are not exchangeable by default.
    Estimated coefficients5, including the intercept40 residual degrees of freedom.
    R² and adjusted R²Both 0.9998 after roundingExceptionally high in-sample fit; investigate identities and validation.
    Residual standard error0.0439In response units; if percentages are used, percentage points.
    InterceptApproximately 71.532Prediction at zero-valued predictors; potentially extreme extrapolation.

    A significant intercept does not demonstrate autonomous profitability independent of economic processes or identify omitted political factors. A constant can absorb the level of a local approximation and lack substantive meaning when the origin is far from the sample.

    One useful way to understand the fit is to expand the identity around reference values ω₀ and ρ₀. Writing Δω = ω − ω₀ and Δρ = ρ − ρ₀:

    r% = 100(1 − ω₀)ρ₀ − 100ρ₀Δω + 100(1 − ω₀)Δρ − 100ΔωΔρ.
    (27)

    The first three terms form a local additive approximation; the last is the omitted interaction. If joint variations are small, the approximation can attain a very high R². This offers a mathematical explanation to investigate in the data, without automatically attributing the result to exceptional causal robustness.

    23BIC selection and specification coherence

    The exercise initially explores year, real output, net capital stock, depreciation, and the four distributive and productivity predictors. The displayed backward search removes depreciation but retains year, output, and stock alongside the four predictors. The four-predictor model is therefore an additional proposal requiring explicit comparison.

    m_amplio <- lm(Mean_Gross_Profit ~ Year + RealGDP + K_Net_Stock +
      DepreciationRate + K_Productivity + L_Productivity +
      Mean_w_share + Mean_w, data = eco)
    m_bic <- step(m_amplio, direction = "backward",
                  k = log(nobs(m_amplio)), trace = 0)
    m_eco <- lm(Mean_Gross_Profit ~ Mean_w_share + L_Productivity +
                K_Productivity + Mean_w, data = eco)
    formula(m_bic)
    BIC(m_amplio, m_bic, m_eco)

    step() implements a local search: failure to improve the criterion by removing any one term does not establish that no better subset can be obtained by removing several terms jointly. The output may retain the AIC label even when k=log(n) uses a BIC-type penalty.

    Comparisons must use the same response and rows. Criteria calculated by extractAIC() and BIC() can differ by additive constants under a compatible parameter-counting convention; comparisons should remain within the same definition. Automatic selection does not replace identity analysis, theory, or out-of-sample evaluation.

    If the specification is chosen using the same data, subsequent conventional intervals do not automatically incorporate selection uncertainty. For prediction, selection is performed within each training set, keeping evaluation observations separate.

    24Collinearity: precision, stability, and material restrictions

    For predictor j, variance inflation is summarised by:

    VIFj = 1/(1 − R²j).
    (28)

    R²ⱼ comes from regressing Xⱼ on all other predictors with an intercept, rather than on only one other predictor.

    The documented VIFs are approximately 41.34 for the wage share, 1621.24 for labour productivity, 8.10 for capital productivity, and 1268.56 for the average wage. They indicate little independent variation along several design directions. A threshold of ten is a rule of thumb, not a law automatically determining validity.

    Under perfect collinearity, not all coefficients are separately identifiable: multiple solutions can produce the same fitted values. Under approximate collinearity, a unique solution exists, but some combinations may be estimated unstably. Predictions within a narrow data region can be precise while individual slopes remain fragile.

    The metaphor of micronumerosity emphasises that information depends on design and independent variation, as well as row count. A high condition number caused by scale differences should not be mistaken for a unique structural diagnosis: centred and scaled matrices should also be examined.

    Economically, relationships between production, remuneration, and productivity generate observable restrictions. Connecting them with value theory requires explicit mediations. High VIFs do not, by themselves, establish a thesis about the origin of value.

    25Economic diagnostics: interpreting the combined results

    Published results, pp. 68–77: different hypotheses and calibrations are not interchangeable
    Documented procedureResultInterpretation at 5%, unless stated otherwise
    Shapiro–Wilk on the responsep = 0.0006404Reject marginal normality; this does not directly test error normality.
    Studentised Breusch–Paganp = 0.09915Do not reject homoskedasticity at 5%; reject at 10%. Non-rejection does not establish the absence of heteroskedasticity.
    Two-sided Durbin–Watson, carApproximate p = 0.072Do not reject at 5%; account for simulation-based calibration.
    One-sided Durbin–Watson, lmtestp = 0.03317Reject in favour of positive autocorrelation; this uses a different alternative.
    Breusch–Godfrey, up to order 1p = 0.2872Do not reject absence of autocorrelation up to that order.
    Breusch–Godfrey, up to order 2p = 0.5276Do not reject the joint hypothesis up to that order.
    Breusch–Godfrey, up to order 3p = 0.03631Reject the joint hypothesis; this does not separately identify each lag as significant.
    RESET, powers 2 and 3p = 0.0000675Evidence against functional form under the calibration used; it does not identify a specific cause.

    The default bptest() is the Koenker-studentised version of Breusch–Pagan. A general White test requires a suitable auxiliary specification, usually including squares and interactions; the names are not automatically synonymous.

    The Durbin–Watson results do not necessarily contradict each other: one-sided and two-sided alternatives ask different questions and can use different calibrations. Time-series analysis requires verifying year order, gaps, and the relevance of the lag structure.

    RESET detects certain functional-form departures through additional terms. Rejection does not identify multicollinearity as the cause. An omitted interaction, insufficient temporal dynamics, or other specifications may be relevant; diagnostics should guide justified comparisons.

    Cook’s distance should be interpreted in terms of the specific years. Crises or institutional changes may provide substantive information. A low Cook’s distance does not guarantee stability against every perturbation, and a high value does not justify deleting a year to improve fit.

    26HC and HAC standard errors: scope and calculation

    With a general error covariance matrix Ω, the covariance of OLS is:

    Var(β̂ | X) = (XTX)−1XTΩX(XTX)−1.
    (29)

    Robust estimators replace the unknown middle component with an estimate. HC handles heteroskedasticity under appropriate independence conditions. HAC also incorporates autocovariances of the estimator’s contributions. For Newey–West with a Bartlett kernel:

    V̂HAC = B[Γ̂0 + Σℓ=1…L(1 − ℓ/(L+1))(Γ̂ℓ + Γ̂ℓT)]B,   B = (XTX)−1.
    (30)

    Defining st = xtet, Γ̂ℓ sums stst−ℓT over available pairs. This formula uses unnormalised sums and may include the finite-sample adjustment n/(n − p). The lag choice L, kernel, and prewhitening must be reported because they affect the result.

    # Requires lmtest and sandwich. Data already ordered by Year.
    V_HAC <- sandwich::NeweyWest(m_eco, lag = 3,
                               prewhite = FALSE, adjust = TRUE)
    lmtest::coeftest(m_eco, vcov. = V_HAC, df = Inf)
    lmtest::coefci(m_eco, vcov. = V_HAC, df = Inf, level = .95)
    # Lag-truncation sensitivity; do not choose a lag based on its p-value.
    sapply(1:4, function(L) sqrt(diag(sandwich::NeweyWest(
      m_eco, lag = L, prewhite = FALSE, adjust = TRUE))))

    Specifying df=Inf makes the asymptotic normal reference explicit. A t approximation using residual degrees of freedom can be adopted as a finite-sample convention, but that change does not make it exact. With 45 observations, the performance of any approximation calls for care and sensitivity analysis.

    HAC covariance leaves OLS coefficients and fitted residuals unchanged. It does not remove autocorrelation, normalise errors, resolve endogeneity, or repair an identity treated as an independent mechanism. Its consistency requires conditions on moments and process dependence. The laboratory implements HC3 and HAC manually and checks HAC against sandwich when the package is available.

    27Time, trends, and predictive validation

    Sorting a plot by a predictor helps visualise an association, but joining those points does not represent a historical trajectory. To study evolution, use year on the horizontal axis and preserve chronological order. An upward and a downward trend can also share a temporal component; their opposite signs do not rule out spurious regression.

    Temporal assessment includes plots, autocorrelations, unit roots, stationarity, and possible breaks. The choice of intercept, trend, and lags in ADF, Phillips–Perron, or KPSS changes the question. A single p-value should not mechanically decide between levels and differences.

    For integrated variables, assess whether a justified cointegrating relationship exists. Differencing can reduce stochastic trends, but also changes the economic object. An accounting identity and a cointegrating relationship are not interchangeable concepts. HAC standard errors do not turn a spurious regression into a valid one.

    Predictive evaluation reserves future information. Rolling-origin validation fits the earliest years, predicts the next, and progressively expands the window. Variable selection, transformations, and standardisation, if used, are repeated using only each window’s training observations.

    RMSE = √[(1/m)Σ(yt − ŷt)²];   MAE = (1/m)Σ|yt − ŷt|.
    (31)

    Test metrics are compared with simple benchmarks, such as the last observed value. Ex ante forecasting also requires knowing or forecasting future covariates. Using contemporaneous values observed after the fact produces a retrospective conditional evaluation; that information availability must be declared.

    In swimming, appropriate validation considers how new participants enter and whether measurements are repeated or clustered by team. Randomly splitting rows does not guarantee independence when several belong to the same person or group.

    28Extensions justified by the question

    An extension should address a specific limitation. Interactions and nonlinear terms represent varying slopes; dynamic models incorporate lags and temporal processes; generalised least squares models a covariance structure when sufficiently justified.

    A gamma GLM may be appropriate for a strictly positive response whose conditional distribution and mean–variance relationship fit that family. The canonical link is inverse; the log link is a common choice with a different interpretation. The marginal shape of the profit rate does not decide between them or resolve temporal dependence.

    ARCH and GARCH describe dynamic conditional heteroskedasticity; they require evidence and a question warranting volatility modelling. Copulas study specified dependence structures. None of these names is automatically an improvement when the central problem concerns measurement, identification, or shared identities.

    Regularisation can stabilise prediction with correlated predictors, but changes the estimation problem and does not restore a lost causal interpretation. Choices are assessed against explicit objectives and validation appropriate to the design.

    29Theory, evidence, and the mediations of explanation

    Materialist research can examine how categories such as labour, capital, productivity, and distribution are expressed in empirical magnitudes without reducing their content to a data column. Mediation between category and measurement requires explicit coverage, units, historical context, and aggregation level.

    The relationship between essence and manifestation does not license treating every surface association as a necessary determination. Nor does it require separating abstraction from experience: formalisation selects relationships, states conditions, and makes specific implications testable. Its scope is strengthened by clarifying which aspects of the phenomenon remain outside the model.

    Nature’s material contribution to use-values must be distinguished from the Marxian thesis about labour and value under commodity relations. Attributing the exclusive production of all use-values to labour confuses different levels. Value theory, capital composition, and surplus accounting require their respective mediations.

    Limit theorems for dependent sequences are part of statistical theory. Laws of large numbers, central limit theorems, and ergodic results have different versions and conditions; independence is not a universal requirement of all of them. The applied question is whether the process being studied meets the conditions of the result invoked.

    A striking empirical fit can motivate further questions, but its magnitude does not suspend those conditions. In the economic case, investigating accounting identities and historical variation helps distinguish definitional regularities, estimated associations, and mechanisms requiring additional identification.

    30What the two cases support

    In the documented biostatistical tables, age shows a negative association with conditional speed, and the four-predictor set improves fit relative both to a common mean and to the age-only model. This applies to the sample, specifications, and assumptions: it does not establish an individual ageing effect or automatically represent the entire adult population.

    The United States exercise documents an additive reconstruction with extremely high in-sample fit, accompanied by strong collinearity and diagnostics calling for reassessment of functional form and dependence. Variable construction requires checking identities before assigning independent meanings to slopes. The evidence presented is insufficient to certify out-of-sample forecasting performance or already-corrected HAC inference.

    The shared methodological lesson is that regression is evaluated across connected dimensions: coherent measurement, algebraic identification, probabilistic assumptions, numerical stability, predictive performance, and substantive interpretation. Each contributes a condition of validity; none completely substitutes for the others.

    III · Laboratory and references

    31A complete reproducible laboratory in R

    The following code includes generated data, manual-calculation functions, and the required checks. It runs on R 4.1 or later and uses base R for its core operations. Extensions using lmtest, sandwich, and tolerance run only if those packages are installed; they are not installed automatically.

    The first laboratory generates a cross-sectional swimming sample. The second constructs synthetic macroeconomic series satisfying known identities. This construction makes it possible to study how additive regression achieves a good fit without discovering a new causal mechanism. Diagnostic tests on that simulation serve a computational purpose and do not represent United States findings.

    The program also reconstructs R², adjusted R², and F tests from published sums of squares, without confusing that arithmetic check with recovery of the microdata. It verifies agreement between matrix estimates and lm(), unit invariance, standardisation, manual and automated intervals, and, when sandwich is available, the manual HAC calculation.

    To save plots when running from a console, open a device beforehand with pdf("regression_laboratory.pdf") and close it afterwards using dev.off(). In RStudio, plots can be inspected in the graphics panel.

    Synthetic laboratory results: R 4.3.3; seeds specified in the code
    Executed synthetic resultValue
    Swimming: R² / adjusted R²0.7446455 / 0.7037888
    Swimming: residual sum of squares0.4150405
    Macroeconomics: additive R²0.9999556
    Macroeconomics: interactive identity coefficients100 and −100
    Rolling origin: model / last-value RMSE0.01383205 / 0.18606987
    Rolling origin: model / last-value MAE0.01101683 / 0.17496457

    These outputs were obtained by executing the laboratory. The algebraic equalities enforced through stopifnot() passed, including the comparison between manual HAC and sandwich. The optional tolerance example was not executed in that verification. Synthetic results are not estimates from the empirical studies.

    # LINEAR REGRESSION: BIOSTATISTICS AND POLITICAL ECONOMY
    # Jose Mauricio Gomez Julian | Revised: 2026-11-04
    # Run after saving this code: source("regression_laboratory.R", encoding = "UTF-8")
    # Base R; does not install packages or download data.
    # Both laboratories use SYNTHETIC data. They do not replicate the 2021 samples.
    options(width = 110)
    
    validar <- function(d, columnas) {
      stopifnot(is.data.frame(d), all(columnas %in% names(d)))
      if (!all(vapply(d[columnas], is.numeric, logical(1))))
        stop("Required columns must be numeric.")
      if (any(!is.finite(as.matrix(d[columnas]))))
        stop("NA, NaN or Inf detected: document their treatment before fitting.")
      invisible(d)
    }
    
    # QR estimation and algebraic verification for full-rank models with an intercept.
    resumen_manual <- function(m) {
      X <- model.matrix(m); y <- model.response(model.frame(m))
      n <- nrow(X); p <- ncol(X)
      stopifnot(m$rank == p, n > p, attr(terms(m), "intercept") == 1)
      b <- qr.coef(qr(X), y)
      yhat <- drop(X %*% b); e <- y - yhat
      SSE <- sum(e^2); SST <- sum((y - mean(y))^2); SSR <- sum((yhat - mean(y))^2)
      s2 <- SSE / (n - p)
      V <- summary(m)$cov.unscaled[colnames(X), colnames(X), drop = FALSE] * s2
      se <- sqrt(diag(V)); crit <- qt(.975, n - p)
      IC <- cbind(estimate = b, EE = se, lower = b - crit * se, upper = b + crit * se)
      stopifnot(isTRUE(all.equal(unname(b), unname(coef(m)), tolerance = 1e-8)),
                abs(SST - SSR - SSE) < 1e-7 * max(1, SST),
                isTRUE(all.equal(unname(V), unname(vcov(m)), tolerance = 1e-8)),
                isTRUE(all.equal(unname(IC[, c("lower", "upper")]),
                                 unname(confint(m)), tolerance = 1e-8)))
      list(n = n, p = p, SST = SST, SSR = SSR, SSE = SSE, s2 = s2,
           R2 = 1 - SSE / SST, R2_ajustado = 1 - (SSE / (n - p)) / (SST / (n - 1)), IC = IC)
    }
    
    vif_manual <- function(m) {
      X <- model.matrix(m)[, -1, drop = FALSE]
      stopifnot(ncol(X) > 1L)
      vapply(seq_len(ncol(X)), function(j) {
        aux <- lm(X[, j] ~ X[, -j, drop = FALSE])
        1 / (1 - summary(aux)$r.squared)
      }, numeric(1)) |> setNames(colnames(X))
    }
    
    # HC3 matrix: heteroskedasticity adjustment under exogeneity and independent observations.
    vcov_hc3_manual <- function(m) {
      X <- model.matrix(m); e <- residuals(m); h <- hatvalues(m)
      stopifnot(m$rank == ncol(X), all(h < 1))
      B <- summary(m)$cov.unscaled[colnames(X), colnames(X), drop = FALSE]
      S <- X * as.numeric(e / (1 - h))
      V <- B %*% crossprod(S) %*% B
      dimnames(V) <- list(colnames(X), colnames(X)); V
    }
    
    # Newey-West HAC with a Bartlett kernel and no prewhitening; chronological order is required.
    vcov_hac_manual <- function(m, lag = 3L, adjust = TRUE) {
      X <- model.matrix(m); n <- nrow(X); p <- ncol(X)
      stopifnot(m$rank == p, lag >= 0, lag < n, lag == as.integer(lag))
      B <- summary(m)$cov.unscaled[colnames(X), colnames(X), drop = FALSE]
      S <- X * as.numeric(residuals(m)); M <- crossprod(S)
      if (lag > 0L) for (ell in seq_len(lag)) {
        C <- crossprod(S[(ell + 1L):n, , drop = FALSE], S[1L:(n - ell), , drop = FALSE])
        M <- M + (1 - ell / (lag + 1)) * (C + t(C))
      }
      V <- B %*% M %*% B
      if (adjust) V <- V * n / (n - p)
      dimnames(V) <- list(colnames(X), colnames(X)); V
    }
    
    inferencia_robusta <- function(m, V, nivel = .95) {
      # Asymptotic normal approximation: not an exact finite-sample t distribution.
      b <- coef(m); se <- sqrt(diag(V)); z <- b / se
      q <- qnorm(1 - (1 - nivel) / 2)
      cbind(estimate = b, EE = se, z = z, p = 2 * pnorm(-abs(z)),
            lower = b - q * se, upper = b + q * se)
    }
    
    intervalos_manuales <- function(m, nuevos, nivel = .95) {
      X0 <- model.matrix(delete.response(terms(m)), nuevos, contrasts.arg = m$contrasts)
      X0 <- X0[, names(coef(m)), drop = FALSE]
      media <- drop(X0 %*% coef(m))
      vmedia <- rowSums((X0 %*% vcov(m)) * X0)
      q <- qt(1 - (1 - nivel) / 2, df.residual(m))
      IC <- cbind(fit = media, lwr = media - q * sqrt(vmedia), upr = media + q * sqrt(vmedia))
      IP <- cbind(fit = media, lwr = media - q * sqrt(vmedia + sigma(m)^2),
                  upr = media + q * sqrt(vmedia + sigma(m)^2))
      stopifnot(isTRUE(all.equal(unname(IC), unname(predict(m, nuevos, interval = "confidence", level = nivel)), tolerance = 1e-7)),
                isTRUE(all.equal(unname(IP), unname(predict(m, nuevos, interval = "prediction", level = nivel)), tolerance = 1e-7)))
      list(confidence = IC, prediction = IP)
    }
    
    # A. SYNTHETIC BIOSTATISTICS LABORATORY
    set.seed(20261104)
    n <- 30L
    edad <- sample(18:51, n, replace = TRUE)
    sexo <- rep(0:1, length.out = n)
    z <- rnorm(n)
    brazo <- 74 + 3.5 * z + rnorm(n, sd = 1.8)
    pierna <- 103 + 5 * z + rnorm(n, sd = 2.5)
    imc <- 23 + rnorm(n, sd = 3)
    veloc <- .30 - .018 * edad + .022 * brazo + .008 * (imc - 23) + rnorm(n, sd = .13)
    bio <- data.frame(veloc, edad, sexo, imc, pierna, brazo)
    validar(bio, names(bio)); stopifnot(all(bio$veloc > 0))
    cat("\nA. SYNTHETIC SWIMMING DATA; NOT OBSERVATIONS FROM THE STUDY\n")
    print(head(bio))
    
    m_bio <- lm(veloc ~ edad + imc + pierna + brazo, data = bio)
    m_edad <- lm(veloc ~ edad, data = bio)
    m_sin_edad <- lm(veloc ~ imc + pierna + brazo, data = bio)
    m_dos <- lm(veloc ~ edad + brazo, data = bio)
    print(summary(m_bio)); print(resumen_manual(m_bio))
    print(cor(bio[c("veloc", "edad", "imc", "pierna", "brazo")]))
    
    # Unit change: fitted values do not change; the coefficient is divided by ten.
    bio$brazomm <- 10 * bio$brazo
    m_mm <- lm(veloc ~ edad + imc + pierna + brazomm, data = bio)
    stopifnot(max(abs(fitted(m_bio) - fitted(m_mm))) < 1e-8,
              abs(coef(m_bio)["brazo"] / 10 - coef(m_mm)["brazomm"]) < 1e-8)
    
    # Standardisation: same sample and same four predictors.
    vars <- c("veloc", "edad", "imc", "pierna", "brazo")
    bio_z <- as.data.frame(scale(bio[vars]))
    m_z <- lm(veloc ~ edad + imc + pierna + brazo, data = bio_z)
    beta_z <- coef(m_bio)[-1] * vapply(bio[names(coef(m_bio))[-1]], sd, numeric(1)) / sd(bio$veloc)
    Rxx <- cor(bio[vars[-1]]); rxy <- cor(bio[vars[-1]], bio$veloc)
    stopifnot(max(abs(beta_z - coef(m_z)[-1])) < 1e-8,
              max(abs(drop(solve(Rxx, rxy)) - beta_z)) < 1e-8)
    print(beta_z)
    print(anova(m_edad, m_bio))
    print(anova(m_sin_edad, m_bio))
    stopifnot(abs(anova(m_sin_edad, m_bio)$F[2] - summary(m_bio)$coef["edad", "t value"]^2) < 1e-7)
    
    nuevos <- data.frame(edad = 22, imc = 20, pierna = 100, brazo = 70)
    print(intervalos_manuales(m_bio, nuevos))
    print(vif_manual(m_bio))
    print(inferencia_robusta(m_bio, vcov_hc3_manual(m_bio)))
    cat("Residual Shapiro-Wilk: exploratory; it neither tests exogeneity nor confirms normality.\n")
    print(shapiro.test(residuals(m_bio)))
    cat("Changing term order alters sequential ANOVA, not fitted slopes.\n")
    print(anova(m_bio))
    print(anova(lm(veloc ~ brazo + pierna + imc + edad, data = bio)))
    
    # Base plots. With source(), a non-interactive device may generate Rplots.pdf.
    op <- par(no.readonly = TRUE)
    par(mfrow = c(2, 2)); plot(m_bio); par(op)
    grilla <- data.frame(edad = seq(min(bio$edad), max(bio$edad), length.out = 100))
    ic <- predict(m_edad, grilla, interval = "confidence")
    ip <- predict(m_edad, grilla, interval = "prediction")
    plot(bio$edad, bio$veloc, xlab = "Age (years)", ylab = "Speed (m/s)", pch = 19,
         main = "Synthetic laboratory: mean and uncertainty")
    matlines(grilla$edad, cbind(ic, ip[, -1]), lty = c(1, 2, 2, 3, 3), col = "#8b4513")
    legend("topright", c("Media", "Mean CI", "Individual PI"), lty = 1:3, bty = "n")
    
    # B. VERIFICATION OF DOCUMENTED RESULTS USING ROUNDED SUMS OF SQUARES
    # This arithmetic checks consistency between tables; it does not refit the original data.
    SST_doc <- 1.730004
    SSE_doc <- c(complete = .64517, without_age = 1.56336, edad = .99021)
    p_doc <- c(complete = 5, without_age = 4, edad = 2)
    R2_doc <- 1 - SSE_doc / SST_doc
    R2a_doc <- 1 - (SSE_doc / (30 - p_doc)) / (SST_doc / 29)
    print(data.frame(SSE = SSE_doc, R2 = R2_doc, R2_ajustado = R2a_doc))
    F_extra <- ((SSE_doc["edad"] - SSE_doc["complete"]) / 3) / (SSE_doc["complete"] / 25)
    F_edad <- ((SSE_doc["without_age"] - SSE_doc["complete"]) / 1) / (SSE_doc["complete"] / 25)
    F_global <- ((SST_doc - SSE_doc["complete"]) / 4) / (SSE_doc["complete"] / 25)
    print(data.frame(test = c("Three additional variables", "Conditional age", "Global"),
                     F = c(F_extra, F_edad, F_global),
                     p = c(pf(F_extra, 3, 25, lower.tail = FALSE),
                           pf(F_edad, 1, 25, lower.tail = FALSE),
                           pf(F_global, 4, 25, lower.tail = FALSE))))
    
    # C. SYNTHETIC MACROECONOMIC LABORATORY
    # An accounting identity generates the response: this is not a causal test.
    set.seed(20261105)
    Year <- 1964:2008; n <- length(Year); t <- seq_len(n)
    L_Productivity <- 45000 * exp(.014 * (t - 1)) * (1 + .02 * sin(t / 3))
    Mean_w_share <- .62 - .001 * (t - 1) + .008 * sin(t / 4)
    K_Productivity <- .88 - .005 * (t - 1) + .025 * cos(t / 5)
    Mean_w <- Mean_w_share * L_Productivity
    Mean_Gross_Profit <- 100 * (1 - Mean_w_share) * K_Productivity
    # Additional variables available in each year, also synthetic.
    empleo <- 90000000 * exp(.009 * (t - 1))
    RealGDP <- L_Productivity * empleo
    K_Net_Stock <- RealGDP / K_Productivity
    DepreciationRate <- 4.5 + .1 * sin(t / 6)
    eco <- data.frame(Year, RealGDP, K_Net_Stock, DepreciationRate,
                      K_Productivity, L_Productivity, Mean_w_share, Mean_w, Mean_Gross_Profit)
    validar(eco, names(eco)); eco <- eco[order(eco$Year), ]
    cat("\nC. SYNTHETIC MACROECONOMICS WITH AN EXACT ACCOUNTING IDENTITY\n")
    print(head(eco))
    print(c(profit_identity_error = max(abs(eco$Mean_Gross_Profit - 100 * (1 - eco$Mean_w_share) * eco$K_Productivity)),
            wage_identity_error = max(abs(eco$Mean_w - eco$Mean_w_share * eco$L_Productivity))))
    
    m_eco <- lm(Mean_Gross_Profit ~ Mean_w_share + L_Productivity + K_Productivity + Mean_w, data = eco)
    print(summary(m_eco)); print(resumen_manual(m_eco)); print(vif_manual(m_eco))
    V_HAC <- vcov_hac_manual(m_eco, lag = 3, adjust = TRUE)
    print(inferencia_robusta(m_eco, V_HAC))
    print(sapply(1:4, function(L) sqrt(diag(vcov_hac_manual(m_eco, lag = L)))))
    cat("HAC is shown as a calculation: inferential validity requires additional assumptions.\n")
    
    # Exact interaction: this regression reconstructs a known data identity.
    m_identidad <- lm(Mean_Gross_Profit ~ K_Productivity + K_Productivity:Mean_w_share - 1, data = eco)
    stopifnot(max(abs(fitted(m_identidad) - eco$Mean_Gross_Profit)) < 1e-8)
    print(coef(m_identidad))
    # No t tests are printed for this deterministic identity: they have no inferential purpose.
    
    # BIC: stepwise selection is a local search. Compare with the proposed theoretical model.
    m_amplio <- lm(Mean_Gross_Profit ~ Year + RealGDP + K_Net_Stock + DepreciationRate +
                     K_Productivity + L_Productivity + Mean_w_share + Mean_w, data = eco)
    m_bic <- step(m_amplio, direction = "backward", k = log(nobs(m_amplio)), trace = 0)
    print(formula(m_bic)); print(BIC(m_amplio, m_bic, m_eco))
    
    # Rolling-origin validation. Covariates for the evaluation year are treated as known.
    # This is therefore retrospective conditional prediction, not a complete ex ante forecast.
    formula_eco <- formula(m_eco)
    pred <- rep(NA_real_, n); base_ingenua <- rep(NA_real_, n)
    inicio <- 25L
    for (i in inicio:(n - 1L)) {
      entrenamiento <- eco[seq_len(i), ]
      ajuste <- lm(formula_eco, data = entrenamiento)
      pred[i + 1L] <- predict(ajuste, newdata = eco[i + 1L, ])
      base_ingenua[i + 1L] <- eco$Mean_Gross_Profit[i]
    }
    idx <- which(is.finite(pred))
    metricas <- function(y, yhat) c(RMSE = sqrt(mean((y - yhat)^2)), MAE = mean(abs(y - yhat)))
    print(rbind(model = metricas(eco$Mean_Gross_Profit[idx], pred[idx]),
                last_value = metricas(eco$Mean_Gross_Profit[idx], base_ingenua[idx])))
    plot(eco$Year, eco$Mean_Gross_Profit, type = "l", col = "#2c2418", xlab = "Year", ylab = "Rate (%)",
         main = "Synthetic identity and conditional prediction")
    lines(eco$Year, fitted(m_eco), col = "#8b4513", lty = 2)
    lines(eco$Year[idx], pred[idx], col = "#c4956a", lty = 3)
    legend("topright", c("Identity", "Additive fit", "Rolling origin"), lty = 1:3,
           col = c("#2c2418", "#8b4513", "#c4956a"), bty = "n")
    
    # D. OPTIONAL DIAGNOSTICS: packages are not installed automatically.
    if (requireNamespace("lmtest", quietly = TRUE) && requireNamespace("sandwich", quietly = TRUE)) {
      print(lmtest::bptest(m_eco))
      for (L in 1:3) print(lmtest::bgtest(m_eco, order = L))
      print(lmtest::dwtest(m_eco, alternative = "two.sided"))
      print(lmtest::resettest(m_eco, power = 2:3, type = "fitted"))
      V_pkg <- sandwich::NeweyWest(m_eco, lag = 3, prewhite = FALSE, adjust = TRUE)
      # Compare manual HAC with the package implementation.
      stopifnot(isTRUE(all.equal(unname(V_HAC), unname(V_pkg), tolerance = 1e-5)))
      print(lmtest::coeftest(m_eco, vcov. = V_pkg, df = Inf))
    } else cat("\nOptional packages not installed: lmtest and sandwich. The base laboratory is already complete.\n")
    
    # Marginal normal tolerance: a different question, without conditioning on covariates.
    if (requireNamespace("tolerance", quietly = TRUE)) {
      set.seed(20261106)
      poblacion_normal_demo <- rnorm(60, mean = 1.4, sd = .16)
      print(tolerance::normtol.int(poblacion_normal_demo, alpha = .05, P = .95, side = 2, method = "HE"))
    } else cat("\nOptional package not installed: tolerance. Its function results are not fabricated.\n")
    
    # Import original empirical data when available:
    # entorno <- new.env(parent = baseenv())
    # objetos <- load("velo.Rdata", envir = entorno)
    # stopifnot("base" %in% objetos)
    # bio_real <- entorno$base
    # validar(bio_real, c("veloc", "edad", "sexo", "imc", "pierna", "brazo"))
    # m_real <- lm(veloc ~ edad + imc + pierna + brazo, data = bio_real)
    # if (requireNamespace("readxl", quietly = TRUE)) {
    #   eco_real <- as.data.frame(readxl::read_excel("DATOS.xlsx"))
    #   validar(eco_real, names(eco))
    #   eco_real <- eco_real[order(eco_real$Year), ]
    #   stopifnot(!anyDuplicated(eco_real$Year), all(diff(eco_real$Year) == 1))
    # }
    
    cat("\nAlgebraic checks completed. Versions and platform:\n")
    print(sessionInfo())

    To apply these functions to empirical data, explicitly replace the synthetic objects with the original files, check the dictionary, and retain the database edition. The final import code remains commented out so execution cannot silently depend on missing files.

    32A glossary of essential distinctions

    Vocabulary for interpreting the analysis
    ConceptsOperational distinction
    Error / residualThe error belongs to the population model; the residual is computed after fitting.
    Fit / forecastFitting uses the estimation sample; forecasting evaluates unused observations under a defined information set.
    Mean / individual / population contentThese motivate different confidence, prediction, and tolerance intervals.
    Collinearity / endogeneityThe former concerns identification or precision through predictor relationships; the latter connects regressors to the error.
    Orthogonality / independenceA zero inner product is not equivalent to distributional factorisation.
    Significance / magnitudeA p-value alone does not measure an association’s size, usefulness, or importance.
    Identity / mechanismA definitional equality does not, by itself, explain changes in its components.
    Robust covariance / corrected modelHC or HAC adjusts inference under conditions; it does not repair every specification problem.
    Gross rate / net rateThe latter incorporates a coherent treatment of depreciation.
    Statistical construction / arbitrarinessMeasurement conventions require justification and can be assessed objectively.

    33References and further reading

    Technical sources allow readers to verify what each function calculates. Political-economy references supply the conceptual and historical framework and should be read in relation to their specific research questions.

    1. Original study and numerical results. Gómez Julián, José Mauricio, published under the name Isadore Nabi. Applications of the Classical Linear Regression Model in R: A Theoretical and Applied Analysis (Spanish-language document). Dated October 9, 2021; blog post published December 1, 2021. View source.
    2. OLS estimation in R. R Core Team. lm() documentation: specification, design matrix, and QR calculation. View source.
    3. Prediction and intervals. R Core Team. predict.lm() documentation. View source.
    4. Sequential ANOVA. R Core Team. anova.lm() documentation. View source.
    5. Stepwise selection. R Core Team. step() documentation. View source.
    6. Kolmogorov–Smirnov. R Core Team. ks.test() documentation. View source.
    7. Normal tolerance. Young, Derek S. (2017). “Normal Tolerance Interval Procedures in the tolerance Package”. The R Journal, 8(2), 200–212. DOI: 10.32614/RJ-2016-041. View source.
    8. Inference and covariance. lmtest package documentation: coeftest() and coefci(). View source.
    9. Heteroskedasticity. bptest() documentation, including references to Breusch–Pagan and Koenker. View source.
    10. Autocorrelation. bgtest() documentation. View source.
    11. Functional form. resettest() documentation, with reference to Ramsey (1969). View source.
    12. Nature, labour, and use-values. Marx, Karl (1875). Critique of the Gotha Programme, Part I. View source.
    13. HAC covariance. Newey and West (1987, 1994); sandwich::NeweyWest() documentation. View source.
    14. Robust computation. Zeileis, Achim (2004). “Econometric Computing with HC and HAC Covariance Matrix Estimators”. Journal of Statistical Software, 11(10). DOI: 10.18637/jss.v011.i10. View source.
    15. Profitability identity in EPWT. Elveren, Adem Y., and Sara Hsu (2015). Military Expenditures and Profit Rate: Evidence from OECD Countries. PERI Working Paper 374, Section 4.1. Consulted copy of the research paper. View source.

    Contextual bibliography: Smith, The Wealth of Nations; Ricardo, On the Principles of Political Economy and Taxation; Marx, Capital, particularly Volumes I and III, and Critique of the Gotha Programme for the distinction concerning nature and use-values; Samuelson (1966), “A Summing Up”, The Quarterly Journal of Economics, 80(4), 568–583; Gujarati and Porter (2010), Econometría, fifth edition; Greene (2012), Econometric Analysis, seventh edition; Farjoun and Machover (1983), Laws of Chaos; Kuhn, The Structure of Scientific Revolutions. Additional references and the editions used in the study are listed in its bibliography.

    EPWT and the Penn World Table are not interchangeable databases. Empirical replication requires retaining the EPWT version, the file used, the transformations, and the correspondence between theoretical categories and statistical columns.
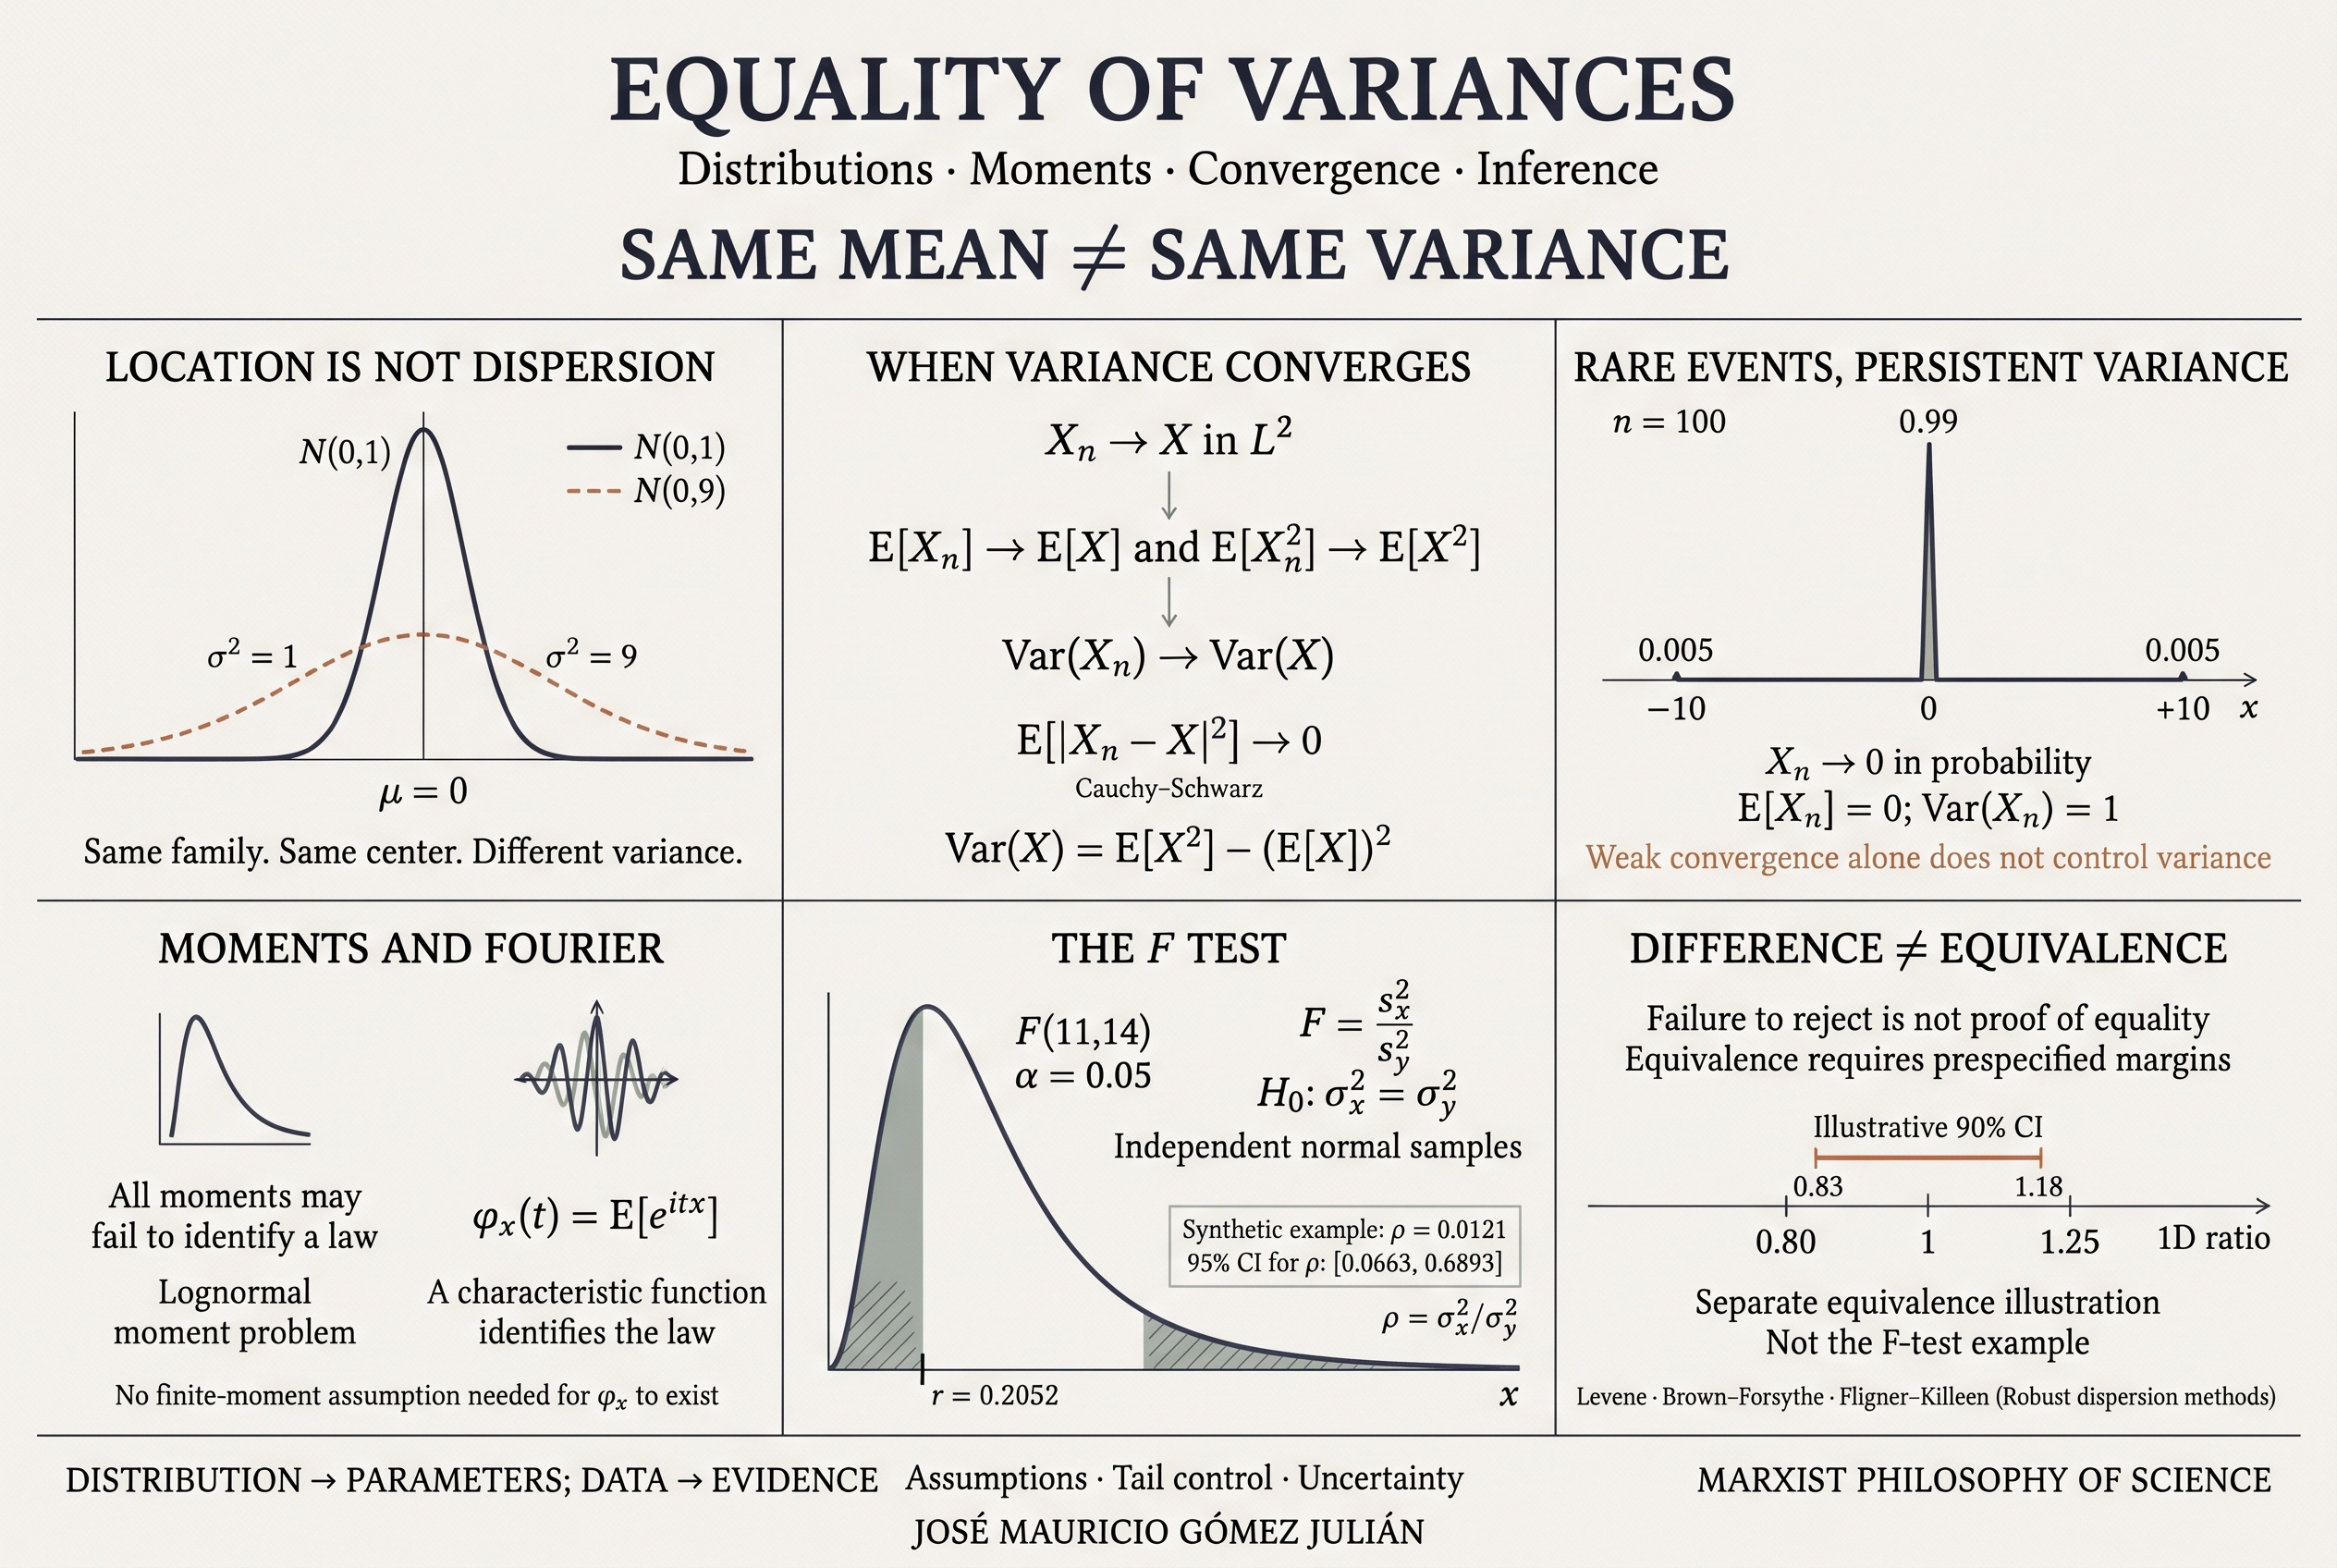
  • A THEORETICAL APPROACH TO DETERMINING THE EQUALITY OF VARIANCES OF TWO POPULATIONS

    A THEORETICAL APPROACH TO DETERMINING THE EQUALITY OF VARIANCES OF TWO POPULATIONS

    Marxist Philosophy of Science
    Mathematical statistics · theory and application

    A Theoretical Approach to Equality of Variances in Two Populations

    Distributions, Moments, Convergence, and Statistical Inference

    Originally published:
    Revised:

    Abstract

    Equal means and similar shapes do not guarantee equal variances. This essay connects the mathematical conditions that justify equality with estimation, the F test, robust alternatives, and practical equivalence through proofs, counterexamples, and a reproducible R example.

    01The question: what does equality of variances mean?

    Comparing two populations requires distinguishing their location, dispersion, and complete probability distributions. A mean describes a center; a variance measures quadratic dispersion around that center. Equality of one characteristic does not automatically imply equality of the others.

    Let X and Y be real random variables with finite second moments. The question is whether their population parameters satisfy σX2 = σY2. With samples alone, we observe estimates of these parameters and must quantify their uncertainty. A mathematical identity, an asymptotic approximation, and an inferential conclusion answer different questions.

    02Means, moments, and dispersion

    An order-r raw moment is an expectation of powers. A central moment instead uses deviations from the mean. For ordinary positive integer moments, assume absolute integrability: E[|X|r] < ∞.

    mr = E[Xr]
    μr = E[(X − E[X])r]

    The first raw moment is the mean; the first central moment is zero.

    Var(X) = E[(X − μ)2]
    = E[X2] − μ2,   μ = E[X]

    Variance is the second central moment. It equals E[X²] only when μ = 0.

    Squaring prevents positive and negative deviations from canceling and gives greater weight to larger deviations. If a variable is measured in meters, its variance is measured in square meters; its standard deviation returns dispersion to the original unit.

    We must also distinguish the parameter σ2, the random estimator S2, and its observed value s2. A population moment is not, by definition, a test statistic.

    03What implies what: distribution, location, and scale

    Basic logical relationships
    ConditionValid conclusion
    X and Y have the same lawTheir moments agree whenever they exist; in particular, their finite variances agree.
    E[X] = E[Y]This does not determine variance.
    Same normal family and same meanVariances can still differ.
    Var(X) = Var(Y)This determines neither the mean nor the complete distribution.
    Equal sample sizesThis imposes no equality on population parameters.
    A nonsignificant testThis establishes neither equality nor practical equivalence.
    X ∼ N(0, 1),   Y ∼ N(0, 9)
    E[X] = E[Y] = 0;   Var(X) = 1 ≠ 9 = Var(Y)

    Our notation is N(μ, σ²): the second parameter is the variance.

    A scale transformation changes variance itself: Var(a + bX) = b2Var(X). Preserving standardized shape therefore need not preserve dispersion in the original units.

    Same mean; different dispersionTwo normal densities centered at zero: variances one and nine. −8 −6 −4 −2 0 2 4 6 8 x 0.00 0.05 0.10 0.15 0.20 0.25 0.30 0.35 0.40 Density Same mean; different dispersion N(0, 1) · σ² = 1 N(0, 9) · σ² = 9
    Figure 1. Two normal populations with identical means. The wider curve has three times the standard deviation and nine times the variance. Each density integrates to one.

    The reverse implication also fails: a standard normal variable and a variable taking −1 and 1 with probability 1/2 both have mean zero and variance one, although one is continuous and the other discrete.

    04Lʳ convergence and mean-square convergence

    Convergence concerns a sequence of random variables and a limit, rather than an informal resemblance between two samples. For r ≥ 1, with the variables defined on the same probability space, Lr convergence means:

    Xn → X in Lr   ⇔   E[|Xn − X|r] → 0

    The case r = 1 is convergence in mean; r = 2 is mean-square convergence.

    Convergence of E[Xn] to E[X] alone does not give L1 convergence: the expectation of a signed difference can conceal cancellations. L1 distance uses the absolute value. Likewise, a test of means does not measure the L2 distance between variables.

    In L2, the norm ‖X‖2 = (E[|X|2])1/2 arises from the inner product E[XY]. This Hilbert-space structure explains the usefulness of quadratic tools; it does not turn every kind of convergence into L2 convergence. Probability theory also studies other Lr spaces. [1]

    Proof: controlling the first and second moments

    Cauchy–Schwarz, also applied to the constant random variable one, gives:

    |E[Xn] − E[X]| ≤ ‖Xn − X‖2 → 0

    For the squares, factor the difference and apply Cauchy–Schwarz again:

    |E[Xn2] − E[X2]|
    ≤ ‖Xn − X‖2 · ‖Xn + X‖2 → 0

    The second norm is bounded because ‖Xₙ + X‖₂ ≤ ‖Xₙ − X‖₂ + 2‖X‖₂.

    Finally, use Var(Xn) = E[Xn2] − E[Xn]2. The result is convergence to a limit, with no arbitrary residual constant.

    05Why convergence in distribution is not enough

    The chain L2 ⇒ convergence in probability ⇒ convergence in distribution is valid; the reverse implications fail in general. Convergence in distribution controls expectations of bounded continuous functions, whereas x2 is unbounded.

    For each integer n ≥ 1, consider a variable whose mass increasingly concentrates at zero, while retaining rare and increasingly extreme events:

    P(Xn = √n) = P(Xn = −√n) = 1/(2n)
    P(Xn = 0) = 1 − 1/n

    The two extreme probabilities add to 1/n; all three probabilities add to one.

    For any ε > 0 and sufficiently large n, P(|Xn| > ε) = 1/n → 0. Hence Xn → 0 in probability and in distribution. Nevertheless:

    E[Xn] = 0;
    E[Xn2] = n · (1/n) = 1;
    Var(Xn) = 1 ≠ 0 = Var(0)

    Decreasing frequency and increasing magnitude of the extremes offset each other exactly.

    This example even converges to zero in L1, since E[|Xn|] = 1/√n → 0, yet its variances still fail to converge to the variance of the limit.

    A sufficient additional condition for convergence in distribution to yield convergence of the first two moments is uniform integrability of the squares:

    limK→∞ supn E[Xn2 · 1{Xₙ² > K}] = 0

    This prevents a persistent share of the second moment from escaping into increasingly distant tails.

    For example, supnE[|Xn|2+δ] < ∞ for some δ > 0 is sufficient for this control. Bounded second moments alone are insufficient, as the counterexample shows. [1]

    06Existence of moments and determination of the distribution

    Once a distribution is fixed, every existing moment has a definite value. A separate question is whether knowing all the moments uniquely identifies that distribution. This is the moment problem. Having finite moments of every order does not, by itself, solve it.

    Distributions with finite support or support contained in a compact interval are determined by their moments. Countability of an infinite support alone is insufficient. General sufficient conditions include a moment-generating function finite on an open neighborhood of zero and Carleman’s criterion. These conditions also cover continuous distributions. [2]

    An explicit example: a family sharing the lognormal moments

    Let f0 be the standard lognormal density, meaning log(X) ∼ N(0,1). For −1 ≤ a ≤ 1, define:

    fa(x) = f0(x)[1 + a sin(2π log x)],   x > 0

    The bracketed factor is nonnegative. The perturbation integrates to zero and preserves normalization.

    For every integer k ≥ 0, substituting z = log x and using the normal transform gives:

    ∫0∞ xk f0(x) sin(2π log x) dx
    = exp(k2/2 − 2π2) sin(2πk) = 0

    The oscillation disappears in every integer moment, even though the densities change with a.

    These distinct densities therefore have exactly the same moments E[Xk] = exp(k2/2). Comparing variances requires only the first two moments; identifying an entire distribution is a more demanding problem.

    07Characteristic functions and the Fourier transform

    A characteristic function provides a representation identifying the complete law of a real random variable. Its general definition uses the distribution as a measure, so it does not presume that a density exists:

    φX(t) = E[eitX] = ∫ℝ eitx dFX(x)

    When a density f exists, the integral becomes ∫ eⁱᵗˣ f(x) dx. The dF definition includes discrete and mixed laws.

    It exists for every real t because |eitX| = 1. Two variables have the same law if and only if their characteristic functions agree for every t. This uniqueness does not require moments to exist. [3]

    If E[X2] < ∞, derivatives at zero recover the relevant moments:

    φ′X(0) = iE[X],   φ″X(0) = −E[X2]
    Var(X) = −φ″X(0) − (E[X])2

    The whole function identifies the law; these two derivatives recover the mean and variance.

    The exponent’s sign and the Fourier normalization factors depend on the chosen convention. Here we use eitx. Inversion theorems, under their respective conditions, recover a measure or density; they do not introduce a free constant justifying an arbitrary difference between variances.

    Characteristic functions do not automatically make the moments of a sequence converge either. Pointwise convergence to a limiting characteristic function gives convergence in distribution, but passing to unbounded moments still requires additional tail control.

    08From populations to samples: consistency

    Let X1, …, Xn be independent and identically distributed observations from a population with finite second moment. The usual sample variance is:

    Sn2 = [1/(n − 1)] ∑i=1n(Xi − X̄n)2
    = [n/(n − 1)]{[1/n]∑i=1nXi2 − X̄n2}

    The n − 1 divisor makes this estimator unbiased under i.i.d. sampling; the second-line identity establishes consistency.

    The strong law of large numbers, applied to X and X2, gives X̄n → E[X] and n−1∑Xi2 → E[X2] almost surely. Thus Sn2 → σX2 almost surely. A finite fourth moment is unnecessary for this consistency, although certain results about its asymptotic distribution may require it.

    For two samples, as both sizes grow, the estimators converge to their respective parameters:

    SX,n2 − SY,m2 → σX2 − σY2

    The limit is zero if the population variances agree. Equal sample sizes n = m are unnecessary.

    If both samples are known to come from the same law, equality of the parameter is already part of that assumption. Their observed sample variances may still differ. If common origin is a conjecture, evidence must come from the data.

    This asymptotic argument is not automatically an approach to the size of a finite population: sampling without replacement changes dependence and design. Nor does it justify ignoring temporal correlation, clusters, or paired measurements.

    09The F test: assumptions, derivation, and interval

    For two independent samples, each i.i.d. from a normal population with positive variance, define ρ = σX2/σY2. Equality means ρ = 1. The two-sided test contrasts H0: ρ = 1 against H1: ρ ≠ 1. [4]

    [(n − 1)SX2]/σX2 ∼ χ2n−1
    [(m − 1)SY2]/σY2 ∼ χ2m−1

    Normality yields these chi-squared distributions; independent samples make the two normalized numerators independent.

    (SX2/SY2)/ρ ∼ Fn−1,m−1

    An F variable is a ratio of independent chi-squared variables, each divided by its degrees of freedom.

    Under H0, the statistic F = SX2/SY2 follows this distribution without the factor ρ. Degrees of freedom identify the numerator and denominator order; they must not be inadvertently interchanged.

    Let qu be the lower-tail quantile defined by P(Fn−1,m−1 ≤ qu) = u. At level α, reject when the observed ratio r lies outside [qα/2, q1−α/2]. This quantile convention agrees with R’s qf.

    p = min{1, 2 min[G(r), 1 − G(r)]}

    G is the F cumulative distribution function under H₀. This is the equal-tail two-sided version; computation uses the upper tail directly for numerical stability.

    CI1−α(ρ) = [r/q1−α/2,   r/qα/2]

    The interval comes from inverting the F/ρ pivot; inversion reverses the quantile order.

    The ratio is dimensionless. An interval containing one is compatible with equality at the corresponding level, but does not prove it. If reduced variability is the target, the one-sided direction should be specified before examining results. Normality is a condition for this exact result; a nonsignificant normality test cannot certify it. [5]

    10Robust alternatives and the scope of their hypotheses

    The classical F test is sensitive to departures from normality. For skewed data or extreme observations, consider procedures that do not rely on the same normal-theory pivot. Robustness must always be related to the design and the target parameter.

    Tools for assessing dispersion
    ProcedureConstruction and interpretation
    LeveneUses ANOVA to compare absolute deviations from group means.
    Brown–ForsytheA median-centered Levene variant that reduces the influence of extreme observations.
    Fligner–KilleenUses ranks and normal scores of median-centered absolute deviations.
    Resampling methodsRequire justified conditions; a naive permutation requires exchangeability, which equal variances alone do not imply.

    Brown–Forsythe constructs Zij = |Xij − mediani| and compares the means of Z across groups. Its calibration is approximate, unlike the exact normal-theory F test. When distributional shapes differ substantially, equal expected absolute deviations and equal variances are not generally equivalent. [6] [7]

    For a common location–scale family, interpretation as a scale comparison is more direct. If variance does not exist, as for a Cauchy law, the target must change, for example to a quantile-based measure of dispersion, and that change must be stated.

    If the substantive objective is to compare means, Welch’s test permits this without imposing equal variances. Mechanically choosing between Student and Welch after a preliminary variance test adds a selection step; the procedure should follow the design and inferential objective. [8]

    11Non-rejection, power, and practical equivalence

    A p-value greater than α means that the test supplies insufficient evidence to reject H0 at the chosen level. It is not the probability that H0 is true. An uninformative study may produce this result even when meaningful differences exist.

    Power is defined against a specific alternative: π(ρ) = Pρ(reject H0). For the equal-tail two-sided F test, a positive alternative ratio ρ, and normal-theory assumptions:

    π(ρ) = G(qα/2/ρ)
    + 1 − G(q1−α/2/ρ)

    The sample ratio has distribution ρF. Both quantiles and G use the design’s degrees of freedom.

    Hypothetical planning · α = 0.05 · independent normal samples
    n per groupPower at ρ = 0.5
    120.1885
    300.4478
    600.7517
    1200.9643

    These are prospective calculations for a specified scenario, rather than estimates derived from the example’s p-value. The relevant difference and the sample sizes should be planned together; equal means cannot replace that work.

    To establish practical equivalence, prespecify limits L and U representing tolerable differences, with 0 < L < 1 < U. The question becomes whether L < ρ < U:

    H0eq: ρ ≤ L or ρ ≥ U
    H1eq: L < ρ < U

    The equivalence null represents differences that are too large, rather than point equality.

    With two one-sided tests at level α, declare equivalence only when both reject. Under the normal model, this is equivalent to the two-sided 1 − 2α confidence interval for ρ lying entirely within (L,U). At α = 0.05 this uses a 90% interval, rather than a 95% interval.

    As a conceptual illustration, a 90% interval [0.83,1.18] would lie inside (0.80,1.25). These reciprocal margins express multiplicative tolerance; they are neither a universal recommendation nor results from the example below. The substantive problem must justify them.

    12A fully reproducible numerical example

    We use two synthetic samples generated from independent normal models X ∼ N(10,1) and Y ∼ N(10,4). Their population means agree by construction; their population variances differ. The vectors are fixed to six decimal places in the code, so the results do not depend on R’s random-number generator.

    Synthetic data · arbitrary measurement units
    SummarySample XSample Y
    Sample size1215
    Sample mean10.0123139.320673
    Sample variance0.6342243.090340
    r = sX2/sY2 = 0.205228
    df = (11,14);   p = 0.012080
    CI95%(ρ) = [0.066318, 0.689321]

    Decimal points match the code to make reproduction straightforward.

    At level 0.05, equality is rejected within the normal model. The interval lies below one: the evidence favors a smaller variance for X than for Y. The point estimate is about 20.5% of Y’s variance, but the interval shows substantial uncertainty. The population ratio used in simulation is 1/4; individual sample ratios need not match it exactly.

    The observed ratio against the null hypothesisF density with eleven and fourteen degrees of freedom, 2.5 percent critical tails, and observed ratio 0.2052. 0 1 2 3 4 5 F 0.0 0.2 0.4 0.6 0.8 Density under H₀ F = 0.2052 Two tails: α = 0.05 F(11, 14) The observed ratio against the null hypothesis
    Figure 2. The F(11,14) reference distribution under equal variances. Shaded regions are the two 2.5% critical tails; the dashed line marks the observed ratio.

    As sensitivity analyses, Brown–Forsythe yields F = 7.973726 and p = 0.009182; Fligner–Killeen yields χ² ≈ 6.840015 and p ≈ 0.008914. Agreement here does not make their hypotheses identical or establish universal robustness. Choose the primary method before searching for the most favorable result.

    13R code: computation, sensitivity, and diagnostics

    The code below uses only base R functions. It reproduces the test, checks its formulas, computes the two sensitivity analyses, and applies the equivalence criterion using illustrative margins. Q–Q plots and a boxplot support inspection without becoming an automatic assumptions test. Inferential validity still depends on the design and model.

    View complete code · copy and run in R or RStudio
    # Igualdad de varianzas / Equality of variances
    # Datos sinteticos fijos / Fixed synthetic data
    # R base: stats + graphics; no external packages.
    x <- c(9.867324, 10.005934, 9.230461, 10.707670,
           10.857477, 8.684811, 9.164998, 10.428310,
           9.504457, 10.836370, 11.206876, 9.653071)
    y <- c(10.769160, 11.227355, 10.982203, 8.646258,
           7.303017, 7.526147, 11.072729, 7.522827,
           8.943126, 8.643210, 9.186375, 12.431695,
           7.238559, 7.421358, 10.896078)
    stopifnot(all(is.finite(c(x, y))), var(x) > 0, var(y) > 0)
    
    # Resumen / Summary
    resumen <- data.frame(
      group = c("X", "Y"), n = c(length(x), length(y)),
      mean = c(mean(x), mean(y)), variance = c(var(x), var(y)))
    print(resumen, digits = 8)
    
    # F bilateral e IC / Two-sided F test and CI
    alpha <- 0.05
    nu1 <- length(x) - 1
    nu2 <- length(y) - 1
    r <- var(x) / var(y)
    test_F <- var.test(x, y, ratio = 1, conf.level = 1 - alpha)
    p_manual <- min(1, 2 * min(pf(r, nu1, nu2),
                             pf(r, nu1, nu2, lower.tail = FALSE)))
    ci_manual <- c(r / qf(1 - alpha/2, nu1, nu2),
                   r / qf(alpha/2, nu1, nu2))
    stopifnot(abs(unname(test_F$statistic) - r) < 1e-10,
              abs(test_F$p.value - p_manual) < 1e-10,
              max(abs(as.numeric(test_F$conf.int) - ci_manual)) < 1e-10)
    print(test_F)
    
    # Brown-Forsythe: ANOVA de desviaciones absolutas / of absolute deviations
    datos <- data.frame(
      value = c(x, y),
      group = factor(c(rep("X", length(x)), rep("Y", length(y)))))
    datos$absdev <- abs(datos$value -
                       ave(datos$value, datos$group, FUN = median))
    bf <- anova(lm(absdev ~ group, data = datos))
    print(bf)
    fk <- fligner.test(value ~ group, data = datos)
    print(fk)
    
    # Equivalencia / Equivalence: illustrative margins, not universal
    L <- 0.80
    U <- 1.25
    ci90 <- c(r / qf(1 - alpha, nu1, nu2),
              r / qf(alpha, nu1, nu2))
    p_lower <- pf(r / L, nu1, nu2, lower.tail = FALSE)
    p_upper <- pf(r / U, nu1, nu2)
    p_tost <- max(p_lower, p_upper)
    equivalent <- all(ci90 > L & ci90 < U)
    stopifnot(identical(equivalent, p_tost < alpha))
    print(list(CI90 = ci90, margins = c(L, U),
               p_TOST = p_tost, equivalent = equivalent))
    
    # Potencia prospectiva / Prospective power under independent normal samples
    power_F <- function(n1, n2, rho, alpha = 0.05) {
      stopifnot(n1 >= 2, n2 >= 2, n1 == as.integer(n1),
                n2 == as.integer(n2), rho > 0, alpha > 0, alpha < 1)
      df1 <- n1 - 1
      df2 <- n2 - 1
      q <- qf(c(alpha/2, 1 - alpha/2), df1, df2)
      pf(q[1]/rho, df1, df2) +
        pf(q[2]/rho, df1, df2, lower.tail = FALSE)
    }
    sizes <- c(12, 30, 60, 120)
    print(data.frame(n_per_group = sizes,
      power_rho_0.5 = vapply(sizes, function(n) power_F(n, n, 0.5), numeric(1))))
    stopifnot(abs(power_F(12, 15, 1) - alpha) < 1e-10)
    
    # Diagnosticos / Diagnostics; no automatic normality-test gate
    op <- par(mfrow = c(1, 3))
    boxplot(value ~ group, data = datos, col = "#fffdf7",
            border = "#8b4513", xlab = "Group", ylab = "Value")
    qqnorm(x, main = "X: normal Q-Q"); qqline(x, col = "#8b4513")
    qqnorm(y, main = "Y: normal Q-Q"); qqline(y, col = "#8b4513")
    par(op)
    sessionInfo()
    

    The manual calculation and var.test should agree numerically. This example does not establish equivalence within (0.80,1.25). Brown–Forsythe is implemented through ANOVA of absolute deviations, and fligner.test follows R’s documented procedure. [5] [7]

    14Homogeneity, the structure of the phenomenon, and abstraction

    Statistical homogeneity must be specified: equal variances, equal distributions, and exchangeability are distinct properties. Their relevance depends on the unit of analysis, measurement scale, selection process, and relationships among observations.

    A population mixing subgroups shows how the phenomenon’s structure enters total variability. If G identifies the subgroup and X has finite second moment, the law of total variance states:

    Var(X) = E[Var(X | G)] + Var(E[X | G])

    Total dispersion includes variability within groups and variability between their means.

    Two populations can have identical within-subgroup variances yet different total variances when the separation of subgroup means or the mixture composition changes. For example, if each subgroup has variance one, their means are −a and a, and each has weight 1/2, total variance is 1 + a2. Structural heterogeneity thus enters an explicit mathematical result.

    From a materialist perspective, statistical abstraction selects relationships within the phenomenon and must justify that selection. A theorem establishes what follows from assumptions; research determines whether those assumptions adequately represent the material process. Larger samples can reduce uncertainty without correcting an ill-defined population, omitted dependence, or a misspecified mixture.

    15Conclusions: conditions before shortcuts

    Equal variances can follow from a known distributional identity or be investigated through appropriate estimation and testing. Equal means, standardized shape, and sample size cannot replace that justification.

    L2 convergence permits passage to the limiting variance; convergence in distribution needs additional conditions controlling second moments. Characteristic functions identify complete laws, whereas determination by moments requires its own conditions.

    With finite data, the variance ratio and its confidence interval explain the size and uncertainty of dispersion differences. Power evaluates the design’s ability to detect differences; equivalence requires prior substantive margins. Each conclusion must match its target, model, and actual supporting evidence.

    References and further reading

    1. MIT OpenCourseWare. Fundamentals of Probability (2018), lectures 16–19. Read source.
    2. Lin, G. D. (2017). Recent developments on the moment problem. Journal of Statistical Distributions and Applications, 4, 5. DOI: 10.1186/s40488-017-0059-2. Read source.
    3. Duke University. The Probability Workbook: Characteristic functions (aka Fourier Transforms). Read source.
    4. NIST/SEMATECH. e-Handbook of Statistical Methods, §1.3.5.9, F-Test for Equality of Two Variances. Read source.
    5. R Core Team. stats: var.test — F Test to Compare Two Variances. Read source.
    6. NIST/SEMATECH. e-Handbook of Statistical Methods, §1.3.5.10, Levene Test for Equality of Variances. Read source.
    7. R Core Team. stats: fligner.test — Fligner-Killeen Test of Homogeneity of Variances. Read source.
    8. R Core Team. stats: t.test — Student’s t-Test (Welch procedure when var.equal = FALSE). Read source.
  • GENERAL CONCEPTUAL ASPECTS OF EXPERIMENTAL BLOCK DESIGNS

    GENERAL CONCEPTUAL ASPECTS OF EXPERIMENTAL BLOCK DESIGNS

    Mathematical statistics · Design of experiments

    General Conceptual Foundations of Experimental Block Designs

    Local control, randomization, and combinatorial structure: from complete blocks to treatment information.

    Original publication: · Revised:

    1. Comparing treatments under heterogeneous conditions

    Comparing treatments requires conditions in which their differences can be interpreted. A field has areas of unequal fertility; animals from the same litter share a background; a machine changes between working days. When these differences become mixed with treatment response, comparisons lose precision. Block designs use prior information about this heterogeneity to construct local comparisons.

    The main question is which treatments produce different responses. The blocking factor represents another relevant source of variation: area, litter, batch, or working day. A block brings together units that are relatively similar with respect to that source; treatments are randomly assigned within it. Homogeneity concerns relevant attributes and never means that the units are identical. [1]

    A completely randomized design can be valid in a heterogeneous collection of units. However, part of its residual error may reflect differences that suitable blocking could explain. If the blocking factor explains little, any precision gain may be small or offset by the use of degrees of freedom.

    2. Unit, treatment, block, and replicate

    Experimental vocabulary: four objects worth distinguishing
    ObjectMeaningAgricultural example
    Experimental unitSmallest unit assigned a treatment as a whole; its subsamples do not receive separate assignments.A plot assigned a fertilizer.
    TreatmentCondition or combination of conditions whose response is to be compared.One of four formulations: A, B, C, or D.
    BlockUnits grouped before treatment assignment according to a relevant source of variation.A strip with relatively homogeneous fertility.
    Treatment replicateApplication to another experimental unit; independence depends on the design.Treatment A applied to a separate plot in each block.
    SubsampleAdditional measurement within the same experimental unit.Several plants measured in one plot.

    Measuring ten plants in one plot does not provide ten independently randomized plots. Subsamples can improve measurement of that unit, but treating them as independent replicates creates pseudoreplication and overstates the experimental information.

    In a multicenter clinical trial, a center may define a randomization stratum and enter the analysis. This does not imply that each center is a complete block with just one patient per treatment. Blocking on prognostic characteristics should also be distinguished from permuted blocks used to balance assignments during recruitment.

    3. What is randomized and what is modeled

    Randomization is an assignment procedure. Fixed and random effects are model formulations. Statistical independence describes probabilistic relationships. Linear independence describes relationships among vectors. Each concept answers a different question.

    • Random assignment: treatment positions are randomized within each block, subject to the design restrictions. With four treatments used once each, assignment is a permutation: allocating one treatment to a plot restricts the choices for the others.
    • Fixed effects: inference concerns the particular levels included, such as four formulations deliberately selected for comparison.
    • Random effects: a population of levels and a distribution of their effects are represented. For blocks, a possible model is βj ∼ N(0, σB2) when selection and the inferential objective justify it. [2]

    Treatments can be randomly assigned while their effects are modeled as fixed. Assignments may be generated independently between blocks even though they are constrained within each block. This does not establish error independence: spatial proximity, repeated measurements, or interference between units can introduce dependence.

    4. Gradients, means, and variances

    Systematic differences between blocks may change the expected response without changing residual variance. Three objects should be separated: the mean function, the variance function, and the dependence structure. An additive block effect changes the first; modeling heteroscedasticity changes the second; a spatial or temporal covariance structure changes the third.

    Three distinct questions about heterogeneity
    ObjectQuestionPossible representation
    MeanDoes the expected level change between blocks?E(Yij) = μ + τi + βj
    VarianceDoes error dispersion change?Var(εij) = σj2
    DependenceDo two units share residual information?Cov(εij, εi′j′) ≠ 0

    Homoscedasticity means constancy of the relevant variance; heteroscedasticity means that it varies. Homogeneity of variance across groups is a common formulation of the former. These properties are not exclusive to any single data structure and must be defined relative to the model and the conditioning involved. [3]

    01 · Spatial gradient
    ∇f(x, y) = ( ∂f/∂x, ∂f/∂y )T

    If f represents a differentiable scalar field of fertility, its gradient collects the partial derivatives. It points toward the greatest local increase; its magnitude measures the maximum rate per unit distance. It is not, by definition, a variance gradient. [4]

    If fertility changes mainly in one direction, blocks may be narrow along that direction and extend approximately along similar levels. Actual placement requires knowledge of the field. Categorical factors, such as litter or batch, require no derivatives.

    Batabyal, Sarkar, and Mandal studied radish in established fertility gradients with NPK and farmyard-manure treatments. Their work provides a material context for controlling heterogeneity; the numerical example below is an independent teaching construction. [5]

    5. The randomized complete block model

    In the classical design used here, there are v treatments, b blocks, and one unit for every treatment–block combination. Each block contains all treatments exactly once: k = v. Thus, the total number of observations is n = vb, and each treatment has b replicates. Complete designs with additional within-cell replication also exist; we explicitly use one observation per cell.

    02 · Additive model
    Yij = μ + τi + βj + εij

    Yij is the response from the unit assigned treatment i in block j; μ is the overall mean; τi is the treatment effect; βj is the block effect; and εij is the deviation unexplained by those terms.

    For identifiable parameters under sum-to-zero coding, impose ∑iτi = 0 and ∑jβj = 0. Reference-level coding is another option. Redundancy in a coding scheme does not mean that a treatment is scientifically irrelevant: it means that some parameters need constraints to have a unique representation.

    03 · Global treatment hypothesis
    H0: τ1 = ⋯ = τv = 0

    Under sum-to-zero coding, this is equality of treatment means in the additive model. Rejection indicates that they are not all equal; it does not identify which pairs differ.

    Specific comparisons require estimates, intervals, and multiplicity adjustment where appropriate. With shared random block effects, responses in the same block can be marginally correlated; conditional error independence is a separate matter. The model must therefore match the intended level of inference.

    6. From field layout to data: a complete example

    Consider four fertilizer formulations A, B, C, and D, three blocks with increasing fertility, and twelve plots. The response is a teaching yield index in arbitrary units. The assignments below illustrate three possible within-block permutations; they are not the output of the optional randomization in the R code.

    Figure 1 · Field organization
    Each cell is a plot; letters identify treatments, not outcomes.
    BlockPosition 1Position 2Position 3Position 4
    B1Lower fertilityCADB
    B2Medium fertilityBDAC
    B3Higher fertilityDCBA
    Original schematic. Fertility changes mainly between rows; each row contains all four treatments. Shading identifies levels without relying exclusively on color. Fertility is not assumed identical across all plots in a row.
    Simulated data, reordered by treatment for readability
    BlockABCDMean
    B11822252923.50
    B22831363933.50
    B33742455043.50
    Mean27.6731.6735.3339.3333.50

    The overall mean is 33.50. Successive block means differ by ten units. Under sum-to-zero coding, estimated block effects are −10, 0, and 10; treatment effects are approximately −5.83, −1.83, 1.83, and 5.83. These estimates come from simulated data and do not represent a real agricultural trial.

    04 · Fitted response and residual
    Ŷij = Ȳi· + Ȳ·j − Ȳ··;   eij = Yij − Ŷij

    For A in B1, the prediction is 27.6667 + 23.5 − 33.5 = 17.6667. The observed value is 18, giving a residual of approximately 0.3333. The model separates the block level from the difference attributed to treatment.

    05 · Orthogonal decomposition
    SSTotal = SSTreatments + SSBlocks + SSError

    In this complete, balanced design with no missing observations, treatment and block sums of squares separate orthogonally. This expression does not justify carrying the same calculations unchanged into an incomplete design.

    06 · Components and F test
    SST = b ∑i(Ȳi· − Ȳ··)2;   SSB = v ∑j(Ȳ·j − Ȳ··)2
    SSE = ∑i,jeij2;   FT = [SST/(v−1)] / [SSE/((v−1)(b−1))]

    The multipliers b and v count the observations contributing to each mean. Dividing a sum of squares by its degrees of freedom gives a mean square. Under the null hypothesis and the normal additive assumptions, the treatment ratio follows F with v−1 and (v−1)(b−1) degrees of freedom.

    ANOVA for the additive block model · rounded values
    SourceSSdfMSF
    Treatments224.3333374.7778168.2500
    Blocks800.00002400.0000—
    Error2.666760.4444—
    Total1027.000011——

    For treatments, F(3, 6) = 168.25 and p ≈ 0.00000353. This indicates incompatibility with equal means under the model; it does not establish that every assumption is true or measure practical importance by itself. The mean difference D−A is approximately 11.67 units. Its unadjusted 95% t confidence interval is approximately [10.33, 13.00], using standard error √(2MSE/b) and six degrees of freedom. This interval concerns that contrast under the stated assumptions.

    What happens when blocks are omitted from these same data
    AnalysisError MSError dfTreatment Fp
    Treatments only100.333380.74530.55468
    Treatments + blocks0.44446168.25000.00000353

    7. Assumptions, diagnostics, and limitations

    • Additivity: the model assumes constant treatment differences across blocks. With one observation per cell, including all treatment–block interactions saturates the twelve observations and leaves zero residual degrees of freedom. Unrestricted interaction cannot be separated from pure error.
    • Errors: classical normal ANOVA assumes zero-mean errors, common variance, and independence at the appropriate level. Normality supports the exact F distribution; randomization also supports its own inferential approaches.
    • Diagnostics: examine residuals against fitted values, treatments, blocks, and the actual run order; use a Q–Q plot and assess spatial patterns when relevant. Diagnostics based on twelve observations have limited power. [6]
    • Interference and measurement: fertilizer runoff, contagion, or instrument drift can violate comparison conditions. Blocking requires operational measures alongside the statistical layout.
    • Missing observations: retain the model structure and reassess estimability and sums of squares. The balanced ANOVA table above no longer applies automatically.

    Unequal variances may call for generalized least squares or explicit variance structures; dependence may call for covariance structures or mixed models. A transformation requires a substantive interpretation. With few experimental units, robust standard errors are not an automatic remedy either.

    Replication, the number of blocks, and the minimum effect of interest should be planned before the trial. Observed significance does not replace a prospective assessment of precision or power.

    8. When a block cannot contain every treatment

    A complete block may become too large to remain homogeneous, or there may be too few comparable units. With twenty treatments and capacity for four units per block, each block contains a subset. This leads to incomplete designs: their structure must support block-adjusted comparisons even when two treatments do not appear together in every block.

    Experimentally, a block groups units. In the combinatorial representation of a binary design, it records the set of treatment labels present. This change of representation should be explicit; blocks are not necessarily regions of a probabilistic sample space.

    Properties that can be combined without being equivalent
    TermOperational definition
    Complete / incompleteEach block contains all treatments / only a subset.
    Binary / nonbinaryA treatment occurs at most once / can repeat within a block.
    EquireplicateAll treatments have the same total number of assignments in the experiment.
    Proper or uniformAll blocks have the same size.
    SimpleNo two blocks have the same treatment composition.

    Equireplication does not mean equal repetition inside every block. A nonbinary design can also be equireplicate. Repeating a block composition can contribute new observations; it is not equivalent to algebraically duplicating identical information.

    9. BIBD: balance through counting

    A balanced incomplete block design, BIBD, is binary, has blocks of common size k < v, replicates each treatment r times, and places every treatment pair together in λ blocks. We use the nontrivial convention 1 < k < v and λ > 0.

    The five parameters
    SymbolMeaningMinimal example
    vNumber of treatments3
    bNumber of blocks3
    kUnits per block2
    rTotal replicates per treatment2
    λShared blocks for every pair1
    07 · An explicit BIBD
    B1 = {A, B};   B2 = {A, C};   B3 = {B, C}

    This is a second example, separate from the complete experiment with four fertilizers. Each block contains two separate units: A and B are not jointly applied to one unit. Positions within a block must be randomized.

    There are six assignments: A, B, and C each occur twice. The three pairs AB, AC, and BC each occur together exactly once. Direct enumeration establishes the existence of the design with these parameters.

    08 · Counting incidences
    vr = bk

    Counting by treatment gives v groups of r occurrences; counting by block gives b groups of k units. Both count the same assignments: 3×2 = 3×2 = 6.

    09 · Counting pair occurrences
    r(k − 1) = λ(v − 1)

    Fix treatment A. In each of its r blocks it has k−1 companions. Equivalently, it meets each of the other v−1 treatments λ times. In the example: 2×1 = 1×2.

    These equalities and integer parameters are necessary but not sufficient for every proposed parameter set. A nontrivial BIBD also satisfies Fisher’s inequality b ≥ v. Proposed parameters require an explicit construction or an applicable existence theorem. [8]

    10. From incidence to statistical information

    Let rows represent treatments and columns represent blocks. Entry nij counts the units in block j assigned treatment i. In a binary design it is zero or one. An incidence structure records membership; it requires neither distances nor a metric.

    Figure 2 · Incidence matrix N
    B1 = AB · B2 = AC · B3 = BC
    TreatmentB1B2B3Row sum r
    A1102
    B1012
    C0112
    Column sum k2226
    One indicates presence and zero absence. The bottom-right corner is the total number of assignments, not a block size. This original figure uses the declared orientation of N.
    10 · Concurrence matrix
    NNT = (r − λ)Iv + λJv

    For a BIBD, the diagonal of NNᵀ contains r and the off-diagonal entries contain λ. I is the identity and every entry of J is one. Here the diagonal is 2 and the other entries are 1. [9]

    The product counts shared blocks: for A and B, multiply their incidences in corresponding blocks and sum. Only B1 contributes one. N records treatment–block incidence; the model matrix X has one row per observation and columns for model parameters. They are not interchangeable.

    11 · Treatment information adjusted for blocks
    C = R − NK−1NT

    For the additive homoscedastic fixed-block model with equally weighted observations, R = diag(r₁,…,rᵥ) and K = diag(k₁,…,kᵦ). C is the adjusted information matrix, apart from the factor 1/σ². Each kⱼ must be positive.

    This expression follows by eliminating block parameters from the normal equations. For a BIBD, R = rI and K = kI. Substituting the concurrence identity and using r(k−1) = λ(v−1) gives:

    12 · Information and uniform precision
    C = (λv/k)(Iv − Jv/v)

    In the example, C = (3/2)(I₃−J₃/3): its diagonal is 1 and its other entries are −1/2. Its eigenvalues are 1.5, 1.5, and 0. The zero corresponds to the common level; the two positive values support contrasts among three treatments.

    On the contrast space, C acts as multiplication by λv/k. Thus the intrablock analysis gives Var(τ̂i−τ̂h) = 2kσ²/(λv) for i ≠ h. Here it is 4σ²/3. Equal precision for all pairs follows from the structure under these assumptions; combinatorial balance and heteroscedasticity are different properties.

    11. Partial balance and further extensions

    PBIBDs organize treatment pairs into association classes; their concurrence counts can be λ₁, λ₂, and so on, depending on class. An association scheme imposes additional regularity on these relations: grouping pairs by frequency alone is insufficient. Their relation matrices form an algebra used to investigate structure and precision. Connections with permutation groups exist, but an association scheme is not simply a group. [10]

    As an original example, take B1 = AB, B2 = BC, B3 = CD, and B4 = DA. Each treatment occurs twice and each block has size two. Adjacent pairs in the cycle occur together once; AC and BD never occur together. This is a connected two-class design—neighbors and opposites—rather than a BIBD. Opposite pairs are compared indirectly.

    For this cycle, C has eigenvalues 0, 1, 1, and 2. Under the same intrablock model, the variance of a difference between neighbors is 1.5σ² and between opposites is 2σ². This derivation shows what can change with partial balance: pairs need not have equal precision.

    Alpha, lattice, cyclic, resolvable, unequal-block-size, and unequally replicated designs address different restrictions and can share properties. Choosing among them requires defined comparison objectives and efficiency criteria; no label guarantees optimality in every setting. Dey’s monograph provides a specialized treatment of these families. [11]

    13 · Intrablock efficiency of a BIBD
    e = λv/(rk) = v(k − 1)/[k(v − 1)]

    In the equireplicate homoscedastic case, contrast information is compared with an ideal reference having the same replication r and residual variance. Here e = 3/4: variance is 1/e = 4/3 times that of the reference. This comparison holds σ² constant; it does not contradict blocking reducing residual error relative to omitting real heterogeneity.

    Variance balance concerns equal precision of pairwise contrasts under a model. Efficiency balance concerns canonical efficiency factors relative to a specified reference. In the BIBD above, all contrast efficiency factors coincide. With unequal replication or block sizes, definitions and normalization require greater care; these concepts should not be equated without conditions.

    12. Local control as the material organization of comparison

    Blocking allows experimental objectivity to be understood as an organized practice. Units enter experiments with material conditions and prior histories. Deciding which differences to record and how to distribute treatments determines which comparisons the experiment can support and with what precision.

    From a materialist interpretation, statistical abstraction is constructed through concrete operations: delimiting plots, identifying litters, recording batches, assigning conditions, and measuring responses. A model preserves certain determinations of this process and concentrates others in its error term. The distinction among treatment effect, block effect, and residual should be assessed against the mechanism under study.

    An attribute is secondary relative to a particular question, rather than necessarily to every investigation. Fertility can be a source of variation controlled when formulations are compared, or the main object of another study. It can also modify their effects, making interaction a research question.

    This epistemological reading is an interpretation of the procedure. The definitions of balance, rank, and estimability retain their specific mathematical conditions. Their articulation with a philosophy of science becomes stronger when it explains verifiable experimental decisions and limitations.

    13. Reproducing the analysis in R

    The following code uses base R only. It reconstructs the twelve observations, fits both models, and checks BIBD incidence. The table is ordered by block and treatment; this is not a temporal run order.

    dat <- data.frame(
      block = factor(rep(c("B1", "B2", "B3"), each = 4)),
      treatment = factor(rep(c("A", "B", "C", "D"), 3)),
      response = c(18, 22, 25, 29, 28, 31, 36, 39, 37, 42, 45, 50)
    )
    
    unblocked <- lm(response ~ treatment, data = dat)
    blocked <- lm(response ~ treatment + block, data = dat)
    anova(unblocked)
    anova(blocked)
    aggregate(response ~ treatment, dat, mean)
    confint(blocked)  # coefficient intervals, not all pairwise contrasts
    
    N <- rbind(A = c(1, 1, 0), B = c(1, 0, 1), C = c(0, 1, 1))
    colnames(N) <- c("B1", "B2", "B3")
    N %*% t(N)
    C_info <- diag(rowSums(N)) - N %*% diag(1 / colSums(N)) %*% t(N)
    eigen(C_info, symmetric = TRUE)$values
    

    In the full ANOVA for these balanced data, treatment and block terms are orthogonal: their order does not change their sums of squares. In incomplete or unbalanced designs, hypotheses and adjustments must be specified; a sequential sum of squares is not automatically an effect adjusted for every other term.

    Intervals from confint() refer to the model parameterization and are not all pairwise comparisons. Diagnostics and their limitations should accompany calculation. The additional R file includes numerical checks and an independent prospective randomization, without changing the figure or retrospectively attaching a seed to it.

    14. Criteria for designing and reporting the experiment

    1. Define the response, the minimum relevant effect, and the actual experimental unit.
    2. Choose blocking factors using knowledge of the process and record how blocks were formed.
    3. Check available units, block sizes, replication, and connectedness.
    4. Generate and retain random assignments before applying treatments.
    5. Plan for interference, missing units, repeated measurements, and execution differences.
    6. Choose a model consistent with assignment, dependence, and the population of inference.
    7. Report effects and uncertainty, assumptions, diagnostics, and reproducible data.
    Experimental precision begins with how comparisons are organized.

    A sound block design connects knowledge of the phenomenon, random assignment, and mathematical structure. Complete blocks provide direct, balanced comparisons; incomplete blocks require organized incidence and estimability. In both, the scope of the conclusion depends on the conditions actually constructed.

    References and specialist reading

    The counting arguments, data, and numerical derivations of the examples are developed in this article. The sources below support its concepts and provide further reading.

    1. NIST/SEMATECH. Randomized block designs. e-Handbook of Statistical Methods, §5.3.3.2.
    2. Penn State, Department of Statistics. Random Effects and Introduction to Mixed Models. STAT 502, Lesson 6.
    3. NIST/SEMATECH. Levene Test for Equality of Variances. e-Handbook of Statistical Methods, §1.3.5.10.
    4. Daniel J. Kleitman, MIT. Gradient. Multivariable Calculus, §3.3.
    5. Batabyal, K.; Sarkar, D.; Mandal, B. (2015). Fertilizer-Prescription Equations for Targeted Yield in Radish under Integrated Nutrient Management System. Journal of Horticultural Sciences, 10(1), 18–23.
    6. NIST/SEMATECH. Are the model residuals well-behaved?. e-Handbook of Statistical Methods, §5.2.4.
    7. Hao Zhang, Purdue University. Incomplete Block Designs. STAT 514, sections on randomization, connectedness, and BIBDs.
    8. Joy Morris, University of Lethbridge. Balanced Incomplete Block Designs (BIBD). Combinatorics, §17.1; necessary conditions and existence.
    9. Peter J. Cameron (2012). Balanced and variance-balanced designs. 6th Workshop on Statistics, Mathematics and Computation, Covilhã; incidence and concurrence matrices.
    10. Peter J. Cameron (2003). Association schemes. The Encyclopaedia of Design Theory; definition, matrix algebra, and partial balance.
    11. Aloke Dey (2010). Incomplete Block Designs. Texts and Readings in Mathematics, 57. Hindustan Book Agency; international edition: World Scientific.
  • GENERAL THEORETICAL ASPECTS OF THE DESIGN STRUCTURE MATRIX

    GENERAL THEORETICAL ASPECTS OF THE DESIGN STRUCTURE MATRIX

    Systems · Architecture · Dependencies

    The Design Structure Matrix: Foundations, Dependencies, and the Analysis of Complex Systems

    How to represent a system, read its dependencies, and recognize the limits of matrix-based formalization.

    Original publication ·
    General theoretical aspects of the design structure matrix

    1. Elements, relationships, and architecture

    Understanding a system requires identifying both its components and the relationships that make its operation possible. A Design Structure Matrix, or DSM, organizes these dependencies in a square representation: each element appears once as a row and once as a column. Its pattern of marks reveals a relational architecture that a simple inventory of parts would leave hidden. [1]

    In a product DSM, elements may be components; in an organization, teams; in a process, activities; and, at a finer level, design parameters. The chosen relationship must be specified: information exchange, material transfer, physical interfaces, and dependencies between decisions are not interchangeable terms. [4]

    A useful question precedes drawing the matrix: what does each element need from the others to perform the function under investigation? If the concern is team coordination, recording spatial proximity may be insufficient; if the concern is a thermal interface, counting messages does not answer the question either.

    2. Formal definition and reading convention

    D = (dij) ∈ {0,1}n×n
    dij = 1 ⇔ j → in is the number of elements. For i ≠ j, a value of 1 means that i receives an input from j; a value of 0 means that this relationship is absent in the model.

    Throughout this article, the row receives and the column provides. Reading across a row identifies its element’s direct inputs; reading down a column identifies the direct recipients of its outputs. This is the inputs-in-rows, or IR, convention. The inputs-in-columns, or IC, convention conveys the same information through the transpose DT. [3]

    Zero must not conceal uncertainty either. If a relationship has not been investigated, keep it as unknown in the evidence register and resolve it before turning the table into a complete binary matrix. A recorded dependency expresses the model’s criterion; it does not, by itself, establish causality.

    3. An example: from requirements to revision

    Consider the development of a simple device. We distinguish six activities and record only deliveries of information or results required by the receiving activity. This is a hypothetical example; its relationships are defined so that every step can be checked.

    Table 1. Example activities and inputs
    CodeActivityRepresented direct input
    ARequirementsNone inside the defined system.
    BDesignRequirements A and revision results F.
    CProcurementDesign specifications B.
    DFabricationMaterials or procurement results C.
    ETestingFabricated prototype D.
    FRevisionTest results E.
    One system, six activities, six directed edgesA→B, B→C, C→D, D→E, E→F, F→B. The cycle is B→C→D→E→F→B.ARequirementsBDesignCProcurementDFabricationETestingFRevision
    Figure 1. Original teaching example. Arrows indicate information or result delivery; the dashed F→B edge closes the revision cycle.

    A→B, B→C, C→D, D→E, E→F, F→B. The cycle is B→C→D→E→F→B.

    The F→B edge returns observations to design. A revision may require updated specifications, procurement, or fabrication; the model indicates a structural possibility of iteration without claiming that every step must be repeated in full on every occasion. A receives no inputs from the other five activities because requirements are treated as fixed outside the cycle under analysis.

    Table 2. Binary DSM: receiver rows and provider columns
    Receiver ↓ / provider →ABCDEF
    A · Requirements—00000
    B · Design1—000
    C · Procurement01—000
    D · Fabrication001—00
    E · Testing0001—0
    F · Revision00001—

    Row B contains two ones: dBA = 1 and dBF = 1. B receives from A and F. Column B contains one one, in row C: B delivers to C. Cell dBF represents F→B, never B→F under this convention.

    The table contains six links and thirty off-diagonal positions. Its directed density is 6/[6(6−1)] = 0.20. This number describes the proportion of recorded relationships; it does not automatically measure project complexity, quality, or difficulty.

    4. Dependency, independence, and coupling

    Table 3. Three basic patterns between two elements
    Pattern between i and jCellsLocal interpretation
    No direct linkdᵢⱼ = dⱼᵢ = 0No direct exchange is recorded between them.
    One-way dependencydᵢⱼ = 1; dⱼᵢ = 0j supplies i, with no reverse direct link.
    Reciprocal couplingdᵢⱼ = dⱼᵢ = 1Each element requires inputs from the other.

    The absence of a direct link does not imply statistical independence or guarantee parallel execution: indirect paths or shared constraints may exist. In our example, A does not deliver directly to C but does so through B.

    Nor does every cycle require a reciprocally linked pair. B, C, D, E, and F form the circuit B→C→D→E→F→B although no pair exchanges directly in both directions. Inspecting only symmetric cells would therefore miss the coupling of the whole group.

    5. Reorder without erasing dependencies

    The same architecture may appear scattered when its elements are displayed in an uninformative order. The following table uses exactly the same six links but orders the elements as E, A, C, F, B, D.

    Table 4. The same DSM in an arbitrary initial order
    Receiver ↓ / provider →EACFBD
    E · Testing—00001
    A · Requirements0—0000
    C · Procurement00—010
    F · Revision100—00
    B · Design010—0
    D · Fabrication00100—
    Dordered = P Dinitial PTP is a permutation matrix: it changes row and column order consistently. Its rows select, from the initial ordering, the positions needed to obtain A, B, C, D, E, F.

    Restoring A, B, C, D, E, F produces table 2. The outlined block corresponds to {B,C,D,E,F}; {A} forms the other block. Within the former, each activity can reach every other activity by following arrows: it is a strongly connected component. Condensing these components leaves a single link: {A}→{B,C,D,E,F}.

    Partitioning seeks a block triangular structure that reveals these groups. An acyclic graph admits a topological order that places links below the diagonal under our convention. With cycles, the blocks can be ordered, but a mere permutation cannot produce a strictly triangular matrix. [5]

    6. From structure to decisions

    Clustering seeks modules with strong internal interactions and fewer external links. Sequencing seeks to expose activity precedences and cycles. These are different objectives: a group that benefits from joint coordination need not be an executable sequence or a strongly connected component. [6]

    In the example, the B–F block invites coordination between design and execution. It does not prescribe merging five departments. One concrete intervention would be to agree which observations from F require changes to B and which changes actually require repeating C, D, or E. Assigning owners and deadlines would require additional information.

    Tearing selects dependencies to be handled provisionally through estimates or assumptions so that an iteration can begin. For example, a preliminary specification of B may be used while awaiting results from F. The assumption must subsequently be checked; omitting a mark from a plan does not eliminate the physical or informational need it represents. [7]

    7. Measures, paths, and numerical models

    kiin = Σj≠i dij  ;  kjout = Σi≠j dijThe first sum counts direct providers to element i; the second counts direct recipients of element j. These are binary network degrees, not amounts of work.

    The input counts for A–F are (0,2,1,1,1,1); their output counts are (1,1,1,1,1,1). B has more direct providers, although every element has the same number of recipients. Neither count suffices to measure impact: one critical interface may matter more than many routine exchanges.

    Under ordinary matrix multiplication, (Dk)ij counts directed walks of length k from j to i. In the example, (D2)CA = 1 through A→B→C. For k = 5, the diagonal is (0,1,1,1,1,1), owing to the five-activity circuit. Walks may repeat vertices; they must not be confused with simple paths or propagation probabilities.

    A numerical DSM can record strength, volume, or rework probability, provided that each value has a definition and supporting evidence. An ordinal scale does not authorize every operation appropriate to quantitative measurement. [9]

    8. DSM, DMM, and MDM: distinguish the domains

    Table 5. Three complementary representations
    ToolWhat it relatesExample
    DSM · Design Structure MatrixElements of one domain; a square matrix.Activity to activity: testing → revision.
    DMM · Domain Mapping MatrixElements of two domains; it may be rectangular.Team to activity: who performs testing.
    MDM · Multiple-Domain MatrixIntegrates DSM and DMM blocks in a multidomain model.Activities, teams, and components with their mappings.

    This distinction expands the example without mixing entity types in one DSM: activity E can be mapped to the laboratory team through a DMM. Another matrix can record interfaces between device components. Integrating them requires defining the meaning of each block and checking that their identifiers are compatible. [8]

    9. Construction, validation, and limitations

    1. State the question. Specify the decision the representation should support and what lies outside its scope.
    2. Define elements and granularity. Avoid comparing a very small task with an entire department without justifying the level of analysis.
    3. Define the relationship. Establish direction, unit, threshold, and observation period; separate relationship types when mixing them would make interpretation ambiguous.
    4. Record evidence. Document the source, date, owner, disagreements, and confidence level for each link.
    5. Check the matrix. Review deliveries and receipts with participants; distinguish confirmed absence from unknown information.
    6. Analyze alternatives. Assess how blocks and decisions change when weights, thresholds, or uncertain links are varied.
    7. Validate the intervention. Compare observed results before and after acting; update the matrix when the process changes.

    This sequence is a proposed workflow for the example, not a universal optimization algorithm. In a real application, one might measure whether the agreement between B and F reduces avoidable returns or merely shifts work to other activities.

    A six-activity matrix does not itself record durations, staffing availability, costs, conflicting objectives, or historical variation. The same structure can operate very differently under other material capacities or coordination rules. In social systems, an observed relationship requires contextual interpretation; formalizing it does not exhaust its explanation.

    The matrix makes dependencies visible; understanding them requires knowing the conditions under which they arise.

    10. Comparative note: the discriminant structure matrix

    The term structure matrix also appears in canonical discriminant analysis, but denotes a different object: a table of correlations between predictors and discriminant functions. SPSS Statistics DISCRIMINANT output uses pooled within-groups correlations. This is not a DSM of dependencies. [10]

    zℓ = aℓ1x1 + ⋯ + aℓpxpzℓ is a discriminant score; x₁,…,xₚ are predictors and aℓj are coefficients. Its linear form does not make the procedure ordinary regression: the analysis seeks discrimination between groups. [11]

    In IBM’s example, an asterisk identifies each variable’s largest absolute correlation with a canonical function. This is a reading aid, not an automatic significance test. The label “stability” proposed for one function summarizes a pattern in that example; it is not a mathematical property of every second function. [12]

    A high loading does not make a function useful on its own either. Structure correlations, function coefficients, and predictive performance must be distinguished. Calling a variable “useless” requires an objective and validation evidence; association mainly with a weak function is insufficient.

    11. Reproduce the example in R

    The following code uses base R only. It builds D from the edges, calculates degrees, reproduces the arbitrary order, and checks the permutation. It also checks the A→B→C walk and the length-five circuit.

    # IR convention: row = receiver; column = provider.
    nodes <- LETTERS[1:6]
    edges <- data.frame(
      provider = c("A", "B", "C", "D", "E", "F"),
      receiver = c("B", "C", "D", "E", "F", "B")
    )
    D <- matrix(0L, 6, 6, dimnames = list(nodes, nodes))
    D[cbind(match(edges$receiver, nodes),
            match(edges$provider, nodes))] <- 1L
    stopifnot(sum(D) == 6L, all(diag(D) == 0L))
    stopifnot(D["B", "A"] == 1L, D["B", "F"] == 1L)
    rowSums(D)  # inputs:  A=0 B=2 C=1 D=1 E=1 F=1
    colSums(D)  # outputs: A=1 B=1 C=1 D=1 E=1 F=1
    scrambled <- c("E", "A", "C", "F", "B", "D")
    D0 <- D[scrambled, scrambled]
    p <- match(nodes, scrambled)
    P <- diag(6)[p, , drop = FALSE]
    D1 <- P %*% D0 %*% t(P)
    dimnames(D1) <- list(nodes, nodes)
    stopifnot(isTRUE(all.equal(D, D1)))
    D2 <- D %*% D
    D5 <- D %*% D %*% D %*% D %*% D
    stopifnot(D2["C", "A"] == 1L)
    stopifnot(all(diag(D5) == c(0, 1, 1, 1, 1, 1)))
    print(D)
    print(D0)
    

    The comments state the convention before data entry. Assertions turn expected results into explicit conditions; larger-network analysis should add strongly connected component procedures and retain evidence for each link.

    12. Synthesis

    A DSM moves from a list of activities or components to an explicit representation of their dependencies. Its usefulness depends on three agreements: which elements are distinguished, which relationship is recorded, and how its direction is read. On that basis, modules, precedences, and iteration circuits can be identified.

    In the example, the matrix and graph express the same six links; permutation reveals the coupled B–F block, while A remains an antecedent outside that cycle. The practical decision is to coordinate and verify the deliveries that sustain the process. Visual order aids interpretation; effective improvement requires intervening in relationships and checking the results.

    References and further reading

    1. Eppinger, S. D., & Browning, T. R. (2012). Design Structure Matrix Methods and Applications. MIT Press. DOI: 10.7551/mitpress/8896.001.0001. View source.
    2. DSM Community. Introduction to DSM. View source.
    3. DSM Community. Reading a DSM. View source.
    4. DSM Community. Different DSM Types. View source.
    5. DSM Community. Sequencing a DSM. View source.
    6. DSM Community. Clustering a DSM. View source.
    7. DSM Community. Tearing a DSM. View source.
    8. DSM Community. Tutorials: Overview. View source.
    9. DSM Community. Numerical DSMs. View source.
    10. IBM. STATISTICS Subcommand (DISCRIMINANT command). SPSS Statistics 30.0.0. View source.
    11. IBM. Discriminant Analysis. SPSS Statistics 30.0.0. View source.
    12. IBM. Structure matrix. SPSS Modeler. View source.
    13. DSM Community. Advanced Numerical DSM techniques. View source.

    The example diagrams, matrices, and data are original teaching material. References distinguish methodological foundations and software documentation.

    Explore the reference monograph
    JOSÉ MAURICIO GÓMEZ JULIÁN
    Marxist Philosophy of Science
  • IMPERIALISM, CHINA AND INTERNATIONAL FINANCE: ON THE IIPPE-2021

    IMPERIALISM, CHINA AND INTERNATIONAL FINANCE: ON THE IIPPE-2021

    POLITICAL ECONOMY · PHILOSOPHY OF SCIENCE

    Imperialism, China and International Finance

    Debates at IIPPE 2021: value, uneven development and structural determinations of essence

    Original publication: September 30, 2021
    Revised and expanded edition: November 2, 2026

    GDP in constant 2010 dollars
    GDP in constant 2010 dollars Comparison across economies. Source shown in the graph: World Bank and OECD.

    Introduction: a controversy over relations, mechanisms and measurements

    Imperialism poses a problem that cannot be resolved by listing powerful countries. It requires an investigation of how the relations that enable particular capitals to appropriate surplus labour generated in other territories are produced and reproduced. Technology, wages, ownership, credit and state power participate in that reproduction, but their roles cannot be established through a single label.

    IIPPE—the International Initiative for Promoting Political Economy—is a pluralistic forum for critical research. Its name refers to political economy, a field of inquiry, rather than exclusively to economic policy, understood as public intervention. [1]

    Michael Roberts’s review, published in September 2021, provides the documentary starting point. It connects imperialism, China, financialisation and interest, adding a Colombian study that was not presented at the conference. Our purpose is to reconstruct the underlying problems, examine their mediations and clarify the differences between hypotheses, measurements and conclusions. [2]

    Three questions guide the essay: Which social relation is being explained? What mechanism is proposed, and under what conditions? Which observation could test it? Convergent findings can strengthen an interpretation without automatically making the models that generate them equivalent.

    I. Background: from finance capital to unequal exchange

    A genealogy that neither begins nor ends with one author

    Hilferding published Finance Capital in 1910; Luxemburg, The Accumulation of Capital in 1913. Bukharin investigated the internationalisation of capital and its articulation with states; Lenin wrote Imperialism, the Highest Stage of Capitalism in 1916, and the book appeared in 1917. Their contributions constitute a historical controversy, not interchangeable stages of a homogeneous theory. [3, 4, 5, 6]

    To study this controversy, it is useful to distinguish corporate concentration, the articulation of banking and industry, capital exports, problems of reproduction and interstate rivalry. An author can illuminate one relation without providing a complete explanation of all the others. Lenin’s centrality does not require attributing absolute priority to him over every Marxist investigation of the world economy.

    Emmanuel shifted the discussion towards international wage differences and prices of production. His formulations of 1962 must be distinguished from the French book of 1969 and its English edition of 1972. His proposal integrates international exchange into an inquiry into value and the worldwide distribution of surplus. [7]

    Emmanuel: economic assumptions and political implications

    In his characteristic formulation, capital mobility and restrictions on labour mobility make it possible to examine a tendency towards equal profit rates alongside persistent wage differences. The question is how these assumptions affect international prices and the distribution of social labour. [7]

    Evaluating the argument requires making the time horizon, degrees of mobility, wage determination and price formation explicit. Altering an assumption may alter the conclusion. This does not invalidate modelling: it specifies the explanation’s domain.

    The implications for international solidarity deserve their own discussion. A relative distributive advantage for some workers does not automatically turn them into owners of the means of production or eliminate their antagonisms with capital. Conversely, acknowledging exploitation within each country does not require denying international hierarchies. Class position and territorial insertion must be examined together.

    Explaining Emmanuel’s reception exclusively through political convenience would replace investigation with imputation. Both political conflicts and theoretical disagreements are recognised here. Controversial attributions—for example, that an author treats capital as an autonomous source of value—require precise passages and contexts; they do not follow from the use of simultaneous equations.

    II. Value, surplus value and transfers: distinctions that explain

    Production and appropriation are different processes

    In Marx’s theory, value concerns socially necessary abstract labour, rather than any individually clocked expenditure of effort. The formation of a general profit rate and prices of production makes it possible to investigate differences between the surplus produced by a capital and the surplus it ultimately appropriates. [8, 9]

    For an introductory scheme, assume one turnover and that all the constant capital considered is consumed during the period:

    W = c + v + s

    Here c is the value of consumed means of production transferred to the product; v, variable capital advanced for labour power; and s, surplus value. The expression organises theoretical categories. Estimation requires deciding which observations represent each term and how labour magnitudes are translated into monetary magnitudes.

    e = s / v   ·   r = s / (C + V)

    The surplus value rate relates the surplus to variable capital. The profit rate relates a flow of profit per period to the relevant total capital advanced, C + V; this must not be confused without justification with consumed costs, c + v. The rates are comparable only when periods, turnover and valuation conventions are aligned.

    A teaching example of redistribution

    Consider two capitals of 100 units each, with one turnover, full consumption of constant capital and a surplus value rate of 100%. A uses 70 units of constant and 30 of variable capital; B uses 40 and 60. Their surplus values are 30 and 60. Total surplus value is 90, and the hypothetical average profit rate is 90/200 = 45%. If each realises 45 in profit, A appropriates 15 more than it produced and B appropriates 15 less.

    This is a teaching construction, neither a historical estimate nor a universal solution to the transformation problem. Costs are held given to isolate the mechanism; a complete system must also explain input prices. Redistribution does not create the 90 units of surplus value: it changes their appropriation.

    What zero-sum means—and what it does not

    If Tᵢ denotes a net transfer within an accounting universe that is closed and uses the same unit of valuation, then:

    Σᵢ Tᵢ = 0

    This identity concerns the distribution of a given magnitude. It does not imply that every economic interaction or expanded reproduction is zero-sum. Production can generate new value; transfers redistribute its appropriation. If the data do not sum to zero, coverage, valuation and statistical discrepancies must be examined before the residual becomes a theoretical conclusion.

    Material welfare, the quantity of use values and the magnitude of value must also be distinguished. Productivity gains can increase available goods without proportionately increasing value per unit. “Benefiting from trade” and “appropriating a net transfer of value” are different questions.

    III. One concrete essence and multiple structural determinations

    Components, common essence and material totality

    The components of a totality, represented through equations articulated within a system, may share determinations of a common essence that makes their unity and differences intelligible. This essence is expressed through set-theoretic, topological, differentiable, metric, operational, and historical and dynamical determinations: each makes particular constitutive relations available for investigation. When a correspondence preserves the relations of a defined structure, an isomorphism can be established at that level; equivalence in one determination can coexist with differences in others.

    The articulation of components admits an integrodifferential representation when the problem requires rates of change, distributed effects or accumulated memory. Under determinate initial conditions and constraints, interactions constitute an internal structure of a material nature: objective through the efficacy of its relations, dynamic through its reproduction and transformation, and nonlinear where its functional dependencies have that property. The coherence of this articulation includes the compatibility of its relations and equations alongside antagonisms and tensions that can drive its development.

    The totality’s structure, generated through component activity, in turn conditions those components’ possibilities of existence, reproduction and transformation. System composition and structural conditioning form a reciprocal relation: interactions produce organisation, and organisation modifies the conditions under which those interactions continue. Emergent properties are explained through this articulation rather than a simple inventory of isolated components.

    The laws guiding the investigation of this genesis and reproduction acquire a generalised realisation within a totality with new mediations. The unity and struggle of opposites allows investigation of the constitution and transformation of antagonistic relations and their processes of emergence and self-organisation; the transformation of quantity into quality concerns regime changes, which can be formalised through bifurcations in particular models; and the negation of the negation examines reorganisations preserving and transforming previous determinations. Chemical synthesis provides a concrete example of material reorganisation and the emergence of properties. These connections are developed by specifying mechanisms and conditions: a general dialectical law does not by itself impose an identical functional form, a bifurcation or self-organised criticality on every system.

    Integrodifferential composition and reciprocal conditioning

    Representing a component through an equation means selecting variables and relations relevant to the problem. Representing the totality must additionally incorporate couplings between components and the restrictions imposed by their organisation. Integration can capture distributed or accumulated effects; differentiation can describe rates of change. Their articulation expresses a concrete possibility for formalising the thesis.

    In a domain where differentiable evolution is an appropriate description, reciprocal conditioning can be schematised as follows:

    dxi/dt = Fi(x(t), S(t), Ht; θi)
    dS/dt = G(S(t), x(t), Ht; Θ)

    x(t) collects the component states; S(t) represents organisational variables or structural constraints; Ht, the relevant history up to that moment; and θi and Θ, model parameters. The first equation expresses how component behaviour depends on the organised totality. The second expresses how that organisation is reproduced or transformed through component activity. Both must satisfy compatible initial conditions and constraints.

    Where accumulated memory needs representation, an integral contribution can be added:

    mi(t) = ∫0t Ki(t, τ) Qi(x(τ), S(τ)) dτ

    Qi represents the contribution of earlier interactions and Ki their present weighting. This formulation allows investigation of how different histories can modify current possibilities. It is a modelling scheme requiring functions, units and observations to be defined for each application; it does not assert that every system must take this specific form.

    The structure is material and objective insofar as the represented relations are effective in the object and do not depend on the investigator’s will. The objectivity of a relation and the adequacy of its mathematical representation are connected but distinguishable questions. Structural reproduction can constrain particular actions while those same actions contribute to sustaining or altering it.

    Emergence, nonlinearity and generalised lawfulness

    The totality contains relations and capacities that cannot be explained by listing isolated components. Explanation requires investigating their organisation and interactions. A dynamics is nonlinear when its functional dependencies do not satisfy the relevant linearity property; couplings can supply concrete mechanisms for this nonlinearity. Explaining the difference between a totality and the sum of its parts requires identifying these organisational relations.

    Generalised lawfulness retains the relation between the system’s genesis and reproduction conditions. The processes constituting a structure subsequently operate within an organisation that modifies their scale, mediations and effects. Continuity of lawfulness can coexist with a transformation of its concrete form of realisation. Sharing general principles does not require using an identical equation at every scale.

    In the problem of imperialism, capitals participate in general valorisation relations while their worldwide articulation configures production chains, monetary hierarchies and access to technology and credit. These structural relations condition particular capitals’ reproduction, while those capitals reproduce them through investment, production and appropriation. Moving from the national to the international requires investigating this reciprocity and its historical mediations.

    The following layered table specifies the determinations of this articulation; section IV develops the three dialectical laws orienting its interpretation.

    What a layered interpretation contributes

    Essence can be interpreted as the articulation of constitutive relations that makes an object’s identity and reproduction intelligible. Understanding it requires abstractions, but no single abstraction necessarily exhausts that articulation. Mathematics can specify particular relations; the correspondence between formalism and object requires additional justification.

    Interpreting essence as an articulation of structural determinations makes it possible to distinguish the following levels. [10]

    Determination Structural question Possible formalisation and scope
    Set-theoretic Which elements or states are distinguished? A set and correspondences; a bijection preserves cardinality, not every additional relation.
    Topological What continuity, neighbourhood and connectedness exist? A topology; homeomorphisms preserve its structure.
    Differentiable Which smooth variations can be described? A smooth structure; diffeomorphisms compare that structure.
    Metric How are lengths or distances quantified? An appropriate metric; isometries preserve the corresponding geometry.
    Operational Which transformations preserve selected relations? Automorphisms and group actions; Lie groups apply in cases with a compatible smooth structure.
    Historical and dynamical How was the system constituted, and which transitions does it admit? Evolutions, path constraints and categories of transitions; irreversible histories do not reduce to invertible symmetries.

    These layers are articulated determinations of a concrete essence, not six independent substances. Their selection depends on the object. A trade network does not automatically possess a manifold’s topology; an economic inequality does not by itself constitute a mathematical distance. States, relations and observation procedures must be defined in each case.

    Adding structure and preserving structure

    Equipping a set with a topology differs from establishing a homeomorphism between spaces. Transformations should therefore not be drawn as if they independently created the next level’s structure. For a smooth manifold M with Riemannian metric g, transformations of the object satisfy:

    Isom(M, g) ⊆ Diff(M) ⊆ Homeo(M) ⊆ Bij(M)

    Preserving the metric imposes additional conditions beyond preserving only differentiable structure; preserving the latter imposes additional conditions beyond topological equivalence. The inclusions are not asserted to be universally strict. Moreover, not every topology admits a smooth manifold structure, and this chain does not classify all mathematical structures.

    The same underlying space can admit different geometries

    On the upper half-plane U = {(x,y): y > 0}, compare:

    gE = dx² + dy²   ·   gH = (dx² + dy²) / y²

    The set, usual topology and smooth structure coincide. Gaussian curvature differs: K = 0 for gE and K = −1 for gH. No isometry exists between these geometries. Topological equivalence does not decide metric equivalence. [11]

    Curvature does not prevent a global metric from existing. Under the usual assumptions—a smooth, Hausdorff, second-countable manifold—Riemannian metrics can be constructed using partitions of unity. A global metric differs from a global chart, a constant matrix in every coordinate system or a globally Euclidean geometry. [11]

    Invariance, identity and historical transformation

    An invariant is always relative to a class of transformations. Remaining unchanged under coordinate changes, under isometries or during physical evolution are different properties. Knowing an abstract symmetry group is also insufficient to reconstruct uniquely every structure admitting it.

    “Operational essence” can designate the restrictions delimiting particular structurally admissible transformations. This does not identify every change that leaves a system recognisable with an exact symmetry. An organism or an economy can persist through dissipative processes that do not preserve a metric.

    For irreversible transitions, a category or semigroup may be more suitable than a group. A groupoid permits partial composition and multiple objects, but requires invertible morphisms: having additional objects does not itself introduce irreversibility. Noether’s connection between symmetry and conservation requires variational dynamics and the corresponding assumptions. [12]

    From the national to the international scale

    The persistence of wage labour, surplus appropriation and competition between capitals makes common relations across scales a legitimate research question. Currencies, borders, jurisdictions, intellectual property and migration restrictions nevertheless introduce specific mediations. An international structure cannot be obtained merely by multiplying a national structure.

    Establishing an isomorphism would require defining the compared structures and constructing a correspondence that preserves their relations. Many applications instead involve aggregations, projections or partial correspondences. Sharing a general law does not prove that components are mutually isomorphic, or that each is isomorphic to the whole.

    This qualification retains a decisive dialectical insight: general relations are realised under concrete conditions and can acquire new determinations within a more complex totality. Investigating that articulation requires specifying what is preserved, what emerges and what ceases to be equivalent.

    IV. Dialectics, complexity and time: connections with conditions

    The three dialectical laws in the constitution and transformation of the totality

    The constitution and transformation of the totality are examined through three laws: unity and struggle of opposites, transformation of quantity into quality, and negation of the negation. Their function in this essay is to guide a reconstruction of the material totality’s genesis, reproduction and transformation. Each proposed mathematical relation must show which aspect of this reconstruction it expresses.

    1. Unity and struggle of opposites. The terms of a contradictory relation presuppose and condition one another within an organisation, while their tendencies can oppose one another. Inquiry must explain both the reproduction of this unity and the tensions transforming it. In the capital–labour relation, for example, capital’s reproduction presupposes wage labour, but surplus appropriation places participants in antagonistic positions over its distribution and control. The totality is constituted through these relations and imposes conditions on their realisation.

    The reference to emergence and self-organisation opens a positive question: how do interactions produce an order which subsequently regulates its own reproduction conditions? A model can investigate feedback and emergent constraints to address it. If self-organised criticality is additionally proposed, the mechanism and properties warranting that specific concept must be identified. The analysis of reciprocal organisation thus connects philosophical explanation with a defined research requirement.

    2. Transformation of quantity into quality. Accumulated variations can modify a system’s organisation and possibilities until a different regime is constituted. The problem is to investigate what accumulates, which relations mediate that accumulation and when the relevant quality changes. A bifurcation represents this passage when parameter variation changes a dynamics’ qualitative structure. In political economy, a hypothesis about concentration and market power must establish how changes in magnitude reorganise relations between capitals; accumulating figures alone does not demonstrate that change.

    3. Negation of the negation. Transformation can supersede an organisational form through processes which that form itself helped generate. The new organisation preserves determinations of the preceding process while transforming their articulation. This perspective investigates historical continuity within qualitative discontinuity: which relations are displaced, which are preserved and in which new configuration they reappear. It does not assume that every trajectory necessarily advances towards a favourable outcome or repeats an identical cycle.

    Chemical synthesis illustrates material reorganisation and the emergence of a compound’s properties. Extending this to a general dialectical law requires explaining the mediations and meaning of the negations in the investigated process. The connection requires determining which relations and processes warrant generalising from each example.

    The three laws are articulated within the argument: contradictory relations constitute a unity, variations can transform its organisation, and transformation incorporates a history preserving and modifying previous determinations. Integrodifferential modelling and the layers of essence make particular aspects of this articulation available for investigation.

    Scope of the mathematical correspondences

    The unity and struggle of opposites directs attention to antagonistic relations; it does not by itself imply that a model exhibits self-organised criticality. The latter requires a dynamical definition and evidence of its properties. Similarly, emergence and non-additivity are insufficient to demonstrate mathematical nonlinearity: the relevant equations, operations or functional relations must be identified.

    A bifurcation provides one possible formalisation of particular qualitative changes when dynamics change regime as a parameter varies. Not every qualitative change is a bifurcation in the technical sense. Chemical synthesis can illustrate concrete transformations; identifying it with the negation of the negation would require an independent argument.

    Self-similarity likewise does not follow from the existence of relations between parts and a whole. It can be exact, approximate or statistical and must be established through a defined scaling transformation. Dialectical inquiry gains precision when mathematical connections become testable problems.

    Temporality and simultaneity in the transformation problem

    One axis of Marxist debate contrasts simultaneous valuation of inputs and outputs with interpretations that distinguish moments of valuation. It matters, but does not exhaust the classification of schools. Relations between value and price systems, money, reproduction and distributive closure also matter.

    Simultaneous equations can represent conditions within a period or states of a dynamic process; they do not automatically deny time’s existence. A temporal formulation does not become historically adequate merely by introducing a subscript t. It must explain what is inherited, what changes and how periods are connected.

    The MELT—monetary expression of labour time—connects labour and monetary magnitudes under a chosen formulation. Its definition, units and valuation date must be declared. Labour hours and money cannot be added as a homogeneous magnitude without such mediation.

    Differences between models demand more than observing different numerical results. They require comparison with relevant data, explicit closures and assumptions. Not every methodological controversy has an immediate empirical resolution, nor does comparison with other philosophies of statistics settle this debate by itself.

    V. Unequal exchange: theories, indicators and evidence

    A map of mechanisms

    Approach Explanatory focus Question requiring examination
    Emmanuel Wage differences and international price formation under mobility assumptions. How do results change with mobility, wages and model closure?
    Carchedi–Roberts Transfers estimated through capital composition, surplus value and production prices. How are theoretical categories translated into national accounts and export sectors?
    John Smith Super-exploitation and the international organisation of production. How are labour-power reproduction and the location of appropriation observed?
    Andrea Ricci Unequal-exchange measurement and international productive structure. Which monetary conversions and sectoral aggregations make labour comparable?
    Cogliano–Veneziani–Yoshihara International exploitation, endowments and credit markets in a calibrated model. What depends on the index’s definition, and what on mechanisms of persistence?

    This table proposes reading questions; it does not equate different mechanisms. Indicators classifying some countries similarly may differ in their measured object and causal explanation. [7, 13, 14, 15, 16]

    Carchedi–Roberts: measurement and decomposition

    The 2021 presentation estimates trade transfers separately from primary income. Its comparison of methods records $600 billion for 2019, equivalent to 1.3% of reference GDP, and $600 billion in primary income for 2017, equivalent to 1.4%. The graph uses each bloc’s own denominator; it is not a homogeneous time series of one combined sum. [13], slides 16–17

    Unequal exchange as a share of each bloc’s GDP, 1950–2019.
    Figure 1. Unequal exchange as a share of each bloc’s GDP, 1950–2019. Carchedi–Roberts, 2021 presentation. IC-GDP: imperialist bloc; DC-GDP: dominated bloc. Denominators differ. Series expressed as percentages of each bloc’s GDP.

    The positive and negative lines need not have equal percentage magnitudes: the same flow can be divided by different GDPs. Nor should they automatically be equated with the rounded 1.5% in the 2021 account. Reproducing the calculation requires specifying the estimation procedure, year and denominator.

    Relative contributions of OCC and RSV to unequal exchange, 1950–2019.
    Figure 2. Relative contributions of OCC and RSV to unequal exchange, 1950–2019. Carchedi–Roberts. OCC: organic composition of capital; RSV: rate of surplus value. Shares in a model decomposition, not growth rates.

    The decomposition between OCC—organic composition of capital—and RSV—rate of surplus value—belongs to the model. A rising relative contribution does not necessarily mean that the other factor’s absolute contribution is falling. Organic composition is not a direct, universal measure of technological superiority: its relation to productivity depends on techniques, wages, prices and sectoral composition.

    Super-exploitation: production organisation and appropriation

    Smith emphasises working conditions and wages in global production, challenging the identification of where value is generated with where national accounts record its appropriation. His linked study makes it possible to examine the objection without reducing it to terminology. [14]

    The disagreement requires distinguishing criticism of an indicator from denial of all unequal exchange. It also requires avoiding identification of the immediate employer with the sole beneficiary without studying contractual and ownership relations. Subcontracting, commercial control and ownership can articulate successive appropriations. Evaluation must follow the chain and its concrete conditions.

    Ricci: transfers per person and units of comparison

    Annual transfers per person and percentages by period, 1995–2019.
    Figure 3. Annual transfers per person and percentages by period, 1995–2019. Ricci (2022), table 2. Current dollars and period-average percentages; accessible transcription below.

    The figure distinguishes annual amounts per person in current dollars for 1995, 2007 and 2019, and percentage columns for 1995–2019, 1995–2007 and 2007–2019. These percentages must not be presented as growth rates, or the last monetary column mechanically paired with a single annual percentage. [15, 27]

    Transcription of figure 3; checked against Ricci (2022), table 2. Positive signs: inflows; negative signs: outflows. Groupings follow the source.
    RegionUSD/person 1995USD/person 2007USD/person 2019Mean % 95–19Mean % 95–07Mean % 07–19
    North America761196526803.93.74.1
    EMU17204939483610.38.512.2
    West Europe24297531692112.710.614.8
    East Asia1984176625405.85.95.7
    Oceania526262636387.14.59.8
    China−196−810−426−14.1−19.0−10.0
    Russia−767−1108−1850−29.7−40.9−17.2
    East Europe−901−615−1309−14.7−18.9−9.9
    South America−269−472−490−6.1−8.4−3.9
    Central America−471−379−454−11.9−13.6−9.8
    Middle East−1443−1502−950−18.9−24.8−12.8
    South Asia−77−220−351−21.5−20.2−23.0
    Southeast Asia−463−1350−1631−46.8−53.9−40.3
    Central Asia−272−380−924−11.9−13.6−9.8
    North Africa−426−1099−1034−30.7−31.6−30.4
    S. Sahara Africa−65−120−132−10.0−11.6−8.3

    In particular, South Asia must not be renamed India; East Asia is not simply Japan; and South America and Central America are not one regional observation. The table reports regions, not individual findings for each country.

    In Global locational inequality (2022), table 2 shows that percentages are period averages and monetary amounts are nominal dollars. EMU denotes the European monetary union bloc in that classification. Its regions also need not coincide with states: “China” incorporates Hong Kong, Macao and Taiwan in this statistical aggregation; “Russia” includes other countries, and “Central America” includes Mexico and the Caribbean. These groupings follow Ricci’s statistical classification. Findings must be interpreted according to that territorial coverage. [27]

    An international index is not the axiomatic article

    Exploiter and exploited countries: basic economy.
    Figure 4. Exploiter and exploited countries: basic economy. Exploitation intensity index and wealth per person. Cogliano–Veneziani–Yoshihara’s international model differs from Yoshihara–Veneziani’s axiomatic foundations.

    Yoshihara and Veneziani’s article (2018) examines exploitation’s axiomatic foundations. The Dynamics of International Exploitation by Cogliano, Veneziani and Yoshihara (2022) develops a model of international exploitation. Its basic economy assigns China an index of 0.9935: just on the exploiting side of the threshold 1, with the authors advising against a definite conclusion. [16, 17]

    The graph relates exploitation classification to wealth per person in a basic economy. An index close to the threshold requires sensitivity analysis. Partial agreement with other studies must not erase classification differences.

    VI. China: three questions that must be distinguished

    Transfers, mode of production and international power

    Roberts’s presentation When did China become capitalist? argues for a trapped transitional economy: it emphasises state direction and planned investment while acknowledging the law of value’s operation. The argument is documented as a position held in 2021, not a classification accepted by all authors. [18]

    Dimension Object of investigation Relevant evidence
    International transfers Net appropriation under an indicator and period. Trade, production, primary income, conversion assumptions and sensitivity.
    Socioeconomic organisation Ownership, control, labour and surplus allocation. Corporate governance, investment decisions, labour discipline, planning and markets.
    Imperialist power International domination and the reproduction of hierarchies. Credit, monopolies, coercion, institutions, foreign policy and military capacity.

    Being a net recipient under an indicator does not by itself establish comprehensive imperialist domination; being a net donor does not exclude relations subordinating third parties. Scale matters: different positions may coexist across sectors, firms, partners and territories.

    Sam King examines monopoly over technologically complex activities as a mechanism reproducing international hierarchy. His 2021 book, Imperialism and the Development Myth, frames the question of productive upgrading and its limits. [19]

    The review also records Walter Daum’s political objection and different positions from Dic Lo and Cheng Enfu. These interventions are acknowledged as disagreements without attributing to them a demonstration that the review does not provide. [2]

    What a growth trajectory cannot decide

    Growth, poverty reduction and the capacity to sustain investment require explanation. They do not by themselves identify a mode of production. Connecting them causally with an ownership form would require mechanisms, comparators, periodisation and external conditions; a favourable outcome is insufficient to identify its cause.

    It would also be circular to declare that every capitalist economy must reproduce precisely one crisis trajectory and exclude any differing case from the category. A theory must specify tendencies, mediations and conditions, and admit observations capable of challenging its scope.

    Dates are decisive. A productivity comparison using aggregate data preceding 2021 does not authorise indefinite descriptions of every Chinese industry as technologically backward. Each conclusion’s scope depends on its period, sectoral disaggregation and supporting sources.

    VII. Financialisation: specify the hypothesis before rejecting it

    One term, several objects

    Research can examine finance’s share of value added, credit expansion, household indebtedness, financial income of nonfinancial firms or shareholder power. Each dimension needs its own indicators. None automatically substitutes for every other dimension.

    Mavroudeas challenges finance’s independence from productive accumulation. Rabinovich specifically examines the financial rentierisation hypothesis for US nonfinancial corporations, finding that asset and income composition require a more differentiated interpretation. These arguments have different scopes. [20, 21]

    Methodologically, a declining sectoral share can coexist with increasing absolute size. An average can conceal corporate concentration. Changes in value added do not directly equal changes in assets, credit or institutional power. Indicator selection must answer a hypothesis defined in advance.

    What the percentages 51.2% and 65.9% measure

    This distinction changes the evidence’s meaning. Counting countries measures how widespread a sign of change is; it does not measure the aggregate magnitude of that change or automatically weight countries by economic size. The chosen time window also matters for detecting earlier expansion.

    Concluding that financialisation explains deindustrialisation requires temporality, mechanisms and alternative variables. An association between sectoral shares does not itself identify causality. Conversely, rejecting an exclusively financial explanation of crises does not eliminate the roles of credit, collateral and liquidity in their transmission.

    VIII. Interest and profitability: structural relations and statistical tests

    Interest as distribution and as a price

    Marx investigates interest as part of profit and examines its division between lender and functioning capitalist. This distributive restriction does not establish a mechanical equality between interest and profit rates at every moment. The analysis itself allows exceptions and distinguishes determinants of fluctuations. [23]

    A concrete explanation must specify whether nominal or real magnitudes, expected or realised rates, and equivalent maturities are being compared. Contractual interest can temporarily exceed realised profitability, resulting in losses or default. Two declining trends are insufficient to identify a unique causal relation.

    Stravelakis: what the “60%” represents

    Nikos Stravelakis’s presentation uses the incremental rate of profit, IROP = ΔPr / I, examining its difference from interest. Slide 7 reports a normalised mutual-information-based measure around 0.606 for 1962–2019. This is not an R² explaining 60% of interest-rate variance, and the statistic alone does not identify causality. [24]

    ΔPr is the change in profit, and I is investment as defined in the study. Their ratio depends on the period and does not by definition coincide with the average rate on the capital stock. A statistic’s economic content depends on the variables it relates and how they were constructed.

    Roberts reports an observation by Karl Beitel concerning profitability trends and bond yields. The association requires examining the series, definitions and estimation procedure before using it as causal evidence. [2]

    IX. Colombia, 1967–2019: evidence with a defined scope

    Growth, profit rate and accumulation in Colombia, 1967–2019.
    Figure 5. Growth, profit rate and accumulation in Colombia, 1967–2019. Duque García (2021), figure 2. Growth and profit rate: left axis. Accumulation rate: right axis. Vertical lines delimit historical periods.

    Carlos Alberto Duque García’s document investigates growth, accumulation and the profit rate using a VAR with generalised impulse responses. It uses 53 annual observations and warns about sample size. Its evidence bears on the Marxian models examined, but does not independently prove a universal law or identify a structural causal effect without further assumptions. [25]

    The graph uses different scales: growth and profitability on the left axis, accumulation on the right. Comparing visual heights without reading the axes can manufacture similarities or differences. Vertical lines delimit historical periods; they do not automatically constitute statistical tests of breaks.

    Evaluation must consider variable definitions, stationarity, lags and stability. Generalised responses’ invariance to variable ordering does not remove the conditions for causal interpretation. Independent replication requires the data and estimation choices, together with an assessment of the findings’ sensitivity.

    World in Crisis, edited by Carchedi and Roberts, brings together profitability studies. Cross-country comparison requires methodological alignment before all its series can be treated as one measurement. [26]

    X. Assessment: investigate the whole without erasing its mediations

    A Marxian perspective can contribute a research programme on surplus production, appropriation and reproduction across scales. Imperialism becomes intelligible through concrete relations between capitals, classes, states and territories, rather than by turning a set of countries into an indivisible subject with homogeneous internal interests.

    The layered interpretation of essence supplies a useful discipline: define which relations constitute the object, which abstraction represents them, which transformations preserve that representation and which history explains its configuration. Formalisation establishes consequences under assumptions; material adequacy requires testing and comparison with alternatives.

    Political action and scientific inquiry can be articulated without replacing one another. Solidarity among workers requires understanding both shared exploitation and the inequalities shaping their reproduction. Specifying these mediations makes the critique of capitalism more demanding and the discussion of its transformation clearer.

    XI. Documentary library

    The library brings together works of conceptual reference, axiomatic foundations, econometric analysis and international political economy. Each entry includes its cover or opening page and access to the document.

    Cover or opening page: Diccionario filosófico

    CONCEPTUAL REFERENCE · PDF

    Diccionario filosófico

    Rosental · Iudin

    Reference dictionary for studying philosophical vocabulary and conceptual relations.

    OPEN / DOWNLOAD PDF
    Cover or opening page: The Theory of Exploitation as the Unequal Exchange of Labour

    AXIOMATIC ARTICLE · PDF

    The Theory of Exploitation as the Unequal Exchange of Labour

    Naoki Yoshihara · Roberto Veneziani · 2018

    Formal foundations of exploitation definitions. Distinct from the later international application.

    OPEN / DOWNLOAD PDF
    Cover or opening page: Economic Growth and the Rate of Profit in Colombia 1967–2019

    WORKING PAPER · PDF

    Economic Growth and the Rate of Profit in Colombia 1967–2019

    Carlos Alberto Duque García · 2021

    VAR analysis of growth, accumulation and profitability, including its warning about 53 annual observations.

    OPEN / DOWNLOAD PDF
    Cover or opening page: World in Crisis

    EDITED VOLUME · PDF

    World in Crisis

    Guglielmo Carchedi · Michael Roberts, eds. · 2018

    Research on the law of profitability in different countries. Methods need comparison before findings are aggregated.

    OPEN / DOWNLOAD PDF
    Cover or opening page: Value and Unequal Exchange in International Trade

    MONOGRAPH · PDF

    Value and Unequal Exchange in International Trade

    Andrea Ricci · 2021

    Study of value, trade and global exploitation, developing the foundations of unequal-exchange measurement.

    OPEN / DOWNLOAD PDF

    XII. References and resources

    1. IIPPE. About IIPPE. ↩
    2. Roberts, Michael (2021-09-30). IIPPE 2021: imperialism, China and finance. ↩
    3. Hilferding, Rudolf (1910). Finance Capital. ↩
    4. Luxemburg, Rosa (1913). The Accumulation of Capital. ↩
    5. Bukharin, Nikolai. Imperialism and World Economy. Written 1915 and 1917. ↩
    6. Lenin, V. I. (written 1916; published 1917). Imperialism, the Highest Stage of Capitalism. ↩
    7. Emmanuel, Arghiri (1969; English edition 1972). Unequal Exchange: A Study of the Imperialism of Trade. Monthly Review Press. Bibliographic chronology: Arghiri Emmanuel Association. Publisher record. ↩
    8. Marx, Karl (1867). Capital, vol. I, chapter 1. ↩
    9. Marx, Karl (1894). Capital, vol. III, chapter 9. ↩
    10. Gómez Julián, José Mauricio (2026). Geometría, historia y legalidad: fundamentos dialéctico-materialistas de los espacios con estructura métrica. Manuscrito de investigación / Research manuscript. ↩
    11. Lee, John M. (1997). Riemannian Manifolds: An Introduction to Curvature. Springer. Also: George Voutsadakis, Differential Geometry (2024), chapter 5, construction of Riemannian metrics. Partition-of-unity construction. ↩
    12. Tong, David. Classical Dynamics, section 2.4: Noether’s Theorem and Symmetries. University of Cambridge. ↩
    13. Carchedi, Guglielmo & Michael Roberts (2021). The economics foundations of imperialism. IIPPE presentation; title as printed in the PDF. Slides 16–19 discussed here. ↩
    14. Smith, John. Imperialism in the Twenty-First Century. Study of global production and exploitation. ↩
    15. Ricci, Andrea (2021). Value and Unequal Exchange in International Trade: The Geography of Global Capitalist Exploitation. Routledge. See also reference 27, table 2. ↩
    16. Cogliano, Jonathan F., Roberto Veneziani & Naoki Yoshihara (2022-08-10). The Dynamics of International Exploitation. Working paper, figure 2 and table 1. ↩
    17. Yoshihara, Naoki & Roberto Veneziani (2018). The Theory of Exploitation as the Unequal Exchange of Labour. Economics & Philosophy 34(3), 381–409. DOI: 10.1017/S0266267118000238. ↩
    18. Roberts, Michael (2021). When did China become capitalist? IIPPE presentation. ↩
    19. King, Sam (2021). Imperialism and the Development Myth: How Rich Countries Dominate in the Twenty-First Century. Manchester University Press. ↩
    20. Mavroudeas, Stavros D. (2018). Financialization Hypothesis: A Creative Contribution or a Theoretical Blind Alley? Lecture, Queen Mary University of London, November 22. ↩
    21. Rabinovich, Joel (2017). The financialisation of the nonfinancial corporation: A critique to the financial rentieralization hypothesis. CEPN working paper 2017-22. ↩
    22. Subasat, Turan & Stavros Mavroudeas (2023). Financialization Hypothesis: A Theoretical and Empirical Critique. World Review of Political Economy 14(2), 204–233. DOI: 10.13169/worlrevipoliecon.14.2.0204. Figures 6–7. ↩
    23. Marx, Karl (1894). Capital, vol. III, chapter 22. ↩
    24. Stravelakis, Nikos (2021). A Reconciliation of Marx’s Theory of Interest and the Risk Premium Puzzle. Presentation, PDF, especially slide 7. ↩
    25. Duque García, Carlos Alberto (2021, September). Economic Growth and the Rate of Profit in Colombia 1967–2019: A VAR Time-Series Analysis. Working paper, especially sections 5–6 and the sample-size note. ↩
    26. Carchedi, Guglielmo & Michael Roberts, eds. (2018). World in Crisis: A Global Analysis of Marx’s Law of Profitability. Haymarket Books. ↩
    27. Ricci, Andrea (2022). Global locational inequality: Assessing unequal exchange effects. Environment and Planning A: Economy and Space 54(7), 1323–1340. DOI: 10.1177/0308518X221107023. Table 2 and appendix 1. ↩

    Reading vocabulary

    Marxian refers to concepts, problems and arguments associated with Marx; Marxist, to traditions and programmes identifying with Marx’s work. Unequal exchange denotes a family of mechanisms and measurements, not one indicator. Super-exploitation requires an explicit definition relative to labour-power reproduction. MELT is a monetary labour relation defined within each interpretation. PPP means purchasing power parity and cannot simply be interchanged with current dollars. OCC and RSV denote organic composition of capital and rate of surplus value. IC and DC name the imperialist and dominated blocs in the Carchedi–Roberts figures.

    Further resources

    The following resources extend the essay’s definitions and debates. Research works, explanatory articles and reference materials serve different documentary functions.

    Explore conceptual and documentary resources
    1. Michael Roberts: IIPPE 2021
    2. Lenin: Spanish PDF
    3. Emmanuel: Unequal Exchange, PDF
    4. Self-similarity: conceptual reference
    5. Totality: systems theory article
    6. Essence and topology: philosophical study
    7. Isomorphism: philosophical dictionary
    8. Law: philosophical dictionary
    9. Matter: philosophical dictionary
    10. Laws: conceptual reference
    11. Induction/generalisation: reference
    12. Unity and struggle of opposites
    13. Emergence: conceptual reference
    14. Self-organisation: reference (not specifically self-organised criticality)
    15. Quantity and quality: philosophical dictionary
    16. Bifurcation theory
    17. Negation of the negation
    18. Chemical synthesis
    19. Author’s paper on Bayes estimators and Gaussian mixtures
    20. Value: archived dictionary entry
    21. Labour movements in the 1960s: thematic search
    22. Mediation: philosophical dictionary
    23. IIPPE: website
    24. Carchedi–Roberts presentation
    25. Lenin: English PDF
    26. John Smith: linked study
    27. Ricci: referenceed research paper
    28. Sam King: publisher record
    29. Sam King: thesis
    30. IIPPE China: YouTube channel
    31. Roberts: China presentation
    32. Roberts on capitalism and China
    33. Roberts on financialisation and profitability
    34. Mavroudeas: theoretical lecture
    35. Rabinovich: empirical paper
    36. Roberts on Austrian business-cycle theory
    37. Roberts on interest and stagflation
    38. Stravelakis: PPTX presentation
    39. Rosental–Iudin: PDF
    40. Yoshihara–Veneziani: PDF
    41. Duque García: PDF
    42. World in Crisis: PDF
    43. Andrea Ricci: book PDF

    JOSÉ MAURICIO GÓMEZ JULIÁN · Marxist Philosophy of Science

    Political economy, dialectical materialism and the investigation of social structures.

    READ MICHAEL ROBERTS’S ARTICLE
  • WHAT IS A SPURIOUS CORRELATION?: THE CASE OF CRIME AND SKIN COLOR

    WHAT IS A SPURIOUS CORRELATION?: THE CASE OF CRIME AND SKIN COLOR

    Statistics · Causal inference · Political economy

    What Is a Spurious Correlation?

    Crime and Skin Color: Confounding, Social Inequality, and the Limits of Crime Statistics

    Original publication: September 21, 2021 · Expanded revision: November 2, 2026

    01 · An observed difference does not explain its cause

    A table may show that two variables change together while leaving unresolved why they do so. When the subject is crime and racial classification, that distance between observation and explanation is decisive: a territorial or administrative association does not demonstrate an individual biological predisposition.

    The problem cannot be resolved by rejecting the data or accepting their interpretation without scrutiny. We must reconstruct what was counted, who was observed, how the groups were formed, and which historical and institutional processes could produce the pattern. Scientific criticism requires both rigorous measurement and clarity about the proposed mechanisms.

    This version develops the pedagogical question behind the original post, which drew on Gujarati and Porter and on Ritchey. Their references are retained as background; the argument is reconstructed here through an original exposition, a reproducible exercise, and additional methodological and empirical literature. Passages from those editions are not reproduced as direct quotations. [1][2]

    02 · Association, correlation, prediction, and causation

    Association means that the distribution of one variable differs across values of another. Correlation usually denotes a specific measure of covariation, such as Pearson’s coefficient. Prediction involves anticipating an outcome using available information. Causation asks how an outcome would change under a specified modification or intervention. These tasks are not interchangeable.

    ρXY = Cov(X, Y) / (σX σY)

    The covariance in the numerator captures how X and Y deviate jointly from their means. The denominator removes their units through the standard deviations. The expression requires finite, positive variances. A value near zero indicates little linear association; it does not rule out a nonlinear relationship or establish independence.

    In the causal sense relevant here, an association is spurious relative to an interpretation when the observed pattern does not justify the direct effect attributed to it and may arise from other processes. The term is also used for sampling coincidences, extensive searches across relationships, and shared trends. Naming the specific mechanism matters because these are not all the same problem.

    The statistical relationship may be real; the causal explanation attributed to it may be mistaken.

    A variable may improve a forecast because it summarizes inequalities or institutional decisions without representing a biological mechanism. A causal explanation requires assumptions beyond fitting a regression. The potential-outcomes framework helps formulate this distinction. [3]

    03 · What “skin color,” “race,” and “crime” mean

    Pigmentation is a phenotypic characteristic that can be measured in different ways. Socially assigned race captures how other people or institutions classify someone. Racial or ethnic self-identification records a situated personal response. Genetic ancestry estimates inheritance relationships using data and reference populations. These are not equivalent measurements. [4]

    An analysis must therefore specify who classifies, with which instrument, at what time, and under which categories. It must also recognize that the meaning of those categories may vary across countries and institutions. A category recorded by police does not thereby become a measurement of ancestry.

    Before calculation: define the object of study
    DimensionDecision to make explicit
    UnitPerson, household, neighborhood, municipality, or police encounter.
    ClassificationMeasured pigmentation, self-identification, or external classification.
    OutcomeAct committed, victimization, report, arrest, charge, or conviction.
    ExposurePopulation, observation time, journeys, contacts, or relevant opportunities.
    ContextOffense type, territory, period, and data source.

    There is no single homogeneous variable called “criminality” that allows homicide, corporate fraud, traffic offenses, and environmental crimes to be combined without qualification. Their opportunities, harms, and detection processes may differ. Selecting the behaviors to study is part of defining the problem.

    04 · From event to record: how the data are constructed

    An event may go unreported; a report may not lead to arrest; an arrest does not establish guilt; a conviction is an outcome of the judicial process. These transitions require analysis in their own right. Victimization surveys and police records have different coverage: the former may capture unreported events, whereas the latter record what is reported and institutionally recognized. [5]

    As a teaching model, if C is the number of relevant events and q is the common probability that each event is recorded, then:

    E[R | C, q] = Cq

    The formula assumes that each event can generate at most one record and that there are no false or duplicate records. This equality of expectations does not require independence between events; independence would be an additional assumption for a binomial distribution. Real processes may violate several of these conditions. The equation illustrates that recording depends on both occurrence and observation.

    If q varies across territories, different recorded rates may reflect differences in occurrence, observation, or both. Looking only at the final total cannot determine which explanation matters more. Reporting, patrol allocation, investigation criteria, event classification, and source coverage would have to be studied.

    05 · A fictional example: 84 versus 36

    Construct two sets of neighborhoods, A and B, over one year. They do not represent ethnicities or countries. Their populations remain constant, and resident-years approximate exposure. Each incident is assigned to its location of occurrence and counted once. Two deprivation strata are distinguished without claiming that the label is a sufficient cause of crime.

    Table 1. Data constructed exclusively for illustration
    DeprivationSetIncidentsResident-yearsRate per 1,000
    HigherA80800100
    LowerA420020
    HigherB20200100
    LowerB1680020
    Total AA841,00084
    Total BB361,00036
    Rate = 1,000 × incidents / resident-years

    The numerator counts events; the denominator measures exposure. 84 incidents per 1,000 resident-years does not mean that 8.4% of people committed a crime. One person might be connected with several events, several perpetrators might participate in one event, and someone committing an act might live elsewhere.

    The crude rate ratio is 84/36 = 7/3 ≈ 2.333. The crude difference is 48 incidents per 1,000 resident-years. Within each stratum, however, A and B have identical rates: 100 versus 100 and 20 versus 20. Here, by construction, the aggregate difference comes from composition: A has 80% of its exposure in the higher-rate stratum, while B has 20%.

    This table establishes the mathematical possibility of a compositional mechanism. It cannot estimate its importance in a real population, let alone attribute an individual predisposition to people.

    06 · Comparing equivalent compositions

    The overall rate is a weighted mean of stratum-specific rates. If g identifies the set and z the stratum:

    rg = Σz wgz rgz,   Σz wgz = 1

    rgz is the rate within the stratum; wgz is its exposure share. Thus rA = 0.8 × 100 + 0.2 × 20 = 84, whereas rB = 0.2 × 100 + 0.8 × 20 = 36. Equal rates are combined with different weights.

    For a standardized descriptive comparison, assign both sets a reference exposure split equally between the strata. These common weights are an explicit choice in the exercise:

    rAstd = rBstd = 0.5 × 100 + 0.5 × 20 = 60

    The standardized ratio is 1 and the difference is 0. Another common distribution would produce a different rate level but preserve equality because the stratum-specific rates coincide. Standardization is not automatically an intervention and does not by itself turn this comparison into a causal effect.

    The example shows a difference disappearing after stratification. In a Simpson reversal, the direction of the aggregate association opposes that of the within-stratum associations. That is not what happens here. Simpson’s paper is a classic starting point for examining these aggregation problems. [6]

    07 · The mathematical architecture of association

    The law of total covariance separates two components of an association. For variables with finite second moments:

    Cov(X, Y) = E[Cov(X, Y | Z)]
    + Cov(E[X | Z], E[Y | Z])

    The first term averages the covariation of X and Y within the strata defined by Z. The second captures how their means change jointly between strata. Total covariance can be present even when every within-stratum covariance is zero.

    Conceptual and algebraic derivation

    By definition, Cov(X,Y) = E[XY] − E[X]E[Y]. Iterated expectation gives E[XY] = E[E[XY|Z]]. Within each stratum, E[XY|Z] = Cov(X,Y|Z) + E[X|Z]E[Y|Z]. Substituting leaves E[E[X|Z]E[Y|Z]] − E[E[X|Z]]E[E[Y|Z]], precisely the covariance between the two conditional means. This yields the identity.

    This decomposition is algebraic. It does not identify Z as a cause or justify calling it a confounder without a causal hypothesis. Nor should the four-row table be treated as four interchangeable individual observations: their exposures differ and their units are aggregates. The exercise concerns rates; it does not estimate an individual correlation between race and behavior.

    08 · Confounding, mediation, and selection: three different questions

    The following diagrams are teaching models, not established maps of a society. An arrow represents a proposed causal influence; the absence of an arrow also expresses an assumption. A diagram makes these choices open to examination. [7]

    Confounding: a common cause

    Z · common cause
    X · exposure
    Y · outcome
    Model 1. Z → X and Z → Y; the drawing does not posit X → Y.

    In this model, the path X ← Z → Y may generate association without an effect of X on Y. Adjusting for an appropriate variable may block that path. Two variables being correlated with Z is not sufficient, by itself, to establish this structure.

    Mediation: a pathway that is part of the effect

    D · discriminatory treatment
    M · material opportunities
    Y · defined outcome
    Model 2. D → M → Y. M belongs to the proposed causal pathway.

    If the question concerns the total effect of D, adjusting for M may exclude part of the mechanism of interest. A direct effect raises another question and requires its own assumptions. This diagram does not imply that all inequalities work this way. In regressions involving racial classifications, interpreting adjustment requires attention to temporal order and to which variables might be consequences of the processes studied. [8]

    Selection: studying only those who entered the records

    X · differential treatment
    S · selection
    U · another cause
    Model 3. X → S ← U. Restricting analysis to S = 1 can associate X and U.

    S is a collider because two arrows point into it. Conditioning on it may open an association that was previously absent. [9] If U also affects a subsequent outcome Y, selection may distort the analysis of X and Y. Policing applications must separately model decisions to stop, record, and act afterward: this minimal diagram does not replace that work.

    09 · Why a neighborhood is not a person

    The ecological fallacy involves attributing a relationship observed between aggregates to individuals without information justifying that step. This does not make territorial studies useless: it delimits the conclusions they support. Robinson provided a classic formulation of the distinction between ecological and individual correlations. [10]

    Suppose a neighborhood has a particular demographic composition and a high incident rate. That information does not identify perpetrators, their residence, or the circumstances of each event. It also does not automatically distinguish exposure to victimization from participation as a perpetrator. Those are different variables and social roles.

    The reverse error matters too: individual data alone do not adequately describe every contextual effect. Research may require personal and territorial levels, relationships between them, and spatial dependence. A multilevel model organizes part of that structure but does not automatically remove confounding or turn coefficients into causal effects.

    Moving between scales requires compatible data and defensible assumptions. Scale is not a presentation detail; it is part of the object under study.

    10 · Class, racialization, and institutions: mechanisms to investigate

    A historical-materialist reading asks how access to livelihoods, property, labor, urban space, and state power is organized. This essay proposes investigating how these relations may unequally distribute opportunities, exposure to harm, and possibilities for protection.

    Racialization may operate through specific practices: restrictions on housing access, hiring criteria, credit barriers, or differential institutional treatment. The relationship between these practices and class position requires historical investigation. Neither reducing racism to an individual opinion nor using “class” as a variable that explains every outcome in advance is sufficient.

    Criticism of a biological interpretation becomes more precise by reconstructing mechanisms and evidence rather than replacing racial essence with a destiny of poverty. A material position does not determine each person’s behavior. Offense types, opportunities to commit them, and the capacity to avoid detection may be distributed differently.

    It is also necessary to study which harms become legally defined and recorded and how economic, corporate, or environmental offenses are investigated. Statistics centered on certain visible offenses do not automatically represent every harmful behavior or every legally defined infraction.

    In debates such as those associated with Black Lives Matter, the relevant object includes institutions and historical experiences of racialization. Sharing distant evolutionary ancestry does not erase the differences between those contemporary social positions.

    11 · What empirical research contributes and what remains open

    Sampson, Morenoff, and Raudenbush (2005) studied violence using longitudinal Chicago data and individual, family, and neighborhood characteristics. They found that contextual and family-background variables statistically accounted for an important part of the differences examined. The observational design and its setting prevent turning that result into a universal law or equating a coefficient’s reduction with proof of one exclusive causal mechanism. [11]

    Knox, Lowe, and Mummolo (2020) examined a different problem: when the police decision to investigate determines who appears in the data and that decision is affected by discrimination, selected records may distort estimates of subsequent treatment. Their methodological result does not license assigning one fixed magnitude of bias to all police agencies. [12]

    These contributions serve different purposes. The first supplies situated evidence about social composition and context; the second formalizes a selection problem. Neither should be confused with our A/B table, which was constructed to teach the arithmetic of rates.

    A residual difference after adjustment does not establish a genetic explanation: it may reflect incomplete measurement, selection, omitted causes, or misspecification. Conversely, a reduced difference does not show that the entire effect of discrimination has been identified. Each conclusion requires stating which alternative was assessed and with what evidence.

    12 · Note: African ancestry and different genealogies

    Cann, Stoneking, and Wilson (1987) analyzed mitochondrial DNA from 147 people and proposed a shared maternal ancestry probably located in Africa. This reconstructs one line of inheritance, not a direct date for the origin of the species or a claim that only one woman existed at that time. [13]

    Subsequent nuclear-genomic findings also provided evidence of gene flow between Neanderthals and ancestors of present-day humans. A general description of human expansion as complete replacement without admixture is therefore inadequate. [14]

    Distant evolutionary ancestry, a family’s genealogy, and Afro-descendant identification concern different scales and questions. The historical-social use of “Afro-descendant” may refer to experiences and ties formed within particular diasporas and societies; it does not claim to describe the whole evolutionary genealogy of humanity.

    Recognizing these differences allows shared evolutionary history and the specificity of contemporary discrimination to be acknowledged together. Neither issue is resolved through a territorial correlation between population composition and incidents.

    13 · A reproducible demonstration in R

    The following code uses only base R functions and the stats package included in a standard installation. The data are contained in the script itself. There is no data download or random simulation. The labels A/B do not encode racial categories.

    # Spurious association / asociacion espuria
    # FICTIONAL data: no racial categories or empirical crime estimates.
    # Datos FICTICIOS: sin categorias raciales ni estimaciones empiricas.
    # Base R + stats only. Counts are incidents, not people or binary trials.
    
    d <- data.frame(
      group = factor(c("A", "A", "B", "B"), levels = c("B", "A")),
      deprivation = factor(c("high", "low", "high", "low"),
                           levels = c("low", "high")),
      incidents = c(80, 4, 20, 16),
      exposure = c(800, 200, 200, 800)
    )
    stopifnot(all(d$exposure > 0), all(d$incidents >= 0))
    d$rate_1000 <- 1000 * d$incidents / d$exposure
    print(d)
    
    # Crude rates / tasas crudas
    crude <- aggregate(cbind(incidents, exposure) ~ group, data = d, FUN = sum)
    crude$rate_1000 <- 1000 * crude$incidents / crude$exposure
    print(crude)
    r <- setNames(crude$rate_1000, as.character(crude$group))
    cat("Crude rate ratio A/B:", unname(r["A"] / r["B"]), "\n")
    cat("Crude rate difference A-B:", unname(r["A"] - r["B"]), "\n")
    
    # Incident counts with a log-exposure offset; reference group = B.
    m_crude <- glm(incidents ~ group + offset(log(exposure)),
                   family = poisson(link = "log"), data = d)
    m_adjusted <- glm(incidents ~ group + deprivation + offset(log(exposure)),
                      family = poisson(link = "log"), data = d)
    rr_crude <- unname(exp(coef(m_crude)["groupA"]))
    rr_adjusted <- unname(exp(coef(m_adjusted)["groupA"]))
    rr_deprivation <- unname(exp(coef(m_adjusted)["deprivationhigh"]))
    print(c(crude_A_over_B = rr_crude,
            adjusted_A_over_B = rr_adjusted,
            adjusted_high_over_low = rr_deprivation))
    
    # Standardization to common exposure shares: low = 0.5, high = 0.5.
    grid <- expand.grid(group = levels(d$group),
                        deprivation = levels(d$deprivation),
                        KEEP.OUT.ATTRS = FALSE, stringsAsFactors = FALSE)
    grid$group <- factor(grid$group, levels = levels(d$group))
    grid$deprivation <- factor(grid$deprivation, levels = levels(d$deprivation))
    grid$exposure <- 1000
    # At exposure = 1000 the predicted count is the rate per 1000.
    grid$rate_1000 <- predict(m_adjusted, newdata = grid, type = "response")
    weights <- c(low = 0.5, high = 0.5)
    grid$weighted_rate <- grid$rate_1000 * weights[as.character(grid$deprivation)]
    standardized <- aggregate(weighted_rate ~ group, data = grid, FUN = sum)
    names(standardized)[2] <- "standardized_rate_1000"
    print(standardized)
    
    # Arithmetic/model checks for this constructed example only.
    stopifnot(abs(unname(r["A"]) - 84) < 1e-8,
              abs(unname(r["B"]) - 36) < 1e-8,
              abs(rr_crude - 7/3) < 1e-7,
              abs(rr_adjusted - 1) < 1e-7,
              abs(rr_deprivation - 5) < 1e-7,
              all(abs(standardized$standardized_rate_1000 - 60) < 1e-6))
    
    # Common exposure rescaling changes the intercept, not the rate ratios.
    scaled <- d
    scaled$exposure <- scaled$exposure * 1000
    m_scaled <- glm(incidents ~ group + deprivation + offset(log(exposure)),
                    family = poisson(link = "log"), data = scaled)
    stopifnot(abs(unname(exp(coef(m_scaled)["groupA"])) - 1) < 1e-7,
              abs(unname(exp(coef(m_scaled)["deprivationhigh"])) - 5) < 1e-7)
    
    # No p-values or confidence intervals are interpreted for artificial cells.
    cat("All example checks passed. / Comprobaciones del ejemplo superadas.\n")
    sessionInfo()
    
    Table 2. Deterministic results for the constructed dataset
    QuantityExpected result
    Crude rates A / B84 / 36 per 1,000 resident-years
    Crude ratio A/B2.333333…
    Adjusted ratio A/B1.000000
    Adjusted higher/lower deprivation ratio5.000000
    Standardized rates A / B60 / 60 per 1,000 resident-years

    What the model represents

    log(μgz) = log(Egz) + β0
    + βA I(g = A) + βH I(z = high)

    μgz is the expected count and Egz is exposure. The term offset(log(exposure)) introduces exposure with its coefficient fixed at 1; it is not a covariate whose coefficient is estimated. I equals 1 when the condition holds and 0 otherwise. B and lower deprivation are the reference categories. Exponentiating βA compares A/B rates at the same stratum; exponentiating βH compares strata at the same set. [15][16]

    The crude model uses only set; the adjusted model includes stratum. The Poisson family with log link is useful for displaying this count-and-exposure structure. It does not turn incidents into binary trials. A binomial model requires a success/failure outcome with defined trials; subtracting incidents from residents does not justify it.

    The code standardizes through predictions for an exposure of 1,000 resident-years and common weights of 0.5/0.5. Internal checks verify the example’s values and their invariance to using a common exposure scale. Adjusted equality remains a property of the fictional dataset.

    14 · How to assess a causal explanation in a real case

    An investigable question must specify the population, period, outcome, and intervention. For example: how would a particular rate change under a defined housing-access policy, or how would a police decision vary if perceived racial information changed while other encounter characteristics were held constant? These questions require different designs.

    1. Define the objective. Separate disparity description, prediction, and the effect of an intervention. Specify whether a total, direct, or mediated effect is of interest.
    2. Document measurement. Identify origin, coverage, categories, exclusions, duplicates, and denominators. Distinguish event location from residence.
    3. Represent time. Establish what precedes what. If feedback exists, use time-indexed variables; a static DAG does not represent simultaneous cycles.
    4. Justify adjustment. Choose variables by their proposed causal role, not their p-value or a coefficient’s change alone.
    5. Examine identification. For effects of defined interventions, discuss consistency, conditional comparability, and positivity; in interconnected neighborhoods, consider possible effects between units. [3]
    6. Seek complementary designs and sources. Triangulate records, surveys, and focused studies; consider experiments, audits, or policy changes when relevant. Their assumptions must be defended in each application.
    7. Quantify uncertainty and sensitivity. Distinguish sampling error from selection and measurement bias. Consider unobserved causes and alternative specifications.
    8. Delimit generalization. A local estimate does not automatically transfer to other periods, countries, or offense types.

    Conditional comparability assumes, for the selected objective, the absence of uncontrolled common causes; regression cannot establish it by itself. Positivity requires the compared alternatives to be possible in the relevant strata. Consistency requires the intervention and its versions to be defined sufficiently well.

    From this perspective, theory guides the search for mechanisms but must also face evidence capable of correcting it. A materialist explanation becomes stronger when it specifies processes, distinguishes scales, and accepts the analysis’s identification limits.

    15 · What the analysis supports

    A statistical difference between groups requires explanation; it does not contain a theory of its causes. The fictional table demonstrates that composition can produce an aggregate difference even when stratum-specific rates are equal. Measurement, selection, and scale problems show why causal interpretation requires further work.

    Regarding crime and skin color, the scientific question is how material conditions, social classifications, and institutions participate in defined and observed outcomes. The analysis presented supplies no evidence of a racial biological predisposition; nor does it estimate one social mechanism valid for every context.

    Explaining an association requires studying both the processes that produce events and the institutions that turn them into data.

    References and further reading

    References 1–2 are bibliographic antecedents of the original post. The remaining sources support the methodological distinctions and identified studies; the historical-materialist interpretation and A/B example are developments of this essay. Web resources accessed November 2, 2026.

    1. Gujarati, D. N., & Porter, D. C. (2010). Econometría (5.ª ed.). McGraw-Hill Interamericana. ISBN 9786071502940.
    2. Ritchey, F. J. (2002). Estadística para las ciencias sociales. McGraw-Hill. ISBN 9789701031414.
    3. Hernán, M. A., & Robins, J. M. (2020). Causal Inference: What If. Chapman & Hall/CRC. Read source.
    4. National Human Genome Research Institute. Use of Population Descriptors in Genomics. Read source.
    5. Bureau of Justice Statistics. Crime: administrative records and victimization surveys. Read source.
    6. Simpson, E. H. (1951). The interpretation of interaction in contingency tables. JRSS Series B, 13(2), 238–241. DOI: 10.1111/j.2517-6161.1951.tb00088.x. Read source.
    7. Greenland, S., Pearl, J., & Robins, J. M. (1999). Causal diagrams for epidemiologic research. Epidemiology, 10(1), 37–48. DOI: 10.1097/00001648-199901000-00008. Read source.
    8. VanderWeele, T. J., & Robinson, W. R. (2014). On causal interpretation of race in regressions adjusting for confounding and mediating variables. Epidemiology, 25(4), 473–484. DOI: 10.1097/EDE.0000000000000105. Read source.
    9. Shrier, I., & Platt, R. W. (2008). Reducing bias through directed acyclic graphs. BMC Medical Research Methodology, 8, 70. DOI: 10.1186/1471-2288-8-70. Read source.
    10. Robinson, W. S. (1950). Ecological correlations and the behavior of individuals. American Sociological Review, 15(3), 351–357. DOI: 10.2307/2087176. Read source.
    11. Sampson, R. J., Morenoff, J. D., & Raudenbush, S. (2005). Social anatomy of racial and ethnic disparities in violence. American Journal of Public Health, 95(2), 224–232. DOI: 10.2105/AJPH.2004.037705. Read source.
    12. Knox, D., Lowe, W., & Mummolo, J. (2020). Administrative records mask racially biased policing. American Political Science Review, 114(3), 619–637. DOI: 10.1017/S0003055420000039. Read source.
    13. Cann, R. L., Stoneking, M., & Wilson, A. C. (1987). Mitochondrial DNA and human evolution. Nature, 325, 31–36. DOI: 10.1038/325031a0. Read source.
    14. Green, R. E., et al. (2010). A draft sequence of the Neandertal genome. Science, 328(5979), 710–722. DOI: 10.1126/science.1188021. Read source.
    15. R Core Team. glm: Fitting Generalized Linear Models. R statistical documentation. Read source.
    16. R Core Team. family: Family Objects for Models; offset: Include an Offset in a Model Formula. R statistical documentation. Read source.

    Fictional A/B data. Incident rates per exposure, not percentages of people committing crimes. Diagrams express teaching hypotheses.

    Read the original post
  • A CASE STUDY ON THE APPLICATIONS OF LINEAR REGRESSION MODELS: ANALYSIS OF WATER PURIFICATION TREATMENTS USING GENERALIZED LINEAR MODELS, PART I

    A CASE STUDY ON THE APPLICATIONS OF LINEAR REGRESSION MODELS: ANALYSIS OF WATER PURIFICATION TREATMENTS USING GENERALIZED LINEAR MODELS, PART I

    MATHEMATICAL STATISTICS · CASE STUDY · PART I

    Regression in Drinking-Water Treatment

    Aluminium sulfate dose, dosing-solution concentration and lime dose: Gaussian models and a critical assessment of assumptions.

    25 SEPTEMBER 2021 · REVISED: 2 NOVEMBER 2026

    1. The problem: from jar testing to prediction

    Chemical dosing in a treatment plant responds to water that changes. Turbidity, colour, pH and other properties shape the experimental choice of treatment. The statistical question is how far these measurements can anticipate the dose selected in the laboratory, and under what conditions that prediction remains defensible.

    This case study examines the investigation by Zulma Cepeda and Edilberto Cepeda C., published in 2005 in the Revista Colombiana de Estadística, concerning a plant in Girardot, Colombia, supplied by the Magdalena River. Its observations were collected in 1997. Three continuous responses are considered: aluminium sulfate dose, the concentration of its dosing solution, and lime dose. The reference study also models the probabilities of applying lime or polymer using logistic regression; that topic forms the continuation into Part II. [1]

    The purpose is both explanatory and critical: to interpret the equations and determine what the published record supports. This is an expanded methodological review, rather than a new fit to the original observations, which are not supplied with the documents examined. A reported result, a mathematical deduction and an empirical validation are distinct levels of evidence.

    An equation can summarise an observed treatment; its scientific usefulness also depends on how it was obtained, where it is applied and how it is assessed.

    2. The physical and chemical process

    The treatment process supplies the material context of the variables. Its stages have different functions, and the actual configuration depends on the plant and source water.

    1. Aeration. Promotes gas exchange with air and, under suitable conditions, oxidation of certain substances, including dissolved iron and manganese. Any resulting precipitates require subsequent removal. Aeration does not amount to disinfection.
    2. Coagulation. Adding a coagulant such as aluminium sulfate destabilises colloidal dispersions. Aluminium hydrolysis generates species and precipitates that can promote particle aggregation and capture; performance depends on conditions including pH and alkalinity.
    3. Flocculation. Controlled mixing promotes contact and aggregate growth. Polymers may assist floc formation. Coagulation and flocculation are related processes with distinguishable mechanisms and operating requirements.
    4. Sedimentation. Separates a fraction of solids through gravity. Solids concentration, settling velocity and turbidity are different properties and should not be treated as one interchangeable measurement.
    5. Filtration. Removes particles through a filtering medium using physical and physicochemical mechanisms. Its effectiveness depends on the medium and operating conditions.
    6. Disinfection. Seeks to inactivate microorganisms through a validated process. Lower turbidity can support its performance, but visibly clear water alone does not establish microbiological safety.

    Drinking-water safety requires assessment of microbial and chemical hazards, operation and distribution. Acceptability criteria —appearance, taste and odour— are a further, distinct consideration. WHO guidance separates health-based targets, risk management and surveillance; recommendations must be related to the applicable regulation and its date. [6]

    What “optimal” means here

    A jar test selects a reagent combination under specified experimental conditions and criteria. The regression predicts that selected response. Full operational optimisation would additionally require an explicit cost function, quality constraints, safety requirements and uncertainty assessment. Here, “optimal dose” therefore names an experimental response, rather than a universally optimal treatment for every water source.

    3. Variables, measurement and data provenance

    Table 1. Water properties: historical study ranges
    SymbolPropertyReported rangeInterpretation
    TURBTurbidity200–1200 NTUOptical response to particles; not a direct substitute for solids in mg/L.
    COLColour50–250 colour unitsDistinguish true/apparent colour and specify the measurement method.
    PHpH7.1–8.33Dimensionless quantity related to hydrogen-ion activity.
    ALCAAlkalinity43–55 mg/L as CaCO₃Acid-neutralising capacity; distinct from pH.
    DURHardness43–50, interpreted as mg/L as CaCO₃The range omits an explicit unit in the source; its context uses CaCO₃.
    TEMPTemperature24–28 °CThermal condition of the water in the study.

    These ranges describe the investigation; they are neither universal drinking-water limits nor evidence that every combination inside them was observed. The paper’s jar-test illustrations include alkalinities of 40 and 58 mg/L as CaCO₃, outside the general 43–55 range. This documentary difference is retained, rather than resolved through invented measurements. [1]

    Table 2. Each response has its own observations
    ResponseMeaningObservationsUnit or convention
    D_SULAluminium sulfate dose40mg/L of reagent applied to the water
    C_SULConcentration of the dosing solution20, a subset of the 40Solution concentration in percent
    D_CALLime dose33Dose; verify the exact recording convention
    Lime/polymer applicationBinary responses for Part II60 register observations, as reported0/1; distinct from amount applied

    Measurement distinctions

    pH is the negative base-ten logarithm of hydrogen-ion activity: pH = −log₁₀ a(H⁺). A concentration-based approximation relative to the standard state can be useful for sufficiently dilute solutions. pH is dimensionless: mol/L describes a concentration, not pH itself. Alkalinity measures acid-neutralising capacity; hardness is associated predominantly with calcium and magnesium.

    True colour is determined after removing particle interference through a specified procedure; apparent colour includes that contribution. Platinum-cobalt (Pt-Co) calibration and instrumental measurement are compatible: an instrumental reading can be expressed on that scale. One Pt-Co unit refers to the standard equivalent of 1 mg/L platinum in the specified reference solution. UV-visible spectrophotometry measures absorbance at specified wavelengths. Its application to biomolecules illustrates an instrumental principle, but does not automatically specify how colour was measured in this water.

    The Beer–Lambert relation, A = εℓc, connects absorbance A, absorption coefficient ε, optical path length ℓ and concentration c under its conditions of validity. It does not identify every environmental colour with a single biomolecule. Wavelength satisfies λ = v/f: the spatial separation of equal-phase states, related to propagation speed and frequency.

    Colour and turbidity thresholds, and pH intervals quoted by a historical paper, should be identified accordingly. Neither hardness of 30–50 mg/L nor temperature of 9–12 °C is a universal health requirement. WHO does not establish a general health-based guideline value for hardness at concentrations ordinarily found in drinking-water. [6]

    The paper locates measurements after sedimentation while describing the material as “raw water”. A replication would need to specify the sampling point. The 1997 observations must also be distinguished from the 2005 publication. Cepeda and Cepeda collected the observations; this review did not.

    4. How the experimental responses are constructed

    4.1. Aluminium sulfate dose

    The historical protocol uses a four-to-six-paddle mixer and 2000 mL beakers. Increasing doses are applied with rapid mixing at about 100 rpm for 30 seconds to 2 minutes, followed by slower flocculation mixing for 5–20 minutes and settling for 5–10 minutes. Where alkalinisation is needed, it precedes the coagulation test. Residual turbidity and colour are measured to select a dose. These settings describe the reference procedure, rather than a universal operating protocol. [1]

    Original graph: residual turbidity against sulfate doses from 30 to 55 mg/L; the lowest observed point is around 40 mg/L.
    Figure 1. Sulfate dose and residual turbidity. Original image retained from Cepeda and Cepeda (2005, p. 236, their Figure 1); reproduced as Figure 6 in the 2021 essay.

    In this illustration, 40 mg/L is the first tested dose below the 5 NTU reference line and is also the lowest plotted point. Reported initial conditions are 200 NTU turbidity, 100 colour units, pH 8.03, alkalinity of 40 mg/L as CaCO₃ and temperature of 24 °C. The line belongs to this historical example: crossing it alone does not establish drinking-water safety. Nor do these few points identify an exact continuous optimum between tested doses.

    4.2. Polymer and lime

    The polymer experiment varies its dose alongside sulfate dose, or keeps one fixed while varying the other. Residual turbidity, colour, pH, floc formation time and the Willcomb index, an indicator of floc characteristics, are assessed. The objective may include lowering cost subject to quality criteria. The historical wording “reduced in 75%” is ambiguous between reducing by 75% and reducing to 75%; replication requires explicit initial and final doses.

    For lime, the described procedure uses 1000 mL of water treated with the selected sulfate and polymer doses. If pH is below 7, lime is added until it reaches that value. This pre-addition pH refers to already treated water and must be distinguished from the inlet pH used as a predictor. The quantity added defines D_CAL for that protocol. Substance, purity and conversion from solution volume to applied mass require documentation.

    4.3. Sulfate dosing-solution concentration

    C_SUL concerns the concentration of the solution used to deliver the reagent; it is not residual sulfate concentration in finished water. A 10 g/L solution equals 1% mass/volume: 1 g per 100 mL of solution. If applied reagent mass is held constant while solution concentration changes, the delivered solution volume changes too.

    Original graph of residual turbidity against sulfate solution concentration in percent; the lowest observed point is near 2%.
    Figure 2. Sulfate dosing-solution concentration and residual turbidity. Original image retained from Cepeda and Cepeda (2005, p. 237); Figure 7 in the 2021 essay. Insufficiently identified curves are not reinterpreted as new fitted models.

    Reported initial conditions are 500 NTU turbidity, alkalinity of 58 mg/L as CaCO₃, pH 7.38 and 27 °C. The lowest plotted point is near 2%. The concentration list in the original text does not fully match the visible axis values, and not all curves are adequately identified. Both limitations are retained as documentary questions. No observations are reconstructed, and statistical significance is not inferred from the graph’s appearance.

    5. From normal regression to the generalised linear model

    A GLM combines a conditional response distribution, a linear predictor and a link. “Linear” refers to the parameter combination in the predictor; it neither requires every physical relationship to be a straight line nor turns association into causation.

    μi = E(Yi | xi),   ηi = β₀ + Σj=1q βjxij,   g(μi) = ηi

    Yᵢ denotes the response for observation i; xᵢ contains its predictors; μᵢ is its conditional mean; ηᵢ is the linear predictor; β₀ is the intercept and βⱼ are coefficients. The link connects the mean to the predictor, and its inverse returns the mean to the response scale. It does not directly transform each observed Yᵢ. [2]

    f(yi | θi, φ) = exp{[yiθi − b(θi)] / a(φ) + c(yi, φ)}

    This is a common exponential dispersion-family representation. θᵢ is the canonical parameter, φ controls dispersion, and a, b and c specify the family. In this parameterisation, μᵢ = b′(θᵢ) and Var(Yᵢ | xᵢ) = a(φ)b″(θᵢ). Membership in the exponential family does not mean that the response necessarily follows an exponential distribution.

    Yi | xi ∼ N(μi, σ²),   g(μi) = μi,   μi = xiTβ

    For a Gaussian model with identity link, the mean equals the linear predictor. The equivalent expression Yᵢ = xᵢᵀβ + εᵢ introduces random error, with E(εᵢ | X) = 0. Under joint normality, independence and common variance, the vector satisfies ε | X ∼ Nₙ(0, σ²Iₙ). Iₙ is the n × n identity matrix; σ²Iₙ, rather than σ² alone, is the covariance matrix.

    With full column rank, ordinary least squares gives β̂ = (XᵀX)⁻¹Xᵀy. Under the homoscedastic normal model this equals the maximum-likelihood estimator of β. The expression projects the response onto the space spanned by the columns of X. Numerically stable methods such as QR decomposition are preferable to explicitly inverting XᵀX.

    General GLM fitting can use iteratively reweighted least squares —IRLS or IWLS—; weights simplify for a normal model with identity link. The 2005 paper does not document its computational algorithm sufficiently to attribute a specific implementation to it here. R documentation explains the default algorithm used by glm(). [3]

    6. Model I: aluminium sulfate dose

    The initial model includes five predictors and an intercept:

    D_SULi = β₀ + β₁ TURBi + β₂ COLi + β₃ ALCAi + β₄ PHi + β₅ TEMPi + εi

    The observed dose varies around a mean that depends on water properties. After backward elimination, the study reports the following mean model with R² = 0.991. That value is retained as a published result, subject to the consistency check in Section 10. [1]

    μ̂D_SUL = −13.571 + 0.085 TURB + 1.592 TEMP

    Turbidity. Holding temperature constant, one additional NTU is associated with an estimated dose increase of 0.085 mg/L; 100 NTU correspond to 8.5 mg/L. Temperature. Holding turbidity constant, an increase of 1 °C is associated with 1.592 mg/L more. These are conditional model associations, not independently established causal effects. Intercept. −13.571 positions the regression surface. TURB = 0 and TEMP = 0 are outside the study ranges, so its value should not be read as a physically applicable dose at that point.

    An educational example, not a recovered observation: for TURB = 500 and TEMP = 26,

    μ̂D_SUL = −13.571 + 0.085(500) + 1.592(26) = 70.321 mg/L

    This estimates the conditional mean of the experimentally selected dose, rather than residual turbidity or a probability of safe drinking-water. The paper interprets temperature in terms of coagulation. That physicochemical discussion must be distinguished from the coefficient’s sign and the specific temperature and mixing conditions. The equation does not establish a universal law that cooling water always improves treatment.

    7. Model II: sulfate dosing-solution concentration

    The initial formulation adds hardness to the previous five properties:

    C_SULi = β₀ + β₁ TURBi + β₂ COLi + β₃ ALCAi + β₄ PHi + β₅ TEMPi + β₆ DURi + εi

    The reported initial R² is 0.530, with individual coefficient p-values above 0.05. The reduced model is:

    μ̂C_SUL = −1.597 + 0.445 PH

    The reduced model has R² = 0.413, with reported p = 0.133 for the intercept and p = 0.003 for the slope. Changes in significance between models are not automatically contradictory: removing predictors changes estimates, their variances and the conditional tests. The source does not fully document the selection trajectory. [1]

    If C_SUL is expressed as a percentage, one additional pH unit is associated with 0.445 percentage points, not a 44.5% relative increase. A pH unit corresponds to a tenfold change in hydrogen-ion activity, a reminder that the predictor itself has a logarithmic scale.

    For PH = 8, the illustrative calculation is:

    μ̂C_SUL = −1.597 + 0.445(8) = 1.963%

    The documented pH interval is 7.1–8.33. The model accounts for part of the observed variation; R² = 0.413 is not a 41.3% probability of a correct prediction. Nor does predicted concentration alone determine the reagent mass delivered: concentration and solution volume must be combined.

    An intercept should not be removed merely because its p-value exceeds 0.05. Forcing the line through the origin imposes C_SUL = 0 at PH = 0, far outside the study domain and without a supplied physical justification. Retaining it preserves a reasonable parameterisation for the observed interval; demonstrating superior prediction would require data-based model comparison.

    8. Model III: lime dose and a transcription correction

    The initial formulation again uses five predictors:

    D_CALi = β₀ + β₁ TURBi + β₂ COLi + β₃ ALCAi + β₄ PHi + β₅ TEMPi + εi

    The source reports R² = 0.930 for the initial model and R² = 0.915 for the reduced model. The latter retains turbidity, colour and pH, with reported coefficient p-values below 0.01:

    μ̂D_CAL = 59.374 + 0.01262 TURB + 0.07746 COL − 8.831 PH

    Holding the remaining predictors constant, another 100 NTU is associated with 1.262 more dose units; another 10 colour units with 0.7746 more; and a 0.1 increase in pH with 0.8831 fewer. The negative pH coefficient is compatible with a lower need for alkaline correction when inlet pH is higher, but it does not replace process analysis or measurement of pH after coagulation.

    For TURB = 500, COL = 100 and PH = 8:

    μ̂D_CAL = 59.374 + 0.01262(500) + 0.07746(100) − 8.831(8) = 2.782

    The result is in the recording units of D_CAL. The examined source does not specify that measurement convention as clearly as it specifies sulfate dose; no undocumented conversion is added here. This is an arithmetic example, not a recovered observation or an operational dosing recommendation.

    A physical constraint the line does not enforce

    With TURB = 200, COL = 50 and PH = 8.33, the equation returns −7.79123. Although each value lies inside its marginal range, the combination may not have been observed. A negative amount of lime has no interpretation as a physical addition. This signals a limitation of the application domain or model specification; it does not establish that negative doses occurred in the original sample.

    Automatically replacing that value with zero introduces a further rule requiring justification and validation. If many zero doses coexist with positive amounts, a two-stage model —application probability followed by amount conditional on application— could be investigated. For strictly positive responses, alternative families and links, such as Gamma with a log link, could be compared. These are research directions, not models fitted here.

    9. Variable selection and inference

    Individual, global and partial tests

    An individual test may evaluate H₀: βⱼ = 0 against H₁: βⱼ ≠ 0, conditional on the other included terms. A global test may assess whether all slopes are zero. A partial test can also concern a block of coefficients, rather than only one.

    F = [(SSER − SSEF) / (pF − pR)] / [SSEF / (n − pF)]

    For nested Gaussian models, SSE_R and SSE_F are the residual sums of squares of reduced and full models; p_R and p_F count coefficients, including the intercept, and n is their common number of observations. The numerator measures the increase in residual error per removed coefficient, while the denominator estimates residual variance. Under the model conditions and null hypothesis, the statistic follows an F distribution with p_F − p_R and n − p_F degrees of freedom. For one restriction, the equivalent statistic satisfies F = t². Comparing different samples invalidates this interpretation. [4]

    A p-value is not the probability that the null hypothesis is true, an effect size, or the probability that a prediction will be correct. A non-significant result also does not prove chemical irrelevance.

    What backward elimination establishes

    The procedure starts from a set of terms and removes some according to a criterion. The first model reports a 0.01 threshold. The statement that final p-values are below 0.01 concerns the retained coefficients and should not be transferred to discarded predictors. The remaining models do not document every selection step or threshold.

    “No loss of information” needs a specified meaning: in-sample fit, a model-comparison test, an information criterion or predictive performance. Selection may produce instability and overoptimistic post-selection p-values if the same data-dependent choice is ignored. Effect sizes, uncertainty and validation should accompany the significance threshold.

    This edition does not attribute the origin of partial tests to 2018 publications: the 2005 source already uses the expression. Li and colleagues’ 2009 paper on partial hypothesis re-ranking is removed as statistical support because its hypotheses are candidate partial translations in a machine-translation system, rather than partial regression tests. [8]

    10. Correlation, fit and an unresolved inconsistency

    Table 3. Simple correlations reproduced from Cepeda and Cepeda (2005, p. 239)
    VariableTURBCOLALCAPHTEMP
    D_SUL0.978**0.517**−0.1960.133−0.266
    TURB10.485**−0.1190.156−0.337*
    COL—1−0.448**0.048−0.046
    ALCA——1−0.2070.181
    PH———1−0.408*

    ** and * indicate two-sided significance at 0.01 and 0.05, respectively, as reported. Dashes fill the omitted triangular portion; they do not mean zero correlation. Hardness is absent from this table.

    The strongest simple association with D_SUL is turbidity, r = 0.978. The simple dose–temperature correlation is −0.266 although the temperature coefficient in the multiple model is positive. A marginal correlation summarises association without holding other predictors constant; a partial coefficient describes a conditional relationship. Sign differences can arise when the joint predictor structure is controlled and do not independently establish error or causation.

    R² = 1 − SSE/SST,   SSE = Σ(yi − ŷi)²,   SST = Σ(yi − ȳ)²

    For ordinary least squares with an intercept, SSE measures residual variation and SST the variation of the response around its mean. R² expresses the fraction accounted for by the fit. Ordinary R² cannot decrease when predictors are added, so it is insufficient for comparing complexity or establishing prediction quality. A high value can coexist with misspecification, heteroscedasticity, dependence or extrapolation. [5]

    A reproducible algebraic check

    If the printed correlations describe exactly the observations used in the reduced sulfate model, fitted by unweighted ordinary least squares with an intercept, its R² can be reconstructed:

    R² = [ryT² + ryθ² − 2ryTryθrTθ] / [1 − rTθ²]

    Here T abbreviates turbidity and θ temperature solely for this identity. Substituting 0.978, −0.266 and −0.337 gives R² ≈ 0.961045, compared with the reported 0.991. This is a deduction from printed correlations, not a refit to individual observations. Simply rounding the result to three decimals does not explain the difference.

    The missing observations and fitting provenance prevent identification of the cause: a typographical error, sample differences, weights or another fitting detail. The reported 0.991 is preserved and the conditional inconsistency disclosed, rather than replaced by a result portrayed as conclusively validated.

    The decrease from 0.530 to 0.413 for concentration, and from 0.930 to 0.915 for lime, concerns different models and different responses. These values should not become a direct ranking of operational usefulness. Prediction errors in each response’s units and explicit use criteria would be needed.

    11. Assumptions: what is specified and what can be assessed

    An audit should distinguish specification —what the model assumes—, reported evidence —what the paper shows— and reproducibility —what another researcher can assess from the available materials. An unpublished diagnostic is not evidence of a failed assumption; a normality statement in an equation is not evidence that normality has been empirically supported.

    Table 4. Revision of the seven methodological issues
    AspectRelevant formulationProposed assessment
    Dimensional coherencePredictors need not share units. Each coefficient translates its predictor’s scale to the response scale.Document units and calibration; standardise when useful while retaining interpretability.
    IdentifiabilityUnique coefficients require full column rank of X, including the intercept column.Rank or QR, VIF and conditioning; pairwise correlations do not exclude multivariate dependencies.
    Conditional meanμ(X) depends on X; independence from X is not required. In the additive model, E(ε | X) = 0.Design justification and relevant predictors; an isolated correlation test does not verify exogeneity.
    Family and dispersionThe distributional assumption concerns Y | X. Here: conditional normality and constant variance.Residuals against fits and predictors; normal quantile plots, scale-location assessment and context.
    Link and functional formThe model is g(μ) = Xβ. Parameter linearity may include justified predictor transformations.Residual structure, nonlinear terms or interactions and model comparison; RESET is only one limited tool.
    DependenceOrdinary GLMs assume conditional independence across observations; they do not automatically resolve serial correlation.Dates, batches, sampling and temporal plots; where appropriate, ACF and dependence-aware models or standard errors.
    Size and stabilityThere is no universal rule about 20% of sampling units containing fewer than five observations.Effective observations relative to parameters, precision, coverage, influence and validation.

    The correlation matrix is genuine descriptive evidence and should be acknowledged. It nevertheless does not supply the complete design, individual responses or residuals needed for a full audit. A chi-square independence test is not a generic test of full column rank. Spearman and Kendall describe rank associations and do not independently verify linear independence or exogeneity.

    For a normal model, residuals e = y − ŷ help reveal patterns, but they are not observed population errors. Even with independent errors, fitting constraints yield Cov(e | X) = σ²(I − H), where H is the projection matrix. Diagnostics therefore seek structure compatible with process dependence, rather than demanding literal independence of all fitted residuals.

    Constant variance belongs to the simple Gaussian specification reproduced here. It can be relaxed through a suitable dispersion structure or appropriate inference, but the word “generalised” does not automatically validate arbitrary heterogeneity. Normal errors concern exact normal-model inference; calculating least squares does not require a normal marginal histogram of Y. [5]

    Sample size and representativeness

    The initial concentration model uses 20 observations for six slopes and an intercept: with no missing values and full column rank, there are 13 residual degrees of freedom. This raises precision and stability concerns without proving invalidity. Normal-model inference can be exact with small samples under its conditions, whereas other GLMs rely more heavily on asymptotic approximations.

    Rules about cells with small expected counts concern particular chi-square approximations, not “observations within sampling units” in every regression. [7] Representativeness depends on sampling design and temporal and material coverage; increasing n does not automatically remove selection bias.

    A replication should record sample identifiers, dates and order, sampling point, calibration, test conditions, reagent batch, units and complete observations. Influence and leverage should accompany residual diagnostics. Without those materials, the proportionate conclusion is that independent validation remains incomplete.

    12. Prediction, uncertainty and operational use

    A point prediction should answer a specific question: are we estimating the process mean under given conditions, or the response for a new sample? A homoscedastic normal model with an intercept distinguishes:

    Mean confidence interval: x₀ᵀβ̂ ± t1−α/2, n−p s √[x₀ᵀ(XᵀX)⁻¹x₀]
    New-response prediction interval: x₀ᵀβ̂ ± t1−α/2, n−p s √[1 + x₀ᵀ(XᵀX)⁻¹x₀]

    x₀ contains the intercept and predictor values for the new case, p counts coefficients and s estimates residual standard deviation. The first interval quantifies uncertainty about the mean. The second adds new-observation variation —the extra 1— and is wider under the same conditions. Neither automatically incorporates uncertainty from selection, measurement or process changes. [9]

    Printed coefficients and R² values cannot reconstruct these intervals: residual variance and the design structure or estimator covariance are also needed. Nor can they recover the original residuals. This edition therefore calculates point examples and explicitly identifies why intervals cannot be reconstructed from the available documentation.

    Proposed validation should assess absolute and squared prediction error in response units, calibration and stability. Where observations are temporal, reserving later periods or using time-based partitions helps avoid treating information too similar to the training sample as genuinely new. Predictor selection and transformations belong within the relevant training set.

    Jar testing remains an experimental reference when source water or operation changes. Transfer to another plant requires review of equipment, reagents, calibration and predictor support, followed by validation on local observations. Statistical output supports a documented technical decision.

    13. Measurement, quantity and quality

    The relation between quantity and quality becomes clearer by distinguishing four levels: the material process; the instrument and measurement procedure; the scale used to express a reading; and the classification or action based on it. Water colour is not identical to an instrument’s numerical output, yet that output is not arbitrary: it emerges from a physical interaction governed by calibration and explicit conventions.

    Quantitative variation can change coagulation conditions, floc formation or treatment performance. Crossing an administrative acceptability threshold, however, does not by itself establish a phase transition or topological rupture. Such a claim would require defined states, relations and mechanisms that justify that mathematical description.

    An organised whole conditions the meaning of its components. A probability distribution structures possible values and their assigned probabilities: an isolated value does not determine its frequency or relative position. A related, though distinct, issue arises in regression: a partial temperature coefficient depends on which other variables are held constant. This helps interpret marginal and conditional associations without turning a philosophical analogy into statistical proof.

    The epistemological contribution lies in connecting object, measurement, model and practice. Knowledge becomes stronger when it identifies both its mediations and the conditions that could refute or limit its conclusions.

    14. Reproducible R appendix

    The first block evaluates the reported equations and the R² consistency calculation. Its results are reproducible arithmetic, without refitting. The if (FALSE) block is a disabled template: it requires actual observations and invents neither a data file nor a dataset. Marginal-range checks do not verify joint support.

    # Educational arithmetic: published equations, not a refit.
    predict_reported <- function(TURB, COL, PH, TEMP) {
      z <- list(TURB = TURB, COL = COL, PH = PH, TEMP = TEMP)
      valid <- vapply(z, function(v) is.numeric(v) &&
        length(v) == 1L && is.finite(v), logical(1))
      if (!all(valid)) {
        stop("Supply four finite numeric scalars.")
      }
      marginal <- TURB >= 200 && TURB <= 1200 &&
        COL >= 50 && COL <= 250 &&
        PH >= 7.1 && PH <= 8.33 &&
        TEMP >= 24 && TEMP <= 28
      lime <- 59.374 + 0.01262*TURB + 0.07746*COL - 8.831*PH
      data.frame(
        sulfate_mg_L = -13.571 + 0.085*TURB + 1.592*TEMP,
        solution_percent = -1.597 + 0.445*PH,
        lime_recorded_units = lime,
        inside_marginal_ranges = marginal,
        negative_lime_prediction = lime < 0
      )
    }
    predict_reported(TURB = 500, COL = 100, PH = 8, TEMP = 26)
    # 70.321 mg/L; 1.963 percent; 2.782 lime recording units.
    # Being within marginal ranges does not establish joint support.
    
    # Reconstruct R-squared from the printed correlation matrix.
    r_yx <- c(0.978, -0.266)
    R_xx <- matrix(c(1, -0.337, -0.337, 1), nrow = 2)
    drop(crossprod(r_yx, solve(R_xx, r_yx)))
    # Approximately 0.9610452, conditional on the stated OLS setup.
    
    # TEMPLATE ONLY: disabled until real observations are supplied.
    if (FALSE) {
      # sulfate_data must contain these measured variables.
      full <- lm(D_SUL ~ TURB + COL + ALCA + PH + TEMP,
                 data = sulfate_data, na.action = na.fail)
      reduced <- update(full, . ~ TURB + TEMP)
      anova(reduced, full, test = "F")
      X <- model.matrix(full)
      c(rank = qr(X)$rank, columns = ncol(X))
      par(mfrow = c(2, 2))
      plot(reduced)
      new_case <- data.frame(TURB = 500, TEMP = 26)
      predict(reduced, new_case, interval = "confidence")
      predict(reduced, new_case, interval = "prediction")
      # This reduced specification is illustrative; do not interpret
      # these commands as reproducing the undocumented selection path.
    }
    

    Template plots and tests need interpretation alongside the design. A future replication should document selection and validation from the outset, preserve each response’s dataset and report uncertainty and influence. These commands do not imply that the historical observations have been analysed here.

    15. Conclusions and scope of this edition

    This case connects water measurements with experimentally selected responses through Gaussian models with identity links. Its educational value lies both in coefficient interpretation and in examining inferential conditions. Predicting a dose, experimentally selecting a dose and establishing drinking-water safety are related tasks with different evidence and decision criteria.

    This revision retains the three models, original figures and correlation matrix; corrects the lime pH coefficient; distinguishes the conditional mean from observed responses; rebuilds the assumptions discussion; and discloses the conditional R² inconsistency. New examples and proposed diagnostics are explicitly identified. Without the original observations, empirical adequacy cannot be certified and intervals or residuals cannot be recovered.

    Editorial note. Originally published 25 September 2021; expanded revision 2 November 2026. Author: JOSÉ MAURICIO GÓMEZ JULIÁN. The historical PDF appears under the name Isadore Nabi. TEMP/TEM notation is standardised, the Spanish mistranslation “lima” is corrected to “cal”, figures are renumbered and duplicated passages removed. The historical APHA reference cited by Cepeda and Cepeda is dated 1985, not 1995. The spline references do not establish historical priority for partial tests; the machine-translation paper is identified for documentary reasons rather than as a statistical foundation. Post-2021 sources belong to this revision.

    References and documentary sources

    1. Cepeda, Z. & Cepeda C., E. (2005). Application of Generalized Linear Models to Data Analysis in Drinking Water Treatment. Revista Colombiana de Estadística, 28(2), 233–242.https://distantreader.org/stacks/journals/estad/estad-28883.pdf
    2. R Core Team. Family Objects for Models. Official documentation: families, links and variance functions.https://search.r-project.org/R/refmans/stats/html/family.html
    3. R Core Team. Fitting Generalized Linear Models. Official documentation.https://search.r-project.org/R/refmans/stats/html/glm.html
    4. R Core Team. ANOVA for Linear Model Fits. Nested-model comparison.https://search.r-project.org/R/refmans/stats/html/anova.lm.html
    5. NIST/SEMATECH. e-Handbook of Statistical Methods, §4.4.4, “How can I tell if a model fits my data?”; see also “Regression Diagnostics”.https://www.itl.nist.gov/div898/handbook/pmd/section4/pmd44.htm
    6. World Health Organization (2026). Guidelines for drinking-water quality: fourth edition incorporating the first, second and third addenda. Companion: Hardness chemical fact sheet.https://www.who.int/publications/i/item/9789240121225
    7. NIST/SEMATECH. e-Handbook of Statistical Methods, §1.3.5.15, “Chi-Square Goodness-of-Fit Test”.https://www.itl.nist.gov/div898/handbook/eda/section3/eda35f.htm
    8. Li, M., Duan, N., Zhang, D., Li, C.-H. & Zhou, M. (2009). Collaborative Decoding: Partial Hypothesis Re-ranking Using Translation Consensus between Decoders. ACL-IJCNLP, 585–592. Documentary reference for the correction.https://aclanthology.org/P09-1066/
    9. R Core Team. Predict method for Linear Model Fits. Confidence and prediction intervals.https://search.r-project.org/R/refmans/stats/html/predict.lm.html
    10. Gómez Julián, J. M. (2021, published as Isadore Nabi). Un caso de estudio sobre las aplicaciones de los modelos de regresión lineal: análisis de tratamientos para potabilización del agua mediante modelos lineales generalizados, parte I. Historical essay.https://marxistphilosophyofscience.com/wp-content/uploads/2021/09/un-caso-de-estudio-sobre-las-aplicaciones-de-los-modelos-lineales-generalizados-isadore-nabi.pdf
    11. Abril Díaz, N. and colleagues. Espectrofotometría: espectros de absorción y cuantificación colorimétrica de biomoléculas. Universidad de Córdoba. Historical instrumental source.https://www.uco.es/dptos/bioquimica-biol-mol/pdfs/08_ESPECTROFOTOMETRIA.pdf
    12. Pérez de la Cruz, F. J. & Urrea Mallebrera, M. A. Abastecimiento de aguas. Coagulación y floculación. Universidad Politécnica de Cartagena. Historical source.https://ocw.bib.upct.es/pluginfile.php/6019/mod_resource/content/1/Tema_06_COAGULACION_Y_FLOCULACION.pdf
    13. Bermúdez Cabrera, X., Fleites Ramírez, M. & Contreras Moya, A. M. (2009). Estudio del proceso de coagulación-floculación de aguas residuales de la empresa textil “Desembarco del Granma” a escala de laboratorio. Tecnología Química, 29(3), 64–73. Process context.https://www.redalyc.org/pdf/4455/445543760009.pdf
    14. Domènech, X. & Peral, J. (2006). Química ambiental de sistemas terrestres. Reverté. Historical bibliographic reference.
    15. American Public Health Association (1985). Standard Methods for the Examination of Water and Wastewater. Edition cited in the 2005 source.
    16. World Health Organization (2009). Tratamiento de emergencia del agua potable en el lugar de consumo. Historical source on treatment stages.http://bvsper.paho.org/share/ETRAS/AyS/texcom/desastres/opsguia5.pdf
    17. Gómez Julián, J. M. (2021, as Isadore Nabi). Modelos lineales generalizados. Background essay.https://marxistphilosophyofscience.com/wp-content/uploads/2021/08/modelos-lineales-generalizados-isadore-nabi.pdf
    18. Gómez Julián, J. M. (2021, as Isadore Nabi). Supuestos del modelo clásico de regresión lineal y de los modelos lineales generalizados. Historical background, subject to this edition’s corrections.https://marxianstatistics.com/2021/09/24/supuestos-del-modelo-clasico-de-regresion-lineal-y-de-los-modelos-lineales-generalizados/
    19. NIST. Regression Diagnostics. Multicollinearity and diagnostic tools.https://itl.nist.gov/div898/software/dataplot/refman1/auxillar/regrdiag.htm
  • GENERAL PRINCIPLES OF PROGRAMMING IN RSTUDIO: A STATISTICAL-MATHEMATICAL APPROACH

    GENERAL PRINCIPLES OF PROGRAMMING IN RSTUDIO: A STATISTICAL-MATHEMATICAL APPROACH

    Statistical notebooks · Mathematics and programming

    R Programming Fundamentals

    A Statistical and Mathematical Approach

    JOSÉ MAURICIO GÓMEZ JULIÁN

    Originally published: September 11, 2021
    Revised and expanded edition: November 2, 2026

    A program organizes transformations of representations. Understanding it requires connecting the form of the data, the meaning of the operations, and the conditions under which a result can become knowledge.

    This chapter integrates the original document’s contents into a self-contained, revised, and expanded exposition: from operators to data structures; from functions to recursion; from a rule on integers to the analysis of economic information. Code examples are provided as copyable text, with mathematical distinctions accompanying the practical work.

    Starting point

    1. Programming as a Way of Knowing

    Programming in R means representing data, defining operations on those data, and organizing their execution so that the result can be inspected and reproduced. A correct instruction must satisfy two requirements: express the intended calculation and preserve the meaning of the information being processed. The first requirement is computational; the second concerns the scientific problem, its concepts, and the way observations were produced.

    This chapter connects operators, vectors, lists, matrices, statistical variables, and data frames with functions, conditions, iteration, and recursion. Applications range from student grades to Collatz dynamics and the treatment of gross domestic product growth rates. The discussion addresses both how to write instructions and why those instructions represent particular mathematical operations, together with the limits of their interpretation.

    R, RStudio, and working files

    R is the language and computing environment. RStudio is an integrated development environment that helps users edit programs, execute instructions, inspect objects, and display plots. R can be used without RStudio; the functions introduced here belong to R or to explicitly identified packages. R supports functional programming and several systems of object-oriented programming. You do not need to master the latter before beginning to calculate and analyze data.

    An .R file stores instructions; a data file stores observations. The console evaluates expressions and displays results. The editor allows you to construct a program that can be executed again in the same order. The object pane helps inspect what has been created, but the program must preserve the evidence of how each object was obtained. A useful practice is therefore to begin with a fresh session and execute the code from the beginning.

    R / 01 An instruction, an object, and a result
    # Lines starting with # are comments.
    v1 <- 10
    v3 <- 150 / v1
    v3
    # [1] 15
    
    getwd()           # Current working directory.
    R.version.string  # R version used to run the program.

    The <- symbol binds a name to a value in an environment. After the first instruction, v1 retrieves the number 10; after the second, v3 retrieves the result 15. An identifier must be distinguished from a character string: v1 looks up an object, whereas "v1" represents text. R is case-sensitive: Data and data are different names.

    From the question to the result

    01Define

    Question, unit of analysis, and variables.

    02Represent

    Objects, types, dimensions, and missingness.

    03Calculate

    Functions, conditions, and algorithms.

    04Interpret

    Result, assumptions, and limitations.

    These stages inform and correct one another. An import anomaly may reveal a formatting problem; an inadmissible operation may expose confusion between categories and quantities; a numerically valid result may answer a different question from the one under investigation. Statistical programming requires keeping the relationship between representation, procedure, and interpretation visible.

    Documentation and references: [1] · [2]

    Syntax and meaning

    2. Operators, Comparisons, and Logic

    Assignment, equality, and separators

    R / 02 Assigning, comparing, and distinguishing a name from its contents
    x <- 12
    12 -> y
    z = 12
    identical(x, y)
    # [1] TRUE
    
    x == z  # Compares values; does not assign a new value.
    # [1] TRUE
    x <- 12; x  # Two expressions on the same line.
    # [1] 12
    
    hello_value <- 5
    greeting <- "hello"
    greeting
    # [1] "hello"

    Rightward assignment -> exists, although this chapter generally uses <- for a consistent reading direction. The = sign also permits assignment in some contexts; inside a call, it usually matches arguments to names. In mean(x = 1:3), x = identifies the function argument. The == operator compares values. The <= operator means “less than or equal to” and must not be confused with assignment.

    A semicolon ; separates expressions on the same line. In the console, evaluating a name may display its value through automatic printing; the semicolon is not a printing function. A comma , separates arguments in calls and index positions in multidimensional structures. In an R numeric constant, a period marks the decimal part: 1.65. A decimal comma in an imported file is specified through reading options and is a separate matter.

    Basic punctuation in the language
    ElementPurposeExample
    <-Assign a value to a namex <- 3
    == / !=Compare equality / inequalityx != 4
    ;Separate expressionsx <- 3; x
    ,Separate arguments or indicessum(1, 2); M[2, 3]
    ()Calls and groupingmean(x); (2 + 3) * 4
    {}Group instructionsThe body of a function or loop
    [] / [[]]Select subsets / extract componentsx[2]; L[[2]]

    Sequences and arithmetic operations

    R / 03 Finite sequences and arithmetic
    2:5
    # [1] 2 3 4 5
    5:2
    # [1] 5 4 3 2
    
    a <- 17
    b <- 5
    c(addition = a + b, subtraction = a - b, product = a * b,
      division = a / b, quotient = a %/% b, remainder = a %% b,
      power = b^2)
    # addition 22; subtraction 12; product 85; division 3.4;
    # quotient 3; remainder 2; power 25.
    
    typeof(8)
    # [1] "double"
    typeof(8L)
    # [1] "integer"

    For numeric arguments, a:b generates a sequence with increments of 1 or −1. 2:5 is a vector of four ordered values. It does not represent the closed real interval [2, 5], which contains infinitely many real numbers. A vector must also be distinguished from a set: it preserves positions and may contain repetitions. If the endpoints do not differ by an integer, the final endpoint may not appear in the sequence.

    a = b⌊a/b⌋ + (a mod b)
    For a nonzero divisor, and within the limitations of machine arithmetic, %/% and %% connect quotient and remainder. For 17 and 5: 17 = 5 × 3 + 2.

    The L suffix in 8L requests an integer constant; it does not perform an arithmetic operation. Powers are written with ^; R also accepts **. Parentheses make the intended order explicit. For example, -2^2 is interpreted as -(2^2), whereas (-2)^2 returns 4.

    Elementwise comparisons

    R / 04 Exact comparison and numerical approximation
    v <- c(2, 5.5, 6, 9)
    t <- c(8, 2.5, 14, 9)
    v > t
    # [1] FALSE TRUE FALSE FALSE
    v == t
    # [1] FALSE FALSE FALSE TRUE
    v != t
    # [1] TRUE TRUE TRUE FALSE
    
    c(0.1 + 0.2 == 0.3,
      isTRUE(all.equal(0.1 + 0.2, 0.3)))
    # [1] FALSE TRUE

    The operators <, >, <=, >=, ==, and != return logical values. For compatible vectors, comparison takes place by position. Use identical() for complete object identity; all.equal() may be more suitable for comparing numerical quantities within a tolerance. The decimal example illustrates a limitation of binary floating-point representation, not a contradiction in arithmetic.

    Conjunction, disjunction, negation, and membership

    Truth table for known logical values
    pqp & qp | q!p
    FALSEFALSEFALSEFALSETRUE
    FALSETRUEFALSETRUETRUE
    TRUEFALSEFALSETRUEFALSE
    TRUETRUETRUETRUEFALSE
    R / 05 Logical filters and membership tests
    u <- c(TRUE, FALSE, TRUE, FALSE)
    w <- c(TRUE, TRUE, FALSE, FALSE)
    u & w
    # [1] TRUE FALSE FALSE FALSE
    u | w
    # [1] TRUE TRUE TRUE FALSE
    !u
    # [1] FALSE TRUE FALSE TRUE
    c(3, 8, 3) %in% c(1, 3, 5)
    # [1] TRUE FALSE TRUE
    
    x <- c(2, 5, 8, NA_real_)
    x[!is.na(x) & x > 3 & x < 8]
    # [1] 5
    any(u)
    # [1] TRUE
    all(u)
    # [1] FALSE

    Conjunction & requires both conditions to hold. Disjunction | is inclusive: it is also true when both conditions are true. Negation ! reverses known logical values. Mathematically, it is an involution because applying it twice recovers the initial value; describing it as an isomorphism requires specifying the structure being preserved. %in% checks whether each element of its left argument appears in its right argument.

    R / 06 Short-circuit evaluation and scalar conditions
    divide_if_valid <- function(x, y) {
      if (length(y) == 1L && is.numeric(y) &&
          !is.na(y) && is.finite(y) && y != 0) {
        x / y
      } else {
        stop("The divisor must be a finite, scalar, nonzero number.")
      }
    }
    divide_if_valid(10, 2)
    # [1] 5

    The operators && and || evaluate from left to right and stop once the result is determined. In the example, the function checks the length and type of y before evaluating value-based scalar conditions. These operators require length-one operands in current R versions. To summarize a logical vector, explicitly choose any() or all(), depending on the question.

    Documentation and references: [1] · [3] · [4] · [7]

    The elementary structure

    3. Vectors and Sequences

    A vector stores elements in ordered positions. Atomic vectors have a single basic storage type; lists can combine components of different types and sizes. Atomic types include logical, integer, double, complex, character, and raw. The word “numeric” may be used broadly to include integers and doubles, so inspect the type with typeof() when the distinction matters.

    A numeric vector of length n can represent an element of ℝn. This interpretation is useful for algebraic operations, but it does not characterize every R vector: a list or a vector of words requires other interpretations. A simple vector also has no row or column orientation by default; dimensions make that orientation explicit when a matrix is used.

    Constructing vectors, allocating space, and assigning positions

    R / 07 Concatenation and preallocation
    v1 <- c(3, 1, 5, 6, 7)
    v2 <- c(TRUE, FALSE, TRUE)
    v3 <- c("ONE", "Monday", "Team")
    integer_vector <- c(2L, 4L, 6L)
    complex_vector <- c(1 + 2i, 3 - 1i)
    
    a <- vector(mode = "numeric", length = 4)
    a
    # [1] 0 0 0 0
    a[1:4] <- 1
    a
    # [1] 1 1 1 1
    
    vector("character", 3)
    # [1] "" "" ""
    vector()
    # logical(0)

    c() combines values. vector() allocates a structure of a specified type and length and initializes its positions. By default, it creates an empty logical vector; filling with zeros applies to numeric mode. The assignment a[1:4] <- 1 changes positions in an existing object. In algorithms that produce many results, allocating space before iteration avoids repeatedly rebuilding the vector.

    Selecting positions, excluding them, and preserving names

    R / 08 Extracting subsets
    v1[2:3]
    # [1] 1 5
    v1[c(1, 5)]
    # [1] 3 7
    v1[-c(2, 4)]
    # [1] 3 5 7
    v1[v1 >= 5]
    # [1] 5 6 7
    
    ages <- c(Ana = 20, Luis = 24, Eva = 21)
    ages[c("Eva", "Ana")]
    # Eva Ana
    #  21  20

    Positive indices select positions; negative indices exclude them; logical indices select where a condition is true; names refer to identified elements. Positive and negative indices cannot be mixed in one selection, apart from zeros. Indexing starts at 1. Extraction can repeat and reorder elements, so it is not generally a subset operation in the strict set-theoretic sense, and still less a selection of “subgroups” in the algebraic sense.

    seq(), rep(), and sequence(): different ways to generate sequences

    R / 09 Sequences with controlled steps, repetitions, and lengths
    seq(from = 1, to = 10, by = 2)
    # [1] 1 3 5 7 9
    seq(from = 10, to = -8, by = -3)
    # [1] 10 7 4 1 -2 -5 -8
    seq(from = 0, to = 1, length.out = 5)
    # [1] 0.00 0.25 0.50 0.75 1.00
    
    rep(3, times = 7)
    # [1] 3 3 3 3 3 3 3
    rep(c("A", "B"), times = 2)
    # [1] "A" "B" "A" "B"
    rep(c("A", "B"), each = 2)
    # [1] "A" "A" "B" "B"
    
    sequence(c(1, 2, 3))
    # [1] 1 1 2 1 2 3
    sequence(c(1, 3))
    # [1] 1 1 2 3
    
    seq_len(0)
    # integer(0)
    1:0
    # [1] 1 0
    seq_along(v1)
    # [1] 1 2 3 4 5

    seq() supports noninteger increments or a prescribed number of positions. rep() distinguishes repeating a complete vector from repeating each element. In these examples, sequence() concatenates sequences beginning at 1 with the specified lengths. Its function name is lowercase. For loop indices, seq_len(n) and seq_along(x) avoid the problem created by 1:n when n is zero.

    Vectorization and recycling

    R / 10 Positionwise operations and repeated operands
    x <- c(1, 2, 3, 4)
    x * 2
    # [1] 2 4 6 8
    x + c(10, 20)
    # [1] 11 22 13 24
    
    # Avoid accidental recycling: check lengths where appropriate.
    y <- c(10, 20, 30, 40)
    stopifnot(length(x) == length(y))
    x + y
    # [1] 11 22 33 44

    Vectorization expresses an operation over positions without an explicit loop. When lengths differ, many operations recycle the shorter vector. R usually warns when the longer length is not a multiple of the shorter one, but exact recycling can occur without warning and still make no sense for the data. If an operation represents paired measurements, verify the correspondence between observations as well as their lengths.

    Summaries and locating results

    R / 11 Summary functions and vector manipulation
    base_vector <- seq(1, 9, by = 2)
    c(length_value = length(base_vector), addition = sum(base_vector),
      mean_value = mean(base_vector), product = prod(base_vector),
      minimum = min(base_vector), maximum = max(base_vector),
      variance = var(base_vector), standard_deviation = sd(base_vector))
    # length 5; sum 25; mean 5; product 945;
    # minimum 1; maximum 9; variance 10; standard deviation 3.162278.
    range(base_vector)
    # [1] 1 9
    diff(range(base_vector))
    # [1] 8
    cumsum(base_vector)
    # [1] 1 4 9 16 25
    
    vector02 <- c(10, 11, 12, 13, 14, 15, 2, 3, 4, 6, 5, 6,
                  6, 11, 11, 11, 11, 11, 11, 11, 11, 11, 11)
    sort(vector02, decreasing = FALSE)
    sort(vector02, decreasing = TRUE)
    order(vector02)       # Ordering positions, rather than the values.
    which.max(vector02)   # First position of the maximum: 6.
    which.min(vector02)   # First position of the minimum: 7.
    unique(vector02)      # Distinct values in order of first appearance.
    letters[1:10]
    LETTERS[1:10]

    range() returns the minimum and maximum; their difference is the range width. which.max() and which.min() return the first position of an extreme, whereas max() and min() return its value. unique() removes repetitions and does not calculate eigenvalues. Eigenvalues concern linear operators and square matrices through a different mathematical question. letters and LETTERS are built-in vectors of the 26 basic Latin letters in lowercase and uppercase; they do not themselves include the full alphabet of every language.

    x̄ = (1/n) ∑i=1n xi
    s2 = [1/(n − 1)] ∑i=1n (xi − x̄)2
    s = √s2
    The mean summarizes level. Variance accumulates squared deviations from the mean; var() uses the divisor n − 1. sd() returns its square root in the original units. Sample variance is undefined with fewer than two available values.

    The divisor n − 1 reflects the loss of one degree of freedom when the mean is estimated from the same sample. Under independent sampling with finite variance, this correction gives an unbiased estimator of population variance. To describe the dispersion of an entire finite population using its average squared deviation, the appropriate divisor may instead be n. The choice depends on the statistical object and should be explicit.

    Pseudorandom sampling and reproducibility

    R / 12 Seed, replacement, and generating distribution
    set.seed(20210911)
    sample_without_replacement <- sample(1:20, size = 5, replace = FALSE)
    set.seed(20210911)
    repeat_sample <- sample(1:20, size = 5, replace = FALSE)
    stopifnot(identical(sample_without_replacement, repeat_sample))
    
    set.seed(20210911)
    sample_with_replacement <- sample(1:3, size = 10, replace = TRUE)
    simulated_normal <- rnorm(100, mean = 0, sd = 1)

    sample() selects from a specified population; replace = TRUE permits repeated selection of the same source position. rnorm() generates values according to a normal distribution using a pseudorandom generator. A seed fixes a state of that generator: it does not make a sample representative or, on its own, guarantee identical results across every R version and configuration. For exact reproduction, also record the version and, where necessary, RNGkind().

    Documentation and references: [6] · [11] · [13]

    Unknown information

    4. Missing Values and Statistical Decisions

    A missing value indicates absent information at a position belonging to the data structure. NA abbreviates Not Available. Depending on the database design, a cell may be missing because of nonresponse, recording error, or structural absence; these causes have different meanings. Code identifies missing-value markers, but explaining why data are missing requires knowledge of the observation process.

    Distinguishing missingness from other special results
    ObjectBasic meaningCheck
    NAA missing-value indicator, with typed variants.is.na(x)
    NaNA numerical result that is not a number, such as 0/0.is.nan(x)
    NULLThe null object; may indicate the absence of a component.is.null(x)
    "NA"A two-letter string unless explicitly converted during import.is.character(x)
    InfFloating-point infinity; not a missing observation.is.infinite(x)
    R / 13 Detecting missingness and counting available observations
    vector03 <- c(10, 11, 12, 13, NA_real_, NA_real_)
    is.na(vector03)
    # [1] FALSE FALSE FALSE FALSE TRUE TRUE
    sum(vector03)
    # [1] NA
    sum(vector03, na.rm = TRUE)
    # [1] 46
    length(vector03)
    # [1] 6
    sum(!is.na(vector03))
    # [1] 4
    
    is.na(c(NA_real_, NaN, Inf))
    # [1] TRUE TRUE FALSE
    is.nan(c(NA_real_, NaN, Inf))
    # [1] FALSE TRUE FALSE

    In many operations, an unknown input produces an unknown result. This is not a question of adding objects with incompatible units: if an addend is unknown, the sum may also be unknown. is.na() returns the missingness mask; x == NA is not the correct detection procedure. A string such as "NA" remains text until explicitly translated into a missing-value marker.

    Excluding from a calculation, removing from an object, and replacing

    R / 14 Three interventions with different effects
    # 1. Exclude from the calculation: the original object is unchanged.
    observed_mean <- mean(vector03, na.rm = TRUE)
    observed_mean
    # [1] 11.5
    
    # 2. Create another vector without the missing positions.
    without_na <- vector03[!is.na(vector03)]
    without_na_alternative <- as.vector(na.omit(vector03))
    stopifnot(identical(without_na, without_na_alternative))
    
    # 3. Explicit replacement: demonstrates an operation, not an imputation recommendation.
    vector04 <- replace(vector03, which(is.na(vector03)), 0)
    mean(vector04)
    # [1] 7.666667
    
    fruit <- c("apple", "orange", "grape", "banana")
    replace(fruit, list = 2, values = "blueberry")
    # [1] "apple" "blueberry" "grape" "banana"

    The na.rm = TRUE option changes which inputs a function considers without rewriting the vector. The selection x[!is.na(x)] constructs another vector and reduces its length. na.omit() may add attributes recording omitted positions. replace() returns a modified object, which must be assigned to retain it. which() turns a logical condition into the positions where it is true; many replacements can also use a logical mask directly.

    Replacing missing values with zero changes both the mean and the meaning of the information: it turns “unknown” into “zero.” The example demonstrates this numerically. Statistical imputation requires justification of the missingness model and procedure; excluding cases can also introduce bias. Report how many values were used and consider whether missingness relates to the variable of interest.

    R / 15 A function that reports the effective number of observations
    all_missing <- c(NA_real_, NA_real_)
    sum(all_missing, na.rm = TRUE)
    # [1] 0
    mean(all_missing, na.rm = TRUE)
    # [1] NaN
    
    available_summary <- function(x) {
      if (!is.numeric(x)) stop("A numeric vector is required.")
      if (any(!is.na(x) & !is.finite(x))) {
        stop("Infinite values were found.")
      }
      observed <- x[!is.na(x)]
      n <- length(observed)
      c(n_total = length(x), n_observed = n,
        n_missing = sum(is.na(x)),
        mean_value = if (n > 0L) mean(observed) else NA_real_,
        median_value = if (n > 0L) median(observed) else NA_real_,
        variance = if (n > 1L) var(observed) else NA_real_,
        standard_deviation = if (n > 1L) sd(observed) else NA_real_,
        minimum = if (n > 0L) min(observed) else NA_real_,
        maximum = if (n > 0L) max(observed) else NA_real_)
    }
    available_summary(vector03)

    Logic with unknown information

    R / 16 Determinate and indeterminate results
    FALSE & NA
    # [1] FALSE
    TRUE | NA
    # [1] TRUE
    TRUE & NA
    # [1] NA
    FALSE | NA
    # [1] NA
    !NA
    # [1] NA

    A conjunction is already false if one term is false, whatever the unknown value of the other term. A disjunction is already true if one term is true. In the other two cases, the available information is insufficient. This extension explains why a table containing only TRUE and FALSE does not describe the full logical behavior of R.

    Documentation and references: [5]

    Heterogeneous information

    5. Coercion, Lists, and Components

    Implicit coercion and explicit conversion

    Coercion changes an object’s representation from one type to another. When combining ordinary atomic vectors, R seeks a common type; among the types used here, a useful hierarchy is logical → integer → double → complex → character. This hierarchy describes a combination rule; it does not prohibit explicit conversions in the opposite direction. Some conversions are possible, while others produce missing values or lose information.

    R / 17 Conversion, a common type, and information loss
    typeof(c(TRUE, 2L))
    # [1] "integer"
    typeof(c(2L, 3.5))
    # [1] "double"
    c(1, "two", TRUE)
    # [1] "1" "two" "TRUE"
    
    as.numeric(c("12", "3.5"))
    # [1] 12.0 3.5
    as.integer(3.9)
    # [1] 3
    
    # A failed conversion produces a warning and an NA.
    failed_conversion <- tryCatch(
      as.numeric("text"),
      warning = function(w) NA_real_
    )
    stopifnot(is.na(failed_conversion))

    Conversion to integer truncates the fractional part, which can alter a measurement. The text "12" has a numeric interpretation; "text" does not. A conversion warning should be investigated rather than hidden in a real analysis. Here it is caught only to allow the reader to execute the whole block and observe the result defined for that case.

    Lists preserve different components

    R / 18 Containing a component versus extracting its value
    record <- list(
      name = "Ana",
      grades = c(90, 55, 89, 68),
      active = TRUE,
      metadata = list(group = "A", date = as.Date("2021-09-11"))
    )
    record["grades"]       # A one-component list.
    record[["grades"]]     # The numeric vector stored in that component.
    record$grades          # Another way to extract it by name.
    record[["grades"]][2]
    # [1] 55
    record$metadata$group
    # [1] "A"
    length(record)
    # [1] 4
    str(record)

    A list organizes heterogeneous objects without forcing them into one atomic type. It can contain vectors, other lists, matrices, and model results. [ preserves a list of selected components; [[ extracts a component; $ makes extraction by a literal name convenient. For programmatic access using a name stored in a variable, prefer record[[column_name]].

    A named list can serve purposes similar to a dictionary, but its names may be duplicated and access follows R list semantics. Flattening it with unlist() may coerce values to a common type, removing the structural separation that preserved different components. It should therefore not be used as an automatic substitute for extracting a particular component.

    Documentation and references: [6]

    From positions to axes

    6. Matrices, Operations, and Arrays

    Creating a matrix and naming its axes

    R / 19 Dimensions and filling direction
    vm01 <- c(10, 7, 1, 6, 8, 3)
    matrix01 <- matrix(data = vm01, nrow = 2, ncol = 3, byrow = TRUE)
    colnames(matrix01) <- c("Col_1", "Col_2", "Col_3")
    rownames(matrix01) <- c("Row_1", "Row_2")
    matrix01
    #       Col_1 Col_2 Col_3
    # Row_1    10     7     1
    # Row_2     6     8     3
    
    matrix(vm01, nrow = 2, ncol = 3, byrow = FALSE)
    #      [,1] [,2] [,3]
    # [1,]   10    1    8
    # [2,]    7    6    3
    dim(matrix01)
    # [1] 2 3
    length(matrix01)
    # [1] 6

    A matrix has two axes: rows and columns. data supplies the elements, nrow the number of rows, and ncol the number of columns. byrow = TRUE distributes the sequence across rows; FALSE, the default, proceeds down columns. This option determines where the initial sequence is placed; it does not sort values from smallest to largest. Atomic matrices have one common element type; list matrices also exist.

    Combining rows and columns

    R / 20 Binding along compatible axes
    matrix03 <- matrix(c(10, 1, 8, 7, 6, 3), nrow = 2,
                       ncol = 3, byrow = TRUE)
    colnames(matrix03) <- colnames(matrix01)
    rownames(matrix03) <- c("New_1", "New_2")
    row_bound_matrix <- rbind(matrix03, matrix01)
    column_bound_matrix <- cbind(matrix01, matrix03)
    dim(row_bound_matrix)
    # [1] 4 3
    dim(column_bound_matrix)
    # [1] 2 6

    rbind() stacks rows and requires compatible columns; cbind() adds columns and requires compatible rows. When combining data, verify the identity and order of units as well as dimensions. Two matrices with the same number of rows may refer to different people, or to the same people in a different order.

    Inspecting values, constructing masks, and filtering

    R / 21 A condition and the extraction that uses it
    row_bound_matrix[2, 3]
    # [1] 3
    row_bound_matrix[, 3]
    # New_1 New_2 Row_1 Row_2
    #       8       3     1     3
    
    mask <- row_bound_matrix[, 3] > 2
    mask
    # [1] TRUE TRUE FALSE TRUE
    row_bound_matrix[mask, , drop = FALSE]
    row_bound_matrix[row_bound_matrix[, 3] > 2, , drop = FALSE]
    
    matrix01[1, , drop = FALSE]  # Preserves a one-row matrix.
    matrix01[1, ]               # Simplifies to a vector.

    The expression M[, 3] > 2 produces a mask indicating which positions satisfy the condition. The expression M[mask, ] uses that mask to extract rows. Distinguishing these operations clarifies what each line returns. An empty index before the comma keeps all rows; an empty index after it keeps all columns. drop = FALSE preserves two dimensions when extraction selects a single row or column.

    Axis totals, sorting, and transposition

    R / 22 MARGIN = 1 for rows and MARGIN = 2 for columns
    apply(X = row_bound_matrix, MARGIN = 2, FUN = sum)
    # Col_1 Col_2 Col_3
    #    33    22    15
    apply(X = row_bound_matrix, MARGIN = 1, FUN = sum)
    # New_1 New_2 Row_1 Row_2
    #      19      16    18    17
    
    stopifnot(
      isTRUE(all.equal(colSums(row_bound_matrix),
                       apply(row_bound_matrix, 2, sum))),
      isTRUE(all.equal(rowSums(row_bound_matrix),
                       apply(row_bound_matrix, 1, sum)))
    )
    apply(row_bound_matrix, 2, sort)
    apply(row_bound_matrix, 1, sort)
    t(row_bound_matrix)

    apply() receives an object, the axis or axes organizing the calculations, and the function to apply. For sums, rowSums() and colSums() express the intention directly. If the applied function returns several values, apply() may reorganize the result’s dimensions; for example, when sorting by row, it may place each result in a column. Inspect dim() to confirm the resulting structure.

    Sorting each column separately breaks the original relationships between variables in a row. If each row represents a person, this transformation can combine ages, heights, and measurements from different people. To sort observations while preserving rows, construct a single index with order() and apply it to every column. Transposition with t() exchanges axes; it does not sort values.

    Elementwise multiplication and matrix multiplication

    R / 23 Hadamard product, inner product, and matrix multiplication
    matrix01 * matrix03
    #       Col_1 Col_2 Col_3
    # Row_1   100     7     8
    # Row_2    42    48     9
    
    matrix04 <- t(matrix03)
    matrix01 %*% matrix04
    #       New_1 New_2
    # Row_1     115      115
    # Row_2      92       99
    
    u <- c(1, 2, 3)
    v <- c(4, 5, 6)
    u * v
    # [1] 4 10 18
    sum(u * v)
    # [1] 32
    drop(crossprod(u, v))
    # [1] 32
    (A ⊙ B)ij = aijbij
    (AB)ij = ∑k=1p aikbkj
    Elementwise multiplication requires compatible shapes. For matrix multiplication, A is m × p and B is p × n; the result is m × n. Each entry combines a row of A with a column of B.

    The symbol * denotes elementwise multiplication, also called the Hadamard product for matrices of the same size. %*% denotes matrix multiplication. For numeric vectors, the Euclidean inner product sums products of corresponding positions. Distinguishing these three operations avoids assigning the ambiguous label “vector multiplication” to a single expression.

    Arrays and their relationship to tensors

    R / 24 An array with three axes
    A <- array(1:12, dim = c(2, 3, 2),
               dimnames = list(row = c("f1", "f2"),
                               column = c("c1", "c2", "c3"),
                               slice = c("t1", "t2")))
    A[, , "t1"]
    dim(A)
    # [1] 2 3 2
    length(A)
    # [1] 12

    In R, an array organizes a vector through a dimension attribute. It can have one, two, or more axes. A matrix is the two-axis case. Creating an array does not amount to performing a tensor product: it constructs a computational representation. A numeric array can store tensor components relative to chosen bases, but an abstract tensor and the container holding its components are not conceptually identical.

    Documentation and references: [8] · [9]

    What is measured and how it is encoded

    7. Statistical Variables and Factors

    Statistical classification describes a variable’s nature and the operations that make sense on its values. Computational classification describes storage and behavior in the language. The two are connected through encoding decisions; neither determines the other on its own. A number used as a person’s identifier does not become a quantity suitable for averaging merely because it is stored numerically.

    Variable nature and encoding structure
    Statistical natureExamplePossible representation in RInterpretive criterion
    Discrete numericNumber of visitsinteger or doubleSeparated values, often counts.
    Continuous numericHeightdoubleA magnitude modeled on a continuum; measurement and storage have finite precision.
    Nominal categoricalType of clothingfactor or characterCategories without intrinsic order.
    Ordinal categoricalRating: poor, fair, goodordered / factorMeaningful order; distances between categories need not be equal.
    R / 25 Factor levels, order, and internal codes
    Clothing <- factor(c("Shirt", "Shoes", "Coat", "Socks"))
    levels(Clothing)
    # [1] "Coat" "Shirt" "Shoes" "Socks"
    
    Response <- factor(c("Good", "Fair", "Fair", "Poor"),
                        levels = c("Poor", "Fair", "Good"),
                        ordered = TRUE)
    Response
    # [1] Good Fair Fair Poor
    # Levels: Poor < Fair < Good
    Response > "Fair"
    # [1] TRUE FALSE FALSE FALSE
    
    encoded_measurement <- factor(c("10", "20", "10"))
    as.numeric(encoded_measurement)
    # [1] 1 2 1
    as.numeric(as.character(encoded_measurement))
    # [1] 10 20 10

    A factor represents categories through integer codes and labels called levels. Alphabetical order in a nominal factor’s levels does not create a substantive hierarchy. In an ordered factor, order is deliberately specified using levels and ordered = TRUE. Even then, the distance between “Poor” and “Fair” need not equal that between “Fair” and “Good.”

    If the labels represent numbers, first recover them as text and then convert them. If they represent genuine categories, converting their internal codes to numbers does not justify averaging the categories. Decisions about measurement scales precede function calls. Models that accept factors may construct contrasts from their levels; these contrasts also depend on ordering and the chosen configuration.

    Documentation and references: [11]

    Tables with statistical structure

    8. Data Frames: Observations and Variables

    A data.frame brings together variables with the same number of rows. In the usual arrangement of individual-level data, each row corresponds to an observational unit and each column to a variable. A cell contains that variable’s observed value for that unit. In longitudinal data, a row may represent a combination of unit and time, so specify what identifies a record before analyzing it.

    R / 26 Constructing columns inside or outside the call
    Data_01 <- data.frame(
      Height = c(1.65, 1.70, 1.89),
      Hair_length = c("Short", "Medium", "Long"),
      stringsAsFactors = FALSE
    )
    Height <- c(1.65, 1.70, 1.89)
    Hair_length <- c("Short", "Medium", "Long")
    Data_02 <- data.frame(Height, Hair_length,
                           stringsAsFactors = FALSE)
    stopifnot(identical(Data_01, Data_02))
    
    Data_03 <- data.frame(Height = Height, Hair = Hair_length,
                           stringsAsFactors = FALSE)
    Data_03
    #   Height  Hair
    # 1   1.65 Short
    # 2   1.70 Medium
    # 3   1.89 Long

    The first two constructions produce the same table through different ways of organizing the program. The third provides column names explicitly. Since R 4.0.0, data.frame() uses stringsAsFactors = FALSE by default; it is written here to make the decision visible. When a variable is categorical, deliberately construct a factor with appropriate levels.

    Related structures with different properties
    FeatureAtomic matrixData frame
    OrganizationTwo axes; one common atomic type.Columns that may have different types.
    Frequent useAlgebraic computation and homogeneous arrays.Tables of observations and variables.
    Inspectiondim(), typeof(), str().str(), names(), and column classes.
    SelectionM[i, j].d[i, j], d[[j]], d$variable.
    Conversionas.data.frame(M).as.matrix(d), checking coercion.

    A data frame is a list with class data.frame and shared-row constraints; its columns can include logical and numeric types, text, factors, dates, and more complex structures supported by its methods. There is no general guarantee that converting a matrix into a data frame makes every filter or calculation faster. The appropriate structure depends on the information, the operations, and actual performance measurements.

    Extracting columns, rows, and subsets

    R / 27 Selecting while preserving meaning and result shape
    matrix_df <- as.data.frame(matrix01)
    column1 <- matrix_df$Col_1
    stopifnot(identical(column1, matrix_df[["Col_1"]]))
    matrix_df[, 1]                 # A vector.
    matrix_df[1]                   # A one-column data frame.
    matrix_df[, 1, drop = FALSE]    # Preserves the tabular structure.
    matrix_df[2, , drop = FALSE]
    matrix_df[, c("Col_1", "Col_2"), drop = FALSE]
    matrix_df[, c(1, 2), drop = FALSE]
    
    Data_01[Data_01$Height >= 1.70, , drop = FALSE]
    names(Data_03) <- c("Height_m", "Hair")

    Selecting one column may return a vector or a table depending on the form of indexing. The distinction matters when writing functions expecting a particular structure. Col_1 and col_1 are different names. When a name is stored in a variable, [[ extracts that exact column and helps distinguish the object’s name from its textual contents.

    Inspection before analysis

    R / 28 Structure, classes, and missing values by column
    head(Data_01)
    tail(Data_01)
    str(Data_01)
    summary(Data_01)
    dim(Data_01)
    nrow(Data_01)
    ncol(Data_01)
    vapply(Data_01, typeof, character(1))
    colSums(is.na(Data_01))

    head() shows the first six rows by default and tail() the last six; when fewer exist, they show those available. str() describes structure and types. summary() produces summaries depending on each column’s class. dim() returns rows and columns; nrow() and ncol() inspect them separately. View() opens an interactive viewer when the environment supports it, but reproducible checks must be preserved as instructions.

    Documentation and references: [10]

    From file to object

    9. Importing, Exporting, and Preserving Data

    Importing means interpreting a file’s bytes and constructing R objects. Exporting means writing a representation of those objects in another format. The extension provides a clue, but the procedure must match the actual contents, separators, header, decimal symbol, and missing-value markers. A .txt file may have a header or lack one; a CSV may use commas or, under regional conventions, semicolons. None of these properties is determined by the filename alone.

    Paths, directories, and projects

    R / 29 Portable paths and existence checks
    # A temporary directory makes the example independent of existing files.
    example_directory <- tempfile("r_chapter_")
    dir.create(example_directory)
    csv_path <- file.path(example_directory, "data.csv")
    file.exists(csv_path)
    # [1] FALSE: the file has not been written yet.
    
    # Example paths stored as text; the files need not exist.
    relative_path <- file.path("data", "Data01.xlsx")
    windows_path <- "C:/Users/User/Downloads/Data01.xlsx"

    An absolute path identifies a file from the filesystem root. A relative path is interpreted from the working directory. A relative path can be sufficient when the file is in the appropriate location; writing a full path is not always necessary. file.path() constructs paths with suitable separators. Forward slashes / can be used on Windows; a literal backslash inside a string must be escaped. Hierarchical folders provide a useful visual analogy, but are not themselves inheritance or encapsulation in object-oriented programming.

    Text, CSV, and regional conventions

    R / 30 Verified writing and reading with base R
    write.csv(Data_01, file = csv_path, row.names = FALSE,
              na = "", fileEncoding = "UTF-8")
    reimported <- read.csv(csv_path, header = TRUE, sep = ",", dec = ".",
                            na.strings = c("", "NA"),
                            stringsAsFactors = FALSE,
                            fileEncoding = "UTF-8")
    stopifnot(isTRUE(all.equal(Data_01, reimported)))
    
    text_path <- file.path(example_directory, "data.txt")
    write.table(Data_01, file = text_path, sep = "\t", dec = ".",
                row.names = FALSE, col.names = TRUE, quote = TRUE,
                na = "", fileEncoding = "UTF-8")
    from_text <- read.table(text_path, header = TRUE, sep = "\t", dec = ".",
                            na.strings = c("", "NA"),
                            stringsAsFactors = FALSE,
                            fileEncoding = "UTF-8")
    
    regional_path <- file.path(example_directory, "regional_data.csv")
    write.csv2(Data_01, file = regional_path, row.names = FALSE)
    from_regional <- read.csv2(regional_path, stringsAsFactors = FALSE)
    stopifnot(isTRUE(all.equal(Data_01, from_text)),
              isTRUE(all.equal(Data_01, from_regional)))
    Declare the layout instead of inferring it from the extension
    OptionQuestion it answers
    header / col.namesDoes the first row contain column names when reading / will those names be written?
    sepWhich character separates fields?
    decWhich symbol marks the decimal part?
    na.strings / naWhich strings will be read as missing / how will missing values be written?
    skipHow many initial lines will be skipped before interpreting the data?
    row.namesAre additional row identifiers interpreted or written?
    fileEncodingWhich character encoding is used?

    read.csv() defaults to a comma separator and decimal point; read.csv2() uses a semicolon separator and decimal comma. The option must match the file. For text without a header, use header = FALSE and assign names afterward. On export, row.names = FALSE avoids adding an index column that often reappears as an unwanted variable on reimport.

    Excel: sheets, formats, and preliminary rows

    R / 31 One sheet, multiple sheets, and separate files
    # Install these packages once if needed:
    # install.packages(c("readxl", "writexl"))
    
    if (requireNamespace("readxl", quietly = TRUE) &&
        requireNamespace("writexl", quietly = TRUE)) {
      excel_path <- file.path(example_directory, "All_Data.xlsx")
      writexl::write_xlsx(
        list(Datos01 = Data_01, Datos02 = Data_03), path = excel_path
      )
      IMP_01 <- readxl::read_excel(excel_path, sheet = "Data01")
      IMP_02 <- readxl::read_excel(excel_path, sheet = "Data02")
      IMP_first <- readxl::read_excel(excel_path)
    
      # One table per file:
      writexl::write_xlsx(IMP_01,
                         path = file.path(example_directory, "Export1.xlsx"))
      writexl::write_xlsx(IMP_02,
                         path = file.path(example_directory, "Export2.xlsx"))
      stopifnot(nrow(IMP_01) == nrow(Data_01))
    } else {
      message("The Excel example requires the readxl and writexl packages.")
    }

    read_excel() accepts .xls and .xlsx and attempts to detect the format. read_xls() and read_xlsx() specify it directly. The file must exist at the declared path and its actual format must match the reading procedure. Omitting sheet uses the first sheet even when the workbook contains others. readxl returns a tibble, a tabular class inheriting from data.frame, with printing and indexing differences from a base data frame.

    skip = 3 is appropriate when the first three rows contain preliminary material and the header follows. Determine that number by inspecting the particular file. When an explicit range is specified, its rules take precedence over other sheet-geometry options. To export several sheets with writexl, provide a named list, one component per sheet. This approach avoids requiring Java, although other valid alternatives exist for more complex Excel editing and formatting tasks.

    From an import wizard to a reproducible procedure
    Operation in a graphical interfaceInstruction that must be recorded
    Select a filePath and verification with file.exists().
    Select a sheetThe sheet argument or a declared range.
    Skip preliminary rowsskip, based on inspection of the document.
    Declare headers and missingnesscol_names, header, na, or na.strings.
    Confirm the importstr(), dim(), names, types, and missing-value counts.

    RStudio’s import wizards can help configure a reading operation. To preserve the procedure, copy the generated code into the working script and inspect its arguments. The pane does not replace a record of the operation. An RDS file provides another option: it preserves an R object with its classes and attributes, whereas CSV preserves a textual table and may lose those properties.

    R / 32 Preserving an object with its attributes
    rds_path <- file.path(example_directory, "data.rds")
    saveRDS(Data_01, file = rds_path)
    restored_data <- readRDS(rds_path)
    stopifnot(identical(Data_01, restored_data))

    Documentation and references: [18] · [19]

    Connections with mathematics

    10. Functions, Composition, and Functionals

    A function and its call

    An R function receives arguments, evaluates instructions in an environment, and returns a value. It may also produce effects such as displaying text or writing a file. The returned result and those effects are distinguishable. In mathematics, a function assigns each element of a domain to exactly one element of a codomain; a particular computational function may fail, fail to terminate, or depend on external state. Identifying it with a mathematical mapping therefore requires specifying its domain, conditions, and effects.

    R / 33 Definition, formal argument, and evaluation
    square <- function(x) {
      x^2
    }
    square(3)
    # [1] 9
    square(c(1, 2, 3))
    # [1] 1 4 9
    is.function(square)
    # [1] TRUE
    formals(square)
    body(square)

    In function(x), x is a formal argument. In square(3), the supplied value is 3. The function is vectorized because the ^ operation in its body accepts vectors. A user-defined function may be short even if built-in functions perform related tasks; defining one helps express an intention, validate inputs, and automate a repeatable procedure.

    Composing calls is different from passing functions

    R / 34 Results as arguments and functions as arguments
    sum(c(1:50))
    # [1] 1275
    
    f <- function(x) 2 * x
    g <- function(x) x + 1
    f(g(3))
    # [1] 8
    
    apply_to <- function(x, fun) {
      fun(x)
    }
    apply_to(1:5, mean)
    # [1] 3
    apply_to(1:5, sum)
    # [1] 15

    In sum(c(1:50)), a vector is constructed and its elements are then summed. sum() receives the resulting vector, not the function c as an object. This structure illustrates nested calls and composition of operations. By contrast, apply_to(1:5, mean) supplies the function mean itself as an argument. The second structure is an example of a higher-order function.

    (f ∘ g)(x) = f(g(x))
    ∑i=1n i = n(n + 1)/2
    The first identity evaluates g and then f, assuming compatible domains. In the second, pairing the first and last summands gives n + 1; the argument yields n(n + 1)/2 and verifies 1275 when n = 50.
    Classification by properties rather than code length
    ConceptDistinguishing propertyExample
    Nested callsOne call appears inside another.sum(c(1, 2, 3))
    Inner functionIts definition occurs inside another function.A function created by make_offset().
    Higher-order functionReceives a function or returns a function.apply_to(x, mean).
    Functional in R programmingReceives a function and produces results by applying it.lapply(list_object, mean).
    Mathematical functionalA scalar-valued mapping on a suitable function space or other appropriate objects.A function is mapped to its definite integral.
    Control-flow constructDetermines which instructions execute and when.if, for, while.

    Mathematical functionals and numerical evaluation

    𝓘(f) = ∫01 f(t) dt
    𝓘(t ↦ t2) = 1/3
    The argument is a whole function; the result is a scalar. On a suitable class, such as continuous real-valued functions on [0, 1], this mapping is well defined. The integration variable t ranges over the interval and is not a free parameter of the result.
    R / 35 An integral and two functionals applied to data
    integrand <- function(t) t^2
    integral_result <- integrate(integrand, lower = 0, upper = 1)
    integral_result$value
    # [1] 0.3333333
    integral_result$abs.error
    stopifnot(abs(integral_result$value - 1/3) < 1e-12)
    
    groups <- list(A = c(1, 2, 3), B = c(4, 5, 6))
    lapply(groups, mean)
    vapply(groups, mean, numeric(1))
    # A B
    # 2 5

    The mathematical integral and its approximation algorithm are different objects: integrate() returns a list containing an approximate value, an estimated absolute error, and other components. lapply() applies a function to each component and preserves a list of results. vapply() adds an expected output type and shape; here each group must produce a numeric scalar. apply(), already used with matrices, also receives a function through FUN.

    The uses of “functional” in programming and functional analysis are related but not universally identical. The computational terminology allows vector-valued outputs and data objects that require further specification to be interpreted within a mathematical function space. A precise connection identifies domain, operation, and codomain in each case, rather than inferring equivalence merely because one instruction contains another.

    Operators and primitive functions

    Many operators can be called as functions, for example `+`(2, 3). This does not make every built-in function an operator or every operator a low-level primitive function. is.primitive() inspects that technical property. An operator can be unary, binary, or user-defined, and may act on objects other than numbers. Its meaning depends on the operation and, when dispatch applies, on the classes of its arguments.

    R / 36 Being primitive is a technical property, not a measure of simplicity
    `+`(2, 3)
    # [1] 5
    is.primitive(sum)
    # [1] TRUE
    is.primitive(mean)
    # [1] FALSE

    Documentation and references: [14] · [15]

    Organizing execution

    11. Conditions, Loops, and Student Grades

    Scalar decisions and vectorized ifelse()

    R / 37 An explicit set of rules
    grades <- c(90, 55, 89, 68)
    average_grade <- mean(grades)
    average_grade
    # [1] 75.5
    
    if (average_grade >= 70) {
      cat("Passed the course\n")
    } else if (average_grade >= 60) {
      cat("Resit examination\n")
    } else {
      cat("Failed the course\n")
    }
    
    demo_averages <- c(75.5, 66.75, 47.25, NA_real_)
    ifelse(is.na(demo_averages), "No information",
           ifelse(demo_averages >= 70, "Passed",
                  ifelse(demo_averages >= 60, "Resit", "Failed")))
    # [1] "Passed" "Resit" "Failed" "No information"

    This illustration assumes a grading scheme in which 70 or above is a pass, 60 to below 70 allows a resit examination, and below 60 is a fail. Adapt these thresholds to the applicable regulations. Once the first condition has excluded values of 70 or above, the second need only ask whether 60 has been reached. Write a closing brace and else together as } else { to avoid parsing problems when running the code.

    if requires a nonmissing condition of length one. ifelse() selects elements over a vector of conditions and returns an object with its shape. It is not a universal replacement for if: output types and attributes require inspection, and evaluated branches may calculate values for positions that are not ultimately selected. Scalar logic and side effects normally call for if.

    What cat(), print(), and return() mean

    Displaying and returning are different operations
    InstructionPurposeRelevant result
    cat(..., sep = " ", file = "")Concatenate and write a textual representation.Normally returns NULL invisibly; produces output.
    print(x)Display an object through the method appropriate to its class.Usually returns the object invisibly.
    return(x)End a function’s evaluation and return a value.The caller can use the returned value.
    Last expression in the bodyImplicit return when no earlier return is used.Its value becomes the function result.

    In its usual uses, cat() accepts atomic arguments and names; a nonempty list needs a suitable representation or a function such as print(). The options sep, fill, labels, file, and append control separators, line filling, and destination. Writing a message does not automatically construct a reusable result. An analysis function commonly returns a table or list and leaves presentation to another instruction.

    Iterating over known values

    R / 38 A loop, its vectorized counterpart, and an accumulator
    for (x in seq_len(5)) {
      print(round(sqrt(x), digits = 2))
    }
    # [1] 1
    # [1] 1.41
    # [1] 1.73
    # [1] 2
    # [1] 2.24
    
    round(sqrt(seq_len(5)), digits = 2)
    # [1] 1.00 1.41 1.73 2.00 2.24
    
    Accumulator <- 0
    for (i in seq_len(5)) {
      if (i %% 2 == 0) {
        Accumulator <- Accumulator + i
      }
    }
    Accumulator
    # [1] 6

    A for loop assigns successive elements of a collection to the iteration variable and executes its body. The first example computes square roots of independent values: it is not recursion and does not use the previous root as the next input. Rounding to two decimal places controls numerical presentation; it does not achieve “infinitesimal precision.” The sum accumulator starts at zero because zero is the additive identity, not because the first even number is unknown.

    Three students, four assessments, and a tabular result

    R / 39 One row per student and one column per assessment
    grades1 <- c(90, 55, 89, 68)
    grades2 <- c(70, 65, 65, 67)
    grades3 <- c(40, 59, 70, 20)
    grade_matrix <- rbind(Ana = grades1, Bruno = grades2, Carla = grades3)
    colnames(grade_matrix) <- c("Exam_1", "Exam_2", "Exam_3", "Project")
    grade_averages <- rowMeans(grade_matrix)
    grade_averages
    #   Ana Bruno Carla
    # 75.50 66.75 47.25
    
    status <- character(length(grade_averages))
    for (j in seq_along(grade_averages)) {
      current_average <- grade_averages[j]
      if (is.na(current_average)) {
        status[j] <- "No information"
      } else if (current_average >= 70) {
        status[j] <- "Passed"
      } else if (current_average >= 60) {
        status[j] <- "Resit"
      } else {
        status[j] <- "Failed"
      }
    }
    course_results <- data.frame(
      student = names(grade_averages), average = unname(grade_averages), status,
      stringsAsFactors = FALSE
    )
    course_results

    Each row identifies a student, so averages are calculated by row. If the interpretation changed so that each row represented a subject, the meaning of averaging that row would need review. Displaying three vectors separated by semicolons does not construct a matrix; rbind() does. Equal weights are an assumption: when assessments have different weights, use a weighted mean with coherent weights and a positive total weight.

    x̄w = [∑j=1k wjxj] / [∑j=1k wj]
    Each grade x_j is multiplied by its weight w_j. Equal positive weights recover the simple mean. Weights represent the agreed contribution of each assessment.
    R / 40 A differently weighted project changes the average
    weighted.mean(grades1, w = c(0.20, 0.20, 0.20, 0.40))
    # [1] 74

    while, repeat, break, and next

    R / 41 Choose the structure according to the repetition criterion
    # while: check before each execution.
    counter <- 0L
    while (counter < 3L) {
      counter <- counter + 1L
    }
    stopifnot(counter == 3L)
    
    # repeat: an explicit exit using break.
    counter <- 0L
    repeat {
      counter <- counter + 1L
      if (counter >= 3L) break
    }
    
    # next: skip the rest of the current iteration.
    even_values <- integer(0)
    for (i in seq_len(6)) {
      if (i %% 2 != 0) next
      even_values <- c(even_values, i)
    }
    even_values
    # [1] 2 4 6

    while may never execute its body if its initial condition is false. repeat needs an explicit exit or may continue indefinitely. break exits the innermost loop; next advances to its next iteration. These are language control-flow constructs, not object classes. Clarity improves when the chosen structure expresses the actual repetition criterion and unnecessary nested conditions are reduced.

    Documentation and references: [4] · [12]

    Automating without hiding assumptions

    12. Custom Functions and Validation

    Four decisions when defining a function

    Choose a name expressing the task; declare arguments and defaults; build the calculation and its checks; and return an object with a useful structure. Braces delimit the body. return() may appear before the last line to end evaluation early; it is neither a compulsory typographical closing marker nor a printing instruction. Describe accepted inputs and the conditions that produce errors.

    R / 42 A complete function summing even numbers from 1 through n
    validate_integer <- function(x, minimum = 0, name = "x", maximum = 1e6) {
      if (length(x) != 1L || !is.numeric(x) || is.na(x) ||
          !is.finite(x) || x != floor(x) || x < minimum || x > maximum) {
        stop(name, " must be a scalar integer between ", minimum, " and ", maximum, ".")
      }
      invisible(TRUE)
    }
    
    sum_even <- function(n) {
      validate_integer(n, minimum = 0, name = "n")
      accumulator <- 0
      for (i in seq_len(n)) {
        if (i %% 2 == 0) accumulator <- accumulator + i
      }
      accumulator
    }
    sum_even(50)
    # [1] 650
    sum_even(0)
    # [1] 0

    The one-million limit keeps this iterative exercise manageable; it is not a mathematical boundary of the problem. Negative, fractional, infinite, missing, and incorrectly sized inputs are rejected. seq_len(0) creates an empty traversal and correctly preserves a zero sum. The function returns a number that can be used in further calculations.

    m = ⌊n/2⌋
    2 + 4 + ⋯ + 2m = 2∑j=1mj = m(m + 1)
    There are m positive even integers through n. Each is twice an integer from 1 to m. Applying the sum formula gives m(m + 1), independently checking the loop result.
    R / 43 Comparing methods and returning reusable classifications
    sum_even_formula <- function(n) {
      validate_integer(n, minimum = 0, name = "n")
      m <- floor(n / 2)
      m * (m + 1)
    }
    stopifnot(sum_even(50) == sum_even_formula(50),
              sum_even(0) == sum_even_formula(0),
              sum_even(5) == sum_even_formula(5))
    
    parity <- function(x) {
      if (!is.numeric(x) || anyNA(x) || any(!is.finite(x)) ||
          any(x != floor(x)) || any(abs(x) > 2^53 - 1)) {
        stop("Finite integers exactly representable as double are required.")
      }
      ifelse(x %% 2 == 0, "Even", "Odd")
    }
    parity(1:6)
    # [1] "Odd" "Even" "Odd" "Even" "Odd" "Even"
    parity(50)
    # [1] "Even"

    The parity function accepts a vector or a single value. Traversing 1:n answers “What is the parity of each integer in this traversal?”; evaluating only n answers “What is the parity of this value?” The vectorized function preserves the distinction through its input. The numerical bound avoids claiming exact parity for values whose representation no longer guarantees all consecutive integers.

    Documentation and references: [1] · [16]

    A mathematical laboratory

    13. Collatz: Orbits, Iteration, and Recursion

    The Collatz problem allows us to study an elementary rule whose evolution can produce long trajectories. For positive integers, the transformation divides an even value by two and replaces an odd value with three times that value plus one. The assertion of eventual arrival at 1 concerns every positive seed. Traversing particular examples verifies those examples and explores patterns; it does not turn exploration into a universal proof.

    T(n) = n/2, if n is even3n + 1, if n is odd
    n0 = a,   nk+1 = T(nk)
    The seed a is a positive integer. Each application of T produces one transition. The observed trajectory is the sequence n_0, n_1, … . The standard rule sends 1 to 4; our exploration algorithms stop upon reaching 1.

    One transition and a trajectory algorithm

    R / 44 Local state, preallocation, and explicit stopping
    exact_integer_limit <- 2^53 - 1
    
    validate_collatz <- function(n) {
      if (length(n) != 1L || !is.numeric(n) || is.na(n) ||
          !is.finite(n) || n < 1 || n != floor(n) ||
          n > exact_integer_limit) {
        stop("The seed must be an exactly representable positive integer.")
      }
      invisible(TRUE)
    }
    
    collatz_step <- function(n) {
      validate_collatz(n)
      if (n %% 2 == 0) return(n / 2)
      if (n > floor((exact_integer_limit - 1) / 3)) {
        stop("3*n + 1 would exceed the chosen range of exact integers.")
      }
      3 * n + 1
    }
    
    collatz_iterative <- function(n, max_steps = 10000L) {
      validate_collatz(n)
      validate_integer(max_steps, minimum = 0, name = "max_steps", maximum = 1e6)
      trajectory <- numeric(max_steps + 1)
      trajectory[1] <- n
      steps <- 0L
      current <- as.double(n)
      while (current != 1 && steps < max_steps) {
        current <- collatz_step(current)
        steps <- steps + 1L
        trajectory[steps + 1L] <- current
      }
      trajectory <- trajectory[seq_len(steps + 1L)]
      list(seed = n, trajectory = trajectory,
           iterations = steps, terms = length(trajectory),
           maximum = max(trajectory), reached_one = current == 1,
           status = if (current == 1) "Reached 1" else "Step limit reached")
    }
    
    c8 <- collatz_iterative(8)
    c27 <- collatz_iterative(27)
    c8$trajectory
    # [1] 8 4 2 1
    c(c27$iterations, c27$terms, c27$maximum)
    # [1] 111 112 9232
    stopifnot(c8$iterations == 3L, c8$terms == 4L,
              c27$iterations == 111L, c27$terms == 112L,
              c27$maximum == 9232, c27$reached_one)

    The transition function performs one transformation. The iterative function organizes transformations and returns a list with results and termination status. Each call creates its own trajectory, independent of a global vector defined in another session. The seed occupies the first position, followed by each new state. This decision removes counting ambiguities.

    Observed states and applications of the transformation
    SeedTrajectory or summaryTerms, including start and endTransitions to 1Maximum
    1The stopping destination has already been reached.101
    88, 4, 2, 1438
    27Full trajectory stored in c27$trajectory.1121119232

    A stopped trajectory with L terms has L − 1 transitions. The distinction also matters for a = 1: one term is recorded and no transition is performed. c(a, v) concatenates values and does not remove duplicates; if v already contains a, that value appears twice unless the algorithm prevents it. This implementation uses a single trajectory with explicit positions.

    R / 45 The time axis starts at zero; the line joins discrete states
    unfinished <- collatz_iterative(27, max_steps = 10)
    unfinished$status
    # [1] "Step limit reached"
    stopifnot(!unfinished$reached_one, unfinished$iterations == 10L)
    
    seed_one <- collatz_iterative(1, max_steps = 0)
    stopifnot(seed_one$reached_one, seed_one$iterations == 0L)
    
    plot(seq_along(c27$trajectory) - 1L, c27$trajectory,
         type = "l", col = "#8b4513", lwd = 1.5,
         xlab = "Iteration k", ylab = "State n[k]",
         main = "Collatz orbit starting at 27")
    Collatz orbit starting at 27111 transitions to 1; 112 terms including the initial value; maximum 9232 at iteration 77. Points represent discrete states. image/svg+xml Matplotlib v3.10.8, https://matplotlib.org/ 0 20 40 60 80 100 111 Iteration k 0 2000 4000 6000 8000 10000 State nₖ Maximum: 9232 27 → 1 · 111 transitions · 112 terms
    Figure 1 Trajectory calculated exactly for this seed. The initial segment and oscillations belong to the traversal before reaching 1.

    The line makes the plot easier to follow but does not turn its states into a continuous flow. Starting at 27, the trajectory reaches values far above its initial value before descending to 1. A step bound stops an exploration; reaching it reports a limitation of the executed traversal, not a counterexample. Exploring arbitrarily large integers would require exact arbitrary-precision arithmetic and a suitably adapted implementation.

    The recursive version: a base case and a call to itself

    R / 46 The same rule with a different organization of execution
    collatz_recursive <- function(n, max_steps = 300L) {
      validate_collatz(n)
      validate_integer(max_steps, minimum = 0, name = "max_steps", maximum = 300)
      walk <- function(current, remaining, accumulator) {
        accumulator <- c(accumulator, current)
        if (current == 1 || remaining == 0L) return(accumulator)
        walk(collatz_step(current), remaining - 1L, accumulator)
      }
      trajectory <- walk(as.double(n), max_steps, numeric(0))
      reached <- tail(trajectory, 1) == 1
      list(seed = n, trajectory = trajectory,
           iterations = length(trajectory) - 1L,
           terms = length(trajectory), maximum = max(trajectory),
           reached_one = reached,
           status = if (reached) "Reached 1" else "Step limit reached")
    }
    
    r8 <- collatz_recursive(8)
    r27 <- collatz_recursive(27)
    stopifnot(identical(c8$trajectory, r8$trajectory),
              identical(c27$trajectory, r27$trajectory))

    The inner function walk() records the state and checks a stopping case. To continue, it calls itself with the next state, one fewer available step, and the accumulated trajectory. The object returned by the inner call becomes the outer call’s result. An argument need not be renamed simply because another function uses the same name: every call creates its own evaluation environment.

    The recursive example deliberately uses a lower limit. Available depth depends on settings and environmental resources, so a step limit does not guarantee that every R implementation permits that call depth. R does not guarantee tail-call optimization. For long trajectories, the iterative version avoids accumulating recursive frames and is usually more appropriate.

    Pending calls and return in recursive CollatzCalls for states 8, 4, 2, and 1 are stacked. Resolving state 1 returns the full trajectory through the outer calls in reverse order.Pending callsResolution and returnwalk(8, …)walk(4, …)walk(2, …)walk(1, …)Base case: state 1.Accumulated trajectory:(8, 4, 2, 1).Last call: firstto resolve (LIFO).4 terms · 3 transitions
    Figure 2 Inner-function calls, with auxiliary parameters abbreviated. The same trajectory object is returned through the pending calls.

    What the call stack shows

    Starting at 8 leaves calls pending for states 8, 4, and 2 before the state-1 base case is resolved. Return resolves the most recent call first and earlier calls afterward: this is LIFO, last in, first out, also called FILO. A stack-of-plates analogy helps visualize the order, but does not establish that recursion was designed to optimize cache memory. Call stacks and cache policies are different concepts.

    A program that executes A1, then A2, and then calls itself again without a stopping condition leaves any subsequent instruction pending. Thus a final instruction to print “Hello, Fernanda” is not reached in an idealized execution continuing indefinitely. A real system may instead fail earlier through excessive call depth or resource use. A useful algorithm needs a base case or an explicit exit.

    Formalizing the trajectory without assuming termination

    τ(a) = min{k ≥ 0 : Tk(a) = 1}
    𝒪(a) = (a, T(a), …, Tτ(a)(a))
    If the orbit reaches 1, τ(a) is the first hitting index and the trajectory contains τ(a) + 1 terms. Otherwise no such finite minimum exists; one may adopt the convention τ(a) = infinity. This conditional definition does not prove finite hitting time for every seed.

    A recursive formula saying only “keep calling until 1 is reached” describes a procedure, but termination must be established for it to represent a total function on every accepted seed. Moreover, returning only the scalar 1 does not preserve the trajectory, which requires another codomain, such as finite sequences or lists. Separating the transformation T, hitting time, and trajectory avoids conflating different objects in one notation.

    Documentation and references: [1] · [16]

    A closer look at the language

    14. Environments, Classes, and Expressions

    The advanced concepts in this section clarify what R does when it evaluates a function, selects a method, or constructs an expression. They follow the first examples so that they can be linked to familiar operations. These are different explanatory levels: a storage type, a class, a reserved word, and a call are not interchangeable, although they may participate in one instruction.

    Environments and lexical scope

    R / 47 An inner function retains access to its creation environment
    offset <- 100
    make_offset <- function(delta) {
      force(delta)
      function(x) x + delta
    }
    add_two <- make_offset(2)
    add_two(5)
    # [1] 7
    offset
    # [1] 100

    The returned function can look up delta in the environment where it was created. This combination of function and environment is called a closure. Ordinary assignment inside a function establishes names in the call environment; looking up a name absent there proceeds through enclosing environments according to lexical scope. Not every object accessible outside a function belongs to the global environment: there may be enclosing function environments and package environments.

    force(delta) explicitly evaluates the argument before constructing the inner function; R uses lazy argument evaluation through promises. The example illustrates a function factory: it receives a number and returns a function. Its output makes it a higher-order function. Local objects from different calls do not conflict merely because they share a name.

    Types, classes, and methods

    R / 48 Class affects behavior in addition to storage
    date <- as.Date("2021-09-11")
    c(type = typeof(date), mode_value = mode(date), class_value = class(date))
    # type: "double"; mode: "numeric"; class: "Date".
    
    measurement <- structure(1.65, class = "height_m")
    print.height_m <- function(x, ...) {
      cat(format(unclass(x)), "m\n")
      invisible(x)
    }
    print(measurement)
    # 1.65 m
    inherits(measurement, "height_m")
    # [1] TRUE

    typeof() identifies the internal type. mode() supplies a historical classification that can group types; for example, integers and doubles have numeric mode. class() participates in method behavior. The date example stores numeric information, but its class allows it to be printed and interpreted as a date. In the height example, an S3 print() method defines how the object is displayed.

    A generic function selects a method through a dispatch mechanism. In S3, many generics use UseMethod(); S4 has formal definitions of classes, methods, and inheritance, with dispatch that may depend on several arguments. A description of one system should not be projected onto all the others. methods::extends() examines inheritance relationships in the formal system, and genericFunction is an S4 class, not the universal definition of every generic call in R.

    The image of a class as a blueprint or prototype for objects is a teaching aid suited to certain object-oriented models. R contains systems with different properties. A computational class is also not identical to a set-theoretic class: the latter is not simply a set of transfinite cardinality. In theories distinguishing sets and proper classes, many sets are already infinite or have transfinite cardinality without being proper classes.

    Reserved words and names that mask functions

    Reserved words include if, else, repeat, while, function, for, in, next, and break. Reserved constants include TRUE, FALSE, NULL, Inf, NaN, and typed variants of NA, alongside special names associated with .... Natural numbers are not a collection of reserved words. Ordinary function names are not all reserved: other assignments can mask them, often without an automatic warning preventing that design mistake.

    R / 49 The :: operator identifies the originating package
    # Avoid giving an object the name of a frequently used function.
    my_data <- c(1, 2, 3)
    base::sum(my_data)
    # [1] 6
    stats::median(my_data)
    # [1] 2

    A package contains functions, data, and documentation. An R library is a directory where packages are installed; a repository, such as CRAN, distributes packages. install.packages() installs; library() loads and attaches a package; requireNamespace() checks availability and loads its namespace without attaching it. Distinguishing these concepts prevents confusion between a distribution network, packages, and installed directories.

    The … argument and construction of names

    R / 50 Passing additional arguments explicitly
    sum_with_options <- function(x, ...) {
      sum(x, ...)
    }
    sum_with_options(c(1, NA_real_, 3), na.rm = TRUE)
    # [1] 4
    
    named_table <- data.frame(height_m = c(1.65, 1.70))
    names(named_table)
    # [1] "height_m"

    ... receives or forwards additional arguments. In data.frame(), column arguments may take the form name = value; when a name is omitted, the function can construct one from the supplied expression and adjust its syntax. Explicit column names clarify the structure and avoid dependence on name-transformation rules.

    Calls, expressions, and deparse()

    R / 51 Constructing a call and evaluating it are different operations
    call_object <- call("sum", c(1, 2, 3))
    typeof(call_object)
    # [1] "language"
    eval(call_object)
    # [1] 6
    
    expression_object <- expression(1 + 2, sqrt(9))
    typeof(expression_object)
    # [1] "expression"
    eval(expression_object)
    # [1] 3
    
    call_text <- deparse(call_object)
    call_text
    # [1] "sum(c(1, 2, 3))"

    call() constructs a call object whose first argument identifies the function and whose remaining arguments are incorporated into the call. Its arguments are evaluated while constructing it, but the resulting call has not yet been executed. eval() evaluates it in an environment. Calling an already defined function and defining a function are different operations: call() does not replace a definition using function().

    expression() stores expressions without evaluating them; evaluating the entire vector returns the value of the last expression. deparse() produces a textual representation of an expression. parse() turns text into language expressions, but converting text to code and evaluating it requires control over its provenance. These are metaprogramming tools, not prerequisites for creating your first data tables.

    Documentation and references: [1] · [16] · [17]

    From economic data to analysis

    15. Application: GDP Growth in Central America

    This application uses the World Bank indicator NY.GDP.MKTP.KD.ZG, annual GDP growth expressed as a percentage. The objective is to select Belize, Guatemala, El Salvador, Honduras, Nicaragua, Costa Rica, and Panama; preserve observations by year; inspect missingness; and construct summaries with explicit meanings. A download’s size and time coverage depend on the particular file and are not permanent properties of the indicator.

    An export may combine countries, other economies, and regional or income-group aggregates. Accordingly, each row is not interpreted as a country, and a row count is not treated as the number of countries in the world. The usual layout also includes metadata columns before the year columns. These text columns are not errors to be removed indiscriminately: they identify information and allow the correct units to be selected.

    A complete teaching sample with explicit provenance

    R / 52 Seven units and five years: exclusively illustrative data
    ca_codes <- c("BLZ", "GTM", "SLV", "HND", "NIC", "CRI", "PAN")
    ca_names <- c("Belize", "Guatemala", "El Salvador", "Honduras",
                    "Nicaragua", "Costa Rica", "Panama")
    
    demo_wb <- data.frame(
      "Country Name" = ca_names,
      "Country Code" = ca_codes,
      "Indicator Name" = "GDP growth (annual %)",
      "Indicator Code" = "NY.GDP.MKTP.KD.ZG",
      "2018" = c(2, 3, 2, 4, -4, 3, 4),
      "2019" = c(1, 4, 3, 3, -3, 2, 3),
      "2020" = c(-12, -2, -8, -9, -2, -4, -16),
      "2021" = c(10, 8, 10, 12, 10, 8, 15),
      "2022" = c(7, 4, 3, 4, NA_real_, 5, 11),
      check.names = FALSE, stringsAsFactors = FALSE
    )
    stopifnot(nrow(demo_wb) == 7L, ncol(demo_wb) == 9L)

    Three-letter codes provide a selection stable against changes in row order. The table uses check.names = FALSE to preserve year headings as written. If a reading procedure changes 2020 into X2020, explicitly correct or interpret that transformation. The procedure below expects four-digit year headings and reports an error if none are found.

    Validating a download and separating metadata from years

    R / 53 Selecting by codes and year names, never by row numbers
    convert_wb_column <- function(x) {
      text_value <- trimws(as.character(x))
      missing_value <- is.na(x) | text_value %in% c("", "..", "NA", "N/A")
      text_value[missing_value] <- NA_character_
      number <- suppressWarnings(as.numeric(text_value))
      if (any(!missing_value & is.na(number))) {
        stop("A year column contains text not recognized as a number or a missing value.")
      }
      if (any(!is.na(number) & !is.finite(number))) {
        stop("A year column contains nonfinite values.")
      }
      number
    }
    
    prepare_growth <- function(input_data, codes = ca_codes,
                                    start_year = NULL, end_year = NULL) {
      d <- as.data.frame(input_data, check.names = FALSE,
                         stringsAsFactors = FALSE)
      required_columns <- c("Country Name", "Country Code", "Indicator Code")
      if (!all(required_columns %in% names(d))) {
        stop("Required identification columns are missing.")
      }
      if (anyDuplicated(names(d))) stop("Column names are duplicated.")
      if (anyNA(codes) || anyDuplicated(codes) || length(codes) == 0L) {
        stop("Requested codes must be unique, nonmissing, and nonempty.")
      }
      selection <- !is.na(d[["Indicator Code"]]) &
        d[["Indicator Code"]] == "NY.GDP.MKTP.KD.ZG" &
        d[["Country Code"]] %in% codes
      d <- d[selection, , drop = FALSE]
      if (anyDuplicated(d[["Country Code"]])) {
        stop("There is more than one row per code for the selected indicator.")
      }
      position <- match(codes, d[["Country Code"]])
      if (anyNA(position)) {
        stop("Not all requested codes were found.")
      }
      d <- d[position, , drop = FALSE]
      year_names <- names(d)[grepl("^[0-9]{4}$", names(d))]
      if (length(year_names) == 0L) stop("No year columns were found.")
      years <- as.integer(year_names)
      sort_index <- order(years)
      years <- years[sort_index]
      year_names <- year_names[sort_index]
      if (!is.null(start_year)) {
        validate_integer(start_year, minimum = 0, name = "start_year", maximum = 9999)
      }
      if (!is.null(end_year)) {
        validate_integer(end_year, minimum = 0, name = "end_year", maximum = 9999)
      }
      if (!is.null(start_year) && !is.null(end_year) && start_year > end_year) {
        stop("The start year cannot be later than the end year.")
      }
      keep <- rep(TRUE, length(years))
      if (!is.null(start_year)) keep <- keep & years >= start_year
      if (!is.null(end_year)) keep <- keep & years <= end_year
      years <- years[keep]
      year_names <- year_names[keep]
      if (length(years) == 0L) stop("The interval contains no available years.")
      values <- lapply(d[year_names], convert_wb_column)
      M <- as.matrix(as.data.frame(values, check.names = FALSE))
      dimnames(M) <- list(codes, as.character(years))
      metadata <- d[, required_columns, drop = FALSE]
      rownames(metadata) <- NULL
      long_data <- data.frame(
        country = rep(d[["Country Name"]], each = length(years)),
        code = rep(codes, each = length(years)),
        year = rep(years, times = length(codes)),
        growth_pct = as.vector(t(M)),
        stringsAsFactors = FALSE
      )
      list(metadata = metadata, years = years,
           matriz = M, long_data = long_data)
    }
    
    ca <- prepare_growth(demo_wb, start_year = 2018, end_year = 2022)
    dim(ca$matriz)
    # [1] 7 5
    head(ca$long_data)
    stopifnot(identical(rownames(ca$matriz), ca_codes),
              nrow(ca$long_data) == 35L, sum(is.na(ca$matriz)) == 1L)

    The function converts only annual columns and checks for unrecognized strings. Suppressing conversion warnings is paired with a check that stops the analysis when unexpected losses appear: the problem is not hidden. Metadata are retained separately. Long format has one row per country-year; the matrix preserves one row per country and one column per year. Both layouts preserve each measurement’s identity.

    The transposition used to build long format organizes the order in which cells are traversed. It does not “fix” year names, nor is it needed because a named vector cannot be averaged. Names are attributes compatible with numeric computation. To extract a series from the matrix, select its row; remove names only when another operation requires it.

    R / 54 Mean, median, dispersion, extremes, missingness, and empirical modes
    Guatemala <- ca$matriz["GTM", ]
    mean(Guatemala)
    # [1] 3.4
    unname(Guatemala)
    # [1] 3 4 -2 8 4
    
    ca_summary <- t(vapply(seq_len(nrow(ca$matriz)),
                           function(i) available_summary(ca$matriz[i, ]),
                           numeric(9)))
    rownames(ca_summary) <- rownames(ca$matriz)
    ca_summary
    
    empirical_mode <- function(x) {
      x <- x[!is.na(x)]
      if (length(x) == 0L) return(numeric(0))
      frequencies <- table(x)
      as.numeric(names(frequencies)[frequencies == max(frequencies)])
    }
    lapply(seq_len(nrow(ca$matriz)),
           function(i) empirical_mode(ca$matriz[i, ]))

    The mean and median summarize different aspects of the level of rates; variance and standard deviation describe dispersion over the period. Their interpretation does not make years independent observations by definition. The empirical mode function returns every value tied for highest frequency, so several may be returned. With continuous measurements containing many distinct values, this mode may be uninformative and highly sensitive to rounding. R’s mode() inspects a computational mode; it does not calculate the statistical mode.

    Four economic questions, four operations

    The calculation must answer the economic question
    QuestionAppropriate operationInterpretive limitation
    What was a country’s observed average annual rate?Arithmetic mean of available rates.Report period and coverage; this is not cumulative growth.
    How much did it grow cumulatively across consecutive years?Compound growth factors.Requires the rates for every transition in the period.
    What equivalent constant annual compound rate gives the same result?Geometric mean of the factors, minus one.Requires a defined number of transitions and valid factors.
    What was the region’s GDP growth?Aggregation using coherent levels and weights.Not obtained simply by adding national rates; follow the aggregate’s methodology.
    G = ∏t=1T(1 + gt/100) − 1
    geq = 100[(1 + G)1/T − 1]
    g_t is an annual percentage rate. G is cumulative growth as a proportion; 100G expresses it as a percentage. The second formula spreads the total factor over T identical factors. A complete temporal chain of transitions is required.
    R / 55 Compounding rates with explicit time coverage
    compound_growth <- function(rates, years) {
      if (!is.numeric(rates) || !is.numeric(years) ||
          length(rates) != length(years) || length(rates) == 0L ||
          anyNA(years) || any(!is.finite(years)) || any(years != floor(years))) {
        stop("Rates and their years must be compatible numeric vectors.")
      }
      if (length(years) > 1L && any(diff(years) != 1)) {
        stop("Years must be ordered and consecutive.")
      }
      if (anyNA(rates)) {
        return(c(cumulative_pct = NA_real_, equivalent_annual_pct = NA_real_))
      }
      if (any(!is.finite(rates)) || any(rates <= -100)) {
        stop("This example requires finite rates greater than -100%.")
      }
      log_sum <- sum(log1p(rates / 100))
      c(cumulative_pct = 100 * expm1(log_sum),
        equivalent_annual_pct = 100 * expm1(log_sum / length(rates)))
    }
    compound_growth(c(10, -10), c(2020, 2021))
    # cumulative_pct: -1; equivalent_annual_pct: approximately -0.5012563.
    compound_growth(ca$matriz["GTM", ], ca$years)
    compound_growth(ca$matriz["NIC", ], ca$years)
    # Both compounded summaries are NA for Nicaragua because one rate is missing.

    An increase of 10% followed by a decrease of 10% leaves a factor of 1.10 × 0.90 = 0.99: cumulative change is −1%, although the sum and arithmetic mean of the rates are zero. The implementation uses log1p() and expm1() to express compounding with improved precision near zero. If rates labeled 2018–2022 describe changes from the preceding year, compounding them compares the end-of-2022 level with the level preceding the first transition, 2017. Interpret time labels according to the indicator definition.

    Dropping a missing rate and compounding the rest can join segments that do not reconstruct growth over the full interval. The function therefore returns missingness rather than presenting a partial accumulation as complete. Nor is the annual sum of different countries’ rates the region’s growth: GDP aggregation requires comparable levels and consistent weights, while avoiding the inclusion of both an aggregate and its members, which would double-count information.

    Using an actual World Bank file

    R / 56 An explicit template separating demonstration from actual data
    # Template for an XLS/XLSX download: adjust the path, sheet, and initial rows.
    # This block does not download data or replace inspection of the file.
    wb_path <- file.path("data", "world_bank_gdp_growth.xlsx")
    if (file.exists(wb_path) && requireNamespace("readxl", quietly = TRUE)) {
      sheets <- readxl::excel_sheets(wb_path)
      print(sheets)
      if (!"Data" %in% sheets) {
        stop("Check the data sheet; this example expected Data.")
      }
      preview <- readxl::read_excel(wb_path, sheet = "Data",
                                        col_names = FALSE, n_max = 8)
      print(preview)
      # skip = 3 fits the layout with column headings on the fourth row.
      wb_input <- readxl::read_excel(wb_path, sheet = "Data", skip = 3,
                                     col_types = "text", na = c("", ".."))
      ca_actual <- prepare_growth(wb_input, start_year = 2000, end_year = 2020)
      print(dim(ca_actual$matriz))
    } else {
      message("The empirical application requires the specified file and readxl.")
    }

    If the sheet is named “Datos” or something else, change the argument after inspecting the workbook. skip = 3 is not a law of the Excel format. For a ZIP download containing CSV, first extract the data file and inspect its preliminary lines; then configure read.csv(), preserving headings with check.names = FALSE. The example years 2000–2020 are an analytical choice, not a promise of complete availability.

    • Record the indicator address, retrieval date, original file, and sheet or table.
    • Confirm country codes, indicator code, and percentage units.
    • Report dimensions after selection without counting metadata as years.
    • Inspect missingness by country and year; do not interpret blank cells as zeros.
    • Preserve the original file and export results under names identifying the period and procedure.
    R / 57 Exports explicitly identified as demonstrations
    write.csv(ca$long_data,
              file = file.path(example_directory, "central_america_demo_long_format.csv"),
              row.names = FALSE, na = "", fileEncoding = "UTF-8")
    write.csv(ca_summary,
              file = file.path(example_directory, "central_america_demo_summary.csv"),
              row.names = TRUE, na = "", fileEncoding = "UTF-8")

    Documentation and references: [20] · [21] · [22]

    Understand, check, and reproduce

    16. Working Principles and Exercises

    A statistical program should make it possible to reconstruct the decisions separating source from result. Data size, file format, and function complexity do not alter that requirement. We need to know what each object represents, how observations were selected, which were excluded, and what the applied operation means. Visual inspection and automatic checks complement one another.

    Validity has computational, mathematical, and substantive components
    Before calculatingDuring calculationWhen interpreting
    Identify unit, variable, scale, and provenance.Check types, lengths, and dimensions.Connect the output to the original question.
    Distinguish observations from metadata.Verify selection by names and codes.Report coverage and missing-value treatment.
    Preserve original data and program.Validate assumptions and boundary cases.Distinguish approximation, verification, and proof.
    Record version and dependencies.Separate returned results from effects.Preserve reproducible output with units and labels.

    Errors worth recognizing

    • Unnoticed reassignment: a later assignment changes the value bound to a name in that environment. Keeping a separate name for original data makes transformations easier to review.
    • Misread equality: <- assigns, == compares, and <= orders. Approximate numerical equality requires an appropriate tolerance.
    • A mask containing missing values: a condition can contain NA. Decide whether to preserve these as unknown information or explicitly exclude them before selection.
    • Identity and order: equal length does not establish that vectors are correctly paired. Use stable identifiers.
    • Mixed types: a label column can turn an entire matrix into text. Calculate summaries on the relevant numeric columns.
    • Incompatible units: adding quantities with different units is a dimensional issue; converting text to numbers is a representation issue. They can coexist but are not identical.
    • Excessive interpretation: numeric output does not establish temporal independence, sample representativeness, causality, or the universal validity of a conjecture.

    Exercises with checkable results

    Apply an operation and explain its meaning
    ExerciseResult or checking criterion
    Construct a sequence from 0 to 1 with five positions.0, 0.25, 0.5, 0.75, 1.
    Extract values strictly between 3 and 8 from c(2, 5, 8, NA).The result is 5; the condition must explicitly handle missingness.
    Sum positive even integers no greater than 50 using a loop and a formula.Both methods give 650.
    Calculate the three students’ average grades.75.50, 66.75, and 47.25; pass, resit, and fail.
    Distinguish elementwise and matrix multiplication for the chapter’s matrices.The former preserves 2 × 3; matrix01 %*% t(matrix03) produces 2 × 2.
    Compare Collatz starting at 8 and at 27.3 and 111 transitions; 4 and 112 terms. From 27 the maximum is 9232.
    Compound a 10% increase and a 10% decrease.Cumulative change is −1%.
    Calculate a mean when every value is missing.Identify that no observations are available; do not interpret the result as a zero mean.

    A minimal reproducibility record

    R / 58 Execution should provide evidence of its conditions
    # Information to accompany a shared analysis.
    sessionInfo()
    RNGkind()
    
    # Brief checks of the integrated applications.
    stopifnot(
      sum_even(50) == 650,
      isTRUE(all.equal(unname(grade_averages), c(75.5, 66.75, 47.25))),
      c27$iterations + 1L == length(c27$trajectory),
      nrow(ca$long_data) == nrow(ca$matriz) * ncol(ca$matriz),
      abs(compound_growth(c(10, -10), c(2020, 2021))[1] + 1) < 1e-10
    )

    The chosen checks contrast identities and results verifiable through another route: a formula against a loop, counts against structures, and compounded rates with a known result. They do not replace reading code or examining data. They make changes that alter important behavior visible when the program is modified.

    Understanding an instruction requires knowing the object it receives, the transformation it performs, and the conclusion it supports.

    A reading principle for this chapter

    Documentation and references: [2]

    Documentation and traceability

    17. References and Provenance

    Definitions of the language and its functions rely primarily on R and package documentation. Links to R-devel may describe behavior newer than a local installation; installed help, accessed with ?name, documents the version being used. This chapter makes relevant behavior explicit, including scalar conditions and the default value of stringsAsFactors.

    1. R Core Team. R Language Definition: objects, evaluation, functions, indexing, and syntax.
    2. R Core Team. An Introduction to R: vectors, structures, and programming.
    3. R Core Team. Logical Operators: elementwise logic and short-circuit evaluation.
    4. R Core Team. Control Flow: if, for, while, repeat, break, and next.
    5. R Core Team. Not Available / Missing Values.
    6. R Core Team. Vectors: Creation, Coercion, etc.
    7. R Core Team. Colon Operator and sequence generation.
    8. R Core Team. Apply Functions Over Array Margins.
    9. R Core Team. Multi-way Arrays.
    10. R Core Team. Data Frames.
    11. R Core Team. Numeric Vectors: types and factor conversion.
    12. R Core Team. Conditional Element Selection: ifelse().
    13. R Core Team. Correlation, Variance and Covariance.
    14. R Core Team. Integration of One-Dimensional Functions.
    15. Wickham, H. Advanced R, second edition: functionals.
    16. Wickham, H. Advanced R: functions and lexical scope.
    17. Wickham, H. Advanced R: object-oriented systems.
    18. The readxl team. Read xls and xlsx files.
    19. The writexl team / rOpenSci. Export to xlsx.
    20. World Bank. GDP growth (annual %), NY.GDP.MKTP.KD.ZG.
    21. World Bank. Methodologies: aggregation rules and methods.
    22. World Bank. Aggregate API Queries: economies and aggregates.

    Sources used in the original document

    The 2021 version drew on A. Ballestero’s materials on operators and functions in RStudio, Kolmogorov and Fomin’s text on function theory and functional analysis, and tutorials, documentation, and technical discussions. That bibliographical provenance is retained. Analogies and formulations revised in this edition should be assessed through the definitions and explanations developed in the chapter.

    Provenance bibliography and original links
    1. Ballestero, A. (2020). Fundamentos de programación en R Studio. Operadores, vectores, listas, matrices, variables y data frame.
    2. Ballestero, A. (2021). Fundamentos de programación en R Studio. Funciones en R, Parte I.
    3. Banco Mundial (2021). Crecimiento del PIB (% anual), source for the original application.
    4. Codecademy (2021). What is function call?
    5. DataMentor (2021). R while Loop.
    6. R Documentation, originally cited as EHZ/ETH Zürich (2020). Unevaluated Expressions.
    7. Estadísticamente (2021). Sucesiones, repeticiones y factores en R.
    8. R Documentation, originally cited as ETH Zürich (2020). Generic Function Objects.
    9. R Documentation, originally cited as ETH Zürich (2020). Logical Vectors.
    10. R Documentation, originally cited as ETH Zürich (2021). Function Calls.
    11. GeeksforGeeks (2020). Matrix vs Dataframe in R.
    12. JournalDev (2021). How to replace values using replace() in R.
    13. Langohr, K. (2010). Introducción a R. Universitat Politècnica de Catalunya.
    14. Mendoza Vega, J. B. (2021). R para principiantes: coerción.
    15. Mendoza Vega, J. B. (2021). R para principiantes: if, else.
    16. Moore, K., and collaborators (2021). Classes (OOP). Brilliant.
    17. Stack Overflow (2013). Confused about R terminology: Attributes, parameters, and arguments.
    18. RDocumentation.org (2021). Expression Deparsing.
    19. Real Academia Española (2021). Anidar.
    20. Sánchez, G. (2020). Character Strings in R.
    21. Simpson, G. (2011). What evaluates to True/False in R?
    22. Stack Overflow (2016). What is the difference between mode and class in R?
    23. Stackoverrun (2021). Global and local variables in R.
    24. Wickham, H., cited in 2019. Functionals, first edition of Advanced R.
    25. Wickham, H., cited in 2019. Functions / Primitive functions, first edition of Advanced R.
    26. Wikipedia, cited in 2020. Implementation.
    27. Wikipedia, cited in 2020. Stack (abstract data type).
    28. TechTerms (2014). FILO, cited in the original note on stacks.
    29. Kolmogórov, A. N., y Fomin, S. V. (1978). Elementos de la teoría de funciones y del análisis funcional, third edition. Moscow: MIR. Originally cited at p. 121.
    30. Huamaní Ninahuanca (2019), mentioned in an original note supporting integer-vector terminology; the PDF does not provide a complete bibliographic reference.
    31. Stack Overflow (2015), a discussion cited in the original note on cat() and print(); the PDF provides no identifiable link.
    32. Study.com (2021), cited in an original note on the class-as-blueprint analogy; the PDF does not include the complete reference.

    Years and titles in this list retain the identification used in the source document; they do not imply that every older resource remains available or replace primary documentation supporting this edition’s corrections. Original Spanish bibliographic titles are retained where appropriate. The Stroustrup quotation cited through Wickham motivated attention to clear control flow; that concern is developed through examples here without extensively reproducing the quotation.

  • INTRODUCTION TO CLINICAL TRIALS FROM STATISTICAL THEORY AND RSTUDIO: ASSOCIATION AND CORRELATION OF PEARSON, SPEARMAN AND KENDALL

    INTRODUCTION TO CLINICAL TRIALS FROM STATISTICAL THEORY AND RSTUDIO: ASSOCIATION AND CORRELATION OF PEARSON, SPEARMAN AND KENDALL

    Mathematical statistics · Theory and practice

    Association and Correlation in Statistics

    Pearson, Spearman and Kendall: foundations, inference, and an introduction to clinical trials with R
    Originally published: September 11, 2021 · Expanded revision: November 2, 2026

    Studying association means asking how the variations, orderings or frequencies of two characteristics relate to one another. The answer depends on what we observe, how we measure it and how the data were obtained: a linear relationship between temperature and industrial conversion is not quite the same problem as comparing heart attacks across two arms of a clinical trial.

    This article develops those distinctions through definitions, explained equations and reproducible calculations in R. It moves from covariance to Pearson, Spearman and Kendall correlations, then to contingency tables, association tests and effect measures for a binary outcome. At each stage, description of the data, uncertainty in estimation and the scientific scope of a conclusion remain distinct.

    01 · The scientific question comes before the coefficient

    A statistical association is a regularity in the joint distribution of variables. Correlation summarizes particular aspects of that regularity. Causation additionally requires an account of what would happen to an outcome if an intervention changed the exposure or treatment. Selecting a coefficient does not, by itself, answer that third question.

    Before calculating, identify the observational unit, measurement scale, target population, observation period and study design. Two measurements on one person form a pair; twenty measurements on the same person are not equivalent to twenty independent people. Ordered categories, numerical magnitudes and nominal categories also call for different analyses.

    QuestionInitial toolLimit of the answer
    Is there a linear association between numerical quantities?Pearson and a scatterplotCurved relationships may be missed.
    Do values tend to preserve an increasing or decreasing order?Spearman or KendallA rank summary may miss nonmonotonic patterns.
    Do event frequencies differ between groups?Contingency table, risks and comparative measuresThe design determines which risks and effects are identifiable.
    Does treatment cause a difference?Appropriate causal design and analysisAssociation or a p-value alone is insufficient.

    The estimand is the population quantity of interest; an estimator is a rule for calculating it from a sample; an estimate is the resulting value. A test statistic is constructed to evaluate compatibility with a hypothesis. For example, ρ is a population correlation, r is its estimator and t is the statistic used in the classical zero-correlation test.

    02 · Covariance and Pearson: from joint variation to standardization

    sXY = ∑i=1n (xi − x̄)(yi − ȳ)n − 1(1)

    Centering each observation around its mean identifies whether it lies above or below average. The product of the two deviations is positive when their signs agree and negative when their signs differ. The sum combines these contributions. Dividing by n − 1 gives the usual sample covariance, unbiased under independent, identically distributed sampling with finite moments.

    Covariance retains units: when X is measured in degrees and Y in percentage points, the units are their product. Its magnitude therefore does not supply a universal scale of association strength.

    r = sXYsXsY = ∑ (xi − x̄)(yi − ȳ)√[∑ (xi − x̄)² ∑ (yi − ȳ)²](2)

    Standardization removes units and places r between −1 and 1. Its sign indicates direction, while its absolute value summarizes linear alignment. The endpoints correspond to a perfect affine relationship in the sample. A constant variable has zero standard deviation, making the coefficient undefined.

    Pearson can be used with quantitative interval or ratio variables; calculating it does not require normality. It is not a proportion of people or a general percentage of shared variation. In simple linear regression with an intercept and the same observations, R² = r², but that identity has this specific context.

    Cov(a + bX, c + dY) = bd Cov(X,Y)
    Cor(a + bX, c + dY) = sign(bd) Cor(X,Y),   b,d ≠ 0(3)

    Adding constants does not change association. Multiplication by positive factors changes covariance but preserves correlation; reversing the sign of one variable reverses Pearson’s sign. Invariance to changes in measurement units is therefore distinct from invariance to arbitrary transformations.

    03 · Zero correlation, dependence and geometry

    If two variables are independent and have finite, positive variances, their population correlation is zero. The converse is false. Let X be uniform on [−1,1] and Y = X²: by symmetry, E[X] = E[X³] = 0, and hence Cov(X,Y) = 0, although knowing X determines Y exactly. Absence of linear association does not remove dependence.

    Geometrically, r is the cosine of the angle between the centered sample vectors. If r = 0, these vectors are orthogonal. Sample orthogonality is not probabilistic independence and should not be confused with linear independence of vectors. Under a jointly bivariate normal model, zero population correlation does imply independence, but separately normal marginal distributions do not suffice.

    [12]
    2026-11-02T13:35:34.701199 image/svg+xml Matplotlib v3.10.8, https://matplotlib.org/ 0 2 4 6 8 10 X 0 2 4 6 8 10 12 Y r = 0.997 ρs = 1.000 A · Linear relationship 0 2 4 6 8 10 X −25 0 25 50 75 100 125 150 175 Y r = 0.865 ρs = 1.000 B · Monotonic and curved −6 −4 −2 0 2 4 6 X −5 0 5 10 15 20 25 30 Y r = -0.000 ρs = 0.000 C · Dependence without linear correlation 0 5 10 15 20 X −2 0 2 4 6 8 10 12 Y r = -0.000 ρs = 0.500 D · One influential point
    Figure 1. Constructed data illustrate contrasting patterns. In C, Y = X²: the U shape reveals dependence although Pearson is zero. In D, one point changes a previously perfect relationship. Coefficients summarize these points; they do not establish causation.

    Inspect the points before choosing a coefficient: linearity, monotonicity, influential values, clusters and restricted ranges can lead to different interpretations. None of the three coefficients discussed here is a universal detector of dependence.

    04 · Spearman: correlation between ranks

    rs = Cor(RX, RY)(4)

    Spearman replaces magnitudes with ordered positions. A strictly increasing relationship preserves the orderings and reaches +1 when the ranks agree perfectly; a decreasing relationship reaches −1 when they are perfectly reversed. Because it uses order, a strictly increasing transformation of a variable preserves the coefficient. A monotonic association can be curved: increasing X may accompany increasingly large increments in Y.

    rs = 1 − 6∑ di²n(n² − 1)   (no ties)(5)

    In the shortcut formula, di is the difference between the two ranks of observation i. Ordering discrepancies reduce the coefficient from its maximum. With ties, assign average ranks and calculate Pearson on those ranks; do not automatically apply the shortcut. Rank methods reduce the influence of extreme magnitudes, but do not eliminate every problem of data, design or interpretation.

    [1]

    05 · Kendall: concordance, discordance and ties

    With n observations there are n(n − 1)/2 pairs of observations. A pair is concordant when the observation higher on X is also higher on Y, and discordant when this ordering is reversed. Equality requires specific treatment.

    τa = C − Dn(n − 1)/2   (no ties)
    τb = C − D√[(C + D + TX)(C + D + TY)](6)

    C and D count concordant and discordant pairs; TX counts pairs tied only on X, and TY those tied only on Y. Pairs tied on both variables contribute to none of these four counts. Without ties, τ can be interpreted as the difference between the probabilities of concordance and discordance for a random pair. The τb version normalizes for ties and is calculated by cor(..., method = "kendall").

    A minimal example with a tie on X
    ObservationXYRank XRank Y
    11111
    2232.53
    3222.52
    44444

    Here C = 5, D = 0, TX = 1 and TY = 0. Thus τb = 5/√30 ≈ 0.912871 and Spearman ≈ 0.948683. The numbers differ because the coefficients summarize different objects; applying identical strength thresholds to both requires justification.

    [3]

    06 · Choosing a measure and specifying its assumptions

    MeasureWhat it summarizesWhat to inspect
    PearsonLinear association between magnitudesScatterplot, influential points, observed range and inferential model.
    SpearmanRank association, sensitive to monotonicityMeaningful ordering, ties and p-value calculation.
    KendallBalance of concordance and discordanceTies, the version of τ and the test approximation.

    The decision should follow the substantive question and anticipated pattern. An isolated normality test does not automatically determine which coefficient makes sense. Pearson remains a calculable linear summary with nonnormal data; what may fail is classical inference used without regard to its model.

    The exact Pearson t test under zero correlation is justified for independent pairs from the bivariate normal model. In the equivalent fixed-X regression formulation, the model uses independent normal errors with constant variance. These are related frameworks; neither reduces to checking the normality of Y alone. Rank methods also require a sampling framework and independent observational units for their ordinary tests.

    Repeated measurements, clusters, time series and complex selection require procedures that respect that structure. A coefficient calculated while ignoring it may describe the points without making its ordinary p-value valid.

    07 · Complete data and manual calculation in R

    Two teaching contexts are retained: conditions in a vinylation process and association between animal activity and metabolism. The industrial question concerns how temperature and pressure relate to percentage conversion; those associations alone do not identify optimal settings for a multivariable process.

    # Illustrative data, not the missing original CSV files.
    vinylation <- data.frame(
      temperature = c(60,65,70,75,80,85,90,95),
      pressure = c(2,4,3,5,4,6,5,7),
      conversion = c(22,29,27,38,43,41,52,56)
    )
    activity <- data.frame(
      activity_index = c(2,3,3,4,5,5,6,7,7,8,9,9,10,11,11,12,13,14,14,15),
      metabolic_rate = c(12,14,13,15,18,16,19,21,20,22,25,23,26,29,27,30,31,34,32,35)
    )
    
    # Retain complete, finite pairs; record what was removed.
    prepare_pairs <- function(x, y) {
      stopifnot(is.numeric(x), is.numeric(y), length(x) == length(y))
      ok <- is.finite(x) & is.finite(y)
      x <- x[ok]; y <- y[ok]
      if (length(x) < 4L) stop("At least four complete pairs required.")
      if (sd(x) == 0 || sd(y) == 0) stop("A variable is constant.")
      list(x = x, y = y, n = length(x), removed = sum(!ok))
    }
    pairs_xy <- prepare_pairs(vinylation$temperature, vinylation$conversion)
    x <- pairs_xy$x; y <- pairs_xy$y; n <- pairs_xy$n
    pairs_xy[c("n", "removed")]
    

    The sample size n is obtained after selecting valid pairs. The function reports excluded observations and prevents correlations involving constant variables. Complete-case deletion is an analytical decision, not a general remedy for missing-data bias: why observations are missing still matters.

    s_xy <- sum((x - mean(x)) * (y - mean(y))) / (n - 1)
    r <- s_xy / (sd(x) * sd(y))
    c(covariance = s_xy, pearson = r)
    stopifnot(isTRUE(all.equal(s_xy, cov(x, y))),
              isTRUE(all.equal(r, cor(x, y))))
    
    S <- cov(vinylation)
    S                         # Variances on the diagonal.
    cor(vinylation)            # Pearson by default.
    cor(vinylation, method = "spearman")
    cor(vinylation, method = "kendall")
    stopifnot(isTRUE(all.equal(cov2cor(S), cor(vinylation))))
    

    In the industrial example, sXY = 142.857143 and r = 0.971057. The eight illustrative points display pronounced positive alignment; the small sample limits assessment of assumptions. In a covariance matrix, variances occupy the diagonal and covariances the off-diagonal positions. A correlation matrix has diagonal entries of 1 for nonconstant variables.

    When comparing matrices with missing values, prefer a common, documented sample. Pairwise deletion may use different observations for each entry and yield a matrix that is not positive semidefinite.

    rx <- rank(x, ties.method = "average")
    ry <- rank(y, ties.method = "average")
    rho_s <- cor(rx, ry)
    stopifnot(isTRUE(all.equal(rho_s, cor(x, y, method = "spearman"))))
    
    # Formula without ties: use only when neither variable has ties.
    if (!anyDuplicated(x) && !anyDuplicated(y)) {
      rho_short <- 1 - 6 * sum((rx - ry)^2) / (n * (n^2 - 1))
      stopifnot(isTRUE(all.equal(rho_s, rho_short)))
    }
    
    kendall_manual <- function(x, y) {
      ij <- combn(seq_along(x), 2)
      sx <- sign(x[ij[1, ]] - x[ij[2, ]])
      sy <- sign(y[ij[1, ]] - y[ij[2, ]])
      C <- sum(sx * sy > 0); D <- sum(sx * sy < 0)
      Tx <- sum(sx == 0 & sy != 0)  # Tied only on x.
      Ty <- sum(sy == 0 & sx != 0)  # Tied only on y.
      den <- sqrt((C + D + Tx) * (C + D + Ty))
      if (den == 0) return(NA_real_)
      (C - D) / den
    }
    tau_b <- kendall_manual(x, y)
    stopifnot(isTRUE(all.equal(tau_b, cor(x, y, method = "kendall"))))
    c(pearson = r, spearman = rho_s, kendall = tau_b)
    
    # Small, tied example: average ranks and pair counts are inspectable.
    u <- c(1, 2, 2, 4); v <- c(1, 3, 2, 4)
    data.frame(u, v, rank_u = rank(u), rank_v = rank(v))
    c(spearman = cor(u, v, method = "spearman"),
      kendall = kendall_manual(u, v))
    

    The same eight pairs yield Spearman = 0.952381 and Kendall = 0.857143. The code makes ranks and pair counts explicit and checks manual formulas against R functions. Automatic calculations do not replace understanding of the estimated object.

    08 · Inference: hypotheses, p-values and decisions

    H0: ρ = 0   versus   H1: ρ ≠ 0
    t = r √[n − 21 − r²],   df = n − 2(7)

    The sample supplies r; the test evaluates a statement about ρ. Under the classical assumptions and H0, the statistic follows Student’s t distribution with n − 2 degrees of freedom. A two-sided alternative combines both tail probabilities, which is why the code uses the absolute value of t.

    The p-value is the probability, under the specified null model, of obtaining a statistic at least as extreme as the observed one. It is not P(H0 | data), the probability that the result is due to chance, or the effect size. A significance level α is fixed as part of the procedure: a Type I error is rejection of a true null hypothesis. The observed p-value is not a personalized probability of having made that error.

    If the prespecified criterion is p ≤ α, reject H0 when it holds. Otherwise, do not reject: insufficient evidence does not prove an exactly zero correlation. Nor does a significant result demonstrate a strong association, clinical importance or causality.

    [5]

    Rank tests distinguish exact procedures from approximations. Ties affect which calculations are available; exact = FALSE explicitly requests an approximation in examples containing ties. A t transformation of Spearman should not be presented as exact for every sample. In R, even the option named exact for Spearman can use approximations depending on sample size.

    [2]

    09 · Confidence intervals: Fisher’s transformation

    zr = atanh(r) = ½ ln[1 + r1 − r]
    SE(zr) ≈ 1√(n − 3)(8)

    The coefficient r is bounded and its sampling distribution may be asymmetric, particularly near ±1. Fisher maps it to an unbounded scale with an approximately normal distribution and a variance approximately stable across values of ρ. The standard error shown belongs to that transformed scale.

    CIz = zr ± z1−α/2√(n − 3)
    CIρ = [tanh(Lz), tanh(Uz)](9)

    Transform first, construct the interval second, and invert its endpoints third. The bounds then return to the correlation scale. The approximation requires n > 3 and |r| < 1 and remains sensitive to the model and sample size. A 95% interval is interpreted through the procedure’s coverage across repeated samples, rather than a 95% frequentist probability assigned to the fixed parameter after observing the data.

    [11]
    if (abs(r) >= 1) stop("Perfect correlation: inspect the data separately.")
    t_stat <- r * sqrt((n - 2) / (1 - r^2))
    p_two <- 2 * pt(-abs(t_stat), df = n - 2)
    alpha <- 0.05
    z_r <- atanh(r)
    ci_r <- tanh(z_r + c(-1, 1) * qnorm(1 - alpha/2) / sqrt(n - 3))
    pearson_test <- cor.test(x, y, method = "pearson", conf.level = 1-alpha)
    c(t = t_stat, df = n-2, p = p_two, lower = ci_r[1], upper = ci_r[2])
    stopifnot(isTRUE(all.equal(p_two, pearson_test$p.value)),
              isTRUE(all.equal(as.numeric(ci_r), as.numeric(pearson_test$conf.int))))
    
    # Ties: explicitly request approximations rather than exact p-values.
    cor.test(activity$activity_index, activity$metabolic_rate,
             method = "pearson")
    cor.test(activity$activity_index, activity$metabolic_rate,
             method = "spearman", exact = FALSE)
    cor.test(activity$activity_index, activity$metabolic_rate,
             method = "kendall", exact = FALSE)
    
    # Quantile comparison, not a correlation-confidence-interval recipe.
    cbind(df = c(6, 30, 1000), t975 = qt(.975, c(6, 30, 1000)),
          normal975 = qnorm(.975))
    

    For the industrial data: t = 9.958592, df = 6, p ≈ 0.00005931 and Fisher’s approximate 95% CI ≈ [0.843728, 0.994925]. These are illustrative results under the stated model. The code compares the manual calculation with cor.test(); its ordinary intervals are supplied for Pearson, not automatically for the other two measures.

    The biological example yields Pearson ≈ 0.994995, Spearman ≈ 0.997742 and Kendall ≈ 0.984084. It is a constructed series with pronounced association, not an estimate about actual animals. Convergence of t quantiles toward normal quantiles as degrees of freedom grow is a separate fact: it does not justify constructing an interval for ρ as r ± a quantile times the denominator of the t statistic.

    10 · Scatterplots, regression and diagnostics

    old_par <- par(mfrow = c(2, 2))
    plot(conversion ~ temperature, data = vinylation,
         xlab = "Temperature (illustrative units)", ylab = "Conversion (%)", pch = 19)
    fit_temp <- lm(conversion ~ temperature, data = vinylation)
    abline(fit_temp, col = "#8b4513", lwd = 2)
    plot(conversion ~ pressure, data = vinylation,
         xlab = "Pressure (illustrative units)", ylab = "Conversion (%)", pch = 19)
    fit_pressure <- lm(conversion ~ pressure, data = vinylation)
    abline(fit_pressure, col = "#8b4513", lwd = 2)
    plot(fitted(fit_temp), residuals(fit_temp),
         xlab = "Fitted conversion", ylab = "Residual", pch = 19)
    abline(h = 0, lty = 2)
    qqnorm(residuals(fit_temp)); qqline(residuals(fit_temp))
    par(old_par)
    
    # y = x^2: strong dependence, zero sample Pearson on a symmetric grid.
    grid_x <- seq(-2, 2, length.out = 101)
    c(pearson = cor(grid_x, grid_x^2),
      spearman = cor(grid_x, grid_x^2, method = "spearman"))
    

    The formula conversion ~ temperature places conversion on the response side; the model and plot preserve that orientation. Pearson is symmetric in X and Y, whereas regression is not: exchanging the response changes the question and generally the fitted line.

    A simple linear model is Yi = β0 + β1Xi + εi. The intercept is included by default; removing it requires justification and changes identities such as R² = r². More generally, “linear” refers to parameters: lm(y ~ x + I(x^2)) remains linear in its coefficients although it describes a curve.

    OLS: minimize ∑ ei²
    WLS: minimize ∑ wiei²(10)

    Residuals ei are differences between observed and fitted responses. Weighted least squares uses supplied weights; it does not automatically estimate those weights as part of this minimization. When variances are known up to a common factor, inverse-variance weights are commonly used. Integer frequency weights or grouped means require care with within-group variation and degrees of freedom.

    lm() also accepts a response matrix and fits each column; this does not turn weights into independent replicates. Residual inspection, design and substantive knowledge matter more than the mere presence of a straight line drawn over the data.

    [10]

    11 · From magnitudes to categories: contingency tables

    A contingency table organizes counts of units across categories. For a two-arm trial with a binary outcome, use rows for treatment and columns for event status. Each participant contributes to one cell, and follow-up remains comparable.

    Table 1. Hypothetical trial: these counts are not from the historical study
    GroupEventNo eventTotal
    Illustrative aspirin201,9802,000
    Illustrative placebo401,9602,000
    Total603,9404,000

    With this orientation, prop.table(trial, 1) calculates outcome proportions within each arm. By contrast, prop.table(trial, 2) calculates group composition within each outcome. With no margin argument it gives joint proportions. None of these instructions alone calculates a relative risk.

    The observed frequencies Oij are the data. Under independence, expected frequencies follow from the margins:

    Eij = ni+n+jN(11)

    ni+ is row i’s total, n+j is column j’s total, and N is the overall total. The formula applies the marginal outcome proportion to each row. Here H0 implies 30 events and 1,970 non-events per arm. Expected counts can be fractional: they are theoretical averages, not additional participants.

    12 · Chi-square, Yates and Fisher: what is being tested?

    X² = ∑i,j (Oij − Eij)²Eij
    df = (F − 1)(C − 1)(12)

    Squaring prevents positive and negative discrepancies from cancelling; division by Eij scales each discrepancy relative to its expected count. F and C denote the numbers of rows and columns. Under H0 and suitable approximation conditions, X² is compared with a chi-square distribution. This is not a correlation between numerical codes assigned to categories.

    The χ²ν distribution is the distribution of a sum of squared independent standard normal variables. It appears in goodness-of-fit tests, independence tests and, under normality, variance inference. For the table, the statistic has an approximate chi-square distribution; the distribution’s definition does not make every sum of squares exactly chi-square.

    # Hypothetical trial: 2,000 participants per arm, same follow-up.
    # These counts are not results of the historical aspirin trial.
    trial <- matrix(c(20, 1980, 40, 1960), nrow = 2, byrow = TRUE,
      dimnames = list(group = c("Aspirin", "Placebo"),
                      outcome = c("Event", "No_event")))
    addmargins(trial)
    prop.table(trial, margin = 1) # Outcome proportions within each arm.
    prop.table(trial, margin = 2) # Arm composition within each outcome.
    addmargins(prop.table(trial)) # Joint proportions and marginal totals.
    
    # Equivalent representation with aggregated frequencies.
    trial_long <- data.frame(
      group = factor(c("Aspirin", "Aspirin", "Placebo", "Placebo"),
                     levels = c("Aspirin", "Placebo")),
      outcome = factor(c("Event", "No_event", "Event", "No_event"),
                       levels = c("Event", "No_event")),
      freq = c(20, 1980, 40, 1960))
    from_long <- xtabs(freq ~ group + outcome, data = trial_long)
    stopifnot(all(from_long == trial))
    
    expected <- outer(rowSums(trial), colSums(trial)) / sum(trial)
    contributions <- (trial - expected)^2 / expected
    X2 <- sum(contributions)
    df_chi <- (nrow(trial)-1) * (ncol(trial)-1)
    p_chi <- pchisq(X2, df = df_chi, lower.tail = FALSE)
    chi_test <- chisq.test(trial, correct = FALSE)
    expected; contributions
    c(X2 = X2, df = df_chi, p = p_chi)
    stopifnot(isTRUE(all.equal(X2, unname(chi_test$statistic))),
              isTRUE(all.equal(p_chi, chi_test$p.value)))
    
    # Sensitivity comparison; choose the primary method before examining p.
    c(pearson = chi_test$p.value,
      yates = chisq.test(trial, correct = TRUE)$p.value,
      fisher = fisher.test(trial)$p.value)
    fisher.test(trial) # Conditional OR estimate and confidence interval.
    

    The example gives X² ≈ 6.768190, df = 1 and p ≈ 0.009280 without correction. Yates gives p ≈ 0.013455 and two-sided Fisher p ≈ 0.012806. All three reject at 0.05 here. The comparison describes procedural sensitivity; it does not license choosing whichever p-value is convenient after seeing the results.

    R applies Yates by default to 2 × 2 tables. Its modification reduces absolute discrepancies before squaring and can make the test conservative. Small expected counts signal a need to inspect the approximation, rather than a universal instruction to apply Yates. Consider the design, table configuration and exact or simulated alternatives.

    [6][13]

    Fisher constructs a conditional distribution given the margins. Under the null hypothesis OR = 1, the first-cell count A follows a hypergeometric distribution:

    P(A = k | margins) = binom(n1, k) binom(n0, m − k)binom(N, m)(13)

    n1 and n0 are arm sizes; m is the event total and N = n1 + n0. “binom(n,k)” counts ways of selecting k elements from n. The numerator allocates m events across the arms, while the denominator counts all compatible allocations. In this parameterization E[A] = n1m/N and Var(A) = n1(m/N)(1 − m/N)(N − n1)/(N − 1).

    The hypergeometric distribution describes allocations without replacement within a finite total; a binomial assumes independent trials with constant probability. A small sampling fraction can make a binomial approximation useful. Conditioning on margins does not mean that both were fixed by design: a trial’s total event count is usually random. Fisher supplies conditional inference, not the only possible inference.

    [7]

    Large sparse tables may use conditional simulation, documenting the number of replicates and random seed. If observations are paired, such as before-and-after outcomes on the same people, ordinary independence tests fail to respect the design; for paired binary outcomes, consider McNemar’s test.

    13 · Risk, odds and effect size

    Write the table as (a,b) in the first row and (c,d) in the second: treatment events and non-events, followed by control events and non-events. Each measure answers a different question.

    MeasureDefinitionInterpretation
    Riskp₁ = a/(a+b); p₀ = c/(c+d)Event probability during the specified follow-up.
    Oddsp/(1−p)Events relative to non-events.
    Relative riskRR = p₁/p₀Multiplicative comparison of risks.
    Odds ratioOR = (a/b)/(c/d) = ad/(bc)Multiplicative comparison of odds.
    Risk differenceRD = p₁−p₀Absolute change in probability.
    Absolute risk reductionARR = p₀−p₁Absolute decrease for an adverse event.
    Relative risk reductionRRR = 1−RRProportional decrease relative to control risk.
    Number needed to treatNNT = 1/ARR, if ARR > 0People treated per adverse event prevented over the period.

    With the illustrative counts, p1 = 1% and p0 = 2%: 10 versus 20 events per thousand participants. RR = 0.50, OR ≈ 0.494949, ARR = 0.01 and RRR = 50%. The absolute reduction is one percentage point, not fifty points. Estimated NNT is 100 over the assumed follow-up, provided a causal interpretation is justified.

    Multiplying odds by one thousand compares events with one thousand non-events; to express events per thousand participants, multiply risk by one thousand. OR approximates RR when risks in both groups are small, but may differ substantially for common outcomes. The odds ratio can be used in frequentist or Bayesian inference; its definition belongs exclusively to neither framework.

    [8]

    An effect size quantitatively reflects the magnitude of a phenomenon relevant to a question. It may be a correlation, difference or ratio. The same p-value can accompany different magnitudes; a similar magnitude can have very different uncertainty depending on study size and quality. Epistemological relevance and the mathematical properties of a measure should be considered together.

    [4]
    CIRR = exp{ln(RR) ± z · √[1/a − 1/n1 + 1/c − 1/n0]}
    CIOR = exp{ln(OR) ± z · √[1/a + 1/b + 1/c + 1/d]}(14)

    These approximate intervals use the logarithmic scale because positive ratios often have asymmetric distributions. For RD, an unpooled Wald approximation is shown, with SE = √[p1(1−p1)/n1 + p0(1−p0)/n0]. These are transparent teaching methods, not universal solutions for sparse counts or zero cells; appropriate alternatives, such as score or exact methods depending on the measure, are needed in those situations.

    a <- trial["Aspirin", "Event"]; b <- trial["Aspirin", "No_event"]
    c0 <- trial["Placebo", "Event"]; d <- trial["Placebo", "No_event"]
    n1 <- a+b; n0 <- c0+d
    p1 <- a/n1; p0 <- c0/n0
    RR <- p1/p0; OR <- (a*d)/(b*c0)
    RD <- p1-p0; ARR <- p0-p1; RRR <- 1-RR
    
    # Large-sample log intervals: all four counts must be positive here.
    stopifnot(all(trial > 0))
    zcrit <- qnorm(.975)
    se_log_RR <- sqrt(1/a - 1/n1 + 1/c0 - 1/n0)
    se_log_OR <- sqrt(1/a + 1/b + 1/c0 + 1/d)
    ci_RR <- exp(log(RR) + c(-1, 1)*zcrit*se_log_RR)
    ci_OR <- exp(log(OR) + c(-1, 1)*zcrit*se_log_OR)
    se_RD <- sqrt(p1*(1-p1)/n1 + p0*(1-p0)/n0)
    ci_RD <- RD + c(-1, 1)*zcrit*se_RD # Unpooled Wald approximation.
    ci_ARR <- -rev(ci_RD)
    NNT <- if (ARR > 0) 1/ARR else NA_real_
    ci_NNT <- if (all(ci_ARR > 0)) 1/rev(ci_ARR) else c(NA_real_, NA_real_)
    rbind(RR = c(RR, ci_RR), OR = c(OR, ci_OR), RD = c(RD, ci_RD))
    c(ARR = ARR, RRR = RRR, NNT = NNT)
    ci_NNT
    
    Table 2. Uncertainty in the constructed trial; methods specified in the code
    MeasureEstimateApproximate 95% CI
    RR0.500000[0.293372, 0.852161]
    Sample OR0.494949[0.288322, 0.849659]
    RD−0.010000[−0.017527, −0.002473]
    NNT100[57.05, 404.43] before rounding

    The NNT interval inverts endpoints of a positive ARR interval; if that interval crosses zero, inversion passes through infinity and should not be reported as an ordinary finite interval. NNT is commonly rounded upward when communicating whole people. The conditional OR estimate and interval returned by fisher.test() use a different procedure and can differ from the sample OR ad/bc and its log interval.

    14 · What a clinical trial actually adds

    Randomization seeks to make treatment assignment independent of prognostic characteristics; allocation concealment protects recruitment and blinding reduces certain subsequent influences. These are distinct mechanisms. The protocol should define population, outcome, follow-up, comparison and analysis before results are observed.

    Intention-to-treat analysis retains people in their assigned group, directing estimation toward the effect of assignment. It does not remove missing-data or adherence problems. Loss to follow-up, competing events, protocol deviations and multiple outcomes require specific attention. A 2 × 2 table can oversimplify a study with differing follow-up times or censoring.

    [9]

    A favorable relative effect must be read alongside baseline risk, absolute difference, adverse events and the studied population. This example teaches statistical analysis of a hypothetical trial; by itself, it does not establish an individual clinical indication or justify automatic extrapolation from one population to another.

    15 · Reporting results without losing their meaning

    A clear report identifies the question and design; describes variables and units; presents the plot or table; states method, effective sample size and handling of ties or missing data; reports the estimate, interval and p-value when appropriate; and delimits interpretation.

    The strength of a conclusion depends on the correspondence between question, design, measure and inference.

    For the industrial series: “Eight illustrative pairs yielded r = 0.9711, with Fisher’s approximate 95% CI [0.8437, 0.9949]; the classical two-sided test gave p ≈ 0.0000593. This describes positive linear association under the specified model and does not identify a causal effect of temperature.”

    For the constructed trial: “Over an assumed common follow-up, the event occurred in 20/2,000 and 40/2,000 participants; RR = 0.50 with approximate log-scale 95% CI [0.2934, 0.8522], and a risk difference of −1 percentage point.” Absolute magnitude remains necessary even when a p-value is reported.

    When exploring many correlations, distinguish exploratory from confirmatory analysis and consider multiplicity. Do not select the coefficient, test direction or sample solely to obtain significance.

    16 · Reproducibility and references

    Run the R blocks in reading order in a fresh session, using base R and the stats package included with a standard installation. No external files, personal paths or additional packages are required. Object names and code labels remain identical across languages to facilitate comparison.

    # Numerical checks of the transparent examples.
    stopifnot(n == 8L, abs(s_xy - 1000/7) < 1e-10,
              abs(RR - 0.5) < 1e-12, abs(ARR - 0.01) < 1e-12,
              abs(X2 - 6.7681895093) < 1e-8,
              abs(kendall_manual(u, v) - 5/sqrt(30)) < 1e-12)
    sessionInfo()
    

    Numerical checks compare manual formulas with built-in functions. sessionInfo() records version and environment, helping document implementation differences. Printed figures are rounded; calculations retain numerical precision.

    The following bibliography supports further study of the measures and verification of R’s behavior. The original post date is retained as an editorial reference; this revision develops and corrects its content.

    References and documentation

    1. R Core Team. Correlation, Variance and Covariance; cor(), cov(), cov2cor().
    2. R Core Team. Test for Association/Correlation Between Paired Samples; cor.test().
    3. Taylor, J. M. G. (1987). Kendall’s and Spearman’s Correlation Coefficients in the Presence of a Blocking Variable. Biometrics, 43, 409–416.
    4. Kelley, K., & Preacher, K. J. (2012). On effect size. Psychological Methods, 17(2), 137–152. DOI: 10.1037/a0028086.
    5. American Statistical Association (2016). Statement on Statistical Significance and P-Values: six principles.
    6. R Core Team. Pearson’s Chi-squared Test for Count Data; chisq.test().
    7. R Core Team. Fisher’s Exact Test for Count Data; fisher.test().
    8. Dicker, R. C. Analyzing and Interpreting Data. The CDC Field Epidemiology Manual, chapter 8.
    9. Steering Committee of the Physicians’ Health Study Research Group (1989). Final report on the aspirin component of the ongoing Physicians’ Health Study. New England Journal of Medicine, 321, 129–135. DOI: 10.1056/NEJM198907203210301.
    10. R Core Team. Fitting Linear Models; lm().
    11. Pennsylvania State University. STAT 509, Lesson 7: Early Phase Studies; correlation and Fisher transformation.
    12. Pennsylvania State University. STAT 414, Lesson 18: The Correlation Coefficient.
    13. Grizzle, J. E. (1967). Continuity Correction in the χ²-Test for 2 × 2 Tables. The American Statistician, 21(4), 28–32. DOI: 10.2307/2682103.
  • GENERALITIES AND HISTORICAL ORIGINS OF THE CHI-SQUARED DISTRIBUTION

    GENERALITIES AND HISTORICAL ORIGINS OF THE CHI-SQUARED DISTRIBUTION

    Mathematical statistics · History of science

    The Chi-Squared
    Distribution

    Foundations, Geometry, and Historical Origins

    Originally published on September 10, 2021
    Revised and expanded edition · October 29, 2026

    Abstract

    When does a discrepancy between observed and expected frequencies constitute evidence against a hypothesis? Answering this question requires constructing a measure of discrepancy and understanding its behavior under the proposed model. This essay reconstructs that connection, from Pearson’s criterion to quadratic forms in the multivariate normal distribution, ellipsoidal level sets, their transformation into spheres, and the radial integration that yields the chi-squared distribution. It distinguishes exact results from asymptotic approximations, develops the original examples, and provides reproducible R code.

    A difference between what is observed and what is expected does not speak for itself. Its meaning depends on the variability of the process, the constraints on the data, and the sampling model. The chi-squared distribution connects these dimensions: it translates certain quadratic discrepancies into probabilities that we can interpret under explicit assumptions.

    1. Two frequency problems

    Snedecor and Cochran present two situations that capture the problem. A geneticist expects a particular tomato cross to produce red flesh and yellow flesh in a 3:1 ratio. Examining 400 fruits yields 310 red and 90 yellow. If the model were correct, the expected counts would be 300 and 100. Is the difference compatible with sampling fluctuation? [1]

    In another example, 480 men and 420 women are observed among 900 hospitalized cases. Under the hypothesis of equal proportions, 450 cases would be expected in each category. How much weight should we attach to a deviation of thirty cases from the expected count?

    Both problems require separating two operations: measuring discrepancy and calibrating its magnitude probabilistically. A positive number is not inferentially large or small without a reference distribution and degrees of freedom.

    2. Pearson and the historical problem

    Karl Pearson, a foundational figure in mathematical statistics and a communist, formulated a criterion for assessing whether a system of discrepancies could reasonably be attributed to random sampling. The central reference for this essay is his 1900 paper in The London, Edinburgh, and Dublin Philosophical Magazine and Journal of Science, volume 50, pages 157–175. This date refers to the cited publication; a reconstruction of its antecedents must distinguish it from other stages of development. [2]

    The contribution connects a measure of deviation with a probability calculated under a hypothesis. It links the empirical problem, its mathematical representation, and the distribution of the statistic. The historical interest of the argument lies precisely in that transition.

    Pearson’s political characterization is retained in the sense used in the original essay. His scientific contribution and the consistency of all his social positions are separate questions. The following exposition reconstructs the statistical argument; it does not assume that his ideological trajectory was uniform.

    The 1900 text uses notation that is unfamiliar today. We therefore present a modern reconstruction and its connections with determinants, cofactors, and principal axes. The multivariate normal distribution provides the starting point for the geometry; the multinomial model will subsequently bring us back to frequencies.

    3. Constructing a measure of discrepancy

    Let Oi be the observed count and Ei the expected count in category i. With k categories, Pearson’s statistic adds their individual contributions:

    XP2 = ∑i=1k (Oi − Ei)2Ei
    (01)

    Conceptual reading. Subtraction measures disagreement within each category. Squaring prevents positive and negative deviations from canceling and gives greater weight to large discrepancies. Dividing by the expected count weights the deviation according to the scale of the count. Finally, summation combines the individual discrepancies. Each included term requires Ei > 0.

    The statistic is a finite sum, not an infinite series. The lower limit indicates where the sequence of terms begins and the upper limit where it ends. When all observed frequencies match their expected values, the statistic is zero. If at least one differs, it is positive.

    Weighting by expected counts has a more precise justification than simply “accounting for sample size.” In count models, variability depends on the expected frequency. The multinomial structure introduces dependencies and a joint constraint; we will explain why this sum nevertheless acquires an approximate chi-squared law.

    Ei = Npi,   ∑i=1k pi = 1
    (02)

    Conceptual reading. N is the total number of observations and pi the probability of the category under the hypothesis. Multiplying them gives the average count that would arise under repeated sampling. An expected count may be fractional even though every observed count is an integer.

    XP2 = N ∑i=1k (p̂i − pi)2pi,   p̂i = Oi/N
    (03)

    Conceptual reading. Written in terms of proportions, the same formula shows that a fixed relative discrepancy receives more weight as N increases. More data can detect smaller deviations; statistical significance and substantive magnitude are therefore different concepts.

    4. Variables, dimensions, and covariances

    Before introducing matrices, distinguish three concepts. A deviation is the difference between a value and its reference. The standard deviation measures the dispersion of a variable. The standard error of a mean measures the dispersion of that mean across repeated samples.

    SE(X̄) = σ/√N
    (04)

    Conceptual reading. If N observations are independent and have the same finite variance σ², the mean fluctuates less than an individual observation: its standard deviation is σ/√N. Under dependence, this expression must be modified to incorporate covariances. Here N counts observations, not dimensions.

    In the geometric development, d denotes the number of components of a vector, N the sample size, and k the number of categories. A vector with d components lies in ℝd. Its effective degrees of freedom may be smaller when constraints apply.

    Σij = Cov(Xi, Xj),   Σii = σi2
    (05)

    Conceptual reading. Σ, uppercase sigma, is a d × d matrix recording the variability of each component and the covariation between pairs. Its diagonal contains variances. Other entries can be positive, negative, or zero. The symbol Σ is not the summation operator ∑.

    A symmetric matrix for d components contains d variances and d(d−1)/2 distinct off-diagonal covariances. Counting those parameters does not change the dimension of the space containing each observation. Nor does it produce a space of dimension d(d−1).

    Σ = DRD,   D = diag(σ1, …, σd)
    (06)

    Conceptual reading. R is the correlation matrix, and D contains the standard deviations, assumed positive. R describes associations without units; multiplying by D on both sides restores the original scales. This identity distinguishes a formulation using standardized variables from one using variables in their original units.

    5. The quadratic form and the inverse

    Suppose X has a multivariate normal distribution with population mean μ and positive definite population covariance matrix Σ. Its joint density can be written as follows. [3]

    fX(x) = 1(2π)d/2|Σ|1/2 exp[−½(x − μ)⊤Σ−1(x − μ)]
    (07)

    Conceptual reading. The density describes probabilistic concentration around x; integrating it over a region gives that region’s probability. The initial factor normalizes the total probability to one. |Σ| is the determinant, which adjusts the volume scale. The exponential decreases as the quadratic distance from the center increases. This is not a cumulative distribution function.

    Q = (X − μ)⊤Σ−1(X − μ)
    (08)

    Conceptual reading. X−μ expresses displacement from the center. Σ−1 weights that displacement for dispersion and correlations. Transposition, denoted by ⊤, converts the first column vector into a row so that the product returns a scalar. Q is the squared Mahalanobis distance and has no units.

    The exponent −1 denotes a matrix inverse: multiplying Σ by its inverse gives the identity matrix, the operation that leaves every vector unchanged. It does not represent a power of −1, subtraction, or alternating terms. The entries are not inverted separately either.

    d = 1:   Q = (X − μ)2/σ2
    (09)

    Conceptual reading. A deviation of ten units yields Q=25 when the standard deviation is two, and Q=0.25 when it is twenty. The same absolute displacement can be exceptional or ordinary depending on dispersion. In multiple dimensions, we must also adjust for the information shared by correlated variables.

    Q = z12 − 2ρz1z2 + z221 − ρ2,   |ρ| < 1
    (10)

    Conceptual reading. z1 and z2 are deviations divided by their standard deviations; ρ is their correlation. The cross term adjusts for the joint direction of displacement. If ρ is positive, moving in the same direction in both variables is less unusual than moving in opposite directions. If ρ=0, Q reduces to the sum of the two squares. The negative sign in this expansion comes from matrix inversion, not an alternating series.

    6. From historical to matrix notation

    Pearson’s argument combines deviations, scales, and correlations. Its structure is now recognizable as a quadratic form. For standardized variables z, the relevant matrix is R, the correlation matrix; for unstandardized deviations, it is Σ. [2] [4]

    Q = z⊤R−1z = ∑i=1d aiizi2 + 2∑i<j aijzizj,   A = R−1
    (11)

    Conceptual reading. Diagonal terms weight squared components. Cross terms incorporate relationships between components. Since the inverse matrix is symmetric, each pair appears twice in the full sum: aijzizj and ajizjzi. Combining them explains the factor 2. The condition i<j counts each pair once.

    Mij = det(R with row i and column j removed),   Cij = (−1)i+jMij
    (12)

    Conceptual reading. Deleting one row and one column produces a submatrix; its determinant is the minor Mij. The cofactor Cij introduces a positive sign when i+j is even and a negative sign when it is odd. Here an alternation of signs does occur, arising from the determinant’s structure. It must not be confused with the inverse exponent −1.

    (R−1)ij = Cji/det(R)
    (13)

    Conceptual reading. Transposing the cofactor matrix forms the classical adjugate and explains the interchange of indices. Dividing by a nonzero determinant completes the inversion. Minors and cofactors are not defined through elementary row operations, although those operations can help calculate determinants and inverses.

    This translation preserves the algebraic content of the historical exposition while replacing less explicit summation symbols with defined limits. It also distinguishes an observed realization q from the random variable Q: fixing a value of the quadratic form defines a surface; allowing the vector to vary generates a distribution of values.

    7. Ellipsoids, spheres, and topology

    (x − μ)⊤Σ−1(x − μ) = c,   c > 0
    (14)

    Conceptual reading. All points on this surface have the same squared Mahalanobis distance and the same normal density. Replacing equality with ≤ describes the interior together with its boundary. In two dimensions, the boundary is an ellipse; in three, it is an ellipsoidal surface. The bell-shaped density graph is a different object: it adds a further coordinate representing height.

    Principal axes show the natural directions of dispersion. A noncircular ellipse has perpendicular major and minor axes centered at μ. In d dimensions, we choose d orthogonal directions. If some eigenvalues coincide, axes within the corresponding subspace are not unique, but an orthogonal choice is possible.

    Σ = UΛU⊤,   Λ = diag(λ1, …, λd),   U⊤U = I
    (15)

    Conceptual reading. The columns of U are unit eigenvectors defining the principal directions. The positive eigenvalues λj are variances along those directions. At level c, each semiaxis has length √(cλj). The identity matrix I has ones on its diagonal and zeros elsewhere: it represents leaving a vector unchanged.

    Y = Λ−1/2U⊤(X − μ),   Q = Y⊤Y = ∑j=1d Yj2
    (16)

    Conceptual reading. First subtract the center. U⊤ expresses the displacement in principal-axis coordinates. Λ−1/2 divides each coordinate by √λj, giving unit variance. Ellipsoids become spheres. Under normality, the coordinates of Y are independent standard normals: lack of correlation implies independence here because of the normality assumption.

    From ellipsoid to sphereTilted elliptical contours become circles after centering, rotating, and rescaling.Ellipsoidal levelsSpherical levelscenterrotaterescaleCovariance ΣIdentity covariance
    Figure 1. A two-dimensional schematic of whitening. The contours are levels of a quadratic form, not a density graph. The drawing illustrates the procedure; the scales in the two panels are conventional.
    dx = |Σ|1/2 dy
    (17)

    Conceptual reading. The inverse transformation is x=μ+UΛ1/2y. Translation does not change volumes; an orthogonal matrix has a determinant with absolute value one; and the product of the factors √λj is |Σ|1/2. This factor cancels the determinant term in the density normalizer. Probabilities are preserved by jointly transforming the region, density, and volume element.

    8. Radial integration and solid angles

    In whitened coordinates, the density depends only on distance r from the origin. The probability of falling beyond a given radius is obtained by integrating over the entire exterior of a sphere, not over a single surface. Distinguishing radius from squared radius will be decisive.

    r = ‖y‖ = √(y⊤y),   q = r2
    (18)

    Conceptual reading. r measures distance and q measures squared distance. The radius follows a chi distribution; its square follows a chi-squared distribution. We use r as the radial integration variable and q as the variable of the final distribution to keep their densities distinct.

    dy = rd−1 dr dΩ,   ∫Sd−1 dΩ = 2πd/2Γ(d/2)
    (19)

    Conceptual reading. A thin spherical shell has a volume approximately equal to its surface area times its thickness dr. Scaling the radius by a factor r scales its d−1 tangential directions by that factor, producing rd−1. dΩ captures directions on the unit sphere Sd−1. For d=2, the element is r dr dθ; for d=3, it is r² dr dΩ. In d=1 there are two directions, one on each half-line.

    In three dimensions, a solid angle measures the area of a region’s radial projection onto the unit sphere; its unit is the steradian. The whole sphere spans 4π steradians. A face of a cube centered at the origin subtends 2π/3: its six faces divide spatial directions symmetrically. This is the geometric construction illustrated in the original document. In other dimensions, we speak of angular measure on the unit sphere. [6]

    Solid angle of one cube faceRays from the center of a sphere toward a square face delimit an angular region.From a face to its directionsProjection onto the unit sphere6 faces · 4π steradiansOne face: 2π/3origin
    Figure 2. Schematic of radial projection, inspired by the cube construction cited by Weisstein. By symmetry, each face of a cube centered at the origin subtends one sixth of the total solid angle. The lines are schematic and do not represent areas to scale.
    P(Q ≥ q0) = ∫√q₀∞ e−r²/2rd−1 dr∫0∞ e−r²/2rd−1 dr
    (20)

    Conceptual reading. The numerator accumulates mass from the observed radius to infinity; the denominator normalizes by total radial mass. The angular integral and common constants cancel because all directions are included in both cases. This cancellation follows from radial symmetry and the same angular region, not from matching asymptotic behavior of eigenvectors.

    These are volume integrals reduced using polar coordinates. They do not assign positive probability to a single surface of fixed radius: in this continuous model, that surface has probability zero. Probability mass occupies regions with radial thickness.

    q = r2,   dr = dq2√q,   rd−1dr = ½qd/2−1dq
    (21)

    Conceptual reading. Changing the variable also changes the width of each interval. The factor 1/(2√q) adjusts for that change. Multiplying it by rd−1 produces the exponent d/2−1. This “minus one” comes from the Jacobian and the combination of powers; it does not indicate an alternating series either.

    Γ(a) = ∫0∞ ta−1e−t dt,   a > 0
    (22)

    Conceptual reading. Γ is the function that supplies the density normalizer. It extends the factorial: for positive integers m, Γ(m)=(m−1)!. Substituting t=r²/2 in the total radial integral gives 2d/2−1Γ(d/2). The preceding ratio thus becomes a calculable, normalized probability.

    9. The chi-squared law and its properties

    fQ(q) = qd/2−1e−q/22d/2Γ(d/2),   q > 0
    (23)

    Conceptual reading. The power term captures shell geometry and the change of variable; the exponential captures the decline of the normal density with distance. The denominator makes the integral over all positive values equal to one. This is a one-dimensional density, even though it arises from a d-dimensional problem.

    We write Q ∼ χ²d: ∼ means “has distribution,” whereas = states equality between objects or expressions. In this derivation, d is a positive integer because it counts independent normal coordinates. The gamma family defines χ² distributions for any positive real number of degrees of freedom. [7]

    E(Q) = d,   Var(Q) = 2d,   Q ∼ Gamma(shape=d/2, scale=2)
    (24)

    Conceptual reading. Each squared standard normal contributes mean one and variance two. Summing d independent terms adds their means and variances. The gamma equivalence specifies scale two; under the rate parameterization, the rate is 1/2. Confusing rate and scale changes the model.

    The support is [0,∞), although the density formula is stated for q>0. The density can diverge as q approaches zero when the degrees of freedom are less than two, without creating a point mass at zero. For d=2 it is exponential; increasing d makes it less asymmetric. A density can exceed one: it is integrated probability that must lie between zero and one.

    Chi-squared densities with one, two, four, and eight degrees of freedomCurves calculated from the normalized density; the one-degree-of-freedom density diverges as q approaches zero.ν = 1ν = 2ν = 4ν = 80481216Densityq
    Figure 3. Curves calculated from the χ² density. The vertical scale extends to 0.66; the ν=1 curve continues toward infinity as q approaches zero. The curves are densities, not cumulative probabilities.
    p = PH₀(Q ≥ qobs) = ∫qobs∞ fQ(q)dq
    (25)

    Conceptual reading. The p-value is the probability, under H₀ and the model assumptions, of a statistic at least as discrepant as the observed one. Including or excluding the endpoint does not change this continuous integral. It is neither the probability that H₀ is true nor the probability that the result is “due to chance” in an absolute sense.

    10. Why it works for counts

    The preceding normal result is exact when its assumptions hold and population μ and Σ are used. Category counts are not exactly normal. Connecting them with χ² requires the multinomial model and a limiting argument.

    (O1, …, Ok) ∼ Multinomial(N; p1, …, pk)
    (26)

    Conceptual reading. Each independent observation belongs to exactly one category, the categories are exhaustive, and their probabilities remain constant across observations. The counts sum to N. Although individual observations are independent, counts in different categories are not: when one increases with the total fixed, less room remains for the others.

    Var(Oi) = Npi(1−pi),   Cov(Oi,Oj) = −Npipj   (i≠j)
    (27)

    Conceptual reading. The fixed total induces negative dependence. This explains why it would be incomplete to justify Pearson’s statistic by assuming that each count has variance exactly equal to its expectation and that all counts are independent. That idea is natural under an independent Poisson model, but the multinomial requires incorporating the constraint on the total.

    ∑i=1k(Oi−Npi) = 0
    (28)

    Conceptual reading. Once k−1 deviations are known, the total determines the remaining one. There are therefore only k−1 free directions, and the joint covariance matrix is singular in the full space. The relevant geometry lies in a subspace of dimension k−1.

    Wi = Oi−Npi√(Npi),   Cov(W) = I−ss⊤,   s = (√p1, …, √pk)⊤
    (29)

    Conceptual reading. W denotes the vector of Pearson residuals. Dividing by √(Npi) produces dimensionless residuals. Because the probabilities sum to one, s has unit length. The matrix I−ss⊤ removes direction s and leaves the k−1 directions orthogonal to it unchanged. It is a projection of rank k−1; the covariance identity is exact under the multinomial model.

    With k fixed, fixed positive probabilities, and increasing N, the multinomial central limit theorem approximates these residuals by a normal vector in the free subspace. Choosing an orthonormal basis in that subspace gives k−1 independent standard normal coordinates. The sum of their squares yields the limit:

    XP2 = ∑i=1kWi2   ⟶distribution   χ²k−1
    (30)

    Conceptual reading. The arrow denotes convergence in distribution as N increases, not exact equality for every sample. This is the bridge between normal geometry and counts. Subtracting one reflects the constraint on the total rather than an arbitrary rule.

    ν = k−1−m
    (31)

    Conceptual reading. In regular goodness-of-fit problems, estimating m identifiable parameters can consume m additional directions. This formula requires appropriate estimation and regularity conditions, such as maximum likelihood based on the grouped counts. Mechanically subtracting parameters is insufficient: estimating them from ungrouped data before grouping can alter calibration. Structurally impossible categories also need specific treatment. [9]

    11. The original examples, worked through

    11.1. Tomatoes: a 3:1 ratio

    The hypothesis specifies probabilities of 0.75 and 0.25. The 400 fruits are treated as independent observations under the model; clustering by plant or batch would require reassessing that assumption.

    Table 1. Decomposing discrepancy in the genetic example.
    CategoryOEO − E(O − E)²/E
    Red flesh310300100.333333
    Yellow flesh90100−101.000000
    Total40040001.333333
    XP2 = 100/300 + 100/100 = 4/3 ≈ 1.333333;   ν = 1;   p ≈ 0.248213
    (32)

    Conceptual reading. The absolute deviations are equal, but ten fruits carry more weight in a category with an expected count of one hundred than in one with an expected count of three hundred. With one degree of freedom, the approximate right-tail probability is 0.2482. At α=0.05, the 3:1 ratio is not rejected; this does not prove it is exactly true.

    11.2. Hospital cases: a 1:1 ratio

    Table 2. Decomposing the hospital example under equal proportions.
    CategoryOEO − E(O − E)²/E
    Men480450302
    Women420450−302
    Total90090004
    XP2 = 900/450 + 900/450 = 4;   ν = 1;   p ≈ 0.045500
    (33)

    Conceptual reading. Under equal proportions, both categories contribute equally. The value 4 is not interpreted in isolation: with one degree of freedom, its right-tail probability is approximately 0.0455. At α=0.05, equal proportions are rejected within the model; at α=0.01, they are not. The significance level should be chosen before examining the result.

    Right tail for the hospital exampleArea under a chi-squared density with one degree of freedom from four to infinity; p-value approximately 0.0455.χ² with one degree of freedomTail beyond 4: p ≈ 0.0455412Densityq
    Figure 4. Shading represents the right tail in the hospital example. The plot ends at q=12; the stated probability integrates to infinity. The curve’s height is not the p-value.

    In the second example, the observed proportion of men is 480/900≈0.5333: about 3.33 percentage points above 0.5. This illustrates how a relatively small discrepancy can cross a conventional threshold. Its clinical or social relevance requires a substantive question and suitable data.

    12. Applications, conditions, and limitations

    Goodness of fit

    This compares counts with specified probabilities. Categories must follow a clear definition; when continuous data are grouped, interval choices affect the result. Each interval’s probability must be calculated under the corresponding model. If parameters are estimated, the reference distribution requires justification.

    Independence and homogeneity

    In a table with r rows and c columns, independence states that joint probabilities factor into marginal probabilities. Homogeneity compares categorical distributions across populations or groups. Both can produce the same statistic, although their sampling designs differ.

    Eij = Oi+O+jN,   ν = (r−1)(c−1)
    (34)

    Conceptual reading. Oi+ is the total for row i and O+j the total for column j. Their proportions estimate marginal probabilities under independence. The degrees-of-freedom formula accounts for the relevant constraints in an ordinary full table without structural zeros or other restrictions.

    The count table contains observed values; expected values are calculated under the hypothesis. In R, xtabs() constructs the observed table, while chisq.test(... )$expected provides expected counts. Independence of observations does not follow from the independence that the test evaluates: it is a design assumption.

    V = √XP2N min(r−1,c−1)
    (35)

    Conceptual reading. V summarizes the magnitude of association in a contingency table using the uncorrected Pearson statistic. It indicates neither direction nor causality; its interpretation depends on table structure and may benefit from bias corrections and intervals. In a 2 × 2 table, it equals the absolute value of φ. Residuals and proportions show which cells account for the association.

    Variance of a normal population

    The same distributional family appears in another problem with different assumptions: inference about a normal population variance.

    T = (N−1)S2σ2 ∼ χ²N−1
    (36)

    Conceptual reading. For an independent sample from a normal population, S² uses N−1 in its denominator. Estimating the mean consumes one direction. Under H₀: σ²=σ₀², σ₀² is used in T. Depending on the alternative, the test can use the left tail, the right tail, or both; not every test based on χ² is therefore a right-tailed test. [10]

    Diagnostics before calculation

    • Observational unit: identify what is being counted and whether dependence, pairing, clustering, or repeated measurements are present.
    • Counts: use frequencies rather than percentages without their sample size. Weighted frequencies from complex surveys may require design adjustments such as Rao–Scott corrections.
    • Categories: they must be mutually exclusive and exhaustive under the model; structural zeros are not ordinary sampling zeros.
    • Expected counts: inspect their magnitudes and distribution across cells. “All at least five” is a conservative rule of thumb, not a universal theorem or a condition on observed counts.
    • Sparse data: consider an exact procedure, simulation consistent with the hypothesis, or scientifically justified pooling. Do not pool categories to obtain a desired result.
    • Reporting: accompany the statistic with degrees of freedom, p-value, design, diagnostics, proportions, and a suitable measure of magnitude.

    In 2 × 2 tables, Yates’s continuity correction modifies the approximation. R applies it by default in that case through chisq.test(), but it is not a universal remedy for sparse data. Fisher’s exact test and Monte Carlo methods use specific reference distributions. For tables, simulation in chisq.test() conditions on both margins, requires positive margins, and omits Yates’s correction; it does not automatically reproduce every sampling design. [11]

    13. Reproduction and exploration in R

    The code uses base R. RStudio can provide the working environment, but the functions belong to R. No external data files are required. The numerical outputs stated above are deterministic approximations; simulation experiments illustrate variability and depend on their replicates.

    13.1. Manual calculation and the built-in test

    # Original examples: probabilities fixed by H0.
    # No parameters of the category probabilities have been estimated.
    pearson_fixed <- function(observed, probabilities) {
      stopifnot(is.numeric(observed), is.numeric(probabilities),
                length(observed) == length(probabilities),
                length(observed) >= 2L,
                all(is.finite(observed)), all(observed >= 0),
                all(observed == floor(observed)), sum(observed) > 0,
                all(is.finite(probabilities)), all(probabilities > 0),
                abs(sum(probabilities) - 1) < 1e-10)
      expected <- sum(observed) * probabilities
      contributions <- (observed - expected)^2 / expected
      statistic <- sum(contributions)
      df <- length(observed) - 1L
      # Direct upper tail avoids subtracting a probability near 1 from 1.
      p_value <- pchisq(statistic, df = df, lower.tail = FALSE)
      automatic <- chisq.test(observed, p = probabilities)
      stopifnot(isTRUE(all.equal(statistic,
                                unname(automatic$statistic))),
                isTRUE(all.equal(p_value, automatic$p.value)))
      list(table = data.frame(observed, expected, contributions),
           X2 = statistic, df = df, p = p_value,
           test = automatic)
    }
    tomatoes <- pearson_fixed(c(red = 310, yellow = 90), c(0.75, 0.25))
    hospital <- pearson_fixed(c(men = 480, women = 420), c(0.5, 0.5))
    tomatoes$table
    c(X2 = tomatoes$X2, df = tomatoes$df, p = tomatoes$p)
    # X2 = 1.333333333; df = 1; p = 0.248213079
    hospital$table
    c(X2 = hospital$X2, df = hospital$df, p = hospital$p)
    # X2 = 4; df = 1; p = 0.045500264
    
    # Exact binomial alternatives: these are not Pearson approximations.
    binom.test(310, 400, p = 0.75)
    binom.test(480, 900, p = 0.5)

    pchisq() returns cumulative probabilities; lower.tail = FALSE requests the upper tail. Given a vector of counts and probabilities, chisq.test() performs a goodness-of-fit test. The correct argument concerns 2 × 2 tables and does not change these vector-based tests. The checks compare manual summation with the built-in function.

    13.2. An illustrative contingency table

    The following table is an added example constructed to demonstrate the procedure; it is not part of the original data and does not represent an empirical study.

    tab <- matrix(c(40, 20, 30, 50), nrow = 2, byrow = TRUE,
                  dimnames = list(group = c("A", "B"),
                                  response = c("Yes", "No")))
    test <- chisq.test(tab, correct = FALSE)
    test
    test$observed
    test$expected
    test$residuals  # (O - E) / sqrt(E)
    test$stdres     # Adjust for the variance of each residual.
    
    X2_manual <- sum((tab - test$expected)^2 / test$expected)
    df_manual <- (nrow(tab) - 1) * (ncol(tab) - 1)
    p_manual <- pchisq(X2_manual, df = df_manual, lower.tail = FALSE)
    V <- sqrt(X2_manual /
              (sum(tab) * min(nrow(tab) - 1, ncol(tab) - 1)))
    c(X2 = X2_manual, df = df_manual, p = p_manual, V = V)
    stopifnot(isTRUE(all.equal(p_manual, test$p.value)))
    
    # Compare procedures: explicitly report which one is used.
    chisq.test(tab, correct = TRUE)  # Yates, only for 2 x 2 tables.
    fisher.test(tab)                # Fisher's exact test.
    set.seed(20261029)
    chisq.test(tab, simulate.p.value = TRUE, B = 99999)

    With B=99,999 replicates, the smallest attainable simulated p-value is 1/(B+1)=0.00001. This resolution is not precision: the estimate retains Monte Carlo error. Standardized residuals help locate discrepancies, but assessing many cells requires considering multiplicity and dependence. [11]

    13.3. From the normal distribution to χ²: checking the geometry

    set.seed(20261029)
    B <- 50000L
    d <- 3L
    Sigma <- matrix(c(4, 1, 0.5,
                      1, 2, 0.2,
                      0.5, 0.2, 1), nrow = d, byrow = TRUE)
    # chol returns upper-triangular C with t(C) %*% C = Sigma.
    C <- chol(Sigma)
    Z <- matrix(rnorm(B * d), nrow = B, ncol = d)
    X <- Z %*% C  # Each row has mean zero and covariance Sigma.
    Q <- rowSums((X %*% solve(Sigma)) * X)
    Q_standard <- rowSums(Z^2)
    stopifnot(max(abs(Q - Q_standard)) < 1e-8)
    c(empirical_mean = mean(Q), theoretical_mean = d,
      empirical_variance = var(Q), theoretical_variance = 2 * d)
    hist(Q, breaks = 70, probability = TRUE,
         col = "#f5f0e8", border = "#d4c8b0",
         main = "Normal quadratic form and chi-squared law",
         xlab = "q")
    curve(dchisq(x, df = d), add = TRUE, col = "#8b4513", lwd = 2)
    # solve(Sigma) makes the inverse explicit for teaching purposes.
    # For large problems, prefer factorizations and linear solves.

    The identity between the two calculations of Q holds to numerical precision. By contrast, empirical means and variances only approximate their theoretical values because the simulation has finitely many replicates.

    13.4. From counts to the asymptotic limit

    set.seed(20261029)
    B <- 30000L
    prob <- c(0.2, 0.3, 0.5)
    df <- length(prob) - 1L
    threshold <- qchisq(0.95, df = df)
    explore <- function(N) {
      O <- rmultinom(B, size = N, prob = prob)  # One sample per column.
      E <- N * prob
      residuals <- sweep(O, 1, E, "-")
      contributions <- sweep(residuals^2, 1, E, "/")
      X2 <- colSums(contributions)
      c(N = N, minimum_expected = min(E),
        mean = mean(X2), rejection_005 = mean(X2 > threshold),
        percentile_95 = unname(quantile(X2, 0.95)))
    }
    t(vapply(c(20L, 100L, 1000L), explore, numeric(5)))
    qchisq(0.95, df = df)
    # The mean of X2 is k - 1 even at finite N under this model.
    # That does not make the chi-squared distribution exact.
    # The percentile and rejection rate examine the approximation.
    
    # Density, CDF, quantile, and random generation are distinct operations:
    dchisq(4, df = 1)                       # Density height.
    pchisq(4, df = 1, lower.tail = FALSE)  # Tail probability.
    qchisq(0.95, df = 1)                    # 95th-percentile threshold.
    rchisq(5, df = 1)                       # Five simulated values.

    Simulation evaluates the procedure under a particular model; it does not guarantee validity for other designs. An approximation can improve with N while still exhibiting Monte Carlo fluctuation. The discreteness of counts also persists in a finite sample.

    14. Synthesis and glossary

    Discrepancy becomes interpretable evidence when its scale, constraints, and calibrating distribution are made explicit.

    The journey began with observed and expected frequencies. The multivariate normal distribution represented discrepancy through a quadratic form with ellipsoidal levels. Centering, rotating, and rescaling produced standard normal coordinates; integrating over radial shells and squaring the radius yielded the χ² law. The multinomial model brought the argument back to counts and explained the asymptotic character of Pearson’s test.

    This connection does not turn every quadratic deviation into a chi-squared variable, every geometric relationship into probabilistic equivalence, or every significant result into a causal conclusion. Its strength lies in showing how assumptions enable the transition between observation, mathematical structure, and inference.

    Table 3. Notation and concepts to consult while reading.
    Symbol or conceptMeaning in this essay
    NSample size or total count.
    dDimension of the nondegenerate normal vector.
    kNumber of categories in a goodness-of-fit test.
    νDegrees of freedom of the reference distribution.
    Σ / ∑Covariance matrix / summation operator.
    Σ⁻¹Matrix inverse, existing under nonsingularity.
    R / WCorrelation matrix / vector of Pearson residuals.
    Q / qRandom quadratic variable / a value of that variable.
    X²PPearson’s statistic for counts.
    χ²νFamily of distributions indexed by degrees of freedom.
    r / q=r²Radius / squared radius.
    DensityConcentration whose integral over a region gives probability.
    HomoscedasticityConstancy or equality of variances within a model.
    α / p-valueNominal level of the procedure / tail probability under the hypothesis.
    DiffeomorphismA smooth bijection with a smooth inverse.

    15. References and the original paper

    The original references are retained as part of the intellectual development. Added sources document the modern formulation and applications. The revised mathematical exposition is an explanatory reconstruction, not a verbatim transcription of the 1900 paper. The linked original essay is in Spanish; this English edition presents the revised argument in full.

    1. Snedecor, G. W., and Cochran, W. G. (1967). Statistical Methods, 6th ed. Iowa State University Press. See the introductory examples on pp. 20–21 cited in the original paper.
    2. Pearson, K. (1900). On the criterion that a given system of deviations from the probable in the case of a correlated system of variables is such that it can be reasonably supposed to have arisen from random sampling. Philosophical Magazine, series 5, 50(302), 157–175. DOI and publisher’s record.
    3. Penn State, STAT 505. Multivariate Normal Distribution. Multivariate normality, Mahalanobis distance, and ellipsoidal contours. Teaching materials.
    4. Boyd, S. (2007). Symmetric matrices, quadratic forms, matrix norm, and SVD. EE263, Stanford University. Teaching reference cited in the original. 2007–2008 course archive. See also Lall, S., Symmetric matrices and quadratic forms, EE263 notes.
    5. Gómez Julián, J. M. (2021; originally published under the name Isadore Nabi). Hacia una interpretación dialéctica-materialista de la topología general: génesis histórica-teórica de la topología desde la geometría y la teoría de conjuntos [Toward a dialectical-materialist interpretation of general topology: its historical and theoretical genesis from geometry and set theory]. The author’s essay, in Spanish. It contextualizes reflection on structural equivalences; probabilistic conditions are justified in the present text.
    6. Weisstein, E. W. Solid Angle. MathWorld, Wolfram Research. Consulted for the original essay in 2021. Definition and cube example.
    7. R Core Team. The (non-central) Chi-Squared Distribution, stats package documentation. Density, probabilities, quantiles, and simulation.
    8. Kolmogorov, A. N. (1933). Grundbegriffe der Wahrscheinlichkeitsrechnung [Foundations of the Theory of Probability]. Springer. Historical reference added to contextualize the axiomatization of probability.
    9. NIST/SEMATECH. e-Handbook of Statistical Methods, §1.3.5.15, Chi-Square Goodness-of-Fit Test. Grouping, estimation, and degrees of freedom.
    10. NIST/SEMATECH. e-Handbook of Statistical Methods, §1.3.5.8, Chi-Square Test for the Variance. Testing a population variance.
    11. R Core Team. Pearson’s Chi-squared Test for Count Data, stats package documentation. chisq.test(), residuals, and Monte Carlo.
    12. Wikipedia. Elipse [Ellipse]. Geometric source cited in the original and consulted there in 2021. Reference entry, in Spanish. Retained for traceability; the algebraic reconstruction relies on the teaching sources listed above.

    The essay archive

    The original version preserves the 2021 formulation and presentation in Spanish. This English page develops its examples, clarifies its notation, and expands the geometric and statistical foundations.

    Read the original Spanish PDF ↗

    JOSÉ MAURICIO GÓMEZ JULIÁN · Marxist Philosophy of Science
    History, geometry, and statistical inference