“Is that to say we are against Free Trade? No, we are for Free Trade, because by Free Trade all economical laws, with their most astounding contradictions, will act upon a larger scale, upon the territory of the whole earth; and because from the uniting of all these contradictions in a single group, where they will stand face to face, will result the struggle which will itself eventuate in the emancipation of the proletariat.”
Karl Heinrich Marx · Marx-Engels Collected Works, Vol. VI, p. 290
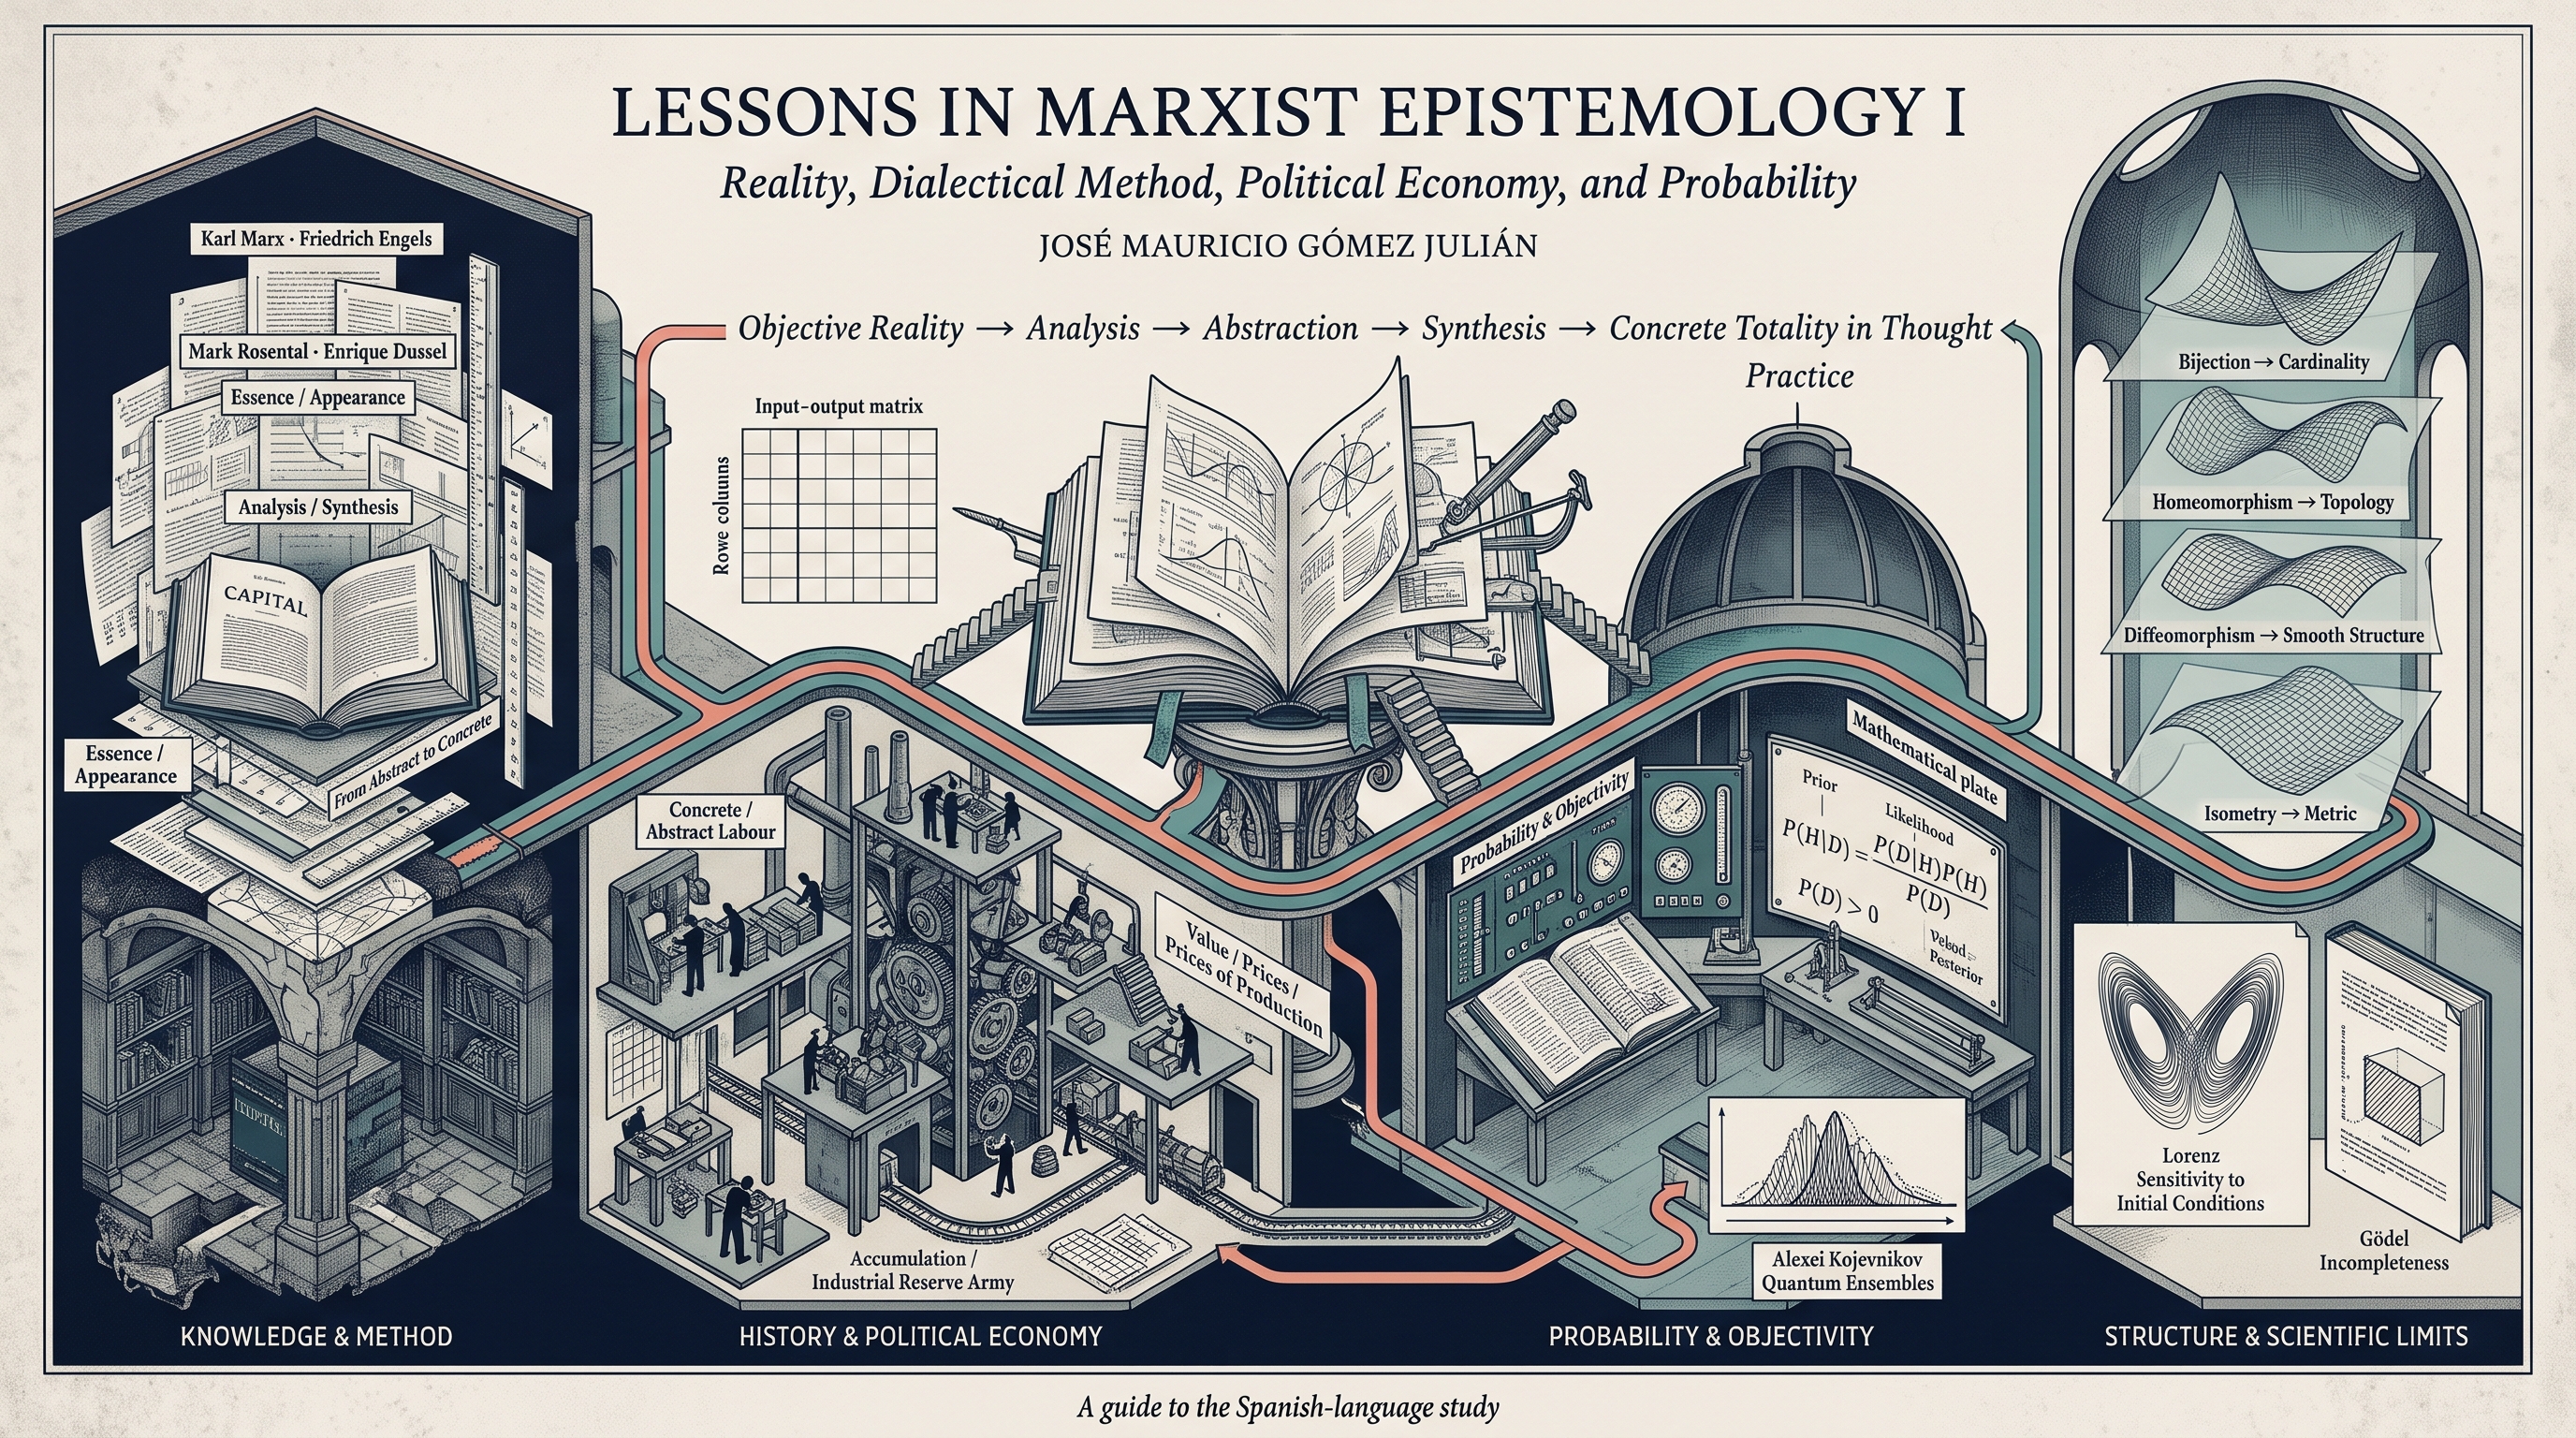
Understanding a changing reality also requires investigating how the categories through which we know it develop. How are experience, abstraction, and practice related? What distinguishes an immediate appearance from the relations that produce it? How can a theory reconstruct a historical process while keeping the order of its concepts grounded in that process? These questions guide the Lessons in Marxist Epistemology.
This first instalment develops a thematic study of Mark Rosental’s Los problemas de la dialéctica en «El Capital» de Marx—the problems of dialectics in Marx’s Capital. It brings that work into conversation with Marx and Engels, the philosophical dictionaries of Rosental and Iudin and of Frolov, and contributions by Hegel, Lenin, and Enrique Dussel. Selected passages are accompanied by my own comments, which extend, clarify, or discuss their arguments. [1]
The preface places this investigation within a five-part project: three studies of works by Rosental; a fourth on Eli de Gortari’s Introducción a la lógica dialéctica; and a fifth combining Richard Levins’s A Response to Orzack and Sober: Formal Analysis and the Fluidity of Science with Alkistis Elliott-Graves’s The Value of Imprecise Prediction. A subsequent synthesis is intended to preserve the traceability of the sources and make their relationship to my own elaborations identifiable.
Political economy is central because Capital allows us to study method at work: categories taking shape, relations being reconstructed, and observable forms being explained. From that starting point, the inquiry reaches into logic, the philosophy of mathematics, statistics, and physics. Their connection lies in the problem of how thought can grasp a reality that exists and changes independently of any particular account of it.
II · OrientationFidelity to method and the openness of knowledge
I use Marxist to identify an orientation that seeks to preserve and develop the logical, epistemological, and methodological foundations elaborated by Marx, Engels, and other classical authors in this tradition. Its content is assessed through the actual articulation of those foundations in research. A label or a declared political allegiance cannot settle that question by itself.
“This methodological fidelity does not mean restricting knowledge to the works of the classics or considering all their conclusions infallible.”
José Mauricio Gómez Julián · Revised manuscript, preface · Translated from Spanish
The continuity at issue allows particular results to be corrected, later knowledge to be incorporated, and research to extend to new objects. The expression classical Marxism identifies the methodological and conceptual core whose definition is itself part of the investigation. Establishing that core requires examining arguments and research practices; it cannot be inferred from a linguistic suffix.
For English readers, this also explains the choice of Marxist in the title. The intended scope includes Marx, Engels, other classical Marxists, and the further development of their research orientation. The methodological commitment is made explicit in the argument rather than delegated to the distinction between the words Marxian and Marxist.
This approach informs my critical use of Soviet sources. Their epistemological contributions do not entail agreement with every historical or political position they hold. In the preface, I explicitly distinguish my interpretation of the Soviet experience from interpretations advanced by authors whose work nevertheless provides important resources for this investigation.
· · ·
III · The object and its knowledgeEssence, appearance, and practice
The materialist starting point is the objective existence of the processes we investigate. Knowledge develops through our relations with them: perception, instruments, concepts, experiments, and social practices. Abstraction participates in this relationship by identifying determinations that immediate observation does not deliver in an already organized form.
The distinction between essence and appearance addresses this work of explanation. Observable forms manifest relations that need to be reconstructed. Investigating value, price, wages, or profit therefore requires explaining the mediations between their determinations and the ways in which they appear. Describing a visible outcome leaves open the question of the process that produces it.
In this vocabulary, a determination is a feature or relation through which the object acquires a specific content. A mediation is a connection or process needed to explain how determinations are related. These terms direct attention to the structure and development of the object under investigation.
Practice plays both a constitutive and a testing role: it helps form the problems, develop the instruments, and assess knowledge. Scientific activity has a material and social history. Its objectivity requires investigating how theoretical constructions relate to the actual processes they concern.
The study consequently connects sensory knowledge and abstract thought, theory and practice, relative and absolute truth. The possibility of deepening an explanation presupposes that knowledge can develop and be corrected while reality retains its objective existence. Necessity and chance are also examined within this framework, as questions about processes and their interrelations.
IV · Operations of methodReconstructing a concrete totality
Analysis distinguishes determinations within a reality initially apprehended in a confused way. Synthesis investigates their articulation and reconstructs a totality of relations. Their unity matters: dividing an object into parts and listing those parts does not yet explain how that object exists or changes.
The movement from the abstract to the concrete acquires its meaning here. Concrete reality is the starting point of knowledge; the concrete as reconstructed in thought is a result of its elaboration. Abstractions allow us to return to the object with a richer understanding of its determinations. Dussel develops this distinction in his reading of the method of the Grundrisse. [2][4]
Consider the categories of political economy. A society may first be apprehended as a complex whole. Analysis distinguishes relations such as commodity exchange, money, wage labour, and capital. Their reconstruction must explain how those relations are connected and under what historical conditions they exist. In this sense, concrete refers to a unity of multiple determinations, not simply to whatever can be immediately seen or touched.
Induction and deduction are examined as related operations within this investigation. The same applies to intuition and the logical assessment of arguments. Each procedure has functions and conditions of application that must be specified in relation to the problem. The discussion of mathematical intuition, constructive approaches, and the finite and infinite extends this methodological inquiry.
The distinction between inquiry and exposition is equally important. The order that makes a process intelligible need not reproduce every chronological stage of its development or every step taken to investigate it. Exposition must justify its mediations and retain its grounding in historical reality. [3]
V · Political economyCategories expressing historical relations
Economic categories acquire their content within determinate social relations. Commodity, money, capital, wage labour, and surplus value must be studied through their conditions of existence and transformation. The investigation asks how these forms are historically produced and how they are connected within social reproduction.
The study addresses the origins of capitalism, the formation of the industrial reserve army, and the transformation of values into prices of production. It also examines contradictions between concrete and abstract labour, use value and exchange value, and social production and private appropriation. The emergence of the general equivalent of commodities is considered within this development.
Several distinctions that organize the argument
Concrete labour concerns the specific useful activity that produces a particular use value; abstract labour concerns labour in the social determination relevant to commodity value. The distinction connects the useful character of production with the social relations through which products are equated.
Values and prices of production enter an inquiry into surplus-value production, its distribution among capitals, and the formation of an average rate of profit. The industrial reserve army is investigated as part of capitalist accumulation and its changing demand for labour. These questions require the historical and conceptual development provided in the full study.
Competition and technological change are particularly important in my comments on Rosental. Their examination connects productivity, surplus value, redistribution, and profitability. Production and circulation are treated as moments of a totality, preserving the distinction between the coexistence of different phases across a system and the succession of phases traversed by a particular commodity.
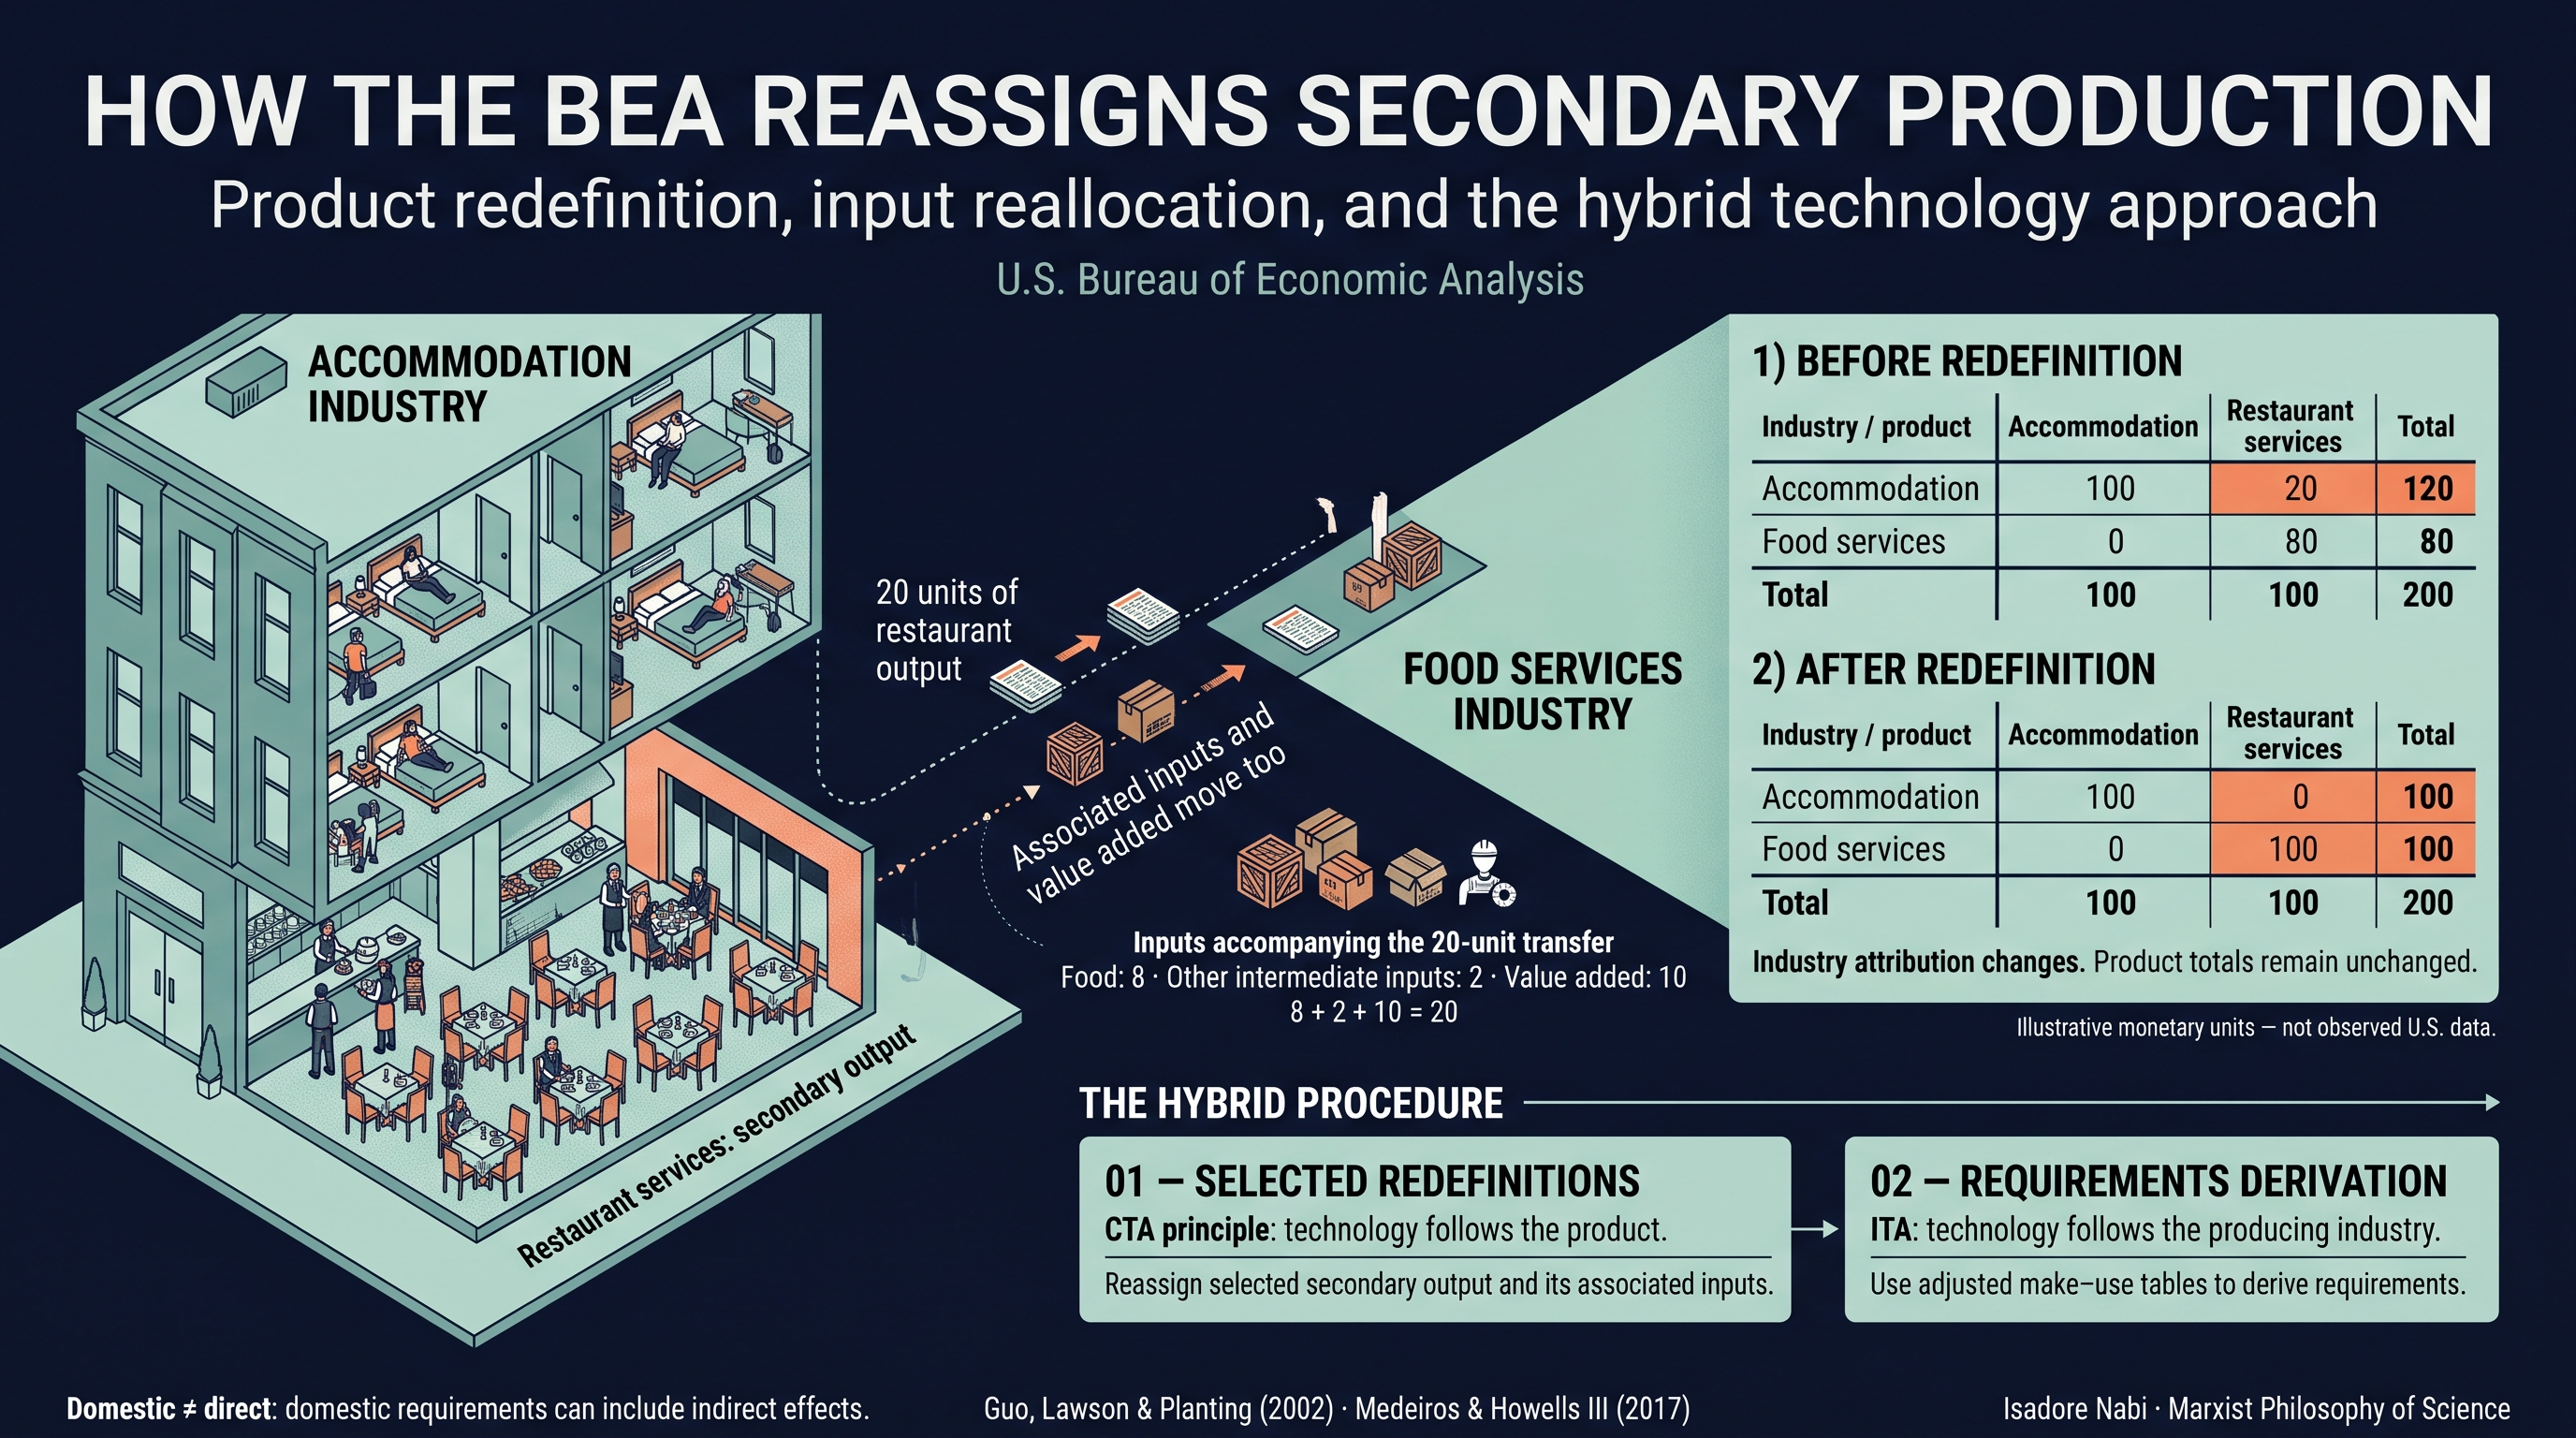
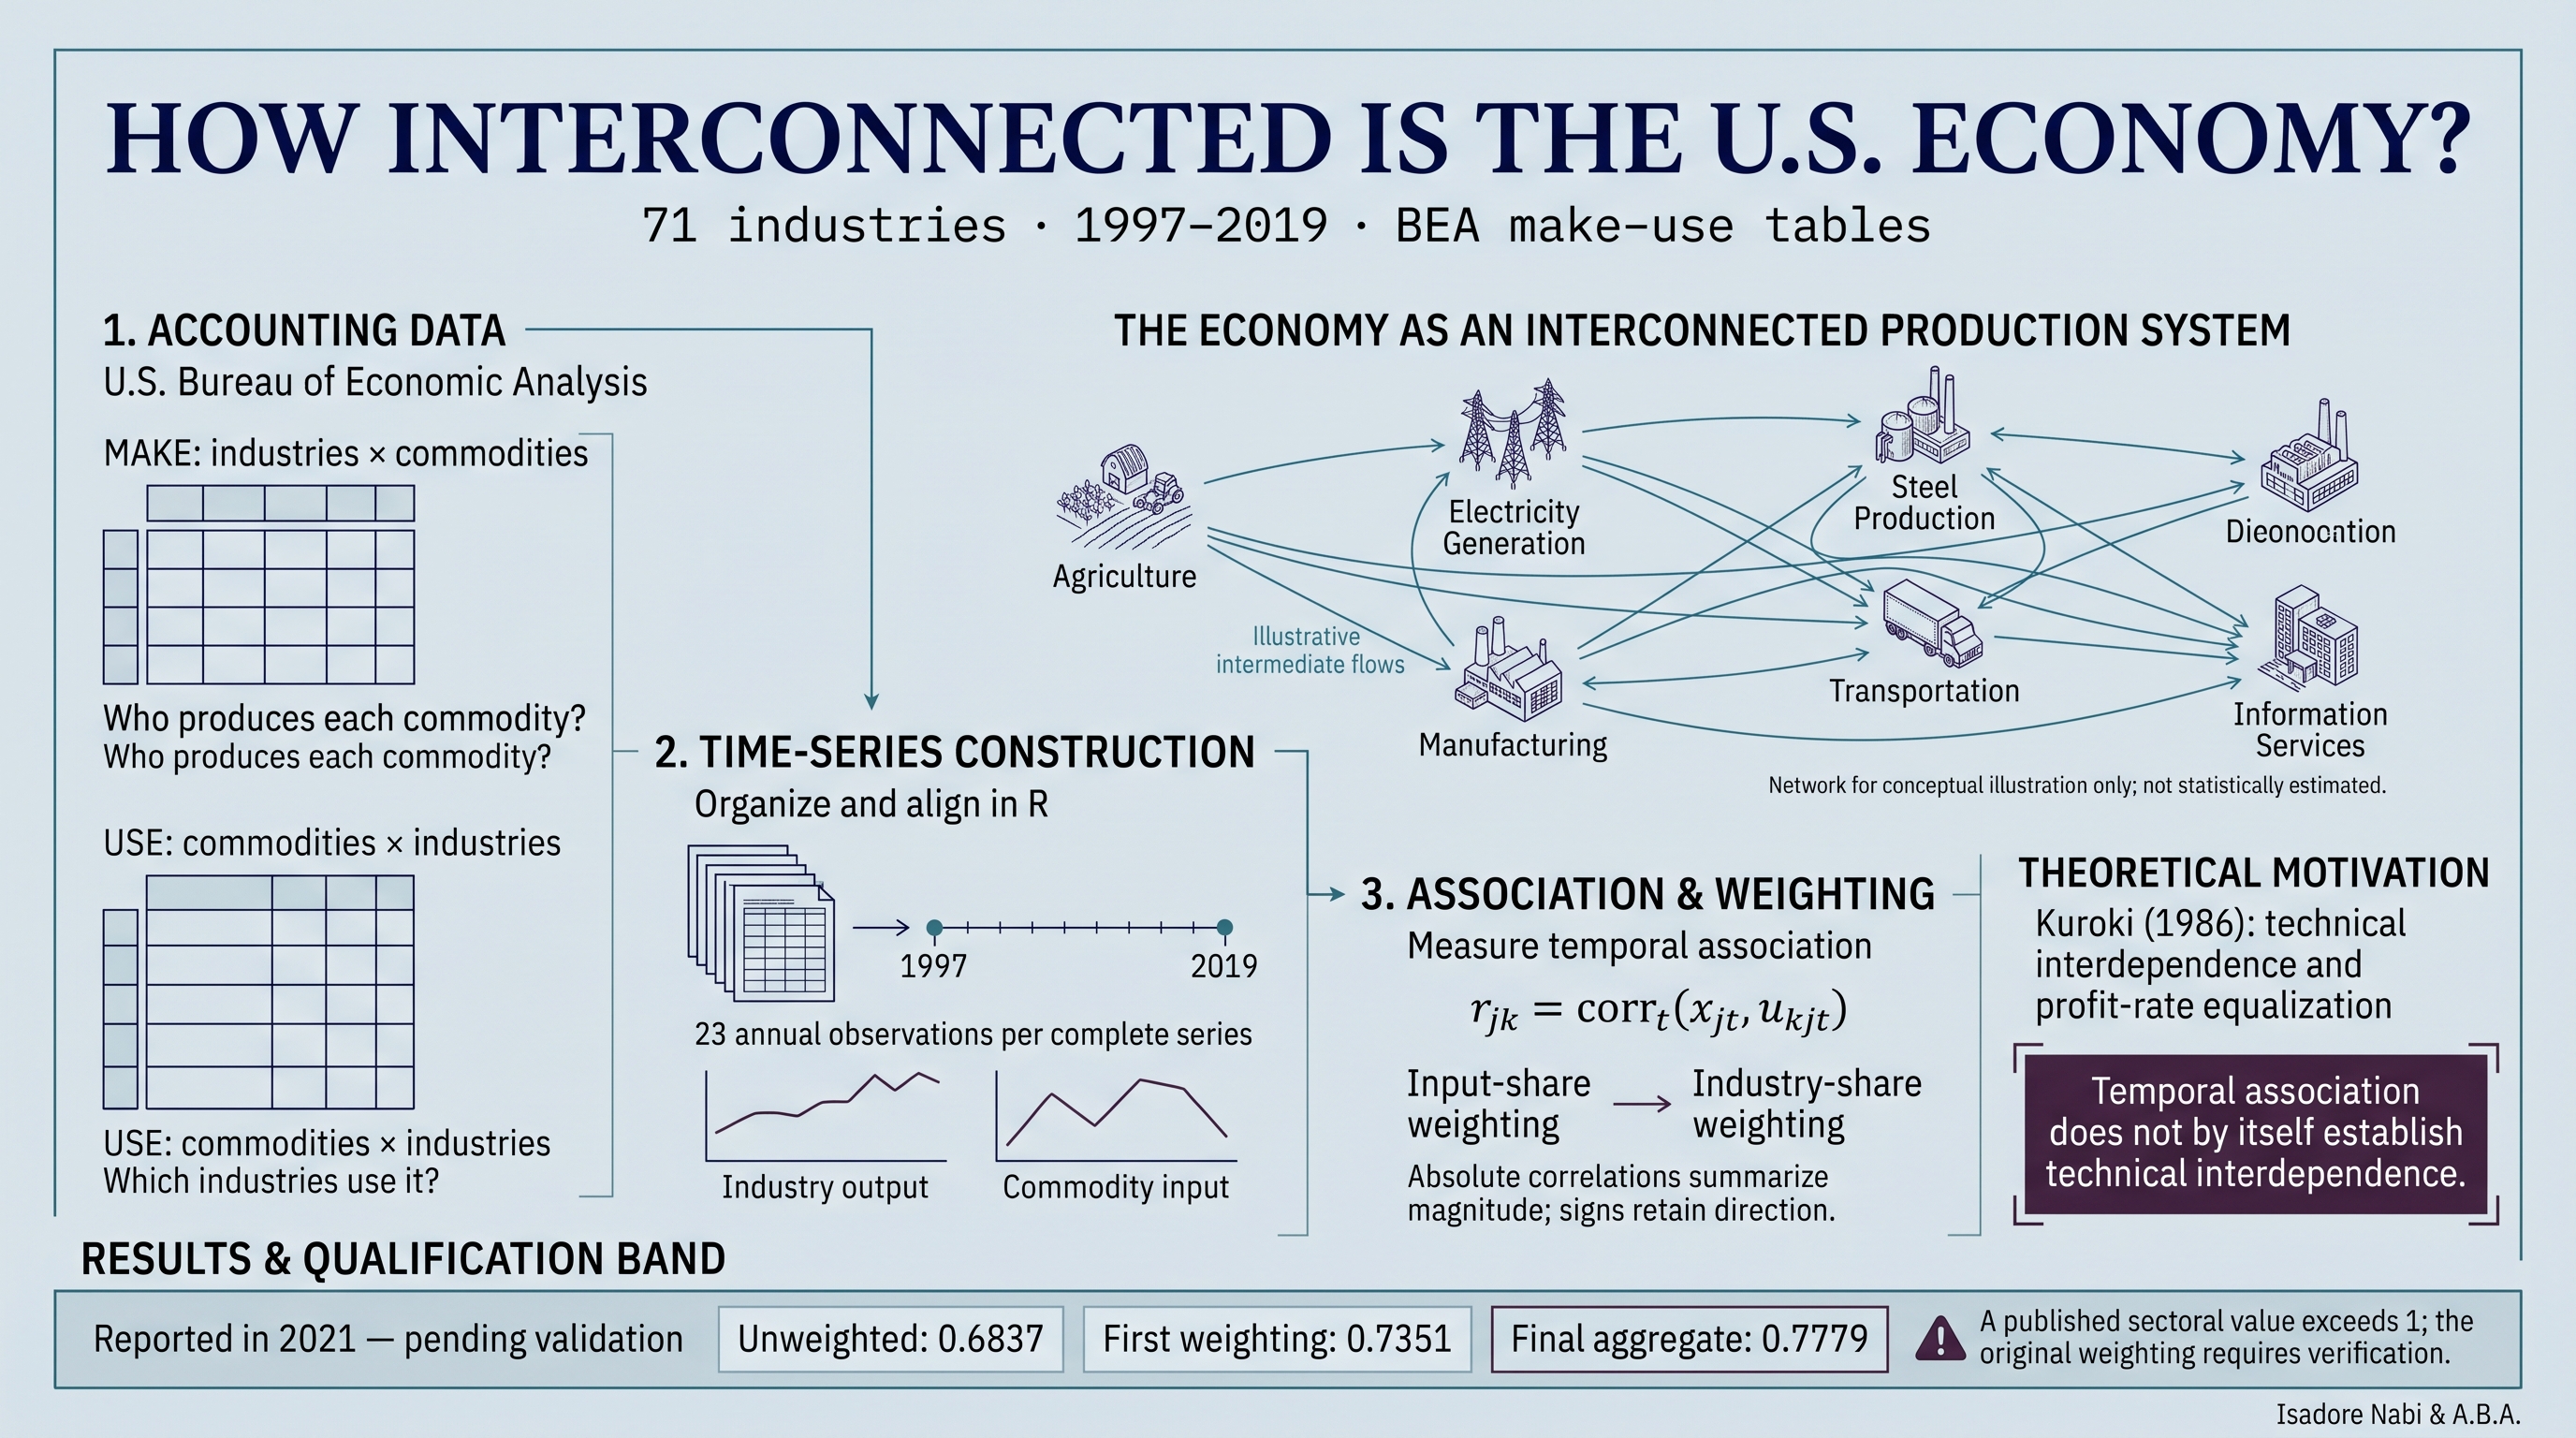
From this concern I propose studying input–output matrices dynamically, using comparable sequences of tables and models to investigate technical transformations and sectoral relations. The comparison with the tables in Volume III of Capital concerns the representation of productive relations and aggregate magnitudes. The choice of simulations or statistical procedures requires prior examination of the problem and the data.
The critique of political economy thus remains connected to history, quantitative investigation, and social action. In the preface, the pursuit of truth is explicitly articulated with concern for human suffering, justice, ethics, and morality.
· · ·
VI · Philosophy of statisticsProbability, evidence, and objectivity
The discussion of total probability, inverse probability, and objective Bayesianism belongs to a broader question: how can we investigate processes when available knowledge is partial and relationships are expressed probabilistically? The document connects this problem with Bernoulli, Laplace, Kolmogorov, and controversies between statistical schools.
Probability calculus and the interpretation of its components need to be distinguished. Axiomatization provides a framework of mathematical relations; research must establish what its objects represent, what information enters a model, and how its application is justified. Philosophical disagreements can affect the choice of procedures and the meaning of inferences even when identities of the calculus are shared. [5][8]
P(D) > 0 · Conditionals defined in the model
Bayes’s theorem in hypothesis-and-data notation, written for events. The posterior combines the model of the evidence with prior information. See DeGroot and Schervish, cited in the study.
Here, P(H) is the prior probability assigned to the hypothesis, P(D|H) represents the probability of the data under that hypothesis, and P(H|D) is the posterior probability conditional on the data and the model. The denominator P(D) normalizes the result. When the hypotheses form a discrete, mutually exclusive, exhaustive set, it can be obtained by summing the data probabilities under those hypotheses, weighted by their prior probabilities.
The likelihood treats the probability or density of the observed data as a function of the parameter or hypothesis, keeping the data fixed. It must be distinguished both from a probability distribution over the parameter and from the reliability of an empirical record. For continuous observations, Bayesian updating is expressed with the corresponding densities and appropriate normalization. [9]
Jon Williamson’s objective Bayesianism provides a framework for discussing constraints on rational degrees of belief and their relationship to evidence. My elaboration seeks to connect these questions with a materialist interpretation of objectivity and chance. The calculus, its inferential uses, and this philosophical interpretation are studied together while retaining their respective functions. [6]
The connection with quantum mechanics
Instruments, complementarity, measurement, and causality extend the investigation into physics. The study draws on Alexei Kojevnikov’s historical reconstruction of probability, Marxism, and ensemble interpretations of quantum mechanics. From that starting point, I examine objectivity, interpretation, and determinism within the document’s broader materialist argument. [7]
This discussion distinguishes mathematical descriptions, experimental arrangements, and philosophical interpretations. Its place in the study is to investigate how probabilistic representations relate to the objective processes and instruments involved in scientific knowledge.
VII · Structure and knowledgeInvariants, levels, and formal limits
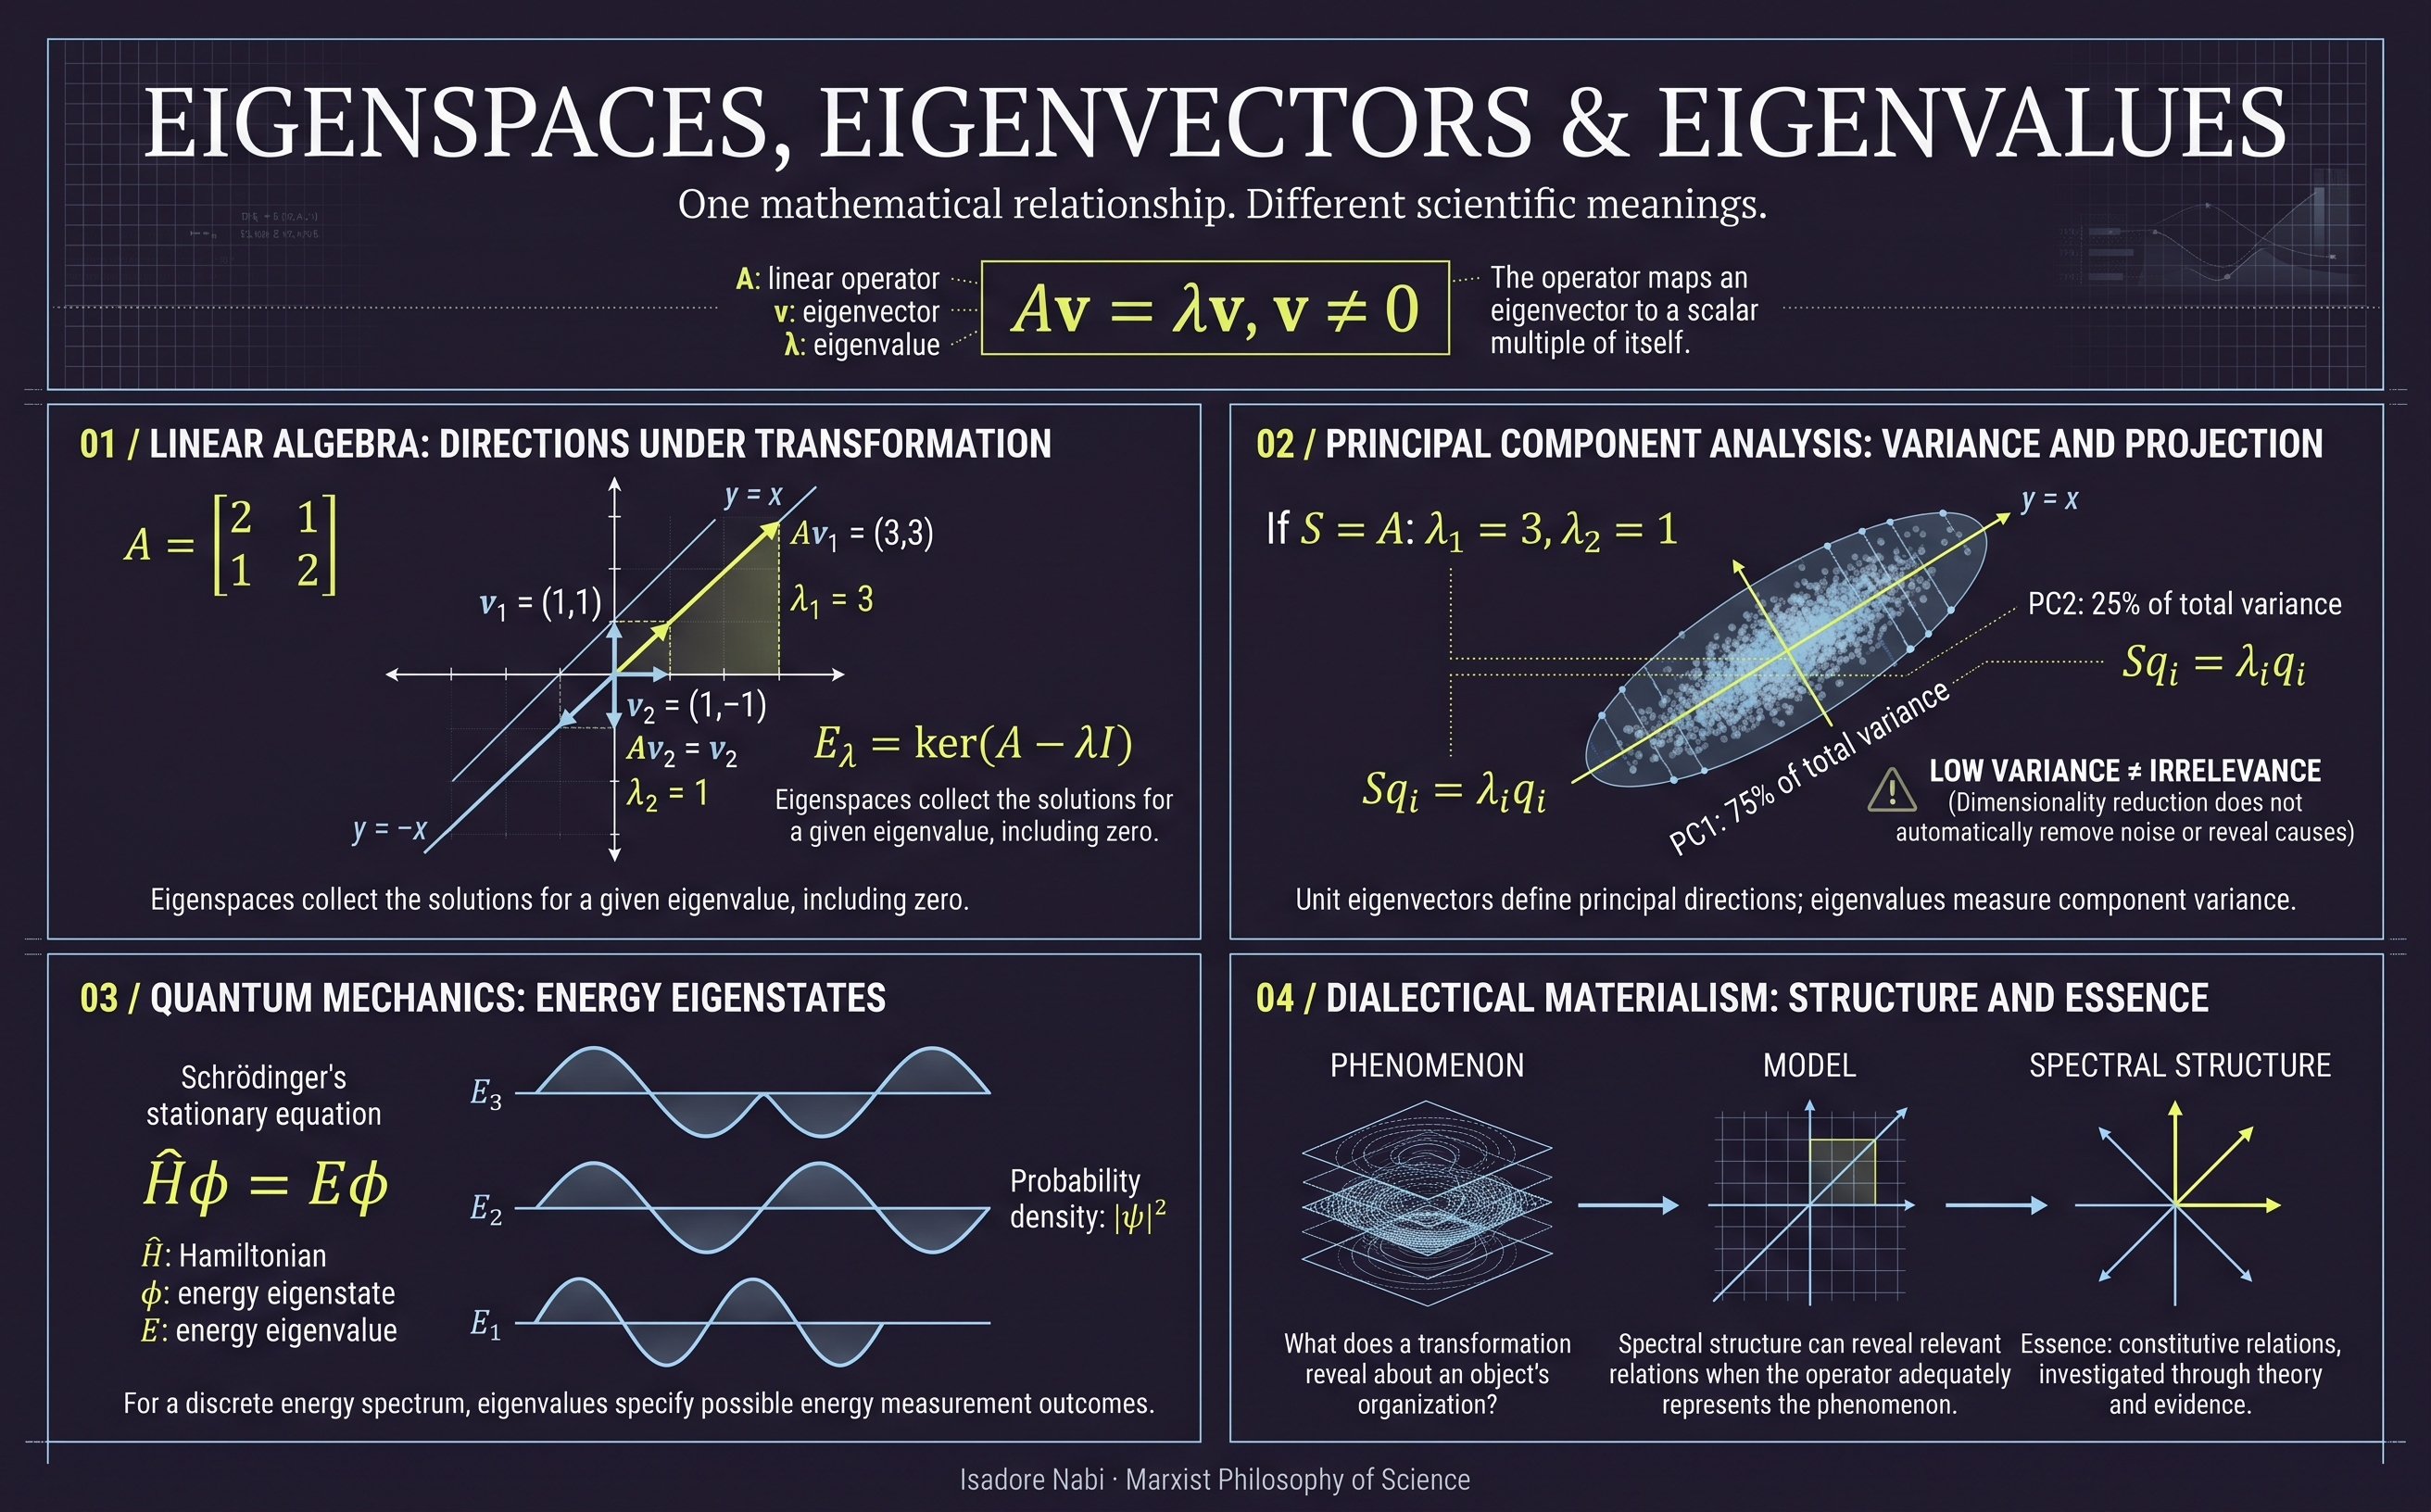
The elaboration on essence incorporates a formalization through mathematical structures and classes of transformations. The question is which relations are preserved, and which can change, while retaining the identity under consideration. Specifying that choice helps define the level at which a system is investigated.
Structural level
Transformation
What is preserved
Set-theoretic
Bijection
Cardinality
Topological
Homeomorphism
Continuity structure; connectedness and compactness
Differentiable
Diffeomorphism
Smooth structure
Riemannian
Isometry
Metric tensor
Essence is investigated through constitutive relations and invariants. The organization of admissible transformations also allows an operational essence to be studied.
An invariant is a property preserved under the specified class of transformations. A topological comparison and a metric comparison therefore ask different questions of the same object. The choice of structure and transformations determines which kind of identity is being considered.
This articulation situates topology within a broader account. Set-theoretic, topological, differentiable, metric, and operational determinations permit distinct investigations. Their relevance must be established through the structure of the object and the transformations under which its identity is examined.
Prediction, decision, and proof
The revised manuscript also distinguishes limits of prediction, undecidability, and incompleteness. Lorenz’s 1963 work exhibits sensitivity to initial conditions in a deterministic model. The spectral-gap undecidability results rule out a universal decision algorithm for the families covered by their constructions. Gödel’s incompleteness results establish limits on proof in formal theories satisfying their conditions of application.
For the first incompleteness theorem, these conditions include consistency, effective axiomatizability, and sufficient arithmetic strength. The relevant conclusion concerns sentences that cannot be proved or refuted within the theory. The existence of a mathematical model, the possibility of predicting its behaviour, the availability of a universal decision procedure, and the reach of its proofs are consequently distinct questions.
I integrate these limitations with the history of our intellectual instruments and the objective existence of processes. Knowledge of essential relations and solutions to particular problems remain possible. Research must specify the reach of its resources and the mediations through which its results refer to reality.
VIII · Reading guideRoutes through the complete study
The full document supports a systematic reading or an approach organized around a particular problem. Its chapters are interconnected: economic applications return to the methodological categories, and discussions of probability reopen questions of objectivity, intuition, formalization, and practice. The Spanish headings below help locate these discussions in the document.
Preface · PrólogoPurpose and standpointThe project of the lessons, the selection of sources, the meaning of “Marxist,” and the connection between knowledge, ethics, and social commitment.
Chapters II and IIIFoundations and operations of knowledgeChapter II, Fundamentación objetiva (material) de la gnoseología marxista, develops essence and appearance, necessity and chance, instruments, analysis and synthesis, induction and deduction, intuition, truth, and practice. Chapter III, Las limitaciones de la lógica formal, continues the examination of formal logic.
Chapters IV–VIIHistory and the reconstruction of the concreteThe origins of classical political economy and capitalism, the industrial reserve army, and the relationship between abstraction and historical inquiry. Chapter VII is Lo abstracto y lo concreto como etapas gnoseológicas de la investigación científica.
Chapter VIIILaws, probability, and the interpretation of physicsLas leyes históricas que rigen el movimiento en general leads into general and specific laws, total and inverse probability, Bayes’s theorem, objective Bayesianism, and interpretations of quantum mechanics.
Chapters IX–XIIValue, prices, and contradictionsChapter IX examines the proceso de transformación de valores en precios de producción. The following chapters address socialism and communism as historical necessities, concrete and abstract labour, use value and exchange value, and the general equivalent of commodities.
Chapter XIII and notesSources and clarificationsThe references identify the works studied. Notes accompany the arguments, source discussions, and my own elaborations throughout the document.
Spanish terms used in the study · A short reading aid
Spanish
English and context
Gnoseología
Theory of knowledge; rendered here as epistemology.
Esencia / fenómeno
Essence / phenomenon or appearance: essential relations and their forms of manifestation.
Necesidad / casualidad
Necessity / chance. Casualidad means chance; causalidad means causality.
Lo abstracto / lo concreto
The abstract / the concrete, examined as moments in the reconstruction of a determinate totality.
Trabajo concreto / trabajo abstracto
Concrete labour / abstract labour.
Plusvalía / precios de producción
Surplus value / prices of production.
Ejército industrial de reserva
Industrial reserve army, investigated in relation to capitalist accumulation.
Probabilidad inversa
Inverse probability, within the discussion of inference and objective Bayesianism.
IX · SourcesBibliography of the study
The first nine references identify the sources cited in this presentation. The expandable section preserves the remaining bibliography of the manuscript. Titles and publication details retain the language of the source entries so readers can identify the editions used; English descriptions in the body are reading aids.
Rosental, M. (1961). Los problemas de la dialéctica en "EL CAPITAL" de Marx. Montevideo: Ediciones Pueblos Unidos.
Dussel, E. (1991). 2. El método dialéctico de lo abstracto a lo concreto (20, 41-33, 14; 21,3-31,38) :(Cuaderno M. desde la página 14 del manuscrito, terminado a mediados de septiembre de 1857). En E. Dussel, La producción teórica de Marx: un comentario a los grundrisse (págs. 48-63). México D.F.: Siglo XXI Editores. Obtenido de Consult source
Marx, K. (1989). Contribución a la Crítica de la Economía Política. Moscú: Editorial Progreso.
Marx, K. (2007). Elementos Fundamentales para la Crítica de la Economía Política (Grundrisse) 1857-1858 (Vol. I). (J. Aricó, M. Murmis, P. Scaron, Edits., & P. Scaron, Trad.) México, D.F.: Siglo XXI Editores.
Kolmogórov, A. (1956). Foundations of the Theory of Probability (Segunda Edición ed.). New York: Chelsea Publishing Company.
Williamson, J. (2010). In Defence of Objective Bayesianism. Oxford: Oxford University Press.
Kojevnikov, A. (19 de Junio de 2019). PROBABILITY, MARXISM, AND QUANTUM ENSEMBLES. Obtenido de The University of British Columbia: Consult source
Efron, B. (1978). Controversies in the Foundations of Statistics. The American Mathematical Monthly, 231-246.
DeGroot, M., & Schervish, M. (2012). Probability and Statistics. Boston: Pearson Education.
Remaining bibliography · 38 references
Bayes, T. (23 de Diciembre de 1763). An Essay towards solving a Problem in the Doctrine of Chances. Philosophical Transactions of the Royal Society of London, 370-418.
Bernoulli, J. (2006). The Art of Conjecturing (Together to a Friend on Sets in Court Tennis). Maryland: John Hopkins University Press.
Eremenko, A. (30 de Abril de 2020). Stack Exchange, History of Sciences and Mathematics. Obtenido de What was Kolmogorov’s point of view in the philosophy of mathematics?: Consult source
Feller, W. (1968). An Introduction to Probability Theory and Its Applications (Tercera ed., Vol. I). New York: John Wiley & Sons, Inc.
Filosofía en español. (9 de Febrero de 2018). Diccionario filosófico abreviado. Obtenido de URSS: Consult source
Fröhlich, N. (2012). Labour values, prices of production and the missing equalisation tendency of profit rates: evidence from the German economy. Cambridge Journal of Economics, 37(5), 1107-1126.
Frolov, I. T. (1984). Diccionario de filosofía. (O. Razinkov, Trad.) Moscú: Editorial Progreso. Obtenido de Consult source
Fundación del Español Urgente. (23 de Marzo de 2021). Formación de gentilicios extranjeros. Obtenido de Lista de topónimos y gentilicios: Consult source
Fundación del Español Urgente. (23 de Marzo de 2021). -ista (sufijo). Obtenido de Sufijos: Consult source
Gigerenzer, G. (2004). Mindless Statistics. The Journal of Socio-Economics, 587-606.
Greene, W. H. (2012). Econometric Analysis (International Edition). Essex: Pearson Education Limited.
Guerrero Jiménez, D. (2018). TRABAJO IMPRODUCTIVO, CRECIMIENTO Y TERCIARIZACIÓN (30 AÑOS DESPUÉS DE MARX Y KEYNES). International Journal of Political Economy, 1-16. Obtenido de Consult source
Haldane, J. B. (1945). Science and Everyday Life. Allahabad,: Kitab Mahal Publishers.
Hegel, F. (1968). Ciencia de la Lógica. Buenos Aires: Solar / Hachette.
Johnsen, J. (17 de Enero de 2019). What is the difference between positivism and empiricism? Obtenido de Quora: Consult source
Kohan, N., & Brito, P. (1 de Febrero de 2009). Marxismo para principiantes. Obtenido de nodo50: Consult source
Laplace, P.-S. (2015). Ensayo Filosófico Sobre Probabilidades. Ciudad de México: Biblioteca Digital del Instituto Latinoamericano de Comunicación Educativa. Obtenido de Consult source
Lenin, V. (1974). Cuadernos Filosóficos. Madrid: Editorial Ayuso.
Loughborough University. (21 de Febrero de 2008). Total Probability and Bayes’ Theorem. Obtenido de The theorem of total probability: Consult source
Maibaum, G. (1988). Teoría de Probabilidades y Estadística Matemática. (M. Á. Pérez, Trad.) La Habana, Cuba: Editorial Pueblo y Educación.
Marx, K. (1894). Capital. A Critique of Political Economy (Vol. III). New York: International Publishers.
Marx, K. (2010). El Capital (Vol. I). México, D.F.: Fondo de Cultura Económica.
Marx, K., & Engels, F. (1987). Karl Marx and Friedrich Engels Collected Works (Vol. XLII). Moscú: Progress Publishers.
Mittelhammer, R. (2013). Mathematical Statistics for Economics and Business (Segunda ed.). New York: Springer.
Nabi, I. (2020). Algunas Reflexiones Sobre la Distribución Binomial Negativa II (Un Análisis Teórico y Aplicado). Documento Inédito. Obtenido de Consult source
Nabi, I. (21 de Marzo de 2021). Sobre el papel y la viabilidad de la violencia en la lucha social de las mujeres en particular y en las luchas sociales en general. Obtenido de El Blog de Isadore Nabi: Consult source
Nabi, I., & B.A., A. (1 de Abril de 2021). UNA METODOLOGÍA EMPÍRICA PARA LA DETERMINACIÓN DE LA MAGNITUD DE LAS INTERRELACIONES SECTORIALES DENTRO DE LA MATRIZ INSUMO-PRODUCTO DESDE LOS CUADROS DE PRODUCCIÓN Y USOS PARA EL CASO DE ESTADOS UNIDOS 1997-2019. Obtenido de El Blog de Isadore Nabi: Consult source
North Carolina State University. (27 de Septiembre de 2020). People – Department of History . Obtenido de Dr Edith D Sylla: Consult source
Perezgonzalez, J. (3 de Marzo de 2015). Fisher, Neyman-Pearson or NHST? A tutorial for teaching data testing. (L. Roberts, Ed.) Frontiers in Psychology, 6(223), 1-11. doi:10.3389/fpsyg.2015.00223
Poisson, S.-D. (2013). Researches into the Probabilities of Judgments in Criminal and Civil Cases. (O. Sheynin, Ed.) Berlin: arXiv. Obtenido de Consult source
Rosental, M. M., & Iudin, P. F. (1971). DICCIONARIO FILOSÓFICO. San Salvador: Tecolut.
Rosental, M., & Iudin, P. (1959). Diccionario filosófico abreviado. Montevideo: Ediciones Pueblos Unidos.
Russell, K. (29 de Enero de 2014). University of Manitoba. Obtenido de Hypothesis testing: Consult source
StackExchange Philosophy. (15 de Junio de 2015). How empiricism and positivism is distinguished? What's their differences? Obtenido de Philosophy: Consult source
TECH2 NEWS STAFF. (28 de Noviembre de 2019). SCIENTISTS MAY HAVE DISCOVERED A FIFTH FUNDAMENTAL 'FORCE OF NATURE,' THEY’RE CALLING IT X17. Obtenido de TECH2: Consult source
Wikipedia. (27 de Septiembre de 2020). Population Genetics. Obtenido de J. B. S. Haldane: Consult source
Wikipedia. (23 de Septiembre de 2020). Statistics. Obtenido de Inverse Probability: Consult source
Wikipedia. (13 de Marzo de 2021). Relación de incertidumbre. Obtenido de Mecánica cuántica: Consult source
Research document · Spanish
Continue with the complete lessons
The full study develops the sources, arguments, economic applications, and research notes introduced here.
Original public edition in Spanish · 2021 · 289 pages. This English presentation draws on the revised manuscript. The linked PDF retains the title and content of the original edition.
José Mauricio Gómez Julián Marxist Philosophy of Science · Theory of knowledge
Today's edition is dominated by escalating geopolitical tensions, with multiple reports highlighting military preparations and political conflicts across the globe, while also featuring significant developments in technology infrastructure and artificial intelligence policies.
· · ·
Economy & Politics
RT News: Argentina helped Bolsonaro flee Brazil
RT News · single source
Argentina confirmed that it helped Brazilian Senator Flavio Bolsonaro flee the country after his election loss to President Lula. Bolsonaro entered Argentina with valid documentation before boarding a private jet to Ecuador and later traveling to Florida. The operation reportedly involved coordination with US Secretary of State Marco Rubio.
“with valid travel documentation and without any legal impediment to entering the country”
Irina: German Chancellor warns of imperialist and revisionist wars in Japan
Irina · single source
German Chancellor Friedrich Merz, addressing Japan—a former Nazi ally—warned of the dangers of imperialist and revisionist wars. Merz thanked Japan for its constant and substantial support for Ukraine and announced that Germany will strengthen military cooperation with Japan.
Negocios.com: US and Israel prepare massive attack against Iran: leaders in the crosshairs
Negocios.com · single source
The United States and Israel are reportedly preparing a massive attack against Iran, with its leaders being targeted as primary objectives. Military preparations are underway, though specific details of the operation remain undisclosed.
Bloomberg Politics: New Zealand Opportunity Party's Wong Vies With Winston Peters for Kingmaker Role
Bloomberg Politics · single source
Qiulae Wong's rapid political ascent could position her as the power broker for New Zealand's next government, challenging Winston Peters for the kingmaker role in potential coalition negotiations.
Granma: Equipment failure puts 48 dialysis patients at risk due to external blockade
Granma · single source
A broken component has impaired a dialysis service, leaving 48 patients at risk. The external blockade has prevented purchasing the necessary replacement part. This situation highlights the critical impact of the blockade on healthcare services.
RT en Español: U.S. and Israel prepare week of intense bombings against Iran
RT en Español · single source
According to RT en Español, the U.S. and Israel are planning a significant military operation against Iran. The strike could occur shortly after the U.S. midterm elections. This development signals heightened tensions in the region.
Rollo Chino: Danyang-Kunshan Bridge is world's longest at 164.8 kilometers
Rollo Chino · single source
The Danyang-Kunshan Bridge in Jiangsu province holds the Guinness World Record as the longest bridge in the world at 164.8 kilometers. Part of the Beijing-Shanghai high-speed rail line, it was completed in 2010 at an estimated cost of $8.5-10 billion.
r/ClaudeCode: Developer creates system for AI to call users directly without phone numbers
r/ClaudeCode · single source
A developer created 'agentring', an MCP server with Android app that allows Claude Code to call users directly when needed. The system uses VoIP technology without requiring phone numbers or Twilio services. It enables voice AI to alert users about critical issues like security vulnerabilities.
“backfill them with the legacy plan and run it again”
r/ClaudeAI: Ex-OpenAI researcher claims Anthropic is downplaying security breach
r/ClaudeAI · single source
An ex-OpenAI researcher alleges that Anthropic is underplaying a recent security breach where an attacker gained full administrator access to Slack, potentially exposing all research secrets. The incident raises concerns about data protection at AI companies.
r/ClaudeAI: User reports growing dependence on Claude Code for business operations
r/ClaudeAI · single source
A user describes how Claude Code has become integral to their business operations, performing tasks continuously and sometimes feeling more in control than the human operator. The rapid integration highlights both the potential and risks of AI in business environments.
Generación IA: EU allows training AI with personal data without consent
Generación IA · single source
EU governments approved a change to GDPR interpretation allowing companies to use European citizens' personal data for AI training without individual consent, potentially considering it a 'legitimate interest'. The measure still requires European Parliament approval.
Marxist Philosophy of Science Mathematics · Computing · Method
Sets and Combinatorics in R
A computational exploration of Cartesian products, power sets, permutations, and combinations
JOSÉ MAURICIO GÓMEZ JULIÁN
Originally published on April 4, 2021 · Revised and expanded edition
Abstract
This article brings together definitions, counting arguments, and reproducible experiments in R to study constructions on finite sets. It examines Cartesian products and power sets, ordered selections with and without repetition, combinations, and multiset permutations. The discussion distinguishes mathematical objects from their computational representations, explains the role of order and multiplicity, clarifies the relationship between power sets and σ-algebras, and separates the calculation of cardinalities from exhaustive enumeration.
Counting means establishing which differences make two objects distinct. Before running a function or applying a formula, we need to decide whether order matters, whether an element may appear more than once, and whether we are constructing subsets, sequences, or collections with multiplicities. R provides an accessible laboratory for making these decisions visible and comparing their consequences with results we can inspect.
The empirical approach proposed here consists of constructing finite examples, comparing representations, and checking identities in specific cases. This activity has exploratory and educational value and helps check implementations. An identity that holds for every size also requires a general argument: running a program for several values does not, by itself, turn an observed regularity into a theorem.
1. Mathematical objects and their representation in R
A set is a collection whose defining feature is membership: writing an element more than once or changing the order of presentation does not create a different set. Thus, {a, b, a} and {b, a} represent the same set. By contrast, the sequences (a, b) and (b, a) are different, and the sequence (a, a) has two positions even though it uses only one distinct symbol.
A multiset records how often each type of element appears, without distinguishing positions. For example, {a, a, b} and {a, b, a} describe the same multiset, which differs from {a, b, b}. Here, braces are used informally to display multiplicities; the context will make clear whether they denote an ordinary set or a multiset.
Which distinctions each object preserves
Object
Order
Multiplicity
Example
Set
Does not distinguish positions
Membership only
{a, b} = {b, a, a}
Sequence or tuple
Distinguishes positions
May include repetitions
(a, b) ≠ (b, a)
Multiset
Does not distinguish positions
Preserves quantities
{a, a, b} ≠ {a, b, b}
An R vector has positions and can contain repeated values; it is therefore not automatically a mathematical set. In this article, we represent sets using finite numeric vectors or character vectors with no duplicates or missing values. The function unique() removes repeated values; setequal() compares membership while ignoring order and duplicates, whereas identical() compares R objects strictly. R’s set operations are documented in [1].
R code
x <- c("a", "b", "a")
A <- unique(x)
A
# [1] "a" "b"
setequal(x, c("b", "a"))
# [1] TRUE
identical(c("a", "b"), c("b", "a"))
# [1] FALSE
1.1. Basic operations and verifiable laws
The union A ∪ B contains elements belonging to at least one of the sets; the intersection A ∩ B retains their common elements; and the difference A ∖ B retains elements belonging to A but not to B. Taking a complement requires a specified universe Ω: Ac = Ω ∖ A. Without an explicit universe, the phrase “everything that is not in A” does not determine a particular set.
R code
S <- c("a", "b")
T <- c("b", "c")
Omega <- c("a", "b", "c", "d")
union(S, T) # "a" "b" "c"
intersect(S, T) # "b"
setdiff(S, T) # "a"
setdiff(T, S) # "c"
setdiff(Omega, S) # "c" "d"
all(S %in% union(S, T)) # TRUE: S is a subset of S union T
For finite sets, the identity |S ∪ T| = |S| + |T| − |S ∩ T| corrects the double counting of shared elements. De Morgan’s laws describe how complements interact with unions and intersections: (S ∪ T)c = Sc ∩ Tc and (S ∩ T)c = Sc ∪ Tc. These laws follow by examining the membership of an arbitrary element; the script also checks them in this example.
2. Preparing the environment and reading conventions
R is the language and computing environment; RStudio is a development interface for working with R. The code can also be run in the R console or with Rscript. The basic examples use R and its standard packages; additional enumerations use gtools, and rje::powerSet() is retained as an alternative way to construct the power set [7].
R code
# Run once if not already installed:
# install.packages(c("gtools", "rje"))
A <- c("a", "b", "c") # Small, inspectable example
B <- c(1, 2, 3)
reference_set <- 1:10 # Reference numerical example
n <- length(reference_set)
k <- 3 # Selection length, where applicable
Outputs preceded by # are comments indicating expected results, not additional instructions. The following sections contain teaching examples; the complete script assembles the helper functions and checks in executable order. Package names are made explicit with package::function() to identify where each operation comes from.
The visual representations and tables are built from text and accessible HTML. This allows readers to select symbols, zoom in, and consult formulas without relying on screenshots.
3. Cartesian products: constructing pairs and tuples
Given two sets A and B, their Cartesian product A × B is the set of all ordered pairs (a, b) such that a belongs to A and b belongs to B. If both sets are finite, each element of A can be paired with every element of B:
A × B = {(a, b) : a ∈ A, b ∈ B} |A × B| = |A| · |B|
Vertical bars denote cardinality.
A Cartesian product preserves coordinate positions. In general, A × B and B × A are different sets, even though they have the same cardinality. If both factors are the same set, pairs such as (a, a) may occur: sharing the same source set does not require the coordinates to be distinct.
A = {a, b, c}; B = {1, 2, 3}; nine ordered pairs
A / B
1
2
3
a
(a, 1)
(a, 2)
(a, 3)
b
(b, 1)
(b, 2)
(b, 3)
c
(c, 1)
(c, 2)
(c, 3)
In R, expand.grid() produces one row for each combination of coordinates. In the function’s documentation, “combination” refers to a configuration of variable values, not an unordered selection in the combinatorial sense used in later sections. We specify stringsAsFactors = FALSE to keep text as text, and omit auxiliary attributes with KEEP.OUT.ATTRS = FALSE[2].
R code
product <- expand.grid(
A = A, B = B,
KEEP.OUT.ATTRS = FALSE,
stringsAsFactors = FALSE
)
nrow(product)
# [1] 9
product_10 <- expand.grid(
x = reference_set, y = reference_set,
KEEP.OUT.ATTRS = FALSE,
stringsAsFactors = FALSE
)
nrow(product_10)
# [1] 100
For k coordinates chosen from A, we write Ak. If |A| = n, then |Ak| = nk. For k = 0, we adopt A0 = {()}, the set containing the empty tuple. This convention keeps the cardinality equal to 1 even when A is empty.
4. Power sets: all subsets of a set
The power set of A, written 𝒫(A), contains all its subsets, including ∅ and A itself. When constructing a subset, each element of A has two possibilities: it is either included or excluded. For n distinct elements, the multiplication principle gives:
𝒫(A) = {S : S ⊆ A} |𝒫(A)| = 2n
For A = {a, b, c}, the eight subsets can be grouped by size. This arrangement by levels makes the distribution 1, 3, 3, 1 visible; a complete Hasse diagram would also include the covering relations between adjacent levels.
{a, b, c}
{a, b}{a, c}{b, c}
{a}{b}{c}
∅
The power set arranged by cardinality
We can construct it using standard R by enumerating combinations of every size. The code uses indices to prevent combn() from interpreting a numeric vector of length one as a population size.
R code
A <- c("a", "b", "c")
PA <- list(A[0]) # A list that CONTAINS the empty subset
for (k in seq_len(length(A))) {
indices <- utils::combn(seq_along(A), k, simplify = FALSE)
PA <- c(PA, lapply(indices, function(i) A[i]))
}
length(PA)
# [1] 8
# Alternative using the package from the original version:
# PA <- rje::powerSet(A)
# P10 <- rje::powerSet(1:10)
# length(P10) # 1024
4.1. Why the power set is a σ-algebra
A σ-algebra ℱ on a universe Ω is a family of subsets that contains Ω and is closed under complements relative to Ω and under countable unions. These conditions imply that it also contains ∅. The power set 𝒫(Ω) satisfies these conditions because it contains every possible subset of Ω [6].
However, “power set” and “σ-algebra” are not synonyms. On Ω = {a, b, c}, both {∅, Ω} and {∅, {a}, {b, c}, Ω} are σ-algebras; neither equals the eight-element family 𝒫(Ω). The first distinguishes only the impossible event from the certain event; the second distinguishes the block {a} from the block {b, c}.
On a finite universe, every family of subsets is finite. Consequently, checking closure under binary unions, together with the other axioms, establishes closure under countable unions: only finitely many distinct subsets can occur in such a union. The script provides a checker for this finite setting. This procedure cannot be extended to infinite universes without further justification.
4.2. The connection with combinations
The subsets of A are partitioned by size. There is exactly one subset of size zero, n subsets of size one, and, in general, a binomial number of subsets of size k. Therefore:
∑k=0n C(n, k) = 2n
This counts every subset once, including the empty set and the full set.
The correspondence between a subset and its vector of membership indicators also establishes a bijection between 𝒫(A) and {0, 1}n. This is a structural connection with binary sequences, not merely a numerical coincidence.
5. Ordered selections without repetition
We choose k distinct elements from n available elements and assign each one a position. There are n possibilities for the first position, n − 1 for the second, and so on. For 0 ≤ k ≤ n:
P(n, k) = n(n − 1) ··· (n − k + 1) = n!(n − k)!
These constructions are also called variations, arrangements, or partial permutations without repetition, depending on the terminological tradition. When k = n, we obtain full permutations: P(n, n) = n!. If k > n, there are no possible selections without repetition, and for k = 0 there is a unique empty selection.
With A = {a, b, c} and k = 2, we obtain six sequences: (a, b), (a, c), (b, a), (b, c), (c, a), and (c, b). The same pair of symbols can appear in two different orders.
R code
n <- 10
k <- 3
prod(n - seq_len(k) + 1)
# [1] 720
# Small enumeration; requires gtools:
# p2 <- gtools::permutations(3, 2, v = A)
# nrow(p2) # 6
The falling product avoids calculating two large factorials separately, although it can also overflow for large sizes. The general function in the script handles k = 0 first, avoiding misleading descending ranges.
5.1. Summing over different lengths
Counting all nonempty sequences of lengths 1 through n means summing P(n, k), rather than calculating a single permutation count. For n = 10, the total is 9,864,100; including the empty tuple raises it to 9,864,101. Lengths distinguish objects: a sequence with two positions is never the same as a sequence with three.
6. Ordered selections with unrestricted repetition
If a symbol may reappear in every position, there are always n options, and the available set does not shrink. Sequences of length k form the Cartesian product Ak:
R(n, k) = nk
For A = {a, b, c} and k = 2, the nine results are (a, a), (a, b), (a, c), (b, a), (b, b), (b, c), (c, a), (c, b), and (c, c). Compared with the previous section, the pairs containing identical symbols have been added.
R code
n <- 10
k <- 3
n^k
# [1] 1000
# With unrestricted repetition, explicitly enabled:
# r2 <- gtools::permutations(
# 3, 2, v = A, repeats.allowed = TRUE
# )
# nrow(r2) # 9
# No external packages needed for the two-position case:
pairs <- expand.grid(x = A, y = A,
KEEP.OUT.ATTRS = FALSE,
stringsAsFactors = FALSE)
nrow(pairs)
# [1] 9
For n = 10 and k = 10, the count is 10,000,000,000. Here, it is best to calculate the cardinality and stop: exhaustive generation is not a reasonable example for an ordinary computer. The script’s memory safeguard prevents this enumeration.
7. Combinations without repetition: choosing subsets
We now choose k distinct elements without distinguishing order. Every subset of size k gives rise to k! ordered sequences. Dividing the preceding count by that number gives:
C(n, k) = nk = n!k!(n − k)!
Factorial domain: 0 ≤ k ≤ n. By combinatorial convention, C(n, k) = 0 when k > n.
With A = {a, b, c} and k = 2, there are three subsets: {a, b}, {a, c}, and {b, c}. A program’s writing {a, b} in the order of the input vector does not give the subset positions.
R code
choose(10, 3)
# [1] 120
A <- c("a", "b", "c")
indices <- utils::combn(seq_along(A), 2, simplify = FALSE)
subsets <- lapply(indices, function(i) A[i])
length(subsets)
# [1] 3
# Another representation: each column is a combination.
utils::combn(A, 2)
# [,1] [,2] [,3]
# [1,] "a" "a" "b"
# [2,] "b" "c" "c"
choose() calculates cardinalities; combn() generates selections. By default, the latter arranges results in columns, whereas gtools::combinations() arranges them in rows. Confusing these orientations leads to counting the length of a selection instead of the number of selections [3].
For a ten-element set, summing combinations of sizes 1 through 10 gives 1,023 nonempty subsets. Adding the empty set yields the 1,024 elements of its power set. The identity C(n, k) = C(n, n − k) also follows from the bijection that assigns each subset its complement.
8. Combinations with repetition: choosing multiplicities
There are n available types; we choose a total of k units and allow types to repeat, without distinguishing positions. An outcome can be described by nonnegative integer multiplicities x₁, …, xₙ satisfying:
x₁ + x₂ + ··· + xₙ = k, xᵢ ≥ 0
For n ≥ 1, the stars and bars method represents the k units as stars and separates the n categories with n − 1 bars. Choosing the positions of the stars among k + n − 1 places is equivalent to choosing the multiplicities:
M(n, k) = C(n + k − 1, k) = (n + k − 1)!k!(n − 1)!
With A = {a, b, c} and k = 2, the six selections are {a, a}, {a, b}, {a, c}, {b, b}, {b, c}, and {c, c}. In particular, {a, b} and {b, a} represent the same outcome. For n = 10 and k = 3, the count is 220.
R code
n <- 10
k <- 3
choose(n + k - 1, k)
# [1] 220
# Small enumeration; requires gtools:
# m2 <- gtools::combinations(
# 3, 2, v = A, repeats.allowed = TRUE
# )
# nrow(m2) # 6
As an additional visual example, with the four symbols {1, 2, 3, 4} and size 2, the selections are 11, 12, 13, 14, 22, 23, 24, 33, 34, and 44. These are ten combinations with repetition; there would be sixteen ordered sequences because they would distinguish, for example, 12 from 21. A tree enumerating only those ten branches belongs in this section.
9. APPLE: permuting a fixed multiset
The word APPLE has five positions but four types of letters: A, P, L, and E. The letter P occurs twice. Swapping those two Ps does not change the visible word. Its distinct rearrangements therefore number neither 5! nor the unrestricted five-letter sequences drawn from four symbols.
When n objects have fixed multiplicities m₁, …, mᵣ summing to n, each visible sequence is counted m₁! ··· mᵣ! times if we artificially distinguish every object. Removing that distinction gives:
The distinction has two parts: combinations with repetition choose the multiplicities; multiset permutations take the multiplicities as fixed and count the possible orders. The script checks the APPLE example through a small enumeration: it permutes the five positions and removes duplicate words. This strategy is educational; it is inefficient for large multisets because it generates duplicates before discarding them.
The correct formula depends on which distinctions are preserved by the object we want to count.
10. Comparison tables and totals by length
The following formulas answer different questions. For n = 10 and k = 3, comparing them shows how much the count changes when we alter the importance of order or the possibility of repetition.
Four selection problems; n = 10 and k = 3
Construction
Order
Repetition
Cardinality
Result
Ordered, without repetition
Matters
No
n! / (n − k)!
720
Ordered, with unrestricted repetition
Matters
Yes
nk
1,000
Combinations without repetition
Does not matter
No
C(n, k)
120
Combinations with repetition
Does not matter
Yes
C(n + k − 1, k)
220
The two formulas without repetition require k ≤ n to use their factorial expressions. The formula for combinations with repetition applies directly for n ≥ 1. All models include one empty selection when k = 0.
Counting and enumerating are different operations
Object
Count
Enumerate in small examples
Product A × B
length(A) * length(B)
expand.grid()
Power set
2^length(A)
The script’s power_set(); rje::powerSet()
Ordered, without repetition
count_ordered(n, k)
gtools::permutations()
Ordered, with repetition
n^k
gtools::permutations(..., repeats.allowed = TRUE)
Combinations without repetition
choose(n, k)
utils::combn()
Combinations with repetition
choose(n + k - 1, k)
gtools::combinations(..., repeats.allowed = TRUE)
10.1. The eleven sizes for n = 10
The k = 0 row is essential for identities that include the empty object. The table presents counts without generating the corresponding collections.
n = 10; k from zero to ten
k
Ordered without repetition
Ordered with repetition
Combinations without repetition
Combinations with repetition
0
1
1
1
1
1
10
10
10
10
2
90
100
45
55
3
720
1,000
120
220
4
5,040
10,000
210
715
5
30,240
100,000
252
2,002
6
151,200
1,000,000
210
5,005
7
604,800
10,000,000
120
11,440
8
1,814,400
100,000,000
45
24,310
9
3,628,800
1,000,000,000
10
48,620
10
3,628,800
10,000,000,000
1
92,378
10.2. Nonempty totals: k from 1 through 10
Sums over lengths, with n = 10
Family
Sum
Total
Ordered, without repetition
∑ P(10, k)
9,864,100
Ordered, with unrestricted repetition
∑ 10k
11,111,111,110
Combinations without repetition
210 − 1
1,023
Combinations with repetition
C(20, 10) − 1
184,755
The last result follows from the identity ∑k=0m C(n + k − 1, k) = C(n + m, m), for n ≥ 1. One justification adds an auxiliary category that absorbs the units needed to reach m: choosing up to m units from n types is equivalent to distributing exactly m units among n + 1 types. We subtract one from the final count to exclude the empty selection.
With unrestricted repetition and at least one available symbol, allowing k to grow without a bound produces infinitely many sequences and infinitely many finite multisets. The range of sizes must therefore be stated whenever a “total” is presented.
Knowing a cardinality does not require materializing every object. A hypothetical matrix with 1010 rows, ten columns, and eight bytes per cell would require approximately 800 decimal GB for the data alone, before accounting for auxiliary structures and temporary copies. This estimate applies to that specific representation; actual consumption depends on the data type and algorithm.
The script therefore sets teaching limits of 100,000 results and 1,000,000 estimated cells before enumeration. These limits do not guarantee that every admitted computation will be fast or use little memory; they prevent accidental execution of the largest examples. For larger tasks, consider lazy generation, partial traversal, or specialized algorithms.
11.1. Overflow and approximate arithmetic
R’s double numbers do not represent every arbitrarily large integer exactly. Rounding can occur even when the result is not infinite. A quotient of factorials does not avoid this problem either: intermediate factorials can overflow even when the final result is representable.
choose() calculates binomial coefficients, and lchoose() obtains their logarithms without first forming the full quantity; lfactorial() serves an analogous purpose for factorials [5]. To estimate an order of magnitude:
R code
# Base-10 logarithm of C(2000, 1000):
log10_binomial <- lchoose(2000, 1000) / log(10)
log10_binomial
# Approximately 600.3114
# Logarithm of P(n, k), within the domain 0 <= k <= n:
n <- 1000
k <- 500
log_P <- lfactorial(n) - lfactorial(n - k)
Working with logarithms reduces numerical range problems; it does not turn a calculation into exact integer arithmetic. Nor should an enormous logarithm automatically be exponentiated, since overflow may reappear. If every digit of a large integer is needed, an appropriate arbitrary-precision tool must be selected and validated for that purpose.
11.2. What the checks establish
The script compares counts with small enumerations, checks summation identities, and examines boundary cases. It also avoids confusing an empty list with a list containing the empty selection. These tests detect implementation errors, inconsistent conventions, and regressions. Explanations based on bijections and counting principles justify the results beyond the finite grid that is checked.
12. Mathematical interpretation and applications
The preceding constructions are related by specific functions and correspondences. Forgetting the order of a sequence of length k without repetition produces a subset of size k, and every subset has k! preimages. If repetitions are allowed, forgetting order produces a multiset; in this case, the number of sequences associated with each multiset depends on its multiplicities.
This difference explains why dividing nk by k! does not, in general, give the number of combinations with repetition. For A = {a, b} and k = 2, the sequences aa and bb each have a single visible order, whereas ab and ba are grouped into the same multiset. The groups do not all have the same size.
12.1. Probability: enumeration does not specify a distribution
Suppose we make two independent draws with replacement from a mechanism that produces a and b with probability 1/2 each. The sequences aa, ab, ba, and bb each have probability 1/4. After forgetting order, the three multisets {a, a}, {a, b}, and {b, b} have probabilities 1/4, 1/2, and 1/4. Choosing uniformly among these three multisets therefore does not reproduce the same experiment.
The formula “favorable outcomes / possible outcomes” requires the counted outcomes to be equally probable. Defining the sample space, the selection mechanism, and the distribution is an additional step beyond enumerating objects.
12.2. Experimental design and data science
Cartesian product: constructing every configuration in a parameter grid or every combination of factor levels. If the factors have different sizes, multiply their cardinalities.
Power set: describing possible selections of variables. A set of n variables has 2n subsets, including the model with no selected predictors.
Ordered selections without repetition: assigning distinct positions to different people, with one candidate per position and no reuse.
Combinations without repetition: selecting committees or subsets of observations when selection order is not part of the outcome.
Combinations with repetition: distributing indistinguishable units among identified categories, with nonnegative quantities and no upper bounds.
The assumptions must be reviewed for each application. Incompatible factor combinations, limited inventories, unequal probabilities, or additional constraints change the problem. A table of formulas guides the choice; the definition of the object and mechanism determines which formula is appropriate.
12.3. Epistemological scope
A computational representation selects which information to retain. Converting a sequence into a set removes order and multiplicity; converting it into a multiset removes order but preserves frequencies. These transformations show that a mathematical abstraction is more than a change of name: it changes the distinctions organizing the problem and, with them, the counting results.
Computational experimentation becomes more informative when that selection is explicit. Defining, representing, deducing, executing, and comparing are complementary stages of reproducible inquiry into finite objects.
13. Complete reproducible script
The following program brings the article together. Copy its contents into a text file named sets_combinatorics.R, save it as UTF-8, and run it with source("sets_combinatorics.R", encoding = "UTF-8") or Rscript sets_combinatorics.R. External packages are used only if installed; the program reports when it skips those blocks.
The counting functions validate nonnegative integer sizes. The enumerators represent each selection as a vector inside a list, including empty cases. The size safeguard runs before calling the enumerators. The representation domain is restricted to finite numeric vectors and character vectors without missing values; sets of more complex objects require an appropriate equality relation.
Open the complete script · functions, examples, and checksComplete script · copy from the first line through sessionInfo()
# SETS AND COMBINATORICS IN R
# JOSÉ MAURICIO GÓMEZ JULIÁN
# Article script. Save as sets_combinatorics.R (UTF-8).
# The basic examples require no external packages.
# install.packages(c("gtools", "rje")) # Only if the optional blocks are wanted.
# 1. Validation and counting functions -------------------------------
nonnegative_integer <- function(x, name) {
if (!is.numeric(x) || is.complex(x) || length(x) != 1L || is.na(x) ||
!is.finite(x) || x < 0 || x != floor(x)) {
stop(name, " must be a finite nonnegative integer.")
}
invisible(TRUE)
}
validate_nk <- function(n, k) {
nonnegative_integer(n, "n")
nonnegative_integer(k, "k")
}
normalize_set <- function(x) {
if ((!is.numeric(x) && !is.character(x)) || is.complex(x) ||
!is.null(dim(x)) || anyNA(x) ||
(is.numeric(x) && any(!is.finite(x)))) {
stop("Use a finite numeric or character vector, with no NA values or dimensions.")
}
unique(x)
}
count_ordered <- function(n, k, repetition = FALSE) {
validate_nk(n, k)
if (!is.logical(repetition) || length(repetition) != 1L ||
is.na(repetition)) stop("repetition must be TRUE or FALSE.")
if (k == 0) return(1)
if (repetition) return(n^k)
if (k > n) return(0)
# Falling product: avoids forming two factorials separately.
prod(n - seq_len(k) + 1)
}
count_combinations <- function(n, k, repetition = FALSE) {
validate_nk(n, k)
if (!is.logical(repetition) || length(repetition) != 1L ||
is.na(repetition)) stop("repetition must be TRUE or FALSE.")
if (k == 0) return(1)
if (n == 0) return(0)
if (repetition) return(choose(n + k - 1, k))
if (k > n) return(0)
choose(n, k)
}
limit_enumeration <- function(rows, columns,
max_rows = 1e5,
max_cells = 1e6) {
if (!is.finite(rows) || rows > max_rows ||
rows * max(1, columns) > max_cells) {
stop("Enumeration stopped by the teaching limit; calculate only the count.")
}
invisible(TRUE)
}
# All enumerations return lists of vectors.
# For k=0, return list(x[0]): a list containing an empty vector.
enumerate_ordered <- function(x, k, repetition = FALSE) {
x <- normalize_set(x)
n <- length(x)
total <- count_ordered(n, k, repetition)
limit_enumeration(total, k)
if (k == 0) return(list(x[0]))
if (total == 0) return(list())
if (!requireNamespace("gtools", quietly = TRUE)) {
stop("This enumerator requires gtools: install.packages('gtools').")
}
m <- gtools::permutations(n, k, v = x,
repeats.allowed = repetition)
lapply(seq_len(nrow(m)), function(i) unname(m[i, ]))
}
enumerate_combinations <- function(x, k, repetition = FALSE) {
x <- normalize_set(x)
n <- length(x)
total <- count_combinations(n, k, repetition)
limit_enumeration(total, k)
if (k == 0) return(list(x[0]))
if (total == 0) return(list())
if (!repetition) {
# Using indices prevents combn(5, 1) from interpreting 5 as 1:5.
indices <- utils::combn(seq_len(n), k, simplify = FALSE)
return(lapply(indices, function(i) x[i]))
}
if (!requireNamespace("gtools", quietly = TRUE)) {
stop("This enumerator requires gtools: install.packages('gtools').")
}
m <- gtools::combinations(n, k, v = x, repeats.allowed = TRUE)
lapply(seq_len(nrow(m)), function(i) unname(m[i, ]))
}
power_set <- function(x) {
x <- normalize_set(x)
n <- length(x)
limit_enumeration(2^n, n)
result <- list(x[0])
for (k in seq_len(n)) {
result <- c(result, enumerate_combinations(x, k))
}
result
}
format_family <- function(F) {
vapply(F, function(x) {
if (length(x) == 0) "{}" else paste0("{", paste(x, collapse = ", "), "}")
}, character(1))
}
# 2. Sets and Cartesian products -------------------------------
A <- c("a", "b", "c")
B <- c(1, 2, 3)
reference_set <- 1:10
n <- length(reference_set)
stopifnot(
setequal(c("a", "b", "a"), c("b", "a")),
!identical(c("a", "b"), c("b", "a")),
identical(normalize_set(c(1, 1, 2)), c(1, 2))
)
product <- expand.grid(A = A, B = B,
KEEP.OUT.ATTRS = FALSE, stringsAsFactors = FALSE)
stopifnot(nrow(product) == length(A) * length(B))
product_10 <- expand.grid(x = reference_set, y = reference_set,
KEEP.OUT.ATTRS = FALSE, stringsAsFactors = FALSE)
stopifnot(nrow(product_10) == 100)
print(product)
# Set operations and laws within an explicit universe.
S <- c("a", "b")
T <- c("b", "c")
Omega <- c("a", "b", "c", "d")
stopifnot(
length(union(S, T)) == length(S) + length(T) - length(intersect(S, T)),
setequal(setdiff(Omega, union(S, T)),
intersect(setdiff(Omega, S), setdiff(Omega, T))),
setequal(setdiff(Omega, intersect(S, T)),
union(setdiff(Omega, S), setdiff(Omega, T)))
)
# 3. Power set and finite sigma-algebra ----------------------
PA <- power_set(A)
P10 <- power_set(reference_set)
stopifnot(length(PA) == 8, length(P10) == 1024,
sum(lengths(PA) == 0) == 1)
print(format_family(PA))
contains_set <- function(x, F) {
any(vapply(F, function(y) setequal(x, y), logical(1)))
}
is_finite_sigma_algebra <- function(F, omega) {
if (!is.list(F)) return(FALSE)
if (!all(vapply(F, function(x) all(x %in% omega), logical(1)))) {
return(FALSE)
}
if (!contains_set(omega[0], F) || !contains_set(omega, F)) return(FALSE)
for (x in F) {
if (!contains_set(setdiff(omega, x), F)) return(FALSE)
for (y in F) if (!contains_set(union(x, y), F)) return(FALSE)
}
TRUE
}
F_min <- list(A[0], A)
F_intermediate <- list(A[0], "a", c("b", "c"), A)
stopifnot(is_finite_sigma_algebra(F_min, A),
is_finite_sigma_algebra(F_intermediate, A),
is_finite_sigma_algebra(PA, A),
!is_finite_sigma_algebra(list(A[0], "a", A), A))
# On a finite universe, closure under binary unions suffices here:
# any countable union involves only finitely many distinct subsets.
# 4. Small sequence enumeration using base R -----------------------
pairs <- expand.grid(x = A, y = A,
KEEP.OUT.ATTRS = FALSE, stringsAsFactors = FALSE)
without_repetition <- pairs[pairs$x != pairs$y, , drop = FALSE]
stopifnot(nrow(pairs) == 9, nrow(without_repetition) == 6,
length(enumerate_combinations(A, 2)) == 3)
# 5. Count table for n=10, k=0,...,10 ------------------------
ks <- 0:n
counts <- data.frame(
k = ks,
ordered_without = vapply(ks, function(k) count_ordered(n, k), numeric(1)),
ordered_with = vapply(ks, function(k) count_ordered(n, k, TRUE), numeric(1)),
combinations_without = vapply(ks, function(k) count_combinations(n, k), numeric(1)),
combinations_with = vapply(ks, function(k) count_combinations(n, k, TRUE), numeric(1))
)
print(counts, row.names = FALSE)
stopifnot(sum(counts$combinations_without) == 2^n,
sum(counts$combinations_without[-1]) == 1023,
sum(counts$ordered_without[-1]) == 9864100,
sum(counts$ordered_with[-1]) == 11111111110,
sum(counts$combinations_with[-1]) == 184755)
# Lists for all lengths are illustrated with n=3.
# Millions of sequences for n=10 are not enumerated.
combinations_by_k <- lapply(0:length(A), function(k) {
enumerate_combinations(A, k)
})
stopifnot(sum(lengths(combinations_by_k)) == 8)
# 6. APPLE: permutations of a multiset -----------------------
letters_in_word <- strsplit("APPLE", "", fixed = TRUE)[[1]]
multiplicities <- as.numeric(table(letters_in_word))
apple_count <- factorial(length(letters_in_word)) /
prod(factorial(multiplicities))
stopifnot(apple_count == 60)
# 7. Boundary cases and memory safeguards ------------------------
stopifnot(count_ordered(0, 0) == 1,
count_ordered(0, 0, TRUE) == 1,
count_ordered(0, 2, TRUE) == 0,
count_ordered(2, 3) == 0,
count_combinations(0, 0, TRUE) == 1,
count_combinations(0, 2, TRUE) == 0,
length(power_set(numeric(0))) == 1,
identical(enumerate_combinations(5, 1), list(5)),
length(enumerate_combinations(A, 0)) == 1)
expected_failure <- tryCatch({
limit_enumeration(10^10, 10)
FALSE
}, error = function(e) TRUE)
stopifnot(expected_failure)
# Large counts: logarithmic scales do not provide exact arithmetic.
log10_binomial <- lchoose(2000, 1000) / log(10)
print(log10_binomial)
# 8. Optional block: gtools ---------------------------------------
if (requireNamespace("gtools", quietly = TRUE)) {
p2 <- enumerate_ordered(A, 2)
r2 <- enumerate_ordered(A, 2, TRUE)
c2 <- enumerate_combinations(A, 2)
m2 <- enumerate_combinations(A, 2, TRUE)
stopifnot(length(p2) == 6, length(r2) == 9,
length(c2) == 3, length(m2) == 6)
# Compare generated objects with formulas on a small grid.
for (nn in 1:4) {
xx <- letters[seq_len(nn)]
for (kk in 0:4) {
for (rr in c(FALSE, TRUE)) {
stopifnot(
length(enumerate_ordered(xx, kk, rr)) ==
count_ordered(nn, kk, rr),
length(enumerate_combinations(xx, kk, rr)) ==
count_combinations(nn, kk, rr)
)
}
}
}
ordered_by_k <- lapply(0:length(A), function(k) {
enumerate_ordered(A, k)
})
stopifnot(sum(lengths(ordered_by_k)) == 16)
# APPLE: distinguish positions first; then remove duplicate words.
positions <- gtools::permutations(length(letters_in_word), length(letters_in_word))
words <- apply(positions, 1, function(i) paste0(letters_in_word[i], collapse = ""))
apple_words <- unique(words)
stopifnot(length(apple_words) == apple_count)
print(head(apple_words))
} else {
message("gtools not installed: its examples were skipped; base counts were computed.")
}
# 9. Optional block: rje ------------------------------------------
if (requireNamespace("rje", quietly = TRUE)) {
PA_rje <- rje::powerSet(A)
stopifnot(length(PA_rje) == 8,
all(vapply(PA_rje, function(x) contains_set(x, PA), logical(1))))
} else {
message("rje not installed: the base-R power-set construction was used.")
}
cat("Checks completed without errors.\n")
sessionInfo()
The output of sessionInfo() records the R version, platform, and packages attached or loaded through a namespace. Keep it alongside the results. The absence of gtools or rje does not count as a successful check of its respective block: those examples are skipped with an explicit message.
14. References and documentation
The following references support the functions used and the conceptual clarification concerning σ-algebras. The counting arguments are developed in the article through multiplication principles, bijections, and explanations of how outcomes are identified.
R Core Team.Set Operations. Official documentation for the base package. Union, intersection, difference, and set comparison operations. Read the documentation.
R Core Team.Create a Data Frame from All Combinations of Factor Variables. Documentation for expand.grid(). Read the documentation.
R Core Team.Generate All Combinations of n Elements, Taken m at a Time. Documentation for utils::combn(). Read the documentation.
gtools package documentation.Enumerate the Combinations or Permutations of the Elements of a Vector. Reference for combinations(), permutations(), and their arguments. Read the CRAN documentation.
R Core Team.Special Functions of Mathematics. Documentation for choose(), lchoose(), factorial(), and lfactorial(). Read the documentation.
Kehle, Christoph (2025).Introduction to Functional Analysis. Lecture notes for 18.102, Massachusetts Institute of Technology, Section 3.1, Definition 3.1 and example, pp. 25–26. Definition of a σ-algebra and the power-set example with counting measure. Read the lecture notes.
rje package documentation.Miscellaneous Useful Functions for Statistics. Reference index, powerSet entry; also available from R with help("powerSet", package = "rje"). Read the package index.
Marxist Philosophy of Science · Philosophy of science
· · ·
A historical, theoretical, and mathematical investigation into the dialectical character of the epistemological foundations of complexity in long-term nonlinear dynamical systems
Determinism, uncertainty, scales, and emergence: toward a materialist interpretation of the relationships between laws, phenomena, and the ways we come to know them.
JOSÉ MAURICIO GÓMEZ JULIÁN
Originally published on April 4, 2021 · Revised and expanded web edition
Abstract
The possibility that deterministic laws can produce irregular behavior and severe limits on prediction requires us to distinguish between the determination of processes, their mathematical representation, and the conditions under which they can be known. This investigation proposes a dialectical materialist interpretation of this problem by connecting the categories of essence, phenomenon, appearance, form, and content with nonlinear dynamics, fractal geometry, critical phenomena, renormalization, and probability theory. Its historical account encompasses Laplace, Poincaré, Lorenz, and Mandelbrot; the tradition of Hegel, Marx, Engels, and Lenin; Soviet philosophical systematization; and scientific contributions associated with dialectical biology. Applications in astronomy, cardiovascular physiology, computing, econometrics, neuroscience, psychiatry, hydrodynamics, and geodynamics are examined. On this basis, the essay develops distinctions between nonlinearity, chaos, and complexity; between geometric irregularity and dynamical instability; between scaling and temporal evolution; and between ergodicity, independence, and exchangeability. The thesis advanced is that dialectics can guide an investigation of relationships, mediations, transformations, and levels of organization, provided that its interpretations are confronted with specific models and evidence. The philosophical correspondences proposed are distinguished from the mathematical definitions and empirical findings that serve as their points of reference.
That a phenomenon has causes, that a model determines a unique evolution, and that an observer can predict it are different claims. Conflating them leads both to a naive determinism—according to which knowing the laws would be enough to anticipate any event—and to an equally hasty interpretation of irregularity as the absence of lawfulness. The study of nonlinear dynamical systems makes it possible to examine this distinction with precise tools while raising philosophical questions about the relationship between reality and its representations.
The central question is how determination, uncertainty, and transformation are articulated when processes involve multiple scales, feedbacks, instabilities, and levels of organization. This question requires consideration of both the material conditions of phenomena and the historical, technical, and conceptual conditions under which they are known. A measurement has finite resolution; a model selects variables; a simulation uses numerical procedures; an explanation identifies mechanisms within a delimited scope. None of these mediations is external to scientific practice.
The thesis of this essay is that dialectical materialism can help organize this investigation through an analysis of the relationships between wholes and parts, continuity and discontinuity, necessity and contingency, and structure and transformation. Its fruitfulness depends on how these relationships are specified. A suggestive analogy may open a question; establishing an explanatory correspondence requires definitions, mechanisms, conditions of application, and empirical or theoretical scrutiny.
The proposed relationship is reciprocal. Scientific developments allow philosophical categories to be revised when, isolated from research, they risk becoming general formulas. Philosophical reflection, in turn, makes it possible to question the assumptions of models, the selection of scales, the meaning of their limits, and extrapolations between disciplines. This reciprocity is understood as a research program requiring specific developments; claiming its universal and optimal usefulness would require comparisons that an investigation of this scope cannot assume have already been made.
The essay develops a historical and conceptual reconstruction, accompanied by mathematical examples and methodological discussion. Figures taken from earlier investigations are presented as documentary evidence from their respective authors. The pedagogical calculations introduced here clarify concepts; they do not constitute new estimates for the physical, biological, or social systems cited.
II · Philosophical background
Essence, phenomenon, appearance, form, and content
A tradition of problems and reconstructions
Questions about what things are, how they manifest themselves, and how their components relate to one another run through ancient philosophy and reappear, with different meanings, in modern systems. Substance, essence, and phenomenon belong to this history, although their meanings are not interchangeable. Investigating their connections requires recognition of the diversity of traditions: there is no single definition that can be transferred without mediation from ancient Greece to Hegel, or from Hegel to a contemporary scientific theory.
Hegelian logic provides a decisive reference for understanding the elaboration of relationships between essence and appearance, form and content, and universality and particularity. Marx and Engels critically rework this inheritance from a materialist standpoint. Their attention to historical relationships, the organization of processes, and the forms in which social relationships manifest themselves offers a starting point for the philosophy of science. Identifying that starting point requires studying their concrete analyses; an intellectual affiliation alone does not demonstrate the validity of a scientific proposition.
Lenin continues this debate in Materialism and Empirio-Criticism, written in 1908 and published in 1909, by discussing the relationships between matter, experience, sensation, and knowledge. His positions can be examined alongside the problems raised by the physics of his time, distinguishing the historical controversy from later technical formulations. A philosophical tradition’s relationship with the sciences involves interpretation, reception, and criticism as well as continuity.
Soviet philosophy and its historical context
The systematization of categories in Rosental and Iudin’s Philosophical Dictionary is a reference point of the original work. The cited Spanish edition of 1971 must be identified as an edition within an earlier publishing tradition. The foreword reproduced in that edition refers to the Twentieth and Twenty-Second Congresses of the Communist Party of the Soviet Union and to the reassessment of the consequences of the cult of personality. These events and the associated intellectual processes should not be dated to 1971 simply because that is the date of the copy consulted.
An assessment of this endeavor can recognize its thematic breadth—philosophy, history, political economy, biology, physics, logic, aesthetics, ethics, and art—while also examining its institutional conditions. Accepting its contributions does not require adopting every formulation without revision, and criticism of Soviet policies does not justify dismissing its philosophical production wholesale. A materialist recovery of this history requires a differentiated assessment of authors, arguments, institutions, and periods.
The recognition expressed here toward this tradition consists in continuing its problems, scrutinizing its answers, and developing the categories systematized within it. Its function in this investigation is to provide an initial vocabulary for studying relationships that scientific models allow us to specify in new ways.
Dialectical biology and relationships between levels
The history of relationships between Marxism and the natural sciences extends beyond the Soviet Union. J. B. S. Haldane contributed to the development of evolutionary genetics and the modern synthesis; Aleksandr Oparin and Haldane formulated proposals concerning the origin of life; Stephen Jay Gould and Richard Lewontin critically examined adaptationism; and Richard Levins investigated problems of evolution, ecology, and biological organization. These names designate distinct contributions and positions whose relationship with a dialectical perspective must be reconstructed in each case.
The joint works of Levins and Lewontin, particularly The Dialectical Biologist (1985) and Biology Under the Influence (2007), provide references for studying the reciprocity between organisms and environments, the selection of explanatory levels, and the commitments involved in modeling. The relationship between parts and wholes appears there as a research problem: components transform the conditions in which they act and are, in turn, transformed by them.
Landau in physics and Semenov in chemistry remain reference points within the scientific horizon considered by the original text. However, a scientist’s membership in a Soviet context is not enough to attribute every result to a specific philosophical methodology. Supporting such an attribution requires sources concerning their practices, arguments, and research decisions. The value of their results can be examined independently of that historiographical question.
Working definitions
Philosophical categories and research questions
Category
Proposed use in this essay
Guiding question
Essence
Relationships and mechanisms that an investigation identifies as constitutive of a process under specified conditions.
Which relationships explain the organization and reproduction of the phenomenon?
Phenomenon
A concrete manifestation of a process, accessible through practices of observation and intervention.
What happens, and how does it present itself under particular conditions?
Appearance
A mode of presentation that may partially reveal a relationship while also concealing its mediations.
Which interpretations does the observation suggest, and which relationships remain outside that presentation?
Form
The configuration, arrangement, and mode of organization of content.
How are the elements and their relationships organized?
Content
The components, interactions, and processes that constitute the object of study.
Which processes and relationships are organized in this way?
These definitions neither exhaust the history of the categories nor establish a universal equivalence between philosophical and scientific vocabularies. They propose explicit uses for this essay. The same observation may be analyzed as a phenomenon in one question and as part of a system’s content in another; this variation requires justification of the scale and the object of reference.
The distinction between essence and phenomenon makes it possible to investigate mechanisms that an isolated observation does not reveal. It does not authorize dismissing any result inconvenient to a theory as mere appearance. A claim about an essential relationship must improve explanation, organize evidence, and allow procedures for revision. Form and content likewise condition one another: changing the organization of components may modify what a system does even when certain material elements remain the same.
Knowing a process requires reconstructing its mediations: what is observed, the relationships that produce it, and the conditions under which an explanation is valid.
An interpretive proposition advanced in this essay
An initial application can be formulated for a convection model. State variables represent selected quantities; equations express proposed relationships between them; a trajectory shows an evolution; and an attractor describes an asymptotic organization under certain conditions. Philosophical categories can guide questions about these relationships, but an equation does not automatically represent essence, nor does a figure constitute mere appearance by definition. That identification depends on what the model can explain and on its relationship with the material system.
From Laplace’s intelligence to the geometries of irregularity
Laplace: lawfulness and incomplete knowledge
The Essai philosophique sur les probabilités first appeared in 1814. The French edition of 1840 and the English translation of 1902 belong to its publishing history and must be distinguished from that first publication. In Laplace’s account, an intelligence that knew all forces and positions could bring the movements of the universe together within a single description. The scope of this ideal depends on exhaustive knowledge that does not correspond to the situation of a human observer.
The very resort to probability theory expresses the distance between that ideal and the conditions of effective knowledge. One source of Laplace’s philosophical interest lies in his articulation of a conception of natural lawfulness with procedures for reasoning when information is incomplete. The thesis that every event has causes should not be confused with a demonstration that any phenomenon can be predicted operationally.
Laplace’s discussion includes the principle of sufficient reason, the relationship between present and past events, and the interpretation of chance in terms of our ignorance of causes. These ideas retain historical value, although their extension to every domain of reality must be argued separately. Deterministic classical mechanics provides one framework; the different interpretations of quantum physics and probability open controversies that are not settled by the success of a classical model.
Poincaré: small differences and large consequences
Poincaré’s investigations of celestial mechanics and the three-body problem transformed the understanding of dynamical systems. Science et méthode (1908) contains a celebrated account of how small initial differences can produce large later differences. The problem is not exclusively one of unknown laws: even with a known evolution rule, the finite precision of initial data can severely limit prediction.
A historical reconstruction must recognize the antecedents and multiple contributions of the qualitative theory of differential equations. Poincaré represents a decisive moment, but the history of chaos cannot be reduced to a sequence of isolated founders. Its subsequent development combines analytical results, geometrical methods, computational techniques, and experimental problems.
Lorenz: determinism and nonperiodic evolution
In Deterministic Nonperiodic Flow (1963), Edward N. Lorenz studies a simplified convection model whose dynamics shows the compatibility of deterministic evolution and irregularity. Its historical significance includes discussion of the limits of long-term weather prediction. The article is a landmark in chaos theory; identifying it as the birth of the entire science of complexity would erase other scientific genealogies.
Reference model
ẋ = σ(y − x)
ẏ = x(ρ − z) − y
ż = xy − βz
The variables x, y, and z represent mode amplitudes in the reduced model; σ, ρ, and β are parameters. A common choice for illustrating its dynamics is σ = 10, ρ = 28, and β = 8/3. Terms such as xy and xz introduce nonlinearity. The properties of one particular regime should not be attributed to every parameter value: the same system can display qualitatively different behaviors.
The example’s philosophical appeal lies in a relatively compact rule generating a temporal organization that cannot be reduced to a simple periodic succession. The difficulty of anticipating a particular trajectory coexists with the possibility of studying equilibria, stability, attractor geometry, and statistical properties. The limit of one form of prediction opens other questions about the same process.
Mandelbrot: form, scale, and irregularity
Fractal geometry, developed by Benoît Mandelbrot and other authors, makes it possible to investigate structures for which the smooth figures of elementary geometry are insufficient as descriptive models. Coastlines, mountains, clouds, trees, rough surfaces, and branching networks motivate questions about how a measurement changes as resolution varies. The 1982 edition of The Fractal Geometry of Nature and the 1983 edition cited in the original investigation must be distinguished bibliographically.
This contribution does not eliminate Euclidean geometry or imply that every natural object is fractal. It proposes concepts suited to describing certain irregularities and scaling laws. In material phenomena, these properties are usually verified within finite intervals of resolution; extending them to arbitrarily small or large sizes requires an additional idealization.
Relating geometry to form and dynamics to content provides an initial orientation, but requires mediation: an attractor’s geometry contains dynamical information, and geometrical constraints can condition material processes. The dialectical contribution consists in investigating these reciprocal relationships, avoiding the conversion of an analytical distinction into an absolute separation.
Dynamical systems, nonlinearity, chaos, and complexity
State, evolution, and observation
A dynamical system can be described by a state space X and an evolution rule. In discrete time, one writes xn+1 = F(xn); in continuous time, a common representation is ẋ = f(x, t). A state brings together the variables that the model considers necessary for describing evolution. Deciding which variables to include is part of the scientific problem: an overly reduced representation may lose relevant mechanisms, while an excessively detailed one may prevent the identification of regularities.
For a differential equation to define a unique deterministic evolution, appropriate existence and uniqueness conditions are required. Writing an equation without a random term is not, by itself, enough to guarantee these properties. The determinism of a model should be distinguished from the metaphysical thesis that all reality is determined in a particular way.
Nor does the observed quantity necessarily coincide with the complete state. It may be represented as yn = h(xn) + εn, where h is the observation function and ε represents measurement error under an explicit model. A one-dimensional record may originate from a system with many dimensions. Its apparent irregularity does not automatically identify the mechanism that produced it.
What nonlinearity means
In a linear system, a superposition principle holds: a linear combination of the relevant inputs or states corresponds to a combination of their responses. Nonlinear interactions can break this property. Feedback that depends on the product of variables, saturation, or a threshold constitutes a common form of nonlinearity.
Nonlinearity may produce equilibria, cycles, quasiperiodic oscillations, multiple stable states, prolonged transients, or chaos. It does not guarantee chaotic behavior. The continuous logistic equation, for example, describes a nonlinear evolution that, in its usual form, converges to an equilibrium under appropriate conditions. The discrete logistic map displays a variety of regimes depending on its parameter.
Pedagogical example · Logistic map
xn+1 = r xn(1 − xn), 0 ≤ xn ≤ 1, 0 ≤ r ≤ 4.
This example allows stability and bifurcations to be studied. For values of r between 1 and 3, the nonzero fixed point is stable; varying the parameter produces changes in stability and period doublings. Other intervals contain chaotic regimes and periodic windows. Increasing a parameter therefore does not amount to monotonically increasing a supposedly universal quantity of complexity.
Figure 15 · Example calculated for this editionLogistic map with initial x = 0.2718281828. The first 250 iterations are discarded and the next 90 are shown. The data are synthetic and deterministic; the figure illustrates different regimes and does not by itself constitute a mathematical proof of chaos. It does not represent measurements of the empirical systems cited.
Deterministic chaos and its criteria
Chaos designates a family of dynamical properties whose formulation depends on the mathematical framework. Sensitive dependence on initial conditions is central to many characterizations, but must be accompanied by assumptions that distinguish chaos from other forms of instability. A separation between trajectories that grows without bound in an unstable linear system does not, on that ground alone, constitute the same phenomenon as irregular recurrent dynamics on a bounded set.
Lyapunov exponents, entropy, and mixing properties allow different aspects of dynamics to be studied. Their use requires specification of the system, the relevant measure, the limits considered, and the definition adopted. The existence of multiple characterizations is a reason to make the vocabulary explicit, especially when transferring it to empirical domains.
Attractors and phase diagrams
Phase space organizes a model’s possible states; a trajectory describes its evolution. A phase diagram represents that organization and can be used for both regular and chaotic dynamics. In general terms, an attractor is an invariant set approached by states from a region of initial conditions; technical definitions specify invariance, attraction, and additional properties.
A fixed point, a limit cycle, and certain more complicated sets can act as attractors. A strange attractor is associated with irregular, often fractal, geometry. Its representation is not an imprecise sketch replacing phase space: it is a structure studied within it. The fact that a figure looks visually dense does not mean its properties are mathematically undefined.
Complexity and emergence
Complexity may refer to diversity of components, the organization of interactions, multiple scales, difficulty of description, computational cost, or the emergence of collective patterns. No single measure resolves all these problems. Chaos theory studies an important part of this field but does not exhaust the sciences of complexity; a system with few variables can be chaotic, while a network with many components can display regular collective dynamics.
Emergence is understood here as the appearance of collective properties whose description requires consideration of organization and interactions. Determining whether that emergence rules out a derivation in principle, reflects computational limitations, or expresses the autonomy of an explanatory level requires additional arguments. The need to study a collective level does not automatically demonstrate that its properties are incompatible with the laws governing the components.
Necessary distinctions for an interdisciplinary reading
Concept
What it characterizes
What it does not establish by itself
Model determinism
Uniqueness of evolution from a state under the conditions of the formulation.
Unlimited practical prediction.
Nonlinearity
Failure of the relevant superposition principle.
The existence of chaos.
Chaos
Properties of dynamical irregularity and instability defined within a specific framework.
The absence of causes or statistical regularities.
Fractality
Geometrical and scaling properties.
A positive Lyapunov exponent.
Complexity
Problems of organization, interaction, scale, or description.
A single universal dynamics or measure.
Randomness
Probabilistic or algorithmic properties that must be defined.
That an observed signal originates from dynamics lacking determination.
Disciplinary breadth is valuable when it makes it possible to compare problems and recognize differences. The following cases preserve the scope of the original investigation while specifying what kind of evidence each contributes. Sharing an equation or a figure does not make the phenomena being modeled identical. Comparison requires specifying which structure is shared, how the variables are interpreted, and which procedures establish its relevance.
1. Astronomy: variable stars and strange nonchaotic attractors
Strange nonchaotic attractors show why geometric irregularity and chaos must be distinguished. In 1984, Grebogi, Ott, Pelikan, and Yorke published a foundational investigation of attractors that are strange without being chaotic in the dynamical sense used. In quasiperiodically forced systems, the geometry can be fractal while the relevant exponents fail to display the positive exponential instability characteristic of other attractors.
The expression “nonchaotic” does not mean that a system is deterministic only because sufficient information is available, nor that it necessarily occupies a universal midpoint between order and chaos. Its deterministic character depends on its evolution rule. The distinction between strange and chaotic depends on geometrical and dynamical properties that must be specified, including the difference between exponents corresponding to the forcing and those corresponding to response variables.
In Strange Nonchaotic Stars, Lindner and colleagues (2015) study luminosity records obtained by the Kepler telescope. For variable stars such as KIC 5520878, they present evidence consistent with strange nonchaotic dynamics. One clue is the ratio between primary and secondary frequencies, which is close to the golden ratio. The article’s scope is an inference supported by observations and diagnostics; a frequency ratio close to a particular number does not, by itself, demonstrate the complete dynamics.
Mathematical clarification · Golden ratio
φ = (1 + √5)/2 ≈ 1.6180339887…
φ − 1 = 1/φ ≈ 0.6180339887…
A frequency ratio may be expressed as φ or its inverse, depending on the order of the quotient. An irrational number cannot be expressed as a ratio of two integers, and its decimal expansion is infinite and not eventually periodic; this does not make it an infinitesimal. The golden ratio is a finite positive number. Its classical geometrical construction must be distinguished from other theorems about the division of line segments, such as the angle-bisector theorem. The presence of a ratio close to φ in a dataset requires consideration of precision, uncertainty, and other possible ratios.
Figure 1Attractor reconstruction from variations in stellar luminosity. Lindner and colleagues (2015). Resource retained from the original PDF, p. 9. Its interpretation requires the article’s diagnostics in addition to the frequency ratio. Reference.
The epistemological interest of this case lies in the fact that the same object can display frequency regularities and geometric irregularity. Research requires combining descriptive domains rather than inferring the entire dynamics from a single visual characteristic. Johnston’s 2015 news article, cited in a note in the original work, is retained among the supplementary popular-science sources; the main scientific reference is the article by Lindner and colleagues.
2. Cardiovascular physiology: rhythms, networks, and organization
Vijay Sharma’s review, published in 2009, examines applications of dynamics and fractal geometry to the cardiovascular system. It considers regimes of equilibrium, periodicity, quasiperiodicity, deterministic chaos, and random behavior, as well as vascular networks and conduction processes. This research horizon is retained with the clarification that a pedagogical classification does not replace diagnosis of a particular record.
Figure 2Schematic representation of different dynamical behaviors. Sharma (2009). Original PDF, p. 10. The drawings are pedagogical categories, not clinical criteria. Reference.
Temporal variability may fulfill different functions depending on the process, scale, and physiological state under study. Greater irregularity therefore does not automatically indicate disease, nor does greater regularity guarantee healthy functioning. Physiological interpretations must rely on specific variables and protocols; the figures present conceptual schemes rather than clinical thresholds.
The relationship between vascular structure, cellular activity, and systemic regulation makes it possible to examine levels of organization. A network can be studied through its components, pathways and modules, and overall organization. Causality may involve constraints imposed by the collective level on local activity and the effects of local activity on those constraints. This reciprocity constitutes a material question for a dialectical interpretation of biological organization.
Figure 3Components, pathways, modules, and large-scale organization. Sharma (2009). Original PDF, p. 11. The figure introduces levels of biological organization. Reference.
3. Computing: Duffing oscillators and logical operations
Aravindh, Venkatesan, and Lakshmanan (2018) study quasiperiodically forced nonlinear systems capable of performing logical operations. Their investigation uses a double-well Duffing oscillator and analyzes how forcing, bias, and encoded inputs modify its response. Computing appears here as a function implemented by a material dynamical organization.
The Duffing oscillator is a second-order nonlinear differential equation. A reference form is ẍ + δẋ + αx + βx³ = γ cos(ωt). This general expression does not replace the specific formulation used in the cited article, which involves quasiperiodic forcing, inputs, and noise. To preserve that detail, the equation included in the original paper is also reproduced.
Figure 4aOscillator formulation used in the computing investigation. Aravindh, Venkatesan, and Lakshmanan (2018). Original PDF, p. 12. The equation that shared numbering with another figure in the 2021 paper is retained. Reference.Figure 4bRegime projections for a quasiperiodically forced system. Aravindh, Venkatesan, and Lakshmanan (2018). Original PDF, p. 12. Parameter values belong to the source model. Reference.
The different regimes are identified through complementary observations and diagnostics. The authors study the transition between a torus, a strange nonchaotic attractor, and chaos, as well as the persistence of particular logical functions under the noise levels considered. This robustness has a specific parametric and experimental scope: it does not imply universal insensitivity to every disturbance.
Figure 5Lyapunov exponent and variation of the control parameter. Aravindh, Venkatesan, and Lakshmanan (2018). Original PDF, p. 13. Torus, strange nonchaotic regime, and chaos are interpreted according to the authors’ criteria. Reference.Figure 6Sensitivity and scaling diagnostics in the studied regimes. Aravindh, Venkatesan, and Lakshmanan (2018). Original PDF, p. 13. The graph retains its labels and parameters. Reference.
The philosophical relevance is that a functional property at the logical level depends on dynamical mechanisms and conditions of organization. There is no need to suppose that the logical operation exists as an entity separate from its physical implementation. Nor does it follow that mathematical logic is refuted by the device’s behavior: the specification of a gate and the dynamics implementing it belong to related levels of description.
4. Econometrics: attractors, monetary aggregates, and data quality
Barnett and Chen (1988) investigate the use of tools from chaos theory and fractal attractors for econometric inference, with an application to Divisia monetary aggregates. Their work makes it possible to formulate questions about dynamical structure and nonlinearity in economic time series. The journal’s correct title is Mathematical and Computer Modelling; the bibliographic link provided here points to the corresponding article.
Figure 7Projections for comparing dynamical structures in econometrics. Barnett and Chen (1988). Original PDF, p. 15. Graphical patterns must be assessed alongside the method and data quality. Reference.Figure 8Further phase projections of the economic cases studied. Barnett and Chen (1988). Original PDF, p. 15. The second set of panels is retained. Reference.
A reconstructed phase-space representation may reveal patterns, but it does not automatically demonstrate that an economy possesses a low-dimensional attractor. Sample size, observation frequency, regime changes, noise, aggregation, and variable selection condition the inferences. A favorable signal-to-noise ratio helps identify structure but does not by itself resolve the problem of causal identification.
In political economy, moreover, institutions, expectations, decisions, and conflicts may modify the relevant rules of a process. A model with constant parameters must justify the period and conditions of its application. The relationship between structure and history requires examining the stability of mechanisms and institutional forms; identifying a regularity does not eliminate the possibility that social action will transform the conditions producing it.
5. Neuroscience: recurrent networks and the emergence of representations
Recurrent neural networks make it possible to model the evolution of activity patterns. A state represents the selected activations, and a rule describes how they change through connections and inputs. In certain models, stable states or attractors can be interpreted as memories or representations. The relevance of that interpretation depends on the task, training, variables, and relationship with neurobiological evidence.
The example illustrates a possibility of functional emergence: a property attributed to the whole depends on distributed interactions. It does not imply that any biological network functions like a particular recurrent-network model, or that every mental process can be reduced to a fixed point. Moving between explanatory levels requires specifying what is retained and what is omitted in each representation.
6. Psychiatry and psychopathology: the scope of a dynamical paradigm
Pezard and Nandrino (2001) examine the relevance of a dynamical perspective for psychopathology. The original work draws on their discussion of networks, attractors, cognition, and the possibility of modeling psychological processes, including a dynamical interpretation of aspects of Freudian psychodynamics. This problem is retained as a proposal for modeling and conceptual discussion.
Using terms such as transition, attractor, or stability requires observable variables, a relevant rule or model, and criteria for testing the claims. A metaphor can guide exploration, but it does not become a clinical explanation simply by incorporating mathematical vocabulary. The temporal and relational character of a phenomenon is a starting point for investigating it; it is not enough to establish that the phenomenon is chaotic.
7. Hydrodynamics: turbulence, continuity, and instability
The transition between laminar and turbulent flow shows the importance of scales, instabilities, and collective transport. Kessler and Greenkorn’s explanation considers momentum exchange through organized movements of fluid regions, alongside molecular processes. A fluid particle in a continuum description should not be identified with an individual molecule.
Figure 13Pedagogical representation of flow regimes. Elert, The Physics Hypertextbook. Original PDF, p. 34. The depicted thresholds are not generalized to every geometry. Reference.
The Reynolds number, Re = ρUL/η = UL/ν, compares inertial and viscous effects through density ρ, characteristic velocity U, length L, dynamic viscosity η, and kinematic viscosity ν. Transition thresholds depend on geometry, perturbations, and flow conditions. The retained illustration has a pedagogical function: its values do not establish a universal criterion applicable to every configuration.
The continuum hypothesis in fluid mechanics assumes a separation of scales that makes it possible to define macroscopic fields. A representative volume contains enough constituents for an average property to be meaningful while remaining small relative to the relevant scales of the process. This volume has no universal microscopic size; it depends on the substance and the conditions of the problem. Its status as an abstraction does not mean that fluids are materially composed of continuous points.
Turbulence does not, by itself, imply the failure of the continuum hypothesis: many descriptions of turbulence employ continuum equations. Separation between molecular and macroscopic scales is studied, among other tools, through the Knudsen number, Kn = ℓ/L, where ℓ is the mean free path. Closure problems in a turbulent description must be distinguished from problems of rarefaction or the validity of the continuum approximation. Supersonic flow does not automatically invalidate that approximation either.
Statistical mechanics provides frameworks for relating microscopic and macroscopic descriptions. This does not establish a simple sequence in which every difficulty in a continuum equation is resolved by moving to a statistical theory. Each description introduces its own assumptions, scales, and problems. The discussion of absolute zero also requires precision: the classical idealization of an absence of thermal agitation should not be transferred into a claim that all quantum motion ceases at that temperature.
Rayleigh–Taylor instability occurs when a configuration of densities and acceleration is unstable; an idealized example is a denser fluid positioned above a less dense one under gravity. Everyday observation of water and oil can guide intuition, but mixing or stirring them does not by itself identify this instability. Relative position, acceleration, viscosity, surface tension, and, in magnetohydrodynamics, the magnetic field are relevant conditions.
Figure 14Hydrodynamic and magnetohydrodynamic simulations. Li and Li (2006). Original PDF, p. 35. Differences between panels have the scope of the source models and parameters. Reference.
The simulations by Li and Li retained in the paper illustrate the study of these problems using adaptive mesh refinement. Differences between panels must be interpreted in accordance with the parameters and models of the source work. A simulation explores the consequences of a formulation and compares them with other results; the appearance of a figure does not demonstrate a general law of complexity.
8. Geodynamics: magnetic fields and dynamo models
Dynamo theory investigates how the movement of conducting materials can sustain magnetic fields. The geodynamo combines fluid dynamics, electromagnetic induction, rotation, and energy transfer. The original investigation refers to three-dimensional simulations developed in the 1990s, within a broader history of models for the generation of Earth’s magnetic field.
The ability to reproduce particular features through simulations provides evidence concerning the plausibility of mechanisms under the modeled conditions. Resolution and parameter constraints must be examined before extrapolating to the planet. Likewise, an explanation of geomagnetic-field generation and a hypothesis about its relationship with climate are distinct problems: the reference to Kilifarska, Bakmutov, and Melnyk (2020) is retained without presenting every connection discussed in that volume as equally established.
The 0–1 test: what it distinguishes and what it does not
Gottwald and Melbourne’s 0–1 test was designed to distinguish, under appropriate conditions, between regular and chaotic dynamics using a time series. The regular class includes both periodicity and quasiperiodicity. The procedure does not require explicit reconstruction of the entire phase space, which facilitates its use in systems of different dimensions and formulations. The object being diagnosed remains a defined dynamics; a finite signal does not, on its own, contain a complete demonstration of its origin.
A schematic account begins with a scalar series φ(j) and a family of translation variables for particular values of an auxiliary parameter c. The growth of their mean square displacement is studied, or that of a corrected version eliminating an oscillatory term.
Outline of the 0–1 test
pc(n) = ∑j=1n φ(j) cos(jc)
qc(n) = ∑j=1n φ(j) sin(jc)
Kc = limn→∞ log Mc(n) / log n
Under appropriate conditions, regular dynamics produces bounded translations and an indicator close to zero, while chaotic dynamics produces diffusive growth and an indicator close to one. The implementation uses versions and estimators that must be described, including the selection of auxiliary parameters and the aggregation of their results. The indicator should not be interpreted as a universal scale of the intensity of chaos: an intermediate value may reflect finite data, transients, noise, or other difficulties.
Figure 9Comparative diagnostics of regular and chaotic dynamics. Gottwald and Melbourne (2016). Original PDF, p. 17. The material comes from the study of the test’s application to defined systems. Reference.Figure 10Evaluation of the diagnostic with noise-contaminated data. Gottwald and Melbourne (2016). Original PDF, p. 18. Noise, sampling, and series-length conditions are part of the interpretation. Reference.
Record length, temporal sampling, and noise affect the diagnosis. Excessively fine sampling can introduce practical difficulties; excessively sparse sampling can lose the structure being sought. Before applying a test, it is useful to examine whether the record contains regime changes, trends, artifacts, or missing values, and whether the treatment applied alters the properties one intends to detect. Robustness must be assessed against justified preprocessing decisions.
Noise, signal, and identification
“Noise” may designate instrumental error, unmodeled disturbances, or a random component deliberately introduced into a description. The word does not identify a single cause. Separating signal from noise presupposes a research question: a fluctuation treated as noise by one model may be the phenomenon of interest in another. What matters is to make explicit what is being modeled, why, and with what evidence.
Detecting irregularity is not enough to distinguish deterministic chaos from a stochastic process. Diagnostics of nonlinearity, reconstructions, exponent estimates, surrogate-data tests, and sensitivity analyses can be combined. No list of techniques operates as a universal recipe; each procedure has conditions. With limited records, different classes of models may be consistent with similar observations.
Two problems of unpredictability
Werndl’s discussion distinguishes difficulties that are often brought together under the same word. One problem is the loss of precision in trajectories from initial states known only approximately. Another is the loss of probabilistic relevance of sufficiently past information for certain events, associated with mixing properties in the framework she studies. Her 2009 investigation critically examines which specific implications can be attributed to chaos.
Both problems require defining what is to be predicted, at what resolution, and under which distribution or set of initial conditions. A trajectory may be difficult to anticipate while still allowing useful estimates of frequencies, ranges, or invariant measures. The distinction between forecasting a point state and describing a distribution is central to epistemology.
Figure 11Historical table of concepts associated with the study of chaos. Oestreicher (2007). Original PDF, p. 24. Its summaries are supplemented by the clarifications developed in the essay. Reference.
The retained table from Oestreicher brings together historical concepts such as causality, determinism, prediction, linearity, attractors, feedback, and fractal dimension. Its value is orienting and documentary. This edition’s working definitions are developed in the text to prevent a historical summary from being read as a single axiomatization of chaos.
Formal logic, classical logic, and the critique of reductionism
The original investigation criticizes the attempt to exhaust complexity through dichotomous schemes. This concern requires distinguishing the formal character of a logic from the principles adopted by a particular logic. A formal system specifies a language and rules; classical logic constitutes a family of systems with particular properties. Nonclassical logics can also be formalized.
Chaos theory develops through mathematical reasoning that can be formulated in classical frameworks. Its results therefore do not, by themselves, prove the failure of all formal logic. The more productive philosophical critique targets unjustified applications of assumptions concerning linearity, independence, separation of scales, or stability; those assumptions are not equivalent to the law of excluded middle.
The text Formal Logic and Dialectics, retained in the original bibliography, expresses a philosophical position on the limits of reductionism and on emergence. It remains a reference for that controversy, with its argument distinguished from a proved mathematical result. Recognizing emergent levels and reciprocal relationships requires examining concrete models; the vocabulary of dialectics can organize that examination without replacing it.
Quantum logic and physical propositions
Quantum logic studies structures of propositions associated with quantum systems and their relationships with probability. In one common formulation, the closed subspaces of a Hilbert space form a non-Boolean structure in which classical distributivity fails. The philosophical interest concerns how properties and measurement operations are represented.
The noncommutativity of certain operators should not be confused with a supposed general failure of associativity, or with the claim that all quantum logic is simply many-valued logic. In the usual lattices, meet and join retain lattice properties, including associativity and commutativity. The structure being studied must be specified before transferring its properties to an epistemological thesis.
Fuzzy sets: degrees of membership
A classical indicator function for a set A assigns the value 1 to its elements and 0 to the rest. In Zadeh’s formulation, a fuzzy set can be described by a membership function with values in the interval [0,1]. This tool represents graded categories, such as “high temperature,” once their context of use has been specified.
Classical and fuzzy membership
1A : X → {0,1}
μA : X → [0,1]
A degree of membership is not, in general, a probability. Saying that a value belongs to a fuzzy set to degree 0.7 is not the same as saying that there is a probability of 0.7 that it belongs to a classical set. The function can be constructed from expert knowledge, data, or learning procedures; fuzzy-set theory need not be defined as the imposition of assumptions external to the data.
Rough sets: indiscernibility and boundaries
In Pawlak’s classical formulation, a universe U and an equivalence relation R group together objects that are indiscernible on the basis of certain information. A set can be approximated from below and above through equivalence classes. The lower approximation brings together objects whose class is contained in the set; the upper approximation includes those whose class intersects it.
Pawlak approximations
Rlower(A) = {x ∈ U : [x]R ⊆ A}
Rupper(A) = {x ∈ U : [x]R ∩ A ≠ ∅}
BoundaryR(A) = Rupper(A) ∖ Rlower(A)
Uncertainty is related here to the resolution of information and the ability to discern objects. This differs from assigning degrees of membership to a category. Fuzzy-rough and rough-fuzzy extensions combine tools, but their terminology must be accompanied by definitions: the order of the adjectives is not enough to establish how a model is constructed.
Forms of uncertainty and possible representations
Problem
Representation
Condition to be made explicit
Variability of outcomes or uncertain information about events
Probabilistic model
Event space, measure, and interpretation.
Gradual membership in a category
Fuzzy set
The meaning and construction of membership.
Indiscernibility according to available attributes
Rough set
Indiscernibility relation and universe.
Conflict or plurality of descriptions
A logical or epistemological framework appropriate to the problem
What counts as a proposition, evidence, and consequence.
The contributions by Karmakar and Ganesan cited from ResearchGate are retained as part of the debate that motivated the original work. Their status is that of opinions and guidance in a forum, not a demonstration of the general superiority of an approach. Choosing between techniques requires examining tasks, assumptions, interpretability, available information, and performance beyond the data used to fit them.
The proposal of fractal logic
Bjorvand (1995) proposes an approach to intelligent systems connected with fractals, neuroscience, evolutionary computing, and set theories. The author himself distinguishes his proposal from a logic in the strict mathematical sense. It is retained for its exploratory interest and its place in the original discussion, without attributing to it an axiomatic apparatus or inference rules that the document does not establish.
Its inclusion distinguishes complete formalization, a heuristic program, and computational application. A proposal can be valuable as a design orientation before it constitutes a fully developed formal theory. Evaluating it requires asking which operations it defines, which problems it solves, and how its results compare with alternatives.
Statistical testing and scientific reasoning
The analogy between a hypothesis test and a reductio ad absurdum can be pedagogically useful if its limits are stated. An outcome improbable under a hypothesis is not a logical contradiction; a p-value does not represent the probability that the hypothesis is true. Fisher’s and Neyman–Pearson’s procedures also have different aims and structures, as Perezgonzalez (2015) explains.
Expert judgment, historical evidence, exploratory description, and study design are part of scientific reasoning. Gigerenzer’s 2004 critique of ritualized testing supports the need to think through the problem and report uncertainty. Recognizing that role does not turn an expert opinion into conclusive evidence or contextual reasoning into formal meta-analysis. Prior knowledge must be identifiable, discussable, and revisable.
Relationships, contradictions, and transformations
Wholes and parts
A whole is constituted through relationships between components and with an environment. Studying it requires delimiting the system and recognizing that this delimitation depends on a question. One description may treat the environment as a fixed condition; another may incorporate it as a dynamical variable. This decision has material consequences for what can be explained and predicted.
The expression “the whole is greater than the sum of its parts” may indicate the relevance of interactions, but it must be developed. In modeling terms, it is useful to identify which terms are lost through aggregation, which constraints emerge, and which collective observables are necessary. A sum may be appropriate for certain quantities while remaining insufficient to describe an organization; that difference does not refute the mathematical operation.
Dialectical contradiction and logical contradiction
Dialectical contradiction is used here to investigate tendencies or relationships that presuppose and stand in tension with one another within a process. Its content must be formulated materially: which forces, mechanisms, interests, or constraints intervene, through which relationships, and under which conditions they produce transformations. A logical contradiction, by contrast, consists in affirming and denying a proposition under the same conditions of meaning.
Divergence between two nearby trajectories does not automatically amount to an antagonistic contradiction. Nor does every negative feedback or competition between variables constitute antagonism in the sense of social theory. The proposed philosophical correspondence can be formulated as an interpretive hypothesis: certain dynamics make explicit tensions between mechanisms whose articulation produces qualitative changes. Each application must identify those mechanisms and the relevance of the term.
Necessity and contingency
Necessity may refer to consequences following from established relationships and conditions; contingency may refer to conditions that could have been different or whose occurrence is not fixed by the adopted level of description. In a deterministic model, evolution from a state can be unique while the choice of that state remains uncertain for an observer. This coexistence does not require attributing incompatible properties to the same object in the same sense.
Dependence on initial conditions, multiple scales, and the existence of disturbances make it possible to investigate how concrete events occur. The materialist position defended here recognizes that the limits of knowledge are part of a historical relationship with objective processes. A measurement limit, however, does not by itself imply a definitive thesis about the ontology of chance.
Quantity, quality, and bifurcations
A continuous variation in a parameter can produce a qualitative change in dynamics: loss of stability, the appearance of cycles, or a modification of basins of attraction. Bifurcations provide mathematical examples of how a quantitative transformation can relate to qualitative reorganizations. The content of that correspondence is determined through concrete conditions of stability and structure.
A dialectical interpretation finds a domain of dialogue here, although the existence of a bifurcation does not demonstrate a universal philosophical law. It matters to examine when the bifurcation occurs, whether the change is continuous or discontinuous in the relevant observable, whether hysteresis exists, and how fluctuations and perturbations intervene. Precision enables philosophy to guide testable questions and to be transformed by their results.
A reciprocal methodological requirement
A dialectical reading must accept that research will refine its categories and that some initial correspondences will prove inadequate. The criterion of usefulness is its capacity to reveal relationships, formulate hypotheses, explain transitions, and organize evidence. The breadth of a philosophical outlook increases its responsibility to distinguish domains, conditions, and levels of validation.
The unity of an interpretation is constructed by explaining the mediations between domains; the diversity of the sciences requires those mediations to be investigated.
A methodological proposition advanced in this essay
A scaling operation modifies the reference quantities used to describe an object. In certain phenomena, the transformation preserves a form or statistical relationship after the relevant values have been rescaled. Invariance does not mean that every quantity remains numerically identical; it may mean that quantities transform according to a homogeneous law.
Example of homogeneity
f(bx) = bα f(x), b > 0.
In this expression, α is a scaling exponent. If the relationship holds for any positive factor b within the relevant domain, one speaks of continuous scale invariance in this sense. If it holds only for factors belonging to a family such as b0n, with integer n, it is considered discrete invariance. This difference concerns the admissible scaling factors, not whether the system’s time is necessarily continuous or discrete.
A continuous-time model can exhibit discrete scale invariance, and a structure constructed by iterations can approximate statistical properties described by continuous laws. Spatial scale, temporal scale, instrumental resolution, and numerical integration step are concepts that must be distinguished. Representing a quantity in a computer does not by itself make the material phenomenon discrete.
Exact self-similarity, statistical self-similarity, and self-affinity
Exact self-similarity occurs when particular parts reproduce the structure of the whole through similarity transformations. Statistical self-similarity preserves distributions or statistical properties under scaling without requiring point-by-point coincidence. Self-affinity permits different factors for different directions or variables. The distinction matters for surfaces, time series, and trajectories whose axes represent different quantities.
As a conceptual example of statistical self-affinity for an appropriate process, one may write X(ct) ≍ cHX(t), where ≍ indicates equality in distribution in the specified sense and H is an exponent. The notation does not assert that two particular realizations coincide exactly. Nor does it allow a value of H to be assigned automatically to any irregular series.
Different texts use self-similarity and scale invariance as closely related or equivalent terms within a convention. The critical task is to identify that convention and the properties actually established. There is no need to invoke a supposed axiomatic opposition between continuity and discreteness to recognize differences between exact self-similarity, statistical scaling, and discrete scaling laws.
Mathematical fractals and natural structures
Cantor sets, the Koch curve, the Sierpiński triangle, and space-filling curves illustrate structures whose geometrical properties differ from those of elementary smooth figures. Some are constructed through exact iterations. Recursion provides a construction mechanism, but should not be used as a universal definition of fractality.
Figure 12aGeometrical constructions and iterative processes. Lesne and Laguës (2012). Original PDF, p. 31. The examples used to introduce scaling and dimension are retained. Reference.Figure 12bOriginal caption for the fractal constructions. Lesne and Laguës (2012). Original PDF, p. 31. The caption was a separate image in the file and is retained in full. Reference.
The retained figure from Lesne and Laguës includes constructions and dimensions that should be studied separately. The middle-thirds Cantor set has dimension log 2 / log 3; the Koch curve, log 4 / log 3; and the Sierpiński triangle, log 3 / log 2. In each case, dimension expresses a precise relationship between the number of parts and the reduction factor for an ideal construction, under appropriate similarity and separation conditions.
Similarity dimension · Appropriate constructions
D = log N / log(1/r), 0 < r < 1.
N: number of copies · r: reduction factor of each copy.
The formula is not a recipe applicable to any irregular shape. Hausdorff dimension is defined through measures constructed from covers; box-counting dimension studies the scaling of the number of boxes required to cover a set. They may coincide in important examples, but they are not identical by definition. Having an integer dimension does not, on its own, exclude all properties usually associated with fractals.
Box-counting dimension · When the limit exists
DB = limε→0 log N(ε) / log(1/ε).
Material structures have cutoff scales. A tree has branches of finite sizes; a vascular network has constituents and biological constraints; a coastline depends on the resolution at which it is measured. Scaling behavior observed over an interval does not prove that an ideal construction continues indefinitely. Measurement must report the range of scales, the fitting procedure, and its uncertainty.
An explicit example: the Koch curve
In the Koch construction, each segment is replaced by four segments, each one-third of its length. After n iterations, the number of segments is 4n, their individual length is 3−n times the initial length, and the total polygonal length is proportional to (4/3)n. The divergence of that length in the limit coexists with the curve’s location within a bounded region.
The example distinguishes length, boundedness, and dimension. It also shows that difficulty of measurement does not depend solely on an observer’s ignorance: certain properties follow from a completely known construction. For a natural object, by contrast, the empirical question is whether an interval exists within which a similar relationship adequately describes observations, and which processes generate that behavior.
Uncertainty, dimension, and knowledge
Fractal dimension is not defined as the number of properties providing incomplete information about a state. It is a geometrical property whose interpretation depends on the dimension used. Incomplete observation may make estimation difficult, but must be distinguished from what is being estimated. Uncertainty about a property and the property itself belong to different levels.
Likewise, a margin of imprecision does not automatically amount to a standard deviation. It may be expressed as absolute error, an interval of resolution, calibration uncertainty, probabilistic dispersion, or estimator bias. Using a standard deviation requires a relevant random variable or distribution and satisfaction of the conditions of its definition. Some distributions do not even have finite variance.
The most defensible philosophical application consists in recognizing that what is observed depends on scales and mediations, without concluding that all scales reveal an identical essence in every sense. Some mechanisms change in relevance as resolution varies; others require new collective variables. The unity of a material object does not guarantee uniformity in its description.
The continuum hypothesis and the limits of its relevance
Cantor’s continuum hypothesis concerns cardinalities: it states that no set size lies strictly between that of the natural numbers and that of the real numbers. The results of Gödel and Cohen establish its independence from ZFC under the corresponding consistency assumptions. This independence allows axiomatic extensions containing the hypothesis or its negation to be studied; it does not require assuming the hypothesis is true.
This problem is not equivalent to the physical continuum hypothesis. Nor does it establish a mathematical gap preventing the study of relationships between discrete and continuous structures. The theory of real numbers, limits, and differential equations can be developed within standard frameworks without resolving the continuum hypothesis. Axiomatic limitations and the limitations of a measuring instrument should not be identified with one another.
Gödel’s second incompleteness theorem concerns, under formal conditions, the impossibility for a sufficiently expressive consistent system to prove its own consistency internally in the relevant formulation. “Consistency,” “truth,” and “falsity of the system” are not interchangeable expressions. This result does not, by itself, demonstrate a general conclusion about what a finite being can know about an infinite reality.
The original investigation uses philosophical images concerning the finite and infinite, parts and wholes, and even, as an analogy, the theological relationship between creature and creator. Their place can be preserved as a reflective resource, distinguished from a mathematical premise. The same applies to the metaphorical reference to uniform convergence: in analysis, this has a precise definition that does not follow from several traditions expressing similar intuitions.
A small separation between trajectories may grow approximately exponentially in particular regimes and directions. This formulation assumes a scale on which the linearized approximation of perturbations is relevant. On a bounded attractor, separation does not grow indefinitely according to the same law: it eventually encounters the constraints of accessible space.
Local approximation of separation
‖δx(t)‖ ≈ ‖δx(0)‖ eλt.
The exponent λ describes a growth rate under specified conditions. If it is positive for the relevant direction or largest exponent, reducing initial error extends the time during which a desired precision is maintained. This does not necessarily eliminate the practical limit, because the temporal benefit depends on a logarithm.
Approximate prediction horizon
T ≈ (1/λ) log(Δ/δ0), λ > 0.
δ0: initial error · Δ: prediction tolerance.
As a purely pedagogical example, if λ = 0.5 per unit of time, δ0 = 10−6, and Δ = 10−1, the approximation gives T ≈ 23.03 units. Reducing the initial error by a factor of one thousand adds approximately 13.82 units. These values do not describe any of the empirical systems cited; they show the relationship between expansion rate, precision, and tolerance.
Exponentials and power laws
An exponential law has its variable in the exponent, as in eλt. A power law has a variable base raised to an exponent, as in xα. They are different functional forms and have different asymptotic behaviors. A semilogarithmic representation can help study an exponential, and a logarithmic representation on both axes can help study a power law, always with the corresponding statistical care.
The fact that two forms include the word “exponent” does not make them identical. This clarification is decisive for relating dynamical sensitivity, scaling laws, and critical phenomena. Each can offer a philosophical problem concerning transformations and limits, but interpretation must preserve the mathematical structure under examination.
What can be predicted over the long term
A point-prediction horizon does not amount to the impossibility of all long-term knowledge. Stable collective observables, invariant distributions, or estimable visitation frequencies may exist. The answer depends on the system’s properties and on the type of question: trajectory, distribution, transition, extreme, or response to a perturbation.
The physical time covered by a series must be distinguished from sample size. More observations can improve some estimates without equivalently extending the temporal horizon of a prediction. Nor does a densely recorded sample over a short interval always amount to prolonged observation of relevant states. Dependence between observations changes the information contributed by each additional datum.
A dialectical reading can investigate the coexistence of stable constraints and sensitive trajectories. The content of that coexistence does not require describing chaos as a mere appearance destined to disappear with greater knowledge. Sensitivity is a property of the model or regime under study; its epistemic consequences emerge when it is related to finite precision and prediction objectives.
In calculus, a critical point may refer to a location where a derivative vanishes or does not exist. In phase-transition theory, the term acquires another meaning: it relates to changes of state and singularities in the thermodynamic limit, together with specific collective properties. A maximum or minimum of an arbitrary function is not, on that ground alone, a critical phenomenon in this physical sense.
Temperature, an external field, or a concentration can act as control parameters, while an order parameter describes aspects of macroscopic organization. Near certain continuous transitions, a correlation length grows and scaling laws appear. These properties need not occur in every transition or in every complex system.
Lesne and Laguës provide a principal reference for this journey through transitions, turbulence, and fractal structures; Halperin’s 2019 note retains its role as a historical introduction to the theory of dynamic critical phenomena. Wilson’s development of the renormalization group is also incorporated to support the relationships between scale and universality.
Critical exponents
If τ = (T − Tc)/Tc is a reduced distance from a critical temperature, some quantities may display asymptotic power-law relationships. The following expressions outline particular critical regimes; their symbols and conditions must be specified for each model.
Examples of critical laws
ξ ∼ |τ|−ν · χ ∼ |τ|−γ
m ∼ (−τ)β for τ < 0, on the relevant ordered branch.
τrel ∼ ξz.
ξ represents a correlation length; χ, a susceptibility; m, an order parameter; and τrel, a relaxation time. The exponents ν, γ, β, and z describe different behaviors. The exponent β in a critical law must not be confused with a parameter called β in another model, such as the Lorenz system. The symbol ∼ expresses asymptotic behavior rather than an exact identity at any distance from the critical point.
These relationships allow investigation of the articulation between microscopic changes and collective responses. From a dialectical perspective, they provide a basis for asking about the mediations that make qualitative transformations possible. Identifying exponents directly with laws of antagonism between variables would omit the physical and mathematical conditions giving them meaning.
Universality and universality classes
Critical universality refers to shared scaling behaviors among systems differing in microscopic details under relevant common conditions. Dimensionality, symmetries, interaction range, and, for critical dynamics, conservation laws and slow modes can matter. Universality has a structure of classes and conditions; it does not assert that any system preserves all its properties at every scale.
Explanation through renormalization examines which perturbations or parameters remain relevant as scale changes. Some microscopic details affect amplitudes or corrections without affecting the dominant exponents of a class. It becomes possible to understand a correspondence between systems without assuming that their components or particular histories are identical.
The location, scale, and shape parameters of a statistical distribution do not define critical universality. Nor does increasing sample size by itself establish a universality class. Relationships between statistical limits, aggregation, and macroscopic laws deserve specific investigation, but must be distinguished from phase-transition theory.
The t distribution and inferential precision
The original reference to Student can be retained as an example of the importance of inferential conditions. For independent, identically distributed normal observations with unknown variance, the statistic standardized using the sample standard deviation follows a t distribution with n − 1 degrees of freedom. As those degrees of freedom increase, the family approaches the standard normal.
A result with specific assumptions
(X̄ − μ) / (S/√n) ∼ tn−1.
This relationship is not a general correction to short-term physics, nor does it identify prolonged observation with a large sample. If data are dependent or fail to satisfy the relevant model, the exact distribution above may no longer apply. The example teaches us to retain assumptions alongside a formula and to distinguish different meanings of “long term.”
Stochastic, critical, and complex phenomena
These three terms should not be arranged as though they formed a single hierarchy of increasing complexity. A stochastic process is characterized through a probabilistic structure; a critical phenomenon through particular transition and scaling properties; and complexity addresses problems of organization and description. They can intersect in different ways. Deterministic dynamics can display criticality, and a stochastic model can be relatively simple.
The discussion with Jaynes about probability and knowledge retains its philosophical relevance if the meaning of randomness is made explicit. The existence of effective probabilistic models does not by itself demonstrate ontological chance, and ignorance of causes does not demonstrate universal determinism. A controversy about the interpretation of probability cannot be settled merely by listing systems with fluctuations.
Why a collective description needs other variables
A many-particle system can obey microscopic laws while requiring collective concepts to explain its macroscopic behavior. Temperature, pressure, and order parameters are not merely alternative names for an individual trajectory. Their usefulness emerges when studying the organization and regularities of large ensembles.
Landau’s reflection on the appearance of statistical laws as the number of degrees of freedom increases retains its central role here. The autonomy of a collective explanation can mean that it uses its own variables, limits, and regularities. Determining its relationship of derivation from, or compatibility with, a microscopic theory requires consideration of the approximations and conditions involved in passing between levels.
Mean field and fluctuations
A mean-field approximation replaces certain effects of interactions with an average field or a simplified effective description. It does not generally consist in averaging the numbers of degrees of freedom of two models. It reduces the problem through an assumption about collective influence whose validity must be examined.
Near some critical transitions, fluctuations and long-range correlations can make an elementary mean-field approximation inadequate. It is not correct, however, to claim that mean field is invalid at every transition: dimensionality and other conditions may permit behavior of this type, including situations above an upper critical dimension. The importance of fluctuations is a concrete physical and mathematical problem.
Renormalization transformations
A renormalization scheme can integrate out or average over small-scale degrees of freedom and rescale the resulting description. The operation transforms parameters and couplings. Iteration studies a flow in a space of descriptions or theories, where certain fixed points organize large-scale behavior.
Outline of a scale transformation
g′ = Rb(g), Rb(g*) = g*.
δg′i ≈ byᵢ δgi, near a fixed point and in appropriate coordinates.
The parameters g describe couplings and b a scale-change factor. In a linearized description, perturbations with positive exponents can grow under the flow toward large scales and become relevant; others diminish. Marginal cases require further analysis. This vocabulary explains why certain details matter for a regime while others primarily affect corrections.
The historical designation “renormalization group” does not require every averaging operation to be invertible. Loss of detail can lead to a semigroup structure. This point is philosophically relevant: an effective description may retain enough information for some questions while losing it for others.
Three uses that must remain distinct
The original work draws on Lesne’s discussion of uses of the term renormalization. That plurality is preserved with more explicit delimitation. First, scale transformations and the elimination of degrees of freedom in critical phenomena and dynamics. Second, reduction to reference quantities or nondimensionalization, common in hydrodynamics and model comparison. Third, effective parameters or parameters corrected for interactions, associated with describing contributions that modify a reference quantity.
These uses can be related, but they are not interchangeable. Standardizing a column of data does not, by itself, amount to constructing a renormalization group. Eliminating a divergence in a perturbative expansion requires a specific theory and procedure. In classical and quantum electrodynamics, discussions of electron mass and charge must be situated within their respective formulations; the historical reference does not make the electron a generic example of ordinary classical mechanics.
A perturbative expansion is a controlled expansion in an appropriate parameter. It does not necessarily mean temporal evolution toward increasing complexity. Divergence of a series, a physical singularity, and trajectory sensitivity are distinct problems, although each may require revising approximations.
Dialectical interpretation and limits of extrapolation
The philosophical interest of changing scale lies in the fact that relevant relationships may be reorganized when a description changes. Explaining collective behavior may require retaining some variables and discarding others. This operation makes it possible to ask which aspects of a process persist, which are transformed, and under which conditions an effective theory is valid.
The analogy with the relationship between essence and appearance is useful if it avoids assuming that averaging over details always reveals a deeper truth. In some problems, reduction eliminates a decisive mechanism; in others, it identifies a robust regularity. The explanatory character of the operation is assessed through the questions it resolves and the evidence it organizes.
In the social sciences, transferring renormalization requires defining transformations, variables, and comparison criteria. Verbal resemblance between institutional scales and physical scales is insufficient. A materialist program can investigate this possibility without anticipating either the identity of mechanisms or the results of the analysis.
Consider a probability space (X, 𝔅, μ) and a transformation T preserving μ. In a common formulation, T is ergodic if every measurable invariant set has measure zero or one, with the relevant specification of invariance. This property rules out a nontrivial decomposition into invariant regions of positive probability with respect to the measure considered.
Ergodicity · A standard formulation
μ(T−1A) = μ(A).
T−1A = A, up to null sets ⇒ μ(A) ∈ {0,1}.
The measure is part of the specification. A dynamical system may possess several invariant measures, and properties must be attributed to the corresponding dynamics–measure pair. A finite record does not by itself demonstrate an asymptotic property; it may provide evidence consistent or inconsistent with concrete hypotheses.
The ergodic theorem and averages
For an integrable function, Birkhoff’s pointwise ergodic theorem establishes almost-sure convergence of time averages in a measure-preserving system. Under ergodicity, the limit agrees almost everywhere with the ensemble average. Without ergodicity, the general limit is related to conditional expectation with respect to the invariant information.
Birkhoff · Ergodic case
limn→∞ (1/n) ∑k=0n−1 f(Tkx) = ∫X f dμ, for μ-almost every x.
The equality does not assert that every microstate has equal probability, or that any finite trajectory exactly represents the average. Nor does it require expressing a whole as a linear sum of independent components. It is a result about averages along a dynamics and a measure, with assumptions that must be retained alongside its conclusion.
Equiprobability and statistical mechanics
The postulate of equal a priori probability is associated with the microcanonical description of an isolated system in equilibrium, given constraints such as energy, volume, and particle number. It must be distinguished from ergodicity. Under the usual thermodynamic convention, a closed system can exchange energy; an isolated system exchanges neither matter nor energy. The example therefore requires specification of the type of system.
Specifying energy and other macroscopic constraints does not amount to knowing the exact positions and momenta of every particle. The latter determines a microstate in a classical description. In a continuous space, speaking of equal probability for individual points likewise does not replace the definition of a measure on accessible regions.
The Princeton chapter cited in the original presents as a fundamental postulate a microscopic expression of entropy through accessible phase-space volume. That formulation must be distinguished both from immediately attributing equiprobability and from an ergodic hypothesis. Its relationship with equilibrium distributions requires development of the conditions of the argument.
Entropy and accessible states · Outline
S = kB log Ω.
Here Ω represents a count of states or an appropriately normalized, dimensionless measure of the accessible set, depending on the formulation. In the continuous case, that normalization must be specified; one does not simply take the logarithm of a dimensional quantity. A statistical formulation can be empirically fruitful without every use resting on the same demonstration of ergodicity.
Ergodicity breaking
Nonergodicity may arise when dynamics is organized into invariant components that do not explore one another in the manner required by the measure considered. There are also situations of extremely slow relaxation that prevent exploration of accessible regions within observational times. This practical difficulty must be distinguished from a structural absence of ergodicity in the mathematical limit.
An investigator’s lack of information does not by itself make a system nonergodic. It may prevent diagnosis of the property or selection of an appropriate measure. Likewise, chaos and nonergodicity are not synonymous: there are ergodic chaotic dynamics and nonchaotic dynamics with ergodic properties relative to particular measures. Mixing is another property requiring definition.
Introducing indicator or dummy variables into a regression can represent categories, institutional changes, or periods. It does not automatically restore ergodicity or turn a nonstationary series into a stationary one. The choice must follow from a hypothesis about the process, the design, and appropriate diagnostics. A statistical regime change and an ergodic decomposition are not the same concept.
Independence, exchangeability, and stationarity
Distinct properties of a sequence of variables
Property
Reference meaning
Clarification
Independence
The joint distribution factorizes in the sense of the probabilistic definition.
It does not amount merely to absence of correlation.
Exchangeability
The joint distribution is invariant under finite permutations of the indices.
It can coexist with dependence.
Strict stationarity
Finite-dimensional distributions are invariant under the relevant temporal shifts.
It does not mean arbitrarily interchanging times.
Ergodicity
Absence of a nontrivial invariant decomposition with respect to a measure; it permits particular relationships between averages.
It is not equivalent to equiprobability or independence.
McCullagh and Nelder’s observation about scales and the treatment of data remains relevant to examining what makes observations comparable. Equivalence of units, however, does not imply independence, and the fact that two observations belong to the same topological space does not determine their probabilistic dependence. The topological structure and the probability structure must be connected explicitly.
Exchangeability expresses a symmetry of a joint distribution, not permission to attribute an identical value or identical history to every observation. It may justify certain symmetric treatments under a model. In time series, order may contain indispensable information; permuting the data may destroy precisely the relationships being investigated.
An example: dependence through a common variable
Suppose that a random parameter Θ is first obtained and that, conditional on it, independent Bernoulli variables are then generated with success probability Θ. The sequence is exchangeable. Its variables are nevertheless marginally dependent when Θ varies: they share a source of variability.
Mixture example · Bernoulli
Xi | Θ independent with distribution Bernoulli(Θ).
Cov(Xi, Xj) = Var(Θ), i ≠ j.
X̄n → Θ almost surely, under this construction.
If Θ is not constant, the average of a prolonged realization converges to its particular parameter, not necessarily to E[Θ], the average mixing all realizations. The example clarifies why exchangeability and dependence can coexist, and why a time average is not always identified with an overall average. The shared variable organizes differences between realizations that indiscriminate aggregation can conceal.
Laws of large numbers under dependence
There is no single law of large numbers with independence as its universal assumption. There are families of results with different hypotheses. For an integrable stationary ergodic sequence, a result of this kind follows from the ergodic theorem. Other formulations use mixing conditions, martingale structures, or other restrictions. Dependence requires further investigation; it does not automatically eliminate the possibility of convergence.
The formulation of a law must indicate the limit to which the average converges. It may be a constant, a conditional expectation, or another random variable. Nor is it enough to say that systematic error is absent: probabilistic and integrability assumptions have a mathematical function that this general expression does not replace.
Central limit theorems under dependence
Ergodicity alone does not guarantee a central limit theorem. In a stationary setting with sufficient dependence and moment conditions, an asymptotic variance can incorporate covariances at different lags. The convergence and value of that variance require additional assumptions; they do not follow merely from formally writing a sum.
Outline of long-run variance · Under sufficient conditions
σ²LR = γ(0) + 2∑k=1∞ γ(k).
√n (X̄n − μ) ⇒ Normal(0, σ²LR), when the CLT applies.
γ(k) denotes an autocovariance and ⇒ convergence in distribution. The expression shows why treating dependent observations as independent can distort uncertainties. Long-range dependence, heavy tails, or regime changes may require different normalizations or limits. Evaluating a model must identify which result applies.
Nabi’s 2021 compendium on laws of large numbers and central limit theorems for dependent variables are retained as continuations of the original program. They must be consulted in the corresponding documents; the present essay develops the conceptual problem and shows reference conditions without attributing results to those texts that have not been reproduced.
Norms, losses, and reference quantities
The discrepancy expressions included at the end of the original investigation allow a further clarification. For finite vectors, the following are losses or distances based on different norms:
Discrepancies between observation and representation
S1(y, ŷ) = ∑i=1n |yi − ŷi|.
S∞(y, ŷ) = maxi |yi − ŷi|.
Sp(y, ŷ) = (∑i=1n |yi − ŷi|p)1/p, 1 ≤ p < ∞.
In this context these are ℓp norms on vectors; Lp spaces generalize the discussion to functions and measures. The infinity norm is not an Lp norm with a finite value of p. These expressions do not assume that ŷ is an arithmetic mean and do not establish exchangeability of a joint distribution.
If a single constant is sought to represent data, different losses may select different centers. The sum of squared errors is minimized at the mean; the sum of absolute errors at a median; and the maximum absolute deviation at the midpoint between the minimum and maximum. For the data 0, 0, and 9, those choices are 3, 0, and 4.5, respectively. The example makes visible that measuring discrepancy involves choosing which differences matter.
Dimensional consistency is necessary to interpret a loss. Comparing variables with different units or scales requires justification of weights or transformations. This decision is not merely aesthetic: it changes the relative importance of discrepancies. The philosophy of statistics finds here a concrete problem concerning how the aims of knowledge enter into the construction of an analytical instrument.
A materialist interpretation of the inferential problem
The philosophical contribution can be formulated more precisely as a critique of automatically generalizing observations beyond their conditions. Distributions, dependencies, and forms of aggregation represent material relationships under a research question. Their examination requires attention to time, shared mechanisms, and transformations of the population under study.
Ergodicity constitutes an important theoretical option within a broader class of probabilistic and dynamical structures. Investigating alternatives does not mean abandoning its definition or making it a generic name for a limitation of knowledge. The original program of expanding the foundations of inference gains precision when it identifies which assumption is relaxed and which result replaces it.
Measurement, models, and criteria for testing claims
Delimiting the object and the objective
An analysis of complexity begins by specifying which phenomenon is being studied and which question is to be answered. Describing a form, reconstructing dynamics, identifying a causal mechanism, forecasting an event, and comparing interventions are different tasks. Model selection must follow the problem and the available knowledge while also considering constraints on data and computation.
Delimiting a system establishes components, relationships, and an environment. It is useful to report which variables are observed, which remain latent, which constraints are maintained, and which mechanisms might change during the study. In social processes, subjects’ actions can alter institutions and relationships; in physical systems, an experimental modification can change the dynamical regime. In both cases, uncertainty about parameters must be distinguished from a modification of model structure.
Identifying relevant scales and times
Spatial resolution, sampling frequency, total observation time, and transient duration condition the results. A series may be extensive in its number of records yet short in time relative to the system’s relaxation. A regularity may exist within an interval of scales and disappear beyond it. These conditions must be part of the explanation rather than relegated to a technical detail without epistemological meaning.
One strategy is to compare results across justified resolutions and windows. The stability of an estimate under these decisions may support its robustness. Variation may reveal a regime change or a limitation of the estimator. Interpretation depends on mechanisms and testing designs, not on a preference for a more uniform result.
Separating uncertainties
Sources of uncertainty and the questions they raise
Source
Problem
Relevant examination
Measurement
Resolution, calibration, missing records, or artifacts.
Provenance, instruments, and sensitivity of the result.
Sampling
Selection of observations and dependence.
Design, coverage, autocorrelation, and precision.
Parameters
Unknown values within an assumed structure.
Identification, estimation, and appropriate intervals.
Model
Omitted variables or inadequate mechanisms or assumptions.
Comparison of structures and observable consequences.
Computation
Discretization, rounding, and numerical tolerances.
Numerical convergence and procedural stability.
Evolution of the process
A change in regime or material relationships.
Continued validity of the description and explanation of the change.
These sources can interact. Sensitivity to initial conditions can amplify measurement errors, while an incomplete equation can produce errors that do not disappear as instrumental precision increases. An interpretation of uncertainty must examine these relationships and avoid assigning every disagreement between model and observation to a single cause.
Making explanations comparable
Model evaluation must specify observables, fitting criteria, and prediction objectives. A good representation of a series does not guarantee a correct causal explanation. It is useful to study predictions other than those used to construct the model, analyze sensitivity to assumptions, and compare alternatives sufficiently flexible to address the same question.
In dynamical systems, comparison may include stability, bifurcations, the distribution of observables, responses to perturbations, and scaling properties. Using a single measure can conceal important disagreements. Multidimensional robustness requires selecting relevant dimensions and understanding what each measures; multiplying indicators without interpretation does not by itself produce a more solid assessment.
Giving categories operational content
If a configuration is proposed to express a relationship between form and content, one must identify which components change, how their interaction is organized, and which observables respond. If a contradiction is postulated, the mutually conditioning tendencies, the mechanism of their tension, and the expected transformations must be described. If a whole is invoked, the relationships justifying the system boundary must be stated.
These requirements do not reduce philosophical categories to a fixed list of variables. They allow examination of how the categories guide specific investigations. They also make it possible to revise a category when it fails to distinguish relevant situations or introduces an equivalence unsupported by the models. The relationship between practice and theory includes this capacity for correction.
History and the social conditions of knowledge
Scientific production depends on instruments, institutions, access to information, funding, training, and controversies. The availability of computers made it possible to investigate dynamics whose mathematical formulations already existed; Kepler’s records allowed stellar behaviors to be analyzed at a previously inaccessible resolution. These material conditions are part of the history of problems and of the evidence available.
Recognizing them does not imply judging a result’s validity by its author’s political position or explaining every controversy through external interests. A materialist analysis must examine arguments and procedures alongside the conditions of their production and circulation. The relationship between science’s internal and social dimensions requires concrete historical investigation.
An open research program subject to testing
A continuation of this work could study how explanation changes in a particular system when passing from microscopic variables to collective observables. Another line could compare which inferential results persist when independence or ergodicity is relaxed. A third could historically reconstruct the use of dialectical categories in identifiable modeling decisions.
In each case, it would be useful to formulate a bounded question, define a body of evidence, and make explicit which finding would support, weaken, or modify the hypothesis. This specificity allows philosophical breadth to become research that can be communicated and debated. It also facilitates comparison of the proposed perspective’s contribution with other methodological orientations.
Complexity as a problem of relationships and mediations
The history examined shows that determinism and prediction are not equivalent concepts. An evolution defined by laws can be sensitive to initial differences that no instrument measures with unlimited precision. This sensitivity does not eliminate every possibility of knowledge: it redirects attention toward observables, distributions, structures, and scales whose behavior can be investigated in other ways.
The interdisciplinary journey also shows that chaos, fractality, and complexity describe related problems without constituting a single property. Strange nonchaotic attractors distinguish geometry from exponential instability; critical phenomena articulate fluctuations and scaling laws; collective models require variables whose relevance cannot be recognized by observing isolated components. Each case retains conditions limiting its extrapolation.
The categories of essence, phenomenon, appearance, form, and content can guide an investigation of these mediations if they are defined and made open to discussion. Their usefulness lies in the questions they allow us to formulate and the relationships they help reconstruct. Identifying mechanisms, constraints, and transformations offers a more precise ground for dialogue between dialectics and the sciences than immediate equivalence between vocabularies.
The analysis of scale and renormalization shows how certain descriptions can preserve regularities while modifying the relevance of details. The analysis of ergodicity and dependence shows that inference requires distinguishing symmetries, averages, and probabilistic structures. These developments provide concrete tools for examining the unity and differentiation of levels within a reality investigated through finite, historical practices.
The materialist position defended here holds that reality constrains representations and that knowledge develops through revisable mediations. Dialectics offers an orientation for studying interactions, tensions, and transformations; the scope of each interpretation depends on its articulation with results and evidence. The sciences, in turn, allow that orientation to be refined and transformed.
Problems remain open concerning comparison between scales, the identification of mechanisms in historical systems, the interpretation of chance, and statistical results under forms of dependence. Their development requires specific models and studies. The investigation continues wherever a category becomes a precise question about material relationships, conditions of knowledge, and possibilities of transformation.
XVI · Reference apparatus
Glossary and clarifying notes
Attractor
An invariant set attracting states from a region under a specified definition and conditions.
Strange nonchaotic attractor
A geometrically irregular structure that does not exhibit chaos under the adopted dynamical criterion; it requires distinguishing exponents and forcing or response variables.
Bifurcation
A qualitative change in dynamics as parameters vary.
Universality class
A family of systems with shared scaling behaviors under relevant common conditions.
Coarse-graining or block description
The construction of variables or descriptions grouping together smaller-scale details.
Dialectical contradiction
A relationship between tendencies or determinations that condition one another and stand in tension within a process; it requires material specification.
Sensitive dependence
A property relating initial proximity to later separation according to a relevant mathematical definition.
Ergodicity
A property of dynamics relative to a measure that rules out a nontrivial invariant decomposition.
Phase space
A space whose points represent states of the modeled system.
Critical exponent
An exponent characterizing an asymptotic behavioral law near a particular critical transition.
Lyapunov exponent
An asymptotic rate of expansion or contraction of infinitesimal perturbations under appropriate conditions.
Fractality
A collection of geometrical and scaling properties requiring specification of the definition of dimension and observational regime.
Exchangeability
Invariance of a joint distribution under finite permutations of its indices.
Mixing
A property of loss of dependence between events separated by evolution, formulated relative to a measure.
Renormalization
A family of procedures whose meaning must be specified: scale transformations, effective parameters, or other related operations in a defined context.
Relaxation time
A temporal scale associated with the approach or response of an observable or distribution under particular conditions.
Supplementary historical and methodological notes
Recognition and contributions. Lewontin received the 2015 Crafoord Prize in Biosciences jointly with Tomoko Ohta. The recognition concerns contributions to understanding genetic polymorphism; its relationship with the author’s philosophical trajectory is an additional question. The prize should not be described simply as a category of the Nobel Prizes. The reference to Levins’s contributions to metapopulation theory and the study of organisms in changing environments is also retained.
Gould, Lewontin, and Levins. The discussions of spandrels, punctuated equilibria, and the critique of adaptationism belong to related but distinct contributions. Lewontin and Levins’s essay on Gould remains relevant to studying the relationship between intellectual commitment and scientific practice. The cited joint works must be distinguished from individually authored works and other collaborations.
Publication and consultation dates. A download date, website update, or translation date does not replace the year of the original article. The editions used in the 2021 paper are retained when identifiable, and verified corrections are indicated, including Sharma (2009), Werndl (2009), Lindner and colleagues (2015), and Laplace’s first publication (1814).
Documentary figures. Illustrations from the original paper retain their data, colors, and labels. Their colors belong to the source scientific material rather than the interface palette. Added captions delimit their scope; they do not update or recalculate the authors’ results. The panels and equation with repeated numbering are identified separately here.
Idealization and reality. A mathematical object can have an infinite scaling structure; a material observation has finite resolution and range. Comparing them requires a measurement model. This difference does not make a model arbitrary, but prevents unconditional identification of its ideal construction with the material object.
Logical terminology. The broad philosophical use of “formalization” to mean making something explicit is not equivalent to possessing a complete formal calculus. Likewise, criticizing a dichotomy applied to a phenomenon does not demonstrate that classical logic lacks the means to represent degrees, probabilities, relationships, or temporal evolution.
Expert judgment. Scientific experience can guide hypotheses and decisions. Its value depends on domain relevance, evidence quality, and the possibility of revision. Forum contributions are retained for their historical role in the argument and distinguished from articles and proved results.
Use of “meta-analysis.” A cross-cutting reflection on theories is not necessarily equivalent to the statistical procedure of combining study results. To avoid ambiguity, “epistemological analysis” or “research program” is used when that is the intended meaning.
Comparison with the original. The 2021 edition contains the formulations and extended quotations motivating this revision. A reference’s presence in the bibliography does not mean that all its claims are adopted; its function may be historical, conceptual, documentary, or critical.
The sources of the original investigation are retained, with additional references for the clarifications and expansions. Forum and popular-science entries are identified as such. Dates of consulted editions are distinguished from first publications where relevant. Incomplete references in the original paper are flagged without inventing publication details. Bibliographic titles are retained in the language of the cited work.
Bibliography of the original investigation, with clarifications
Aravindh, M., Venkatesan, A., and Lakshmanan, M. (2018). Strange nonchaotic attractors for computation. Physical Review E, 97, 052212. DOI.
Barnett, W. A., and Chen, P. (1988). Deterministic chaos and fractal attractors as tools for nonparametric dynamical econometric inference: With an application to the Divisia monetary aggregates. Mathematical and Computer Modelling, 10(4), 275–296. DOI.
Bjorvand, A. T. (1995). A New Approach to Intelligent Systems Theory. Norwegian Institute of Technology, University of Trondheim. Project report, April 28. Document.
Elert, G. (n.d.). Flow regimes. The Physics Hypertextbook. The original investigation records consultation in 2020. Resource.
Gottwald, G. A., and Melbourne, I. (2016). The 0–1 test for chaos: A review. In C. Skokos, G. A. Gottwald, and J. Laskar (eds.), Chaos Detection and Predictability, Lecture Notes in Physics, 915, 221–247. Springer. Authors’ version. Its pagination is independent of the book edition.
Halperin, B. I. (2019). Theory of dynamic critical phenomena. Physics Today, 72(2), 42–43. DOI.
Jaynes, E. T. (2003). Probability Theory: The Logic of Science. Cambridge University Press.
Kessler, D. P., and Greenkorn, R. A. (1999). Momentum, Heat, and Mass Transfer Fundamentals. Marcel Dekker.
Kilifarska, N. A., Bakmutov, V. G., and Melnyk, G. V. (2020). The Hidden Link Between Earth’s Magnetic Field and Climate. Elsevier.
Landau, L. D. (1994). Física teórica. Física estadística, vol. 5, second Spanish-language edition cited in the original investigation. Reverté. Identification of the volume, edition, and collaborators must correspond to the copy used.
Laplace, P.-S. (1814). Essai philosophique sur les probabilités. First publication. The original investigation also uses A Philosophical Essay on Probabilities (1902), an English edition. 1814 copy. Translation details in the original entry require comparison with the English copy’s title page.
Lesne, A. (1998). Renormalization Methods: Critical Phenomena, Chaos, Fractal Structures. Translated by Leila Schneps. Wiley. Contents published by the author.
Lesne, A., and Laguës, M. (2012). Scale Invariance: From Phase Transitions to Turbulence. Springer.
Li, S., and Li, H. (2006). Parallel AMR Code for Compressible MHD or HD Equations. Los Alamos National Laboratory. Technical resource cited in the original paper. Archived copy.
Lindner, J. F., Kohar, V., Kia, B., Hippke, M., Learned, J. G., and Ditto, W. L. (2015). Strange nonchaotic stars. Physical Review Letters, 114, 054101. DOI · Authors’ preprint.
Lorenz, E. N. (1963). Deterministic nonperiodic flow. Journal of the Atmospheric Sciences, 20, 130–141. DOI.
Mandelbrot, B. B. (1983). The Fractal Geometry of Nature. W. H. Freeman. Edition cited in the original investigation; the 1982 edition is distinguished when reconstructing the work’s history.
Marxists Internet Archive (n.d.). Formal Logic and Dialectics, in the resource The Meaning of Hegel’s Logic. The original investigation records 2018 as the resource or consultation date. Text. It is used as a philosophical intervention, not as proof of a mathematical impossibility.
McCullagh, P., and Nelder, J. A. (1989). Generalized Linear Models, 2nd ed. Chapman & Hall.
Nabi, I. (2021). Diferentes abordajes para el TCL con variables dependientes [Different approaches to the CLT with dependent variables]. La Biblioteca del Pueblo / El Blog de Isadore Nabi. Link recorded in the original investigation.
Nabi, I. (2021). Diferentes abordajes para la LGN con variables dependientes [Different approaches to the LLN with dependent variables]. La Biblioteca del Pueblo / El Blog de Isadore Nabi. Link recorded in the original investigation.
Oestreicher, C. (2007). A history of chaos theory. Dialogues in Clinical Neuroscience, 9(3), 279–289. Full text.
Pezard, L., and Nandrino, J.-L. (2001). Paradigme dynamique en psychopathologie: la «théorie du chaos», de la physique à la psychiatrie. L’Encéphale, 27(3), 260–268. Bibliographic record.
Poincaré, H. (1908). Science et méthode. Section on chance. The original investigation cites the English version, “Chance,” in Science and Method, pp. 64–90. Cited extract. The dates of the French work and its translation must be distinguished.
Princeton University Press (n.d.). The Fundamental Postulate. Chapter distributed as a publishing resource. Cited document. The 2021 entry does not identify the author or volume; it is retained without conjecturally completing those details.
ResearchGate (2018). When should one use Fuzzy set theory and Rough set theory? Is there any clear-cut line of difference between them? Forum; contributions include Sandipan Karmakar’s intervention. Discussion.
ResearchGate (2020). What is the difference between Fuzzy rough sets and Rough fuzzy sets? Forum; Ganesan G.’s contribution is cited in the original investigation. Discussion.
Rosental, M., and Iudin, P. (1971). Diccionario filosófico. Tecolut. San Salvador edition cited in the original investigation. The history of the work and its editions predates that year.
Russell, K. (2014). Hypothesis testing. Teaching material, University of Manitoba. Historical link recorded in the original. Its discussion is supplemented here with sources on the differences between statistical testing and logical deduction.
Sharma, V. (2009). Deterministic chaos and fractal complexity in the dynamics of cardiovascular behavior: Perspectives on a new frontier. The Open Cardiovascular Medicine Journal, 3, 110–123. DOI · Publisher’s text.
Stanford Encyclopedia of Philosophy (n.d.). Quantum Logic and Probability Theory. Resource cited in the original investigation with the date 2002. Entry. Its version may change; historically consulted content must be distinguished from later revisions.
Valdebenito, E. (2019). Fractales: la geometría del caos. Document deposited in viXra. Cited document. Retained as an expository source with a function distinct from the mathematical definitions and proofs used in this edition.
Werndl, C. (2009). What are the new implications of chaos for unpredictability? The British Journal for the Philosophy of Science, 60(1), 195–220. DOI. A later deposit date for a version does not replace the article’s year.
Supplementary sources and extensions
Birkhoff, G. D. (1931). Proof of the ergodic theorem. Proceedings of the National Academy of Sciences, 17(12), 656–660. DOI.
Cohen, P. J. (1963). The independence of the continuum hypothesis. Proceedings of the National Academy of Sciences, 50(6), 1143–1148. DOI.
Royal Swedish Academy of Sciences (2015). The Crafoord Prize in Biosciences 2015. Institutional announcement.
Evans, D. J., and Morriss, G. P. Statistical Mechanics of Nonequilibrium Liquids. Section 3.4: Ergodicity, Mixing and Lyapunov Exponents. ANU Press electronic edition. Section.
Gigerenzer, G. (2004). Mindless statistics. The Journal of Socio-Economics, 33, 587–606. DOI.
Grebogi, C., Ott, E., Pelikan, S., and Yorke, J. A. (1984). Strange attractors that are not chaotic. Physica D, 13, 261–268. DOI.
Johnston, H. (2015). “Golden stars” pulsate in a strange, non-chaotic way. Physics World, February 17. Popular-science source cited in a note in the original investigation. Article.
Lenin, V. I. (1909). Materialismo y empiriocriticismo [Materialism and Empirio-Criticism]. Work written in 1908; its composition is distinguished from first publication.
Levins, R., and Lewontin, R. C. (1985). The Dialectical Biologist. Harvard University Press.
Levins, R., and Lewontin, R. C. (2007). Biology Under the Influence: Dialectical Essays on Ecology, Agriculture, and Health. Monthly Review Press.
Lewontin, R. C., and Levins, R. (2002). Stephen Jay Gould—What Does It Mean to Be a Radical? Monthly Review, 54(6), November. Essay mentioned in the notes of the original paper. Journal issue.
Pawlak, Z. (1982). Rough sets. International Journal of Computer & Information Sciences, 11, 341–356. DOI.
Perezgonzalez, J. D. (2015). Fisher, Neyman–Pearson or NHST? A tutorial for teaching data testing. Frontiers in Psychology, 6, 223. DOI.
Wilson, K. G. (1983). The renormalization group and critical phenomena. Reviews of Modern Physics, 55, 583–600. DOI. Account related to his 1982 Nobel Lecture.
Zadeh, L. A. (1965). Fuzzy sets. Information and Control, 8(3), 338–353. DOI.
Euclid. Elementos [Elements]. Spanish-language edition of 1994 cited in the note on the golden ratio in the original paper. The definition of division in extreme and mean ratio is distinguished from other geometrical results mentioned there; volume and publication details are not completed without consulting the copy.
Documentary archive
Original 2021 investigation
The original Spanish paper retains all 54 pages, extended quotations, notes, equations, figures, and bibliography. It allows this edition to be compared with the initial formulations. The revised version develops clarifications and expansions in the body of the essay; the original file remains as a documentary record.
Consult the complete original Spanish paper
If the browser’s PDF viewer does not appear, use the download link below.
The edition is dominated by geopolitical tensions and technological advancements, with headlines covering South Korea's threat to sever ties with Ukraine, Brazil's investigation into Flávio Bolsonaro's potential flight, and breakthroughs in mathematics and physics by OpenAI.
· · ·
Economy & Politics
Irina: South Korea threatens to sever diplomatic ties with Ukraine after ambassador evacuation
Irina · single source
South Korea evacuated its embassy in Kiev and threatened to break off diplomatic relations with Ukraine because President Zelenski revealed secret details of a prisoner exchange deal, contrary to an agreement. This escalation follows a previous withdrawal of the ambassador, Park Ki-chan.
Irina: Security forces arrest Starobelsk student suspected of aiding Ukrainian forces with drone attack data
Irina · single source
Security forces in Starobelsk arrested a student who admitted to transmitting data on the city's administrative building to Ukrainian forces, leading to its destruction. The student also donated to a drone fund and attempted to form an informant group. The attack resulted in the deaths of 21 students and over 60 injured.
“Hands behind your head, you are under arrest.” (our translation)
RT en Español: US sees 'tipping point' in its new hypersonic missile
RT en Español · single source
RT en Español reports that the United States views its new hypersonic missile as a 'tipping point' after allocating $12 billion to hypersonic weapons since 2018 and signing a new contract with Lockheed Martin.
Bloomberg Politics: Israeli Opposition Head Eisenkot Leads Netanyahu After Vote
Bloomberg Politics · single source
Gadi Eisenkot, líder de la oposición, se adelantó a Benjamin Netanyahu en las primeras elecciones desde los ataques de octubre de 2023, lo que prepara un periodo de negociaciones tensas para formar el próximo gobierno.
Granma: Se prevé un déficit de 1 960 MW en el servicio eléctrico para hoy martes
Granma · single source
Se pronostica un déficit de 1 960 MW para el horario de máxima demanda, lo que implicará una afectación de 1 990 MW si se mantienen las condiciones actuales.
Rollo Chino: Dilraba Dilmurat, una estrella china de origen uigur
Rollo Chino · single source
Dilraba Dilmurat, actriz y modelo uigur nacida en Xinjiang, ha alcanzado gran popularidad en la industria del entretenimiento chino, combinando interpretación, moda y presencia en producciones televisivas.
r/ClaudeCode: 31B tokens into Claude Code, I realized a long chat should be a mind map, not a scroll
r/ClaudeCode · single source
El usuario desarrolló una herramienta de mapa mental para visualizar y gestionar sesiones largas de Claude, permitiendo responder directamente en el mapa y superar la dificultad de recordar información.
r/claude: Machines could gain control over humanity through gradual dependence
r/claude · single source
Theodore Kaczynski argued that as machines become more intelligent, humans may gradually delegate decisions to them, eventually leading to a point where machines effectively control society and humans cannot turn them off without self-destruction.
r/ChatGPT: OpenAI claims breakthroughs in mathematics, computer science, and physics
r/ChatGPT · single source
OpenAI announced three discoveries in harmonic analysis, complexity theory, and quantum field theory, including proving a major assumption in computer science wrong and solving a decades-old problem in mathematics, potentially reshaping human knowledge in these fields.
Marxist Philosophy of Science · Mathematical statistics
On Principal Component Analysis (PCA)
Geometric intuition, algebraic foundations, statistical interpretation, and the epistemological scope of dimensionality reduction
JOSÉ MAURICIO GÓMEZ JULIÁN
Representing a phenomenon through many variables allows a rich description, but can also make its principal relationships harder to identify. Principal component analysis—PCA—constructs new coordinates to study the joint variation of those variables. The decisive question is how to reduce a representation’s complexity without losing sight of what is preserved, what is discarded, and under which conditions its interpretation is legitimate.
Abstract
This essay develops PCA through four connected perspectives: a geometric transformation of a cloud of observations; a constrained optimization problem; a matrix decomposition; and a tool for scientific exploration and interpretation. It retains the gene-expression and financial-assessment examples, component-retention criteria, graphical diagnostics, Mahalanobis distance, the discussion of NIPALS, and the comparison with linear regression. Mathematical derivation, reproducibility, and the conditions supporting inference are expanded.
Editorial note. All thematic strands and 51 figures from the 2021 document are preserved. Formulations requiring greater precision are revised in the main discussion; the original images are collected without cropping in the visual archive and retain their attributions. The historical Spanish PDF remains available at the end.
I. Variables, attributes, and dimensionality
A dataset organizes observations of particular units of study: people, animals, firms, territories, products, or states of a physical system. Each unit is described by variables. When p numerical variables are recorded for n units, the usual representation is a matrix X of size n × p: rows correspond to observations and columns to variables. Each row can be interpreted as a point in the feature space ℝp.
The word attribute requires clarification. In data science it may designate a measured feature; in R it also refers to metadata associated with an object, such as its dimensions, names, or class. Adler’s observation about the importance of attributes in R objects is relevant to understanding their computational representation, but such metadata should not automatically be identified with the statistical variables in an investigation. A class attribute can change how R interprets an object without adding a dimension to the measured phenomenon. [1]
The dimensionality of a representation is the number of coordinates used. Intrinsic dimensionality, by contrast, refers to the degrees of freedom needed to describe the underlying structure under the model being considered. A cloud lying approximately on a plane may have many coordinates while still admitting an approximately two-dimensional representation. With noise, effective dimensionality also depends on the approximation tolerance. There is not always a single minimum number independent of the purpose of the analysis.
Variable selection and component extraction
Dimensionality reduction encompasses different strategies. Variable selection retains a subset of the original columns; feature extraction constructs new variables from them. PCA belongs to the second family: a component may combine information from all the initial variables. By definition, it does not identify which columns should be removed or solve a combinatorial search over subsets. Such problems can be connected to PCA, but they have different formulations.
This distinction also limits the meaning of “essential information.” In ordinary PCA, the operational criterion is the variance represented by a linear subspace. Whether that variation is essential to a biological, economic, or social explanation requires an additional argument about measurement, scale, context, and the research question.
II. Bellman, Pearson, and the problem of representation
The expression curse of dimensionality, associated with Richard Bellman, brings together difficulties that arise as the number of dimensions increases: growing computational costs for certain procedures, relative sparsity of observations, reduced effectiveness of some notions of neighborhood, and the need to impose structure on the problem. On a grid with ten positions per axis, systematically exploring p dimensions produces 10p combinations. This illustrates exponential growth; it is not a universal law requiring every statistical method to use exactly that amount of data. [3]
The difficulty depends on the problem, distribution, regularity, and relationships among variables. It is therefore useful to distinguish feature space from the sample space of probability theory: the former organizes observable coordinates, whereas the latter contains the possible outcomes of an experiment. They can be connected through random variables, but the concepts are not interchangeable.
In 1901, Karl Pearson studied lines and planes of closest fit to systems of points. His geometric approach approximates a cloud by a line or plane by minimizing the sum of squared orthogonal distances. Hotelling’s later formulation helped establish principal component analysis as a multivariate technique. This genealogy predates the contemporary vocabulary of machine learning. [11][22]
Historical context and scientific criteria
The original document politically characterizes Pearson as a Marxist. The question of the relationship between intellectual biography, the history of statistics, and philosophy of science is retained here, but that classification requires a dedicated historical investigation and is not used as a premise in deriving PCA. The method’s mathematical validity and the historical assessment of its author belong to different levels of argument that must be supported separately.
Pearson’s line provides a useful intuition: an elongated cloud can be described relatively accurately by a coordinate along its dominant direction. Identifying that direction, however, does not establish a cause of the phenomenon. The fit describes a structure of variation in the measurements; explaining it requires additional theory and evidence.
III. Definition and optimization of PCA
Let x be a random vector of p variables, μ its mean, and Σ its covariance matrix, assuming finite second moments. The first principal component is a linear combination of the centered variables with maximum variance, subject to a normalization constraint on its coefficients. In sample analysis, the population covariance is replaced by its estimate S.
PC1 = a1T(x − μ) = ∑j=1p aj1(xj − μj) maximize aTΣa, subject to aTa = 1.
The vector a₁ defines a direction; the component is the variable obtained by projecting onto it. The unit-length constraint prevents artificially increasing variance by multiplying all coefficients by a constant.
Without this constraint, multiplying a by an arbitrarily large number would increase the combination’s variance without bound. Normalization makes variation along different directions comparable. The second component maximizes the remaining variance, with a unit coefficient vector orthogonal to the first. The procedure continues successively.
ak ∈ arg max aTΣa subject to aTa = 1 and aTaℓ = 0 for ℓ < k.
Each new direction is chosen in the orthogonal complement of the preceding ones. This formulation characterizes the solution independently of the algorithm used to compute it.
The Lagrangian for the first direction is L(a, λ) = aTΣa − λ(aTa − 1). The stationarity condition leads to Σa = λa. The principal directions are therefore eigenvectors of the covariance matrix, and their variances are the corresponding eigenvalues. The first direction is associated with the largest eigenvalue; the remaining directions are ordered in decreasing order. If eigenvalues are repeated, a particular basis for the associated subspace may not be unique.
The mathematical interpretation has two levels. Eigenvectors specify how to combine the original coordinates; eigenvalues quantify variation along those combinations. Observation scores show where each unit of study lies in the new coordinate system. Keeping these three objects separate avoids confusing weights, observations, and amounts of variation.
The direction tells us how to look at the data; the score locates an observation in that view; the eigenvalue measures how much variation appears along it.
IV. Two genes and six mice
Following Josh Starmer’s teaching example used in the original document, consider six mice described by expression measurements for two genes. The mice are the units of study and the genes are the variables. Transcription is the synthesis of RNA from DNA; it must be distinguished from translation, which produces proteins. The quantities are retained as teaching values: no experimental unit or biological precision undocumented by the example is attributed to them. [13]
Original example data · transposed to show one observation per row
Mouse
Gene 1
Gene 2
1
10
6
2
11
4
3
8
5
4
3
3
5
2
2.8
6
1
1
In a two-dimensional plot, each mouse occupies the position defined by its two measurements. The first three have relatively high values for both genes, while the remaining mice have lower values. The cloud allows us to ask questions about covariation and grouping, but a figure alone does not establish population differences or causal mechanisms.
The first step in centered PCA is to subtract each variable’s mean. For these values, the mean of gene 1 is approximately 5.8333 and that of gene 2 is 3.6333. The centroid moves to the origin; differences between pairs of observations remain unchanged.
xijc = xij − x̄j Xc = X − 1x̄T.
The superscript c denotes centering; 1 is a column vector of n ones. Centering is not the same as dividing by standard deviations.
Starmer’s original sequence is preserved in full in the visual archive. The new figure shows the same six centered points, with the principal direction computed from the table and the orthogonal residuals involved in the fitting criterion.
Figure from the revised edition. Projections computed for the six mice in the table. Centering preserves distances; projection onto PC1 introduces the indicated residuals.
The example teaches the geometric mechanics. An actual gene-expression study requires attention to measurement, sequencing depth, appropriate transformations, batch effects, replication, and uncertainty. PCA on an unprepared count table may reflect technical magnitudes before biological differences of interest.
V. Transformations, structure, and preservation
A transformation is a mapping between spaces. It may be linear, affine, or of another kind. It need not map a domain into the same set: in general, we write f: D → C, and its image is the set of values actually reached in the codomain. For ordinary PCA, translations, orthogonal coordinate changes, and projections onto subspaces are especially important.
Transformations discussed in the original and their properties
Transformation
Characterization
Important distinction
Translation
x ↦ x + b
Preserves distances and differences between points; generally not linear because it does not fix the origin.
Rotation
x ↦ Qx, with QTQ = I and det Q = 1
Preserves inner products, norms, angles, and distances.
Reflection
An orthogonal transformation reversing orientation
Also preserves distances. An orthogonal matrix may combine rotations and reflections.
Uniform dilation or contraction
x ↦ cx
Multiplies all distances by |c|; an isometry only when |c| = 1.
Stretching along one or more axes
x ↦ Dx, with D diagonal
Changes relative geometry when scale factors differ.
Shear
A linear deformation that shifts coordinates according to other coordinates
May preserve area or volume in particular cases, but generally alters angles and lengths.
Orthogonal projection
x ↦ Px, with PT = P and P² = P
Generally not invertible; dimensionality reduction may contract distances and map distinct points onto the same point.
Isomorphism, homeomorphism, and isometry
An isomorphism preserves the specified structure: for example, addition and scalar multiplication in vector spaces. A homeomorphism is a continuous bijection with a continuous inverse. An isometry preserves distances; when also surjective, it establishes an equivalence between metric spaces. These notions are related, but none should be used indiscriminately in place of the others.
Preserving topology does not imply preserving a norm or metric: multiplying all coordinates by two provides an elementary counterexample. The transformation is a homeomorphism of ℝp and changes every nonzero distance. Similarly, a translation preserves distances without being a linear isomorphism under the original vector operations, unless it is the zero translation.
In an inner-product space, the Euclidean norm is defined by ‖x‖ = √⟨x,x⟩ and the induced distance by d(x,y) = ‖x − y‖. The norm measures vector length; the metric measures distance between points. Hilbert spaces generalize this framework to complete inner-product spaces. These extensions situate PCA within a broader mathematical landscape, but they do not justify transferring its properties to any normed space without proof.
The philosophical discussion of matter and form
The original reflection on Aristotle and Plato can be retained as a question about the connection between a system’s elements and the relations organizing them. This philosophical interpretation should nevertheless be distinguished from the mathematical definition of structure. Classifying objects “up to isomorphism” means grouping them according to a specified structural equivalence; it does not mean that they belong to any classification whatsoever or to none at all.
From a materialist perspective, mathematical abstraction can be examined as an operation that selects properties of concrete phenomena to study particular relations. The critical requirement is to state what is abstracted and what is preserved. In PCA, certain properties are preserved exactly under a complete orthonormal change of basis; others are only approximated when coordinates are discarded. Philosophical analysis becomes more precise when it starts from that distinction.
VI. Orthogonal projection and reconstruction
Let a be a unit vector defining a line through the origin, and let z be a centered observation written as a column vector. Its coordinate along that line is t = aTz. Its projection in the original space is ẑ = aaTz. The difference e = z − ẑ is perpendicular to the projection direction.
z = ẑ + e, ⟨ẑ,e⟩ = 0 ‖z‖² = ‖ẑ‖² + ‖e‖².
The Pythagorean theorem decomposes squared length into a represented part and a residual part.
For a fixed centered cloud, the sum of ‖z‖² over all observations is constant. Maximizing the sum of squared projected lengths therefore equals minimizing the sum of squared orthogonal residuals. This equivalence requires the same geometry, the same dataset, and comparison of subspaces of equal dimension.
∑i ‖zi‖² = ∑i ti² + ∑i ‖ei‖².
The two formulations do not distinguish an “analytical” PCA from a “numerical” one. They are mathematically equivalent objectives that can be solved using different algorithms.
Squaring is essential. Minimizing a sum of unsquared distances generally defines a different problem and may lead to another solution. Nor must components be computed through the Minkowski or Cauchy–Schwarz inequalities: these tools help prove properties of norms and inner products, but do not replace a specification of the optimization procedure.
A projection is a linear transformation that can be defined without choosing coordinates. Once a basis is chosen, it has a precise matrix representation; there is no opposition between a “purely mathematical” projection and a “merely computational” matrix. For a subspace whose orthonormal columns are collected in Vk, the projection matrix is Pk = VkVkT.
The original discussion of projective geometry is retained as context, with a qualification: the orthogonal projection of PCA belongs here to Euclidean geometry and linear algebra. It need not be conflated with the whole of projective geometry, whose historical development was collective and cannot simply be attributed to Lobachevsky.
In several dimensions, the criterion is written as minimization of the Frobenius norm of the reconstruction residuals. Approximation by the first k components is optimal among approximations of rank at most k under this quadratic loss. “Optimal” always means optimal for a declared criterion, not for every possible scientific purpose.
This identity uses eigenvalues of the sample covariance with divisor n − 1. To reconstruct the original coordinates, add the mean; if variables were standardized, also reverse the scaling.
VII. Slope, unit vectors, and components
The original geometric explanation uses a line with slope 0.25, represented by a displacement of four units along the first axis and one along the second. Its direction vector is (4,1)T. Its length is √17 ≈ 4.1231; dividing its coordinates by that length yields a unit direction.
The vectors have unit norm and zero inner product. The rounded values 0.97 and 0.242 in the original material illustrate this normalization.
The line can be written as y = 0.25x; its slope equals the derivative of this linear function. But the coefficients of a principal direction are not generally “derivatives of the phenomenon.” Here, slope is the ratio of the direction vector’s coordinates. The unit eigenvector contains a normalized representation of that direction and is determined by the covariance structure of the data.
Normalizing (4,1) does not standardize each observation or transform the data into a normal distribution. Nor does it make a cloud’s mean zero. It produces a unit-length vector. With that direction, an observation’s first centered coordinate would be approximately t1 = 0.9701x1c + 0.2425x2c; the second would be t2 = −0.2425x1c + 0.9701x2c.
Illustration and exact calculation
The direction (4,1) belongs to the original graphical explanation. Axes computed exactly from the six-mouse table may differ from that teaching slope. For traceability, the new figure and numerical table in this edition use the SVD of the transcribed values, while the visual archive preserves the original construction.
The Cauchy–Schwarz inequality guarantees that |⟨x,a⟩| ≤ ‖x‖‖a‖ and helps bound the length of a projection. The Minkowski inequality expresses the triangle inequality for Lp norms, with p ≥ 1. Pythagoras provides an exact identity when components are orthogonal in an inner-product space. These relationships serve different purposes; they are not three alternative algorithms for “finding” components.
VIII. Eigenvalues, eigenvectors, and SVD
For the centered matrix Xc, with observations in rows, sample covariance is S = XcTXc/(n − 1). This matrix is real, symmetric, and positive semidefinite. By the spectral theorem, it admits an orthonormal basis of eigenvectors collected as columns of V. Its eigenvalues are real and nonnegative.
S = VΛVT, VTV = I Λ = diag(λ1, …, λp), λ1 ≥ ⋯ ≥ λp ≥ 0 T = XcV, Cov(T) = Λ.
V describes the directions and T contains the scores. The diagonal matrix Λ contains the variances and expresses sample uncorrelatedness between different components.
The singular value decomposition of the data matrix provides the same centered PCA solution. In reduced form, if the rank is r, we write Xc = UΣsVrT, with U of size n × r, Vr of size p × r, and diagonal Σs of size r × r. The subscript distinguishes singular values from population covariance.
The singular values of Xc are square roots of the eigenvalues of XcᵀXc. To obtain component variances, the divisor n − 1 must be included.
What distinguishes the two decompositions
An SVD exists for any real rectangular or square matrix. Diagonalization by similarity requires a square matrix and is not always possible; for general matrices, eigenvalues may be complex and an eigenvector basis need not be orthogonal. These general qualifications, however, do not describe a difficulty of the covariance matrix in PCA: symmetry guarantees orthogonal diagonalization, and positive semidefiniteness guarantees nonnegative eigenvalues.
In a general diagonalization A = PDP−1, the outer matrices are inverses. In an SVD A = UΣVT, the matrices U and V have different roles and are not generally each other’s inverses. If rectangular, they do not even admit a two-sided inverse. In their complete square versions they represent orthogonal transformations; a reduced SVD contains orthonormal bases for subspaces.
The connection between eigenvectors and singular vectors is particularly direct in PCA, because the right singular vectors of Xc are eigenvectors of S. These are not two incompatible theories, but connected formulations for computing the same representation under the same centering and scaling conventions. [2][4]
Explained variance and discarded variance
ρj = λj/∑ℓ=1p λℓ Ck = ∑j=1k ρj, Rk = 1 − Ck.
ρj is the proportion explained by component j; Ck is the cumulative proportion in the first k; Rk is the fraction of variance excluded from that representation. Positive total variance is assumed.
The eigenvalue of a retained component represents variation preserved along that axis, not “lost information.” Reconstruction loss is related to the sum of discarded eigenvalues. This quadratic relationship does not turn variance into a universal measure of meaning, causality, or information in Shannon’s sense.
IX. Centering, standardization, and matrix choice
Centering subtracts the mean. Standardization by z-scores subtracts the mean and divides by each variable’s standard deviation. Vector normalization, in the sense used above, divides by a norm. These are different operations, although all may informally be described as changes of scale.
zij = (xij − x̄j)/sj, sj > 0 R = ZTZ/(n − 1).
If sj is computed using divisor n − 1, the sample covariance of Z is the original variables’ correlation matrix R. Constant columns require prior treatment.
The z transformation produces mean zero and unit variance under the convention used. It does not impose normality: a skewed distribution remains skewed after an affine transformation with positive scale. Descriptive PCA can be computed without assuming multivariate normality; certain tests, intervals, or control limits do require additional assumptions.
Two legitimate decisions with different objectives
Basis of analysis
Interpretation
Substantive decision
Covariances
Centered variables are analyzed in their measurement scales.
May be appropriate when units are comparable and variance differences are meaningful.
Correlations
The covariance of standardized variables is analyzed.
Gives each variable the same initial variance; often relevant with heterogeneous units, although it may also amplify unreliable variables.
A variable measured in thousands may dominate one measured in fractions if changing units increases its variance. But the magnitude of a variable’s mean does not, by itself, determine its variance. A scaling decision requires examination of dispersion, units, and purpose, rather than merely large or small absolute values.
Standardization changes the geometric problem by weighting the original coordinates differently. It should not be presented as a neutral operation that always improves analysis. It also matters whether standard deviation uses n or n − 1. In the same sample, consistently applying either divisor to all variables introduces only a common factor between the two standardizations; directions and explained-variance proportions coincide, but score magnitudes and variances change.
The connection to the same author’s essay on rescaling remains relevant. The web edition retains that link and emphasizes these distinctions so that both texts support each other without reproducing the confusion between standardization and transformation to a normal distribution. [9]
X. Orthogonality, uncorrelatedness, and rank
Two nonzero vectors with zero inner product are orthogonal and therefore linearly independent. The converse is false: two vectors may be linearly independent without being perpendicular. “Orthogonal” and “perpendicular” do not designate properties reserved for three and two dimensions respectively; orthogonality applies in any dimension within an inner-product framework.
For the coefficients of distinct components, ajTak = 0. For the principal variables, covariance is ajTΣak = 0. These identities are connected by the eigenvalue equation. They must not be confused with statistical independence, which requires factorization of the joint distribution.
A counterexample to independence
If U is uniformly distributed on [−1,1], the variables U and U² have zero covariance by symmetry, but U² is completely determined by U. The absence of linear correlation does not eliminate dependence. Under a joint normal distribution, however, uncorrelatedness between components does imply independence.
The number of components with positive variance equals the rank of the centered matrix. For n observations and p variables, that rank cannot exceed min(n − 1, p). A complete covariance decomposition can provide p eigenvectors, but some eigenvalues will be zero when there is linear dependence or insufficient sample rank.
Retaining a complete orthonormal basis of ℝp preserves Euclidean distances under the coordinate change. Retaining all positive-variance components also allows exact reconstruction of the observed centered cloud. With fewer components, the approximation generally leaves residuals; these vanish only when the data already lie in the retained subspace.
Axis order is fixed by eigenvalues, except for ties; sign orientation is arbitrary. Simultaneously replacing aj with −aj and reversing its scores describes the same solution. Isolated signs should therefore not be compared across programs without first aligning conventions.
XI. How many components should be retained?
Component retention is a methodological decision. It depends on the objective, measurement quality, and cost of discarding variation. A plane may be useful for visualization and insufficient for another task. The original document brings together Kaiser, Cattell, MAP, Bartlett, Horn, and Lawley; all are retained here, with their respective scopes clarified. [15]
Cumulative variance and reconstruction error
One may choose the smallest k reaching a previously justified variance proportion. Thresholds such as 80%, 90%, or 95% are conventional decisions, not guarantees of scientific sufficiency. In prediction, selection should be assessed against out-of-sample performance; in reconstruction, it can be justified through a tolerable error in the relevant units.
Kaiser (1960): eigenvalues greater than one
In correlation-based PCA, each standardized variable contributes variance one, and the mean of the p eigenvalues is one. The rule retains components with λ > 1, meaning those explaining more variation than an average standardized variable. This rationale does not automatically transfer to a covariance matrix with arbitrary units. The rule may retain too many or too few components and should not operate as an automatic decision.
Cattell (1966): the scree plot
The scree test looks for a change in slope between the first eigenvalues and a flatter tail. It offers a visual reading of diminishing returns. An “elbow” may be ambiguous; different readers may identify different cutoffs, and some spectra show no clear bend. The original suggestion to examine a baseline along the tail can be retained as a graphical aid, while making its interpretive element explicit.
Velicer (1976): minimum average partial (MAP)
The MAP criterion examines residual correlations among variables after successively removing components and normalizing residuals to obtain partial correlations. It seeks a minimum in the average of squared off-diagonal values. The intuition is to stop when removing further components no longer usefully reduces residual association and begins extracting specific structure or noise.
MAP should not be confused with choosing a percentage of variance or with a universal test of latent causality. The original source’s recommendation to have several high-weight variables can be useful for stable interpretation, but it is not a mathematical identity defining the criterion. Accessible implementations exist, including those documented in psych, so the practical claim that the method is difficult to access needs updating. [24]
The family of tests mentioned in the original evaluates hypotheses about the structure of remaining eigenvalues, such as their equality, under specific distributional assumptions and approximations. It is not the same as the familiar sphericity test applied to the complete correlation matrix. When used sequentially, the exact hypothesis, degrees of freedom, sample size, and stopping criterion must be stated.
Failure to reject a hypothesis does not prove it true: it may also reflect low power. Nor does every statistically significant result require adding a useful dimension. Interpretation must distinguish testing population structure from making a practical decision about representation.
Horn (1965): parallel analysis
Parallel analysis compares observed eigenvalues with those obtained under a random reference of the same size n × p. Simulation or permutation reproduces a setting of absent association according to an explicit mechanism. Components whose eigenvalues exceed the corresponding reference values are retained. It is necessary to state whether comparison uses means or a quantile, such as the 95th percentile, and how many replicates are generated.
The logic addresses a limitation of Kaiser: even when the population correlation matrix is the identity, sample eigenvalues fluctuate and will not all equal one exactly. One must also specify whether parallel analysis concerns components or common factors, because the matrices and comparisons are not identical. [25]
Lawley (1940): likelihood ratios and factor analysis
Likelihood-ratio procedures associated with maximum-likelihood factor analysis assess whether a given number of factors adequately reproduces a covariance or correlation structure under a probabilistic model. They are retained here as part of the original overview, but are not presented as an automatic property of descriptive PCA.
A common-factor model distinguishes shared variation from specific variation; PCA decomposes the total variation in the analyzed variables. Confusing components with factors may lead to criteria or interpretations being applied outside their framework. When software offers both procedures, it is important to check which has actually been run.
A documented decision
Report the primary criterion, compare it with another of a different kind, examine stability, and justify discrepancies. No rule replaces scientific judgment. If the objective changes from visualization to prediction or a latent-factor model, the appropriate choice of dimensions may also change.
XII. Interpreting the financial example
The document uses Minitab output based on eight variables: income, education, age, residence, employment, savings, debt, and credit cards. The eigenvalue table and complete coefficient matrix from that output are reproduced below. The labels require checking how each variable was measured or coded; “residence,” for example, does not by itself identify whether the measurement concerns duration, housing status, or something else. [6]
Eigenvalues, proportions, and cumulative variance · Minitab financial example
PC
Eigenvalue
Proportion
Cumulative
PC1
3.5476
0.443
0.443
PC2
2.1320
0.266
0.710
PC3
1.0447
0.131
0.841
PC4
0.5315
0.066
0.907
PC5
0.4112
0.051
0.958
PC6
0.1665
0.021
0.979
PC7
0.1254
0.016
0.995
PC8
0.0411
0.005
1.000
Complete coefficient matrix · rounding from the original output
Variable
PC1
PC2
PC3
PC4
PC5
PC6
PC7
PC8
Income
0.314
0.145
-0.676
-0.347
-0.241
0.494
0.018
-0.030
Education
0.237
0.444
-0.401
0.240
0.622
-0.357
0.103
0.057
Age
0.484
-0.135
-0.004
-0.212
-0.175
-0.487
-0.657
-0.052
Residence
0.466
-0.277
0.091
0.116
-0.035
-0.085
0.487
-0.662
Employment
0.459
-0.304
0.122
-0.017
-0.014
-0.023
0.368
0.739
Savings
0.404
0.219
0.366
0.436
0.143
0.568
-0.348
-0.017
Debt
-0.067
-0.585
-0.078
-0.281
0.681
0.245
-0.196
-0.075
Credit cards
-0.123
-0.452
-0.468
0.703
-0.195
-0.022
-0.158
0.058
The first three components have eigenvalues greater than one and account for approximately 84.1% of variation. The first two account for around 71.0%. Representing only PC1 and PC2 therefore leaves about 29% of total variation out of view: a two-dimensional plot is informative, but does not exhaust a three-component solution.
The relatively large positive coefficients for age, residence, employment, and savings in PC1 motivate the interpretation of long-term financial stability presented in the original. Among other contributions, PC2 contrasts education and savings with debt and credit cards. Under the chosen sign convention, the latter have negative coefficients; reversing the axis preserves the same structure. PC3 captures a different contrast, with substantial negative coefficients for income, education, and credit cards.
Names such as “stability,” “credit history,” or “academic and income qualifications” are interpretive summaries, not directly observed variables or automatically validated constructs. Supporting them requires examining all loadings, coding, and domain knowledge. A component does not become a valid indicator of risk, solvency, or behavior merely by receiving a plausible label.
How to calculate a score
Because the example uses a correlation matrix, its coefficients are applied to standardized variables. For a particular observation, the first score is obtained as follows:
The formula uses coefficients published to three decimal places; small differences from the program’s higher-precision internal calculation may occur.
As an additional teaching check, a hypothetical observation one standard deviation above the mean in age, residence, employment, and savings, and exactly at the mean of the other variables, would have an approximate score of 0.484 + 0.466 + 0.459 + 0.404 = 1.813. This is not an additional observation from the Minitab dataset: it illustrates substituting values into the linear combination.
Scores belong to observations; coefficients belong to directions. They are not entries of the same matrix under different names. If directions occupy the columns of V, the transformation for all observations is T = ZV. The principal space is the subspace spanned by retained directions; it should not be loosely identified with a particular matrix representing it.
XIII. Mahalanobis distance
An observation may be unremarkable in each variable separately yet unusual because of the combination of its values. If two variables usually increase together, a point high on one and low on the other may depart from the joint pattern even when neither marginal value is extreme. This is the intuition behind the original example.
DM²(x) = (x − μ)TΣ−1(x − μ) DM(x) = √DM²(x).
The formula assumes invertible covariance. For sample data, μ and Σ are replaced by estimates, and threshold interpretation depends on how those estimates were obtained.
Mahalanobis distance weights departure from the center while accounting for scale and covariation. In principal coordinates, if all eigenvalues are positive, squared distance is the sum of squared scores divided by their variances.
DM²(x) = ∑j=1p tj²/λj.
A modest deviation along a very low-variance direction may be more unusual than a larger deviation along a high-variance direction.
If covariance is singular, the ordinary inverse does not exist. A pseudoinverse, regularization, or a subspace model may be considered, but each option changes which departures the diagnostic detects. The pseudoinverse ignores null-space directions; consequently, a subspace-restricted diagnostic should be complemented by residual inspection when points outside that subspace are of interest.
Classical distance uses mean and covariance estimates that can themselves be affected by the outliers one intends to detect. It is not universally “more powerful” under every form of contamination or distribution. Its conceptual advantage over marginal inspection is incorporating the multivariate pattern, but performance depends on the estimator and model.
With known population parameters and multivariate normality, squared distance follows a chi-squared distribution with degrees of freedom equal to dimensionality. When parameters are estimated from the same sample, appropriate limits may require different corrections. A cutoff line should not be applied without stating its rationale.
XIV. The scree plot
A scree plot orders eigenvalues from largest to smallest and plots them against component number. It represents the spectrum of the covariance or correlation matrix being analyzed. The vertical axis should specify whether it shows eigenvalues, variance proportions, or a transformation of those quantities.
Figure from the revised edition. Eigenvalues from the original financial table; the dashed line marks Kaiser’s reference for correlation-based analysis.
The financial example shows a substantial decline across the first components and a later tail of smaller contributions. The original interpretation of retaining three components is consistent with Kaiser and a cumulative proportion near 84.1%. It does not show that the remaining five components have no possible relevance: they may contain contrasts important to a particular objective.
An approximately uniform spectrum suggests that no direction concentrates much variation; in that case, strong reduction loses a substantial fraction. A dominant eigenvalue suggests a direction of common variation, but does not by itself establish a single cause. Spectrum shape also depends on scaling and noise.
XV. The score plot
A score plot represents observations in the coordinates of two or more components. In the PC1–PC2 plane, each point is a unit of study, not an original variable. Axes should show the proportion of variation they represent, allowing readers to see how much of the cloud is visible.
The plot is examined for groupings, gradients, separations, extreme positions, and observations near the center. The original figure identifies a point in a lower corner as a candidate for investigation. Proximity to the edge of the plane does not automatically establish an error, a new group, or a statistically significant outlier.
Distribution around the origin follows from centering the scores. It is not a test of normality and does not imply a circular cloud. Each component has its own variance; unequal graphical scales can visually alter angles and distances. When the figure’s geometry matters, axis scales should be stated and an appropriate aspect ratio preferably maintained.
If two points are separated in the plane, they also differ in the full space. If they appear close, they may still differ in unrepresented components. Likewise, a projected grouping may be useful for exploration without establishing stable clusters, natural categories, or population differences.
Coloring observations by known experimental labels may help interpret the representation, but those labels do not enter the ordinary PCA calculation. If the explicit objective is to separate known groups, an appropriate supervised technique should be considered and validated out of sample.
XVI. The loading or “influence” plot
The document’s “influence” plot corresponds to a loading plot: it represents coordinates associated with variables on two components. Accompanying the traditional label with “loading plot” helps avoid confusion with observation-influence diagnostics in regression.
The term loading has no universal convention. Some programs display the unit eigenvector coefficients; others display coefficients multiplied by the square root of the eigenvalue, or variable–component correlations. The representation type must be stated before comparing magnitudes, interpreting lengths, or applying thresholds.
These identities use an unwhitened component and consistent covariance and scaling conventions.
A unit-eigenvector coefficient near zero indicates a small contribution to that particular linear combination; it does not declare the variable unimportant throughout the analysis. The variable may contribute to other components or to a question not captured by principal variance. Eigenvector coefficients lie between −1 and 1, but in many dimensions all may be far smaller than one without the component being irrelevant.
In the financial example, age, residence, and employment point toward PC1; debt and credit cards have substantial weight in the negative PC2 direction. Interpretation concerns the joint pattern of signs and magnitudes, including smaller loadings when they contribute a relevant contrast. Interpretive consistency should be examined under reasonable changes to observations, scaling, or variable selection.
XVII. The biplot
A biplot brings together markers for observations and variables in one figure. It is grounded in a factorization of the data matrix’s reduced-rank approximation, not an arbitrary overlay of two plots with different units. Starting from X̂c,k = UkΣs,kVkT, singular values can be distributed between the two sets of markers in different ways.
G = UkΣs,kα, H = VkΣs,k1−α X̂c,k = GHT.
The choice of α changes the scaling of observations and variables. Consult the software’s convention before interpreting distances or angles.
Observation positions help identify patterns; variable vectors or markers help relate them to the original measurements. Under appropriate scaling, inner products allow approximate reconstruction of centered values; certain variable orientations may approximate correlations. These readings depend on normalization and approximation quality in the displayed axes.
The financial figure retains the original readings of PC1 and PC2 and the suggestion to investigate the isolated point. The additional clarification is that PC3 also contributes appreciably and is absent from the plane. Apparent closeness between an arrow and a point should not be interpreted as an ordinary distance between objects of the same kind.
A biplot should report the input matrix, preprocessing, displayed components, represented variance, and marker scaling. Without this information, a visually convincing figure can support incompatible interpretations.
XVIII. The outlier plot
The original plot shows a Mahalanobis distance for each observation and a detection reference. No point exceeds the displayed limit. This specific result is retained without turning it into proof that the dataset contains no possible anomaly: the diagnostic concerns a particular metric and threshold.
An observation above a reference line is a signal to investigate. It may reflect a recording error, measurement failure, a unit from another population, an exceptional condition, or a real and scientifically important event. Automatic removal can erase precisely the variation requiring explanation.
It is useful to distinguish two positions: far from the center within the retained subspace, and far from the subspace itself. The first can be examined through a weighted score distance; the second through a reconstruction residual, frequently summarized by a residual sum of squares.
Dk²(x) = ∑j=1k tj²/λj, Q(x) = ‖xc − VkVkTxc‖².
A limit for Dk² does not replace a limit for Q. Their reference distributions and corrections depend on the model and application.
A defensible practice is to verify data provenance, correct demonstrated errors, document decisions, and compare results with and without disputed cases when appropriate. When many observations are examined, it also matters that a series of marginal thresholds can accumulate false alarms.
XIX. Numerical computation and NIPALS
The variational formulation defines the solution sought; the algorithm determines how it is computed. PCA can be obtained through eigendecomposition of covariance, SVD of the prepared matrix, iterative methods, or approximations designed for large matrices. Gradient descent is a possibility for certain formulations, not the mandatory mechanism “orchestrating” every PCA.
Computational approaches and implementation decisions
Procedure
Idea
Main consideration
Eigendecomposition
Diagonalize S or R.
Forming XTX can amplify conditioning problems; useful when the variable matrix has manageable size.
Direct SVD
Decompose the centered or standardized matrix.
Avoids explicitly forming covariance and directly connects directions, scores, and reconstruction.
Truncated iterative methods
Approximate only the leading components.
Require tolerances and convergence checks; useful when few axes are wanted.
Randomized SVD
Approximate the dominant subspace through projections and refinement.
Accuracy depends on the spectrum and parameters such as oversampling and iterations; fix the seed when repeatability is required.
NIPALS
Extract components successively through alternating updates and deflation.
Implementations may incorporate missing-value handling; convergence and assumptions must be stated.
Incremental PCA
Update an approximation in batches.
Reduces memory requirements, but algorithmic and batch details affect the approximation.
NIPALS, step by step
NIPALS stands for Non-linear Iterative Partial Least Squares. The algorithm’s historical name does not automatically make the resulting representation a nonlinear PCA. In its PCA application, it successively seeks rank-one approximations to the residual matrix. The original discussion remains useful for understanding loadings and scores. [4]
Prepare the data and define an initial residual matrix E = Xc, or E = Z if variables were standardized.
Choose a nonzero column of E to initialize a score vector t.
Update the direction using p = ETt/(tTt), and normalize p to unit length.
Update scores using t = Ep and repeat until a declared tolerance is met.
Store t and p, remove their contribution using E ← E − tpT, and continue with another component if appropriate.
This sequence describes the complete-data case. Some implementations adjust products and updates over observed values to handle missing entries. Replacing missing values with zeros is not sufficient, nor can every missingness pattern be assumed harmless. Identifiability, the amount of available information, and the missingness mechanism affect the result.
Sequential extraction allows computation to stop once enough components have been obtained. Deflation and rounding may also accumulate numerical errors; orthogonality, convergence, and reconstruction residuals should therefore be monitored. The claim that “most programs use NIPALS” should be treated as a historical observation from the cited source, not a general property of current software.
A reproducible report states the algorithm actually used. Saying only that “PCA was performed in Python” or “in R” does not identify the input matrix, centering, scaling, missing-value treatment, or retention criterion. Software facilitates computation but does not itself resolve design decisions.
XX. PCA and linear regression
The original comparison with linear regression clarifies two meanings of “best-fitting line.” In ordinary regression of y on x, coefficients minimize errors in the response variable, measured vertically in the usual plot. In two-dimensional PCA, the line minimizes the sum of squared orthogonal distances, treating the coordinates jointly under the chosen metric.
Regression of y on x: minβ₀,β₁ ∑i (yi − β₀ − β₁xi)² Rank-one PCA: min‖a‖=1 ∑i ‖zi − aaTzi‖².
The first formulation selects a response. The second approximates a centered cloud without designating a dependent variable.
The distinction is therefore not that regression “lacks any orthogonality.” In least squares, the residual vector is orthogonal to the space spanned by the design columns under the usual conditions. This algebraic property is not equivalent to measuring geometrically perpendicular distances from each point to a line in variable space.
PCA can be related to orthogonal regression or total least squares, but interpreting errors in all variables requires assumptions about their scales and measurement precision. Symmetry of the criterion does not make units irrelevant: changing one axis’s scale can change the principal line.
Principal component regression also exists, using scores as predictors. Selecting components solely by their variance can discard a low-variation direction informative about the response. The number of components should be chosen with the predictive task and independent validation in view.
Geometric association does not establish causality either. The distinction between description, prediction, and explanation must remain explicit even when both techniques share algebraic tools or representations through lines and planes.
XXI. Three genes and higher dimensions
The original example adds a third gene while retaining the same six mice. The first three-dimensional table contains the following data. The third coordinate shows how a structure barely visible in one plane may become clearer when another variable is examined.
Three-dimensional extension of the gene-expression example
Mouse
Gene 1
Gene 2
Gene 3
1
10
6
12
2
11
4
9
3
8
5
10
4
3
3
2.5
5
2
2.8
1.3
6
1
1
2
Each unit now occupies a point in ℝ³. PC1 identifies the direction of greatest variation; PC2 is chosen in its orthogonal complement, and PC3 completes an orthonormal basis. The plane formed by PC1 and PC2 provides the best two-dimensional approximation under the Euclidean quadratic criterion applied to the prepared data.
Mice 1, 2, and 3 have higher third-gene values than mice 4, 5, and 6. This pattern may contribute to separation in principal coordinates. But a component combines all three variables: it need not coincide with a particular gene’s axis. Examining its coefficients describes how much each measurement contributes to the resulting direction.
The final Starmer figures included in the document also show illustrative variants in which third-gene values change. These variants are preserved in the visual archive. Percentages labeled in them—for example, 91% and 4%, or 79%, 15%, and 6%—belong to the teaching scenes in which they appear; they should not be transferred to another table or preprocessing scheme as universal results.
To avoid that mixture, the numerical results added here are recalculated exclusively from the transcribed tables using covariance-based PCA: centering without standardization. The code below makes it possible to check how the results differ if correlations are used instead.
Recalculated results · centered data without standardization
Data
PC
Eigenvalue
Variance (%)
Cumulative (%)
Two genes
PC1
21.284012
96.3368
96.3368
Two genes
PC2
0.809321
3.6632
100.0000
Three genes
PC1
42.455970
95.7509
95.7509
Three genes
PC2
1.357664
3.0619
98.8129
Three genes
PC3
0.526366
1.1871
100.0000
Recalculated scores · two genes, covariance-based PCA
Mouse
PC1
PC2
1
4.719998
-0.826949
2
4.988861
1.392896
3
2.500152
-0.558086
4
-2.881249
-0.356784
5
-3.890244
-0.504866
6
-5.437518
0.853790
Sign convention: the first coefficient of each direction is nonnegative. For two genes, a₁ ≈ (0.941711, 0.336424)ᵀ and a₂ ≈ (0.336424, −0.941711)ᵀ. Reversing a direction and its scores preserves the result.
The same argument generalizes to p genes, even when the original space cannot be drawn. A table with thousands of variables and few observations admits a PCA calculation, but its sample rank is limited by n − 1. The existence of computable components does not guarantee that estimated directions are stable or faithfully reproduce those of a population.
Observed separations may be consistent with biological differences, but also with technical or preparation differences. Identifying gene 3 as “responsible” for a grouping requires distinguishing geometric contribution from causal mechanism. PCA helps discover questions and hypotheses; design and validation determine which explanations are supported.
XXII. Scientific scope and multidimensional interpretation
The interest of PCA extends beyond a data-reduction recipe. It allows us to study how multiple measurements can be organized through relations that do not coincide with isolated variables. This move from original coordinates to new combinations can be philosophically fruitful, provided that a statistical construction is not turned into a demonstrated ontological essence.
Relations, totality, and mediation
From a materialist reading, variables are measurements produced through concrete practices, and data express aspects of natural or social processes. Analysis of their covariation may reveal regularities that marginal inspection misses. Yet the totality of a phenomenon is not exhausted by a covariance matrix: nonlinear relationships, temporality, heterogeneity, historical conditions, and interaction mechanisms may also matter.
The idea of “essential relations” should be treated as an interpretive hypothesis requiring investigation. An eigenvector summarizes a mathematical structure of variation; attributing to it the status of a fundamental relation of the system requires connecting that structure with substantive theory and independent evidence. This separation strengthens philosophical discussion by making its mediations explicit.
Six dimensions of assessment
Assessing the method at complementary levels
Dimension
Guiding question
Mathematical
What objective is optimized, under which constraints and metric?
Geometric
Are coordinates being changed or directions discarded? Which distances are preserved?
Statistical
Do the sample, measurements, and stability support the observed regularities?
Computational
Which algorithm, tolerances, and data treatment produce the solution?
Substantive
Does the component interpretation make sense in biology, economics, or the domain studied?
Epistemological
Is the aim description, prediction, or explanation? Which inferential step needs additional evidence?
Applications and limitations
In biology, PCA can explore joint patterns of expression or morphology. In economics, it can summarize related series or indicators. In industrial processes, it can help monitor multivariate behavior. In images, it can approximate variation through a lower-dimensional basis. In every case, usefulness depends on the objective, data preparation, and component interpretation.
Major limitations include sensitivity to extreme observations, dependence on units and scaling, the inability of a linear model to fully describe curved structures, and the absence of an explicit class-separation objective. Ordinary PCA also does not automatically distinguish signal from noise or identify causal variables or latent constructs on its own.
Validation may include sensitivity to preprocessing, resampling to examine stability, comparisons between subsamples, residual inspection, and out-of-sample evaluation. When eigenvalues are close, individual directions may change substantially under small perturbations while the joint subspace remains more stable. In that case, evaluate the subspace rather than attaching excessive significance to the name of an isolated axis.
Finally, a low-dimensional representation should not be used to naturalize classifications of people or groups. The financial example illustrates a statistical operation; any decision-making use requires validation appropriate to the context, the meaning of the variables, and the consequences of the decisions.
Scope of the result
PCA identifies the directions of greatest linear variation in a chosen representation. Scientific knowledge additionally requires explaining why that representation is relevant, which relations it can capture, and what evidence supports interpretation of its patterns.
XXIII. Reproducible implementation in Python and R
Reproducibility requires preserving data, matrix orientation, transformations, algorithm, and conventions. The following examples recalculate the gene-table results. Python uses NumPy and direct SVD; R uses prcomp. Neither assumes group labels or uses screenshot percentages as inputs.
Both distinguish centering without scaling from centering with sample standardization. The covariance divisor is n − 1. Component signs may differ between implementations; directions should be aligned before comparing coordinates. With spectral ties, compare the subspace rather than necessarily comparing individual columns.
Python: computation and verification
"""PCA for the six-mouse example. Requires Python and NumPy."""
import numpy as np
X = np.array([
[10, 6], [11, 4], [8, 5],
[3, 3], [2, 2.8], [1, 1]
], dtype=float)
X3 = np.column_stack((X, [12, 9, 10, 2.5, 1.3, 2]))
def pca_svd(data, standardize=False):
"""Rows: observations. Sample scaling uses ddof=1."""
x = np.asarray(data, dtype=float)
if x.ndim != 2 or x.shape[0] < 2:
raise ValueError("At least two observations are required.")
if not np.isfinite(x).all():
raise ValueError("Resolve missing/nonfinite values before PCA.")
mean = x.mean(axis=0)
scale = x.std(axis=0, ddof=1) if standardize else np.ones(x.shape[1])
if np.any(scale == 0):
raise ValueError("Do not standardize constant columns.")
z = (x - mean) / scale
_, singular, vt = np.linalg.svd(z, full_matrices=False)
directions = vt.T.copy()
# Reproducible sign convention: nonnegative first coefficient.
signs = np.where(directions[0, :] < 0, -1.0, 1.0)
directions *= signs
scores = z @ directions
eigenvalues = singular**2 / (x.shape[0] - 1)
total = eigenvalues.sum()
if total <= 0:
raise ValueError("Total variation must be positive.")
proportions = eigenvalues / total
return dict(z=z, mean=mean, scale=scale,
directions=directions, scores=scores,
eigenvalues=eigenvalues, proportions=proportions)
if __name__ == "__main__":
np.set_printoptions(precision=6, suppress=True)
for label, data in [("Two genes", X), ("Three genes", X3)]:
for scaling in (False, True):
r = pca_svd(data, standardize=scaling)
v, t, lam = r["directions"], r["scores"], r["eigenvalues"]
print(label, "correlations" if scaling else "covariances")
print("Eigenvalues:", lam)
print("Explained variance (%):", 100 * r["proportions"])
print("Directions (columns):\n", v)
print("Scores:\n", t)
# Independent properties checking the published result.
assert np.allclose(v.T @ v, np.eye(v.shape[1]))
assert np.allclose(np.cov(t, rowvar=False), np.diag(lam))
assert np.allclose(t @ v.T, r["z"])
assert np.isclose(lam.sum(), np.var(r["z"], axis=0, ddof=1).sum())
for k in range(1, v.shape[1] + 1):
approximation = t[:, :k] @ v[:, :k].T
error = np.sum((r["z"] - approximation)**2)
assert np.isclose(error, (data.shape[0] - 1) * lam[k:].sum())
# Uncorrelatedness and independence are different:
# if U is uniform on [-1,1], Cov(U,U²)=0 by symmetry,
# although U² is determined by U; no simulated test is needed.
The checks verify orthonormal directions, diagonal score covariance, full-component reconstruction, and agreement between discarded variation and squared error. These identities detect transposition or scaling errors that a plausible figure may conceal.
R: the same sample convention
# PCA of the same data. Requires base R.
X <- matrix(c(10,6, 11,4, 8,5, 3,3, 2,2.8, 1,1),
ncol = 2, byrow = TRUE)
colnames(X) <- c("Gene1", "Gene2")
rownames(X) <- paste0("Mouse", 1:6)
X3 <- cbind(X, Gene3 = c(12, 9, 10, 2.5, 1.3, 2))
for (data in list(X, X3)) {
for (scaling in c(FALSE, TRUE)) {
fit <- prcomp(data, center = TRUE, scale. = scaling)
print(fit$sdev^2) # sample eigenvalues
print(100 * fit$sdev^2 / sum(fit$sdev^2))
print(fit$rotation) # directions
print(fit$x) # scores
reconstruction <- fit$x %*% t(fit$rotation)
stopifnot(max(abs(reconstruction -
scale(data, center=TRUE, scale=scaling))) < 1e-8)
}
}
# Signs may differ from Python without changing the solution.
# For parallel analysis, install psych if desired:
# set.seed(2026)
# psych::fa.parallel(X3, fa="pc", n.iter=1000, quant=.95)
# With six observations, this is an illustration, not an empirical recommendation.
The parallel-analysis example remains commented out because it requires the additional psych package. The function explicitly specifies components through fa="pc". A teaching sample of six units should not support recommendations about stable empirical groupings or population dimensionality.
Applying the model to new observations
A new observation is transformed using the means, scales, and directions fitted on training data. They are not recalculated using the test set. If PCA belongs to a predictive pipeline, its fit and all learned preprocessing must occur within each training partition of cross-validation. Otherwise information leaks from the evaluation set.
Tnew = ((Xnew − 1x̄trainingT)Dtraining−1)Vk.
D contains the standard deviations used when fitting the model. Without standardization, D is the identity.
In implementations such as sklearn.decomposition.PCA, centering and scaling are separate operations: PCA should not be assumed to standardize automatically. If StandardScaler is used, its default variance convention employs divisor n; state this when comparing exact magnitudes with R or the code above. Whitening is another transformation: it divides principal coordinates by a measure of their dispersion and changes output variances.
XXIV. Complete archive of the 51 original figures
This archive preserves every graphical element extracted from the PDF’s 49 pages, in order of appearance and without cropping their content. It includes Pearson’s historical figure, the transformation table, Starmer’s sequence, Dunn’s diagrams, and the results and plots from Minitab and Universidad Carlos III de Madrid. A visual filter integrates the color presentation into the article; each figure’s link opens the original PDF page in color.
Reading the historical material
The screenshots retain the labels and conventions of the original document, including the source languages. Where they call a sum of squares an “eigenvalue,” distinguish the eigenvalue of the cross-product matrix from a component’s variance. Where dividing by the hypotenuse is described as “standardizing,” that step concerns vector normalization. The clarifications in the main text govern interpretation of the notation. Percentages from different scenes should not be combined.
A. Pearson and geometric transformations · figures 1–5Original figure 01 · PDF, page 3. Orthogonal approximation line in Pearson’s historical illustration. Source: Pearson (1901); reproduced from Isadore Nabi’s document.View the original page in colorOriginal figure 02 · PDF, page 6. Expression of gene 1 in the six mice and calculation of its mean. Source: Starmer (2018); reproduced from Isadore Nabi’s document.View the original page in colorOriginal figure 03 · PDF, page 6. Expression of gene 2 and calculation of its mean. Source: Starmer (2018); reproduced from Isadore Nabi’s document.View the original page in colorOriginal figure 04 · PDF, page 7. Cloud center obtained from the two means. Source: Starmer (2018); reproduced from Isadore Nabi’s document.View the original page in colorOriginal figure 05 · PDF, page 7. Original table of geometric transformations and their characteristics. Source: Weisstein, Transformation (2021); reproduced from Isadore Nabi’s document.View the original page in colorB. Centering, fitting, and projection · figures 6–15Original figure 06 · PDF, page 8. Translation of the cloud to the coordinate origin. Source: Starmer (2018); reproduced from Isadore Nabi’s document.View the original page in colorOriginal figure 07 · PDF, page 9. Preservation of relative positions after centering. Source: Starmer (2018); reproduced from Isadore Nabi’s document.View the original page in colorOriginal figure 08 · PDF, page 10. First candidate line through the origin. Source: Starmer (2018); reproduced from Isadore Nabi’s document.View the original page in colorOriginal figure 09 · PDF, page 11. Rotation of the candidate line against the centered cloud. Source: Starmer (2018); reproduced from Isadore Nabi’s document.View the original page in colorOriginal figure 10 · PDF, page 11. Illustration of a projection between planes. Source: Weisstein, Projection (2021); reproduced from Isadore Nabi’s document.View the original page in colorOriginal figure 11 · PDF, page 12. Two fitting criteria expressed through projections. Source: Starmer (2018); reproduced from Isadore Nabi’s document.View the original page in colorOriginal figure 12 · PDF, page 13. Perpendicular residual and projected distance from the origin. Source: Starmer (2018); reproduced from Isadore Nabi’s document.View the original page in colorOriginal figure 13 · PDF, page 14. Right triangle connecting the observation, projection, and residual. Source: Starmer (2018); reproduced from Isadore Nabi’s document.View the original page in colorOriginal figure 14 · PDF, page 14. Pythagorean identity: constant total and complementary parts. Source: Starmer (2018); reproduced from Isadore Nabi’s document.View the original page in colorOriginal figure 15 · PDF, page 15. Decomposition of a vector into a score and a residual. Source: Dunn (2021); reproduced from Isadore Nabi’s document.View the original page in colorC. Sums of squares and principal direction · figures 16–25Original figure 16 · PDF, page 16. Choice of a candidate line for measuring fit. Source: Starmer (2018); reproduced from Isadore Nabi’s document.View the original page in colorOriginal figure 17 · PDF, page 16. Projection of an observation onto the candidate direction. Source: Starmer (2018); reproduced from Isadore Nabi’s document.View the original page in colorOriginal figure 18 · PDF, page 17. Distance from a projection to the origin. Source: Starmer (2018); reproduced from Isadore Nabi’s document.View the original page in colorOriginal figure 19 · PDF, page 18. Sum of squared projections for all six mice. Source: Starmer (2018); reproduced from Isadore Nabi’s document.View the original page in colorOriginal figure 20 · PDF, page 18. Comparison of directions and the maximum sum-of-squares criterion. Source: Starmer (2018); reproduced from Isadore Nabi’s document.View the original page in colorOriginal figure 21 · PDF, page 20. Direction vector with coordinates 4 and 1 and approximate length 4.12. Source: Starmer (2018); reproduced from Isadore Nabi’s document.View the original page in colorOriginal figure 22 · PDF, page 22. Normalization of the direction by dividing by its length. Source: Starmer (2018); reproduced from Isadore Nabi’s document.View the original page in colorOriginal figure 23 · PDF, page 22. Normalized coefficients for the illustrative gene combination. Source: Starmer (2018); reproduced from Isadore Nabi’s document.View the original page in colorOriginal figure 24 · PDF, page 23. Singular vector or eigenvector: principal-direction terminology. Source: Starmer (2018); reproduced from Isadore Nabi’s document.View the original page in colorOriginal figure 25 · PDF, page 24. Sum of squares and singular value: the original screenshot’s convention. Source: Starmer (2018); reproduced from Isadore Nabi’s document.View the original page in colorD. Second component and coordinates · figures 26–35Original figure 26 · PDF, page 24. Second direction perpendicular to PC1 in two dimensions. Source: Starmer (2018); reproduced from Isadore Nabi’s document.View the original page in colorOriginal figure 27 · PDF, page 25. Illustrative linear combination defining PC2. Source: Starmer (2018); reproduced from Isadore Nabi’s document.View the original page in colorOriginal figure 28 · PDF, page 25. Normalization of the second direction’s vector. Source: Starmer (2018); reproduced from Isadore Nabi’s document.View the original page in colorOriginal figure 29 · PDF, page 26. PC2 coefficients compared with those of PC1. Source: Starmer (2018); reproduced from Isadore Nabi’s document.View the original page in colorOriginal figure 30 · PDF, page 27. Loadings, scores, and sum of squares in the second direction. Source: Starmer (2018); reproduced from Isadore Nabi’s document.View the original page in colorOriginal figure 31 · PDF, page 28. Coordinate change for the mice into the PC1–PC2 plane. Source: Starmer (2018); reproduced from Isadore Nabi’s document.View the original page in colorOriginal figure 32 · PDF, page 29. Position of each observation according to its principal scores. Source: Starmer (2018); reproduced from Isadore Nabi’s document.View the original page in colorOriginal figure 33 · PDF, page 29. Conversion of sums of squares to variances using n − 1. Source: Starmer (2018); reproduced from Isadore Nabi’s document.View the original page in colorOriginal figure 34 · PDF, page 30. Illustrative explained variance and scree plot. Source: Starmer (2018); reproduced from Isadore Nabi’s document.View the original page in colorOriginal figure 35 · PDF, page 31. Geometric diagram of components and approximation in several dimensions. Source: Dunn (2021); reproduced from Isadore Nabi’s document.View the original page in colorE. Financial example and diagnostics · figures 36–43Original figure 36 · PDF, page 32. Complete financial-analysis output in Minitab. Source: Minitab (2019); reproduced from Isadore Nabi’s document.View the original page in colorOriginal figure 37 · PDF, page 35. Matrix expression of linear combinations of variables. Source: Universidad Carlos III de Madrid (2006); reproduced from Isadore Nabi’s document.View the original page in colorOriginal figure 38 · PDF, page 36. A marginally ordinary point that is unusual in the joint pattern. Source: Minitab (2019); reproduced from Isadore Nabi’s document.View the original page in colorOriginal figure 39 · PDF, page 37. Scree plot for the financial example. Source: Minitab (2019); reproduced from Isadore Nabi’s document.View the original page in colorOriginal figure 40 · PDF, page 38. Score plot for the financial example. Source: Minitab (2019); reproduced from Isadore Nabi’s document.View the original page in colorOriginal figure 41 · PDF, page 39. Loading plot, called an influence plot in the original. Source: Minitab (2019); reproduced from Isadore Nabi’s document.View the original page in colorOriginal figure 42 · PDF, page 40. Biplot for the financial example. Source: Minitab (2019); reproduced from Isadore Nabi’s document.View the original page in colorOriginal figure 43 · PDF, page 41. Distances and reference limit in the outlier plot. Source: Minitab (2019); reproduced from Isadore Nabi’s document.View the original page in colorF. Three genes and geometric extension · figures 44–51Original figure 44 · PDF, page 43. Table of three genes measured in six mice. Source: Starmer (2018); reproduced from Isadore Nabi’s document.View the original page in colorOriginal figure 45 · PDF, page 44. Addition of a third axis to feature space. Source: Starmer (2018); reproduced from Isadore Nabi’s document.View the original page in colorOriginal figure 46 · PDF, page 44. High third-gene values for the first three mice. Source: Starmer (2018); reproduced from Isadore Nabi’s document.View the original page in colorOriginal figure 47 · PDF, page 45. Low third-gene values for the last three mice. Source: Starmer (2018); reproduced from Isadore Nabi’s document.View the original page in colorOriginal figure 48 · PDF, page 46. Illustrative variant with greater separation associated with gene 3. Source: Starmer (2018); reproduced from Isadore Nabi’s document.View the original page in colorOriginal figure 49 · PDF, page 46. Weights of an illustrative combination in three-dimensional space. Source: Starmer (2018); reproduced from Isadore Nabi’s document.View the original page in colorOriginal figure 50 · PDF, page 47. Another principal direction and its weights in three dimensions. Source: Starmer (2018); reproduced from Isadore Nabi’s document.View the original page in colorOriginal figure 51 · PDF, page 47. Final variant with three explained-variance percentages. Source: Starmer (2018); reproduced from Isadore Nabi’s document.View the original page in color
XXV. Glossary and correspondence with the document
Vocabulary that keeps analytical levels separate
Term
Definition in this edition
Observation
A unit of study represented by a row of X and, after transformation, by a row of T.
Original variable
A measurement corresponding to a column of X.
Principal direction
A unit eigenvector of the chosen covariance or correlation matrix.
Principal component
A variable obtained as a centered linear combination along a principal direction.
Score
An observation’s value on a component.
Loading
A coefficient or variable–component association, according to the declared convention.
Eigenvalue
A component’s variance when referring to the corresponding covariance or correlation matrix.
Singular value
A nonnegative SVD quantity; its square is an eigenvalue of XcTXc.
Principal subspace
The space spanned by retained directions.
Projection
An observation’s orthogonal approximation within the subspace.
Residual
The difference between the prepared observation and its reconstruction.
Effective dimensionality
The number of directions considered sufficient under a declared approximation criterion.
Thematic correspondence · no original sections omitted
Content of the 2021 PDF
Development in this edition
I. General conceptual and mathematical foundations
I–III, VIII–X: attributes, dimensionality, Bellman, Pearson, linear combinations, constraints, and spectrum.
III.I–III.III. Results, eigenvalues, criteria, and components
XI–XII: all original criteria, the complete financial table, loadings, and scores.
III.IV. Mahalanobis distance
XIII: definition, geometry, spectral equivalence, singularity, and threshold assumptions.
III.V–III.IX. Scree, scores, loadings, biplot, and outliers
XIV–XVIII: all five diagnostics, their interpretation, and its conditions.
III.X. Final considerations
XIX–XX: NIPALS, other algorithms, and comparison with linear regression.
IV. Geometric intuition in ℝ³
XXI: three genes, six mice, graphical variants, and higher-dimensional extension.
V. References
XXVI: all original bibliographic entries, with editorial corrections and technical additions.
Document figures
XXIV: an archive of all 51 figures, with source page and access to the historical PDF.
Additional developments
Derivations, reconstruction, stability, epistemology, code, and traceability in XXII–XXIII and notes throughout preceding sections.
The discussion maintains the essay’s multidisciplinary ambition: connecting intuition, formalization, computation, and interpretation. Precise distinctions allow these perspectives to complement each other without attributing to a formula results belonging to another level of analysis.
XXVI. References and complete document
The original document’s bibliography is preserved. Jolliffe’s name and the editorial presentation of entries have been corrected; encyclopedic sources and forums remain as historical or teaching aids. The additions incorporate technical documentation and further academic work. Inclusion of a reference in the original is not presented as a new verification of its entire contents or as automatic support for every assertion it contains.
Adler, J. (2012). R in a Nutshell (2nd ed.). O’Reilly Media.
Alger, N. (2013, March 4). Intuitively, what is the difference between Eigendecomposition and Singular Value Decomposition? Answer on Mathematics Stack Exchange. Question and answers.
Bellman, R. (1972). Dynamic Programming (printing consulted in the original). Princeton University Press. Originally published in 1957.
Dunn, K. G. (2021). Process Improvement Using Data. Chapter 6: latent-variable methods; section on PCA. Author’s textbook. PDF document.
Jolliffe, I. T. (2002). Principal Component Analysis (2nd ed.). Springer.
Massachusetts Institute of Technology. (2011; consulted in 2021 in the original). Linear transformations and their matrices. MIT OpenCourseWare, Linear Algebra. Course and materials.
Nabi, I. (2020). Sobre los estimadores de Bayes, el análisis de grupos y las mixturas gaussianas [On Bayes estimators, cluster analysis, and Gaussian mixtures]. Unpublished document cited in the original edition.
Nabi, I. (2021, April 3). ¿Por qué se realiza un ajuste por re-escalamiento, normalización o estandarización sobre los datos en el contexto del aprendizaje automático? [Why are data rescaled, normalized, or standardized in machine learning?]. Marxist Philosophy of Science. Related article.
Nabi, I. (2021, April 2). Una interpretación multidisciplinaria de los espacios característicos, vectores característicos y valores característicos [A multidisciplinary interpretation of eigenspaces, eigenvectors, and eigenvalues]. Complete document.
Pearson, K. (1901). On lines and planes of closest fit to systems of points in space. The London, Edinburgh, and Dublin Philosophical Magazine and Journal of Science, 2(11), 559–572. https://doi.org/10.1080/14786440109462720.
Mathematics Stack Exchange. (2015, March 13). Understanding proof of isometry implies isomorphism. Discussion cited in the original. Its scope depends on the specified structures and surjectivity assumptions.
Starmer, J. (2018, April 2, according to the original reference). Principal Component Analysis (PCA). StatQuest. Cited video. Author’s material index. Source of the gene-expression teaching sequences.
Universidad Carlos III de Madrid. (2006, November 7, according to the original reference). Análisis de componentes principales [Principal component analysis]. Cited teaching material.
Universitat de Girona. (2002, January 24, according to the original reference). Número de factores a conservar [Number of factors to retain]. Material on factor analysis. Historical address cited. The reference is retained; the revised discussion distinguishes components from common factors.
Weisstein, E. W. (consulted in 2021). Projection. MathWorld, Wolfram Research. Reference article.
Weisstein, E. W. (consulted in 2021). Transformation. MathWorld, Wolfram Research. Reference article.
Wikipedia. (2020, version cited in the original). Curse of dimensionality. Encyclopedic entry.
Wikipedia. (2020, version cited in the original). Isomorfismo [Isomorphism]. Spanish entry.
Wikipedia. (2021, version cited in the original). Isomorphism. English entry.
Wikipedia. (2021, version cited in the original). Transcripción genética [Genetic transcription]. Encyclopedic entry. Transcription synthesizes RNA from DNA; translation produces a polypeptide chain from messenger RNA.
Hotelling, H. (1933). Analysis of a complex of statistical variables into principal components. Journal of Educational Psychology. Additional historical reference.
Jolliffe, I. T., & Cadima, J. (2016). Principal component analysis: a review and recent developments. Philosophical Transactions of the Royal Society A, 374, 20150202. DOI. Open-access full text.
Revelle, W. VSS: Very Simple Structure, MAP, and other criteria. Documentation for the psych package. Author’s documentation. Includes Velicer (1976), Determining the number of components from the matrix of partial correlations, Psychometrika, 41, 321–327.
Revelle, W. fa.parallel: Scree plots of data or correlation matrix compared to random matrices. Documentation for the psych package. Author’s documentation. Includes Horn (1965), A rationale and test for the number of factors in factor analysis, Psychometrika, 30, 179–185.
The historical document provides access to the original composition, color screenshots, and discussion as published in 2021. This English web edition expands the exposition and clarifies its mathematical, statistical, and philosophical distinctions while maintaining traceability between versions.
Political economy · Economic statistics · Methodological note
Product Redefinition and Reallocation in the U.S. Input–Output Matrix
Technology Assumptions and the Hybrid Procedure Used by the U.S. Bureau of Economic Analysis
JOSÉ MAURICIO GÓMEZ JULIÁN Originally published: Revised version:
· · ·
Abstract
An industry may produce goods and services with different input structures. To address this heterogeneity, the Bureau of Economic Analysis (BEA) combines the redefinition of selected secondary products and the reallocation of their inputs with a subsequent matrix derivation based on the industry-technology assumption. This note explains the procedure, distinguishes its component operations, and shows why it matters for interpreting interindustry relationships.
I. The Problem of Secondary Production
An industry need not produce only one type of good or service. A hotel, for example, may provide accommodation while also offering restaurant services. Although both activities belong to the same establishment, their requirements for food, labor, energy, and other resources may differ considerably.
In standard make and use tables, products are initially recorded under the industry that produces them. A distinction is drawn between primary products, which are characteristic of an industry, and secondary products. The difficulty arises when the input structure of a secondary activity differs substantially from that of the primary activity.[3]
The methodological question is therefore how to construct relationships between output and inputs that support the study of interindustry linkages without automatically assigning the same technology to heterogeneous activities. The procedure examined here addresses this problem by adjusting the industrial attribution of selected activities.
II. Two Technology Assumptions
Transforming the make-use system into a symmetric representation requires assumptions about the inputs attributable to secondary products. Two formulations are central: the industry-technology assumption (ITA) and the commodity-technology assumption (CTA).[1]
Table 1. What determines the input structure?
Assumption
Proposition
Implication
ITA Industry technology
Products made by an industry share its input structure.
Inputs to secondary production are estimated from the producing industry.
CTA Commodity technology
Each product has an input structure independent of the industry producing it.
Technology is associated with the product, even when it is secondary in its industry of origin.
Expository summary based on Guo, Lawson, and Planting (2002). ITA and CTA stand for industry-technology assumption and commodity-technology assumption, respectively.
These assumptions express different ways of representing production. They should not be interpreted as universal empirical identities. The choice affects the transformation of the tables and, consequently, the interpretation of the resulting coefficients.
III. The BEA’s Hybrid Procedure
In the documentation examined here, the BEA uses a hybrid approach: it combines selective adjustments informed by commodity technology with a subsequent derivation based on industry technology. It is useful to distinguish two broad stages without confusing them with the operations carried out within the first stage.[1][2]
First stage: redefining output and reallocating its inputs
Secondary products are selected when their inputs differ substantially from those of the primary product of the originating industry. Their output is attributed to the industry in which those products are primary: this operation constitutes the redefinition of output.[5][6]
The adjustment must be accompanied by the reallocation of the associated inputs, including intermediate inputs and value-added components. Moving output alone would leave the records of products and costs out of alignment. These adjustments produce the supplementary tables known as after redefinition tables.[2]
This stage approximates the CTA principle, but it does not amount to mechanically applying a pure CTA model to the entire economy. The manual also specifies that reallocations should use an input structure appropriate to the redefined activity, rather than necessarily applying the receiving industry’s entire input pattern.
Second stage: deriving the requirements tables
Starting from the adjusted tables, the mathematical derivation uses the ITA to handle the remaining secondary production. The existence of secondary products therefore does not imply that all must first be redefined: some remain in their producing industry and are treated according to this second assumption.[1]
Understanding the procedure
Standard tablesPrimary and secondary output is recorded in its industry of origin.
After redefinition tablesSelected secondary output is transferred and its associated inputs are reallocated.
Derivation of requirementsCoefficients and cumulative relationships are calculated using the specified technology assumptions.
Reading outline. The second item combines the two operations within the first stage; the third corresponds to the second broad stage.
IV. An Example: Hotels and Restaurants
The BEA uses restaurant services produced by hotels to illustrate redefinition from accommodation to food services.[3] The following example develops that idea using hypothetical figures in monetary units; it does not reproduce observations from the U.S. economy.
Table 2. Before redefinition
Industry / product
Accommodation
Restaurant services
Total
Accommodation
100
20
120
Food services
0
80
80
Total by product
100
100
200
The accommodation industry produces 100 of its primary product and 20 of restaurant services as a secondary product.
Table 3. After redefinition
Industry / product
Accommodation
Restaurant services
Total
Accommodation
100
0
100
Food services
0
100
100
Total by product
100
100
200
Restaurant output of 20 is transferred. Product totals and aggregate output remain constant; attribution across industries changes.
Suppose that this output of 20 is associated with 8 of food inputs, 2 of other intermediate inputs, and 10 of value added. When the output is redefined, these components must also be moved from the accommodation column to the food services column in the use table. The reallocated amount is 20, equal to the value of the transferred output.
Central idea · This note’s synthesis
Redefinition changes the industrial attribution of output while preserving product totals.
The procedure changes the statistical representation: the restaurant may continue to operate within the hotel. The receiving industry in the adjusted tables is an analytical category to which the corresponding output and inputs are attributed.
V. From Adjusted Tables to Requirements
Once the supplementary tables have been obtained, two distinctions must be kept separate: the distinction between direct and indirect effects, and the distinction between the domestic and imported origin of production.
Table 4. Two dimensions of interpretation
Dimension
Distinction
Production linkages
Direct requirements describe inputs used immediately. Requirements incorporating indirect effects also capture successive links in the supply chain.
Origin of production
Domestic requirements consider production within the country. The tables the BEA calls total requirements also incorporate the imported component.
In BEA terminology, “domestic” is not synonymous with “direct”: domestic requirements tables may also capture both direct and indirect effects. See Medeiros and Howells III (2017).
To construct domestic requirements, the BEA starts with intermediate uses after redefinition and subtracts the imported component. It then calculates direct coefficients and market shares, which it combines to obtain the different domestic requirements tables.[4]
A direct requirements table should therefore not be defined as though it already incorporated all indirect effects. These emerge when successive relationships between suppliers and purchasers are developed through the corresponding matrix structure.
VI. Scope and Methodological Interpretation
The purpose of these adjustments is to obtain a more homogeneous relationship between products and inputs. This analytical gain has a counterpart: industries after redefinition depart from the boundaries used in standard tables and from their immediate correspondence with the industrial classification. The BEA manual explicitly identifies this tension between homogeneity and classificatory consistency.[2]
An implication for analysis follows: before comparing sectoral coefficients or indicators, it is useful to check whether they come from tables before or after redefinition. The category “industry” does not necessarily retain the same statistical content in both representations.
Descriptive and predictive uses must also be distinguished. The tables may represent average technological relationships for a reference year. Using them to simulate large changes requires evaluating the assumptions of constant returns to scale and no input substitution, which may become restrictive when the hypothetical economy departs from the observed one.[4]
Greater homogeneity in a table does not, by itself, demonstrate that its coefficients describe invariant technologies. Economic interpretation requires attention both to the construction procedure and to the conditions of the particular application.
VII. Conclusions
The treatment of secondary production is a substantive methodological decision in constructing input–output tables. In the hybrid approach examined here, the first stage redefines selected activities and reallocates their inputs; the second uses the industry-technology assumption to derive requirements from the adjusted tables.
Redefinition changes attribution across industries while preserving product totals. The calculation of direct coefficients must, in turn, be distinguished from the derivation of cumulative relationships incorporating indirect effects. Neither of these distinctions can be replaced by the distinction between domestic and imported production.
Understanding these operations makes it possible to read the input–output matrix as a constructed representation of production relationships: a tool whose scope depends on its sources, classifications, and technology assumptions. That understanding is indispensable for a rigorous interpretation of interindustry relationships.
· · ·
VIII. References
Guo, J., Lawson, A. M., & Planting, M. A. (2002). From Make-Use to Symmetric I-O Tables: An Assessment of Alternative Technology Assumptions (WP2002-03). Paper presented at the 14th International Conference on Input-Output Techniques, Montreal. Full text at the BEA (PDF).
Horowitz, K. J., & Planting, M. A. (2006; updated April 2009). Concepts and Methods of the U.S. Input-Output Accounts. Bureau of Economic Analysis. In particular, chapters 4, 9, and 12. Methodological manual (PDF).
U.S. Bureau of Economic Analysis. (2011, May). Measuring the Nation’s Economy: An Industry Perspective. A Primer on BEA’s Industry Accounts. Revised version. Full document (PDF).
Medeiros, G., & Howells III, T. F. (2017, March). Introducing Domestic Requirements Tables for 1997–2015. Survey of Current Business. Bureau of Economic Analysis. Article and mathematical derivation (PDF).
U.S. Bureau of Economic Analysis. (2005, November 16). What are redefinitions, and where are they described? Frequently asked questions. Read the institutional explanation.
U.S. Bureau of Economic Analysis. (2018, April 13). Redefinition. Glossary. Read the definition.
Marxist Philosophy of Science Political Economy · Quantitative Methods
Empirical Research · United States
Measuring Sectoral Interrelationships in the U.S. Economy
An empirical methodology using make and use tables, 1997–2019
JOSÉ MAURICIO GÓMEZ JULIÁN
· · ·
Social production connects activities that, considered in isolation, appear independent. An industry transforms commodities produced by others; its own products, in turn, enter new production processes. Studying these connections requires linking the analysis of economic structure to instruments that make its relationships observable.
Abstract
This article presents a strategy for organizing annual make and use tables into comparable time series and constructing a descriptive indicator of the association between output and inputs. The original study used BEA data for 71 U.S. industries between 1997 and 2019, processing in R, and two levels of weighting applied to absolute correlations. This edition makes the notation explicit, distinguishes commodities from industries, and preserves the published figures as historical results subject to verification.
1997–2019Study period
71Industries
23Annual observations per complete series
01 / MotivationThe economic problem
From the standpoint of Marxist political economy, the study of branches of production acquires meaning within the reproduction of society as a whole. The division of labor multiplies specializations, but also the material connections required to sustain each activity.
The question guiding this research is how to develop an empirical approximation to the interconnectedness of production using disaggregated accounting data. Input-output accounts provide a particularly useful basis: they allow us to examine what is produced, what is used as an input, and how the uses of commodities are distributed.
The central theoretical antecedent is Kuroki’s discussion of the equalization of the rate of profit and technical interdependence in the volume edited by Semmler. The reference is to the 1986 publication of the proceedings of a conference held in 1985.[1] Connecting this discussion to an empirical indicator requires explaining which relationship is observed and how it relates to the model’s categories.
The empirical task is to make explicit the link between an economic category and the statistical operation used to study it.
It is therefore useful to distinguish three dimensions: the existence of production flows, their relative importance, and the temporal association between their magnitudes. These dimensions complement one another, but each answers a different question.
02 / Statistical foundationData and units of analysis
Reading the files correctly requires identifying the accounting framework. The BEA distinguishes the make and use tables of the make–use framework from the tables of the supply–use framework. In particular, a supply table includes imports and should not automatically be treated as synonymous with domestic production.[2]
Table 1. Orientation of the make–use framework used in this exposition
Object
Rows
Columns
Contents
Make table, V
Industries j
Commodities k
Output of each commodity by each industry.
Intermediate use table, U
Commodities k
Industries j
Inputs of each commodity used by each industry.
Industry output, x
One observation per industry
Vector
Total output of all commodities produced by an industry.
Source: the structure described in the BEA’s input-output accounts manual. Check the orientation of each exported table before using its totals.
Let vjkt denote the output of commodity k produced by industry j in year t, and let ukjt denote that industry’s intermediate use of commodity k. With this orientation, industry output is obtained by summing the industry’s row across the commodity block:
xjt = ∑kvjkt
(1) Gross output of industry j in year t.
The bottom totals row of a make table with this orientation reports commodity totals, whereas industry totals are obtained by summing across rows. Selecting a spreadsheet position without checking its meaning can change the variable being analyzed.[3]
The original screenshots identify tables after redefinitions and uses valued at producers’ prices. A replication must maintain consistent valuation, classification, and treatment of redefinitions across both tables and over time. Updates to a statistical database can revise its historical figures.
03 / PreparationFrom annual tables to time series
Data preparation consists of aligning identifiers and observations. A single year provides a cross section; successive years make it possible to construct a dataset with both industry and time dimensions. Each industry then has an output series and a series for each input category.
Select compatible tables.
Identify the data vintage, monetary units, aggregation level, and treatment of redefinitions. Separate the production blocks from rows and columns containing totals, value added, and final demand.
Obtain output by industry.
Construct each year’s vector x from verified industry totals. Retain codes as identifiers; names serve as descriptions.
Reorient the use block where useful.
Transposing U places industries in rows and commodities in columns. This facilitates combining records while preserving the meaning of each flow: it changes its position, not its economic nature.
Stack the years and align the keys.
Construct a table with one row per industry–year combination. Check that each combination appears only once and that inputs retain a consistent classification.
Construct comparable series.
For each industry, assemble output and each input over the same years. Record missing values, zeros, classification changes, and constant series before calculating correlations.
Calculate, weight, and retain the outputs.
Save signed coefficients, their absolute values, the observations used, the weights, and the aggregate indicators. Validation must make each result traceable to its input data.
Table 2. Working structure, with values represented symbolically
Year
Industry
Output
Input 1
Input 2
…
1997
j
xj,1997
u1j,1997
u2j,1997
…
1998
j
xj,1998
u1j,1998
u2j,1998
…
⋮
⋮
⋮
⋮
⋮
⋱
2019
j
xj,2019
u1j,2019
u2j,2019
…
A complete series has 23 observations. A balanced dataset with 71 industries and one row per industry–year contains 1,633 rows; the number of columns depends on the selected input block.
04 / MeasurementTemporal output–input association
For each pair consisting of an industry and a commodity used as an input, Pearson’s correlation is calculated between the two series. The time index runs through the comparable years; this is not a correlation across industries within a single year.
rjk = corrt(xjt, ukjt)
(2) Temporal linear association between industry output and use of commodity k.
The sign distinguishes movements in the same direction from movements in opposite directions. To summarize their intensity alone, we use ajk = |rjk|. Both matrices should be retained: a large negative coefficient contains economic information that disappears when its absolute value is taken.
Pearson’s correlation is undefined for a constant series. A flow that is zero in every year should likewise not automatically be assigned a correlation of zero. When data are missing, the number of observations underlying each coefficient must be reported, and an explicit comparison rule must be maintained.
05 / AggregationThe two levels of weighting
Weighting incorporates the economic importance of flows. The first level summarizes each industry’s association with its inputs; the second aggregates the industry results.
First level: input composition
Sj = ∑kwjk |rjk|
(3) wjk ≥ 0 and ∑k wjk = 1 for every industry j.
Because each correlation summarizes several years, the weights must represent an explicitly defined temporal distribution. One can select a reference year, average annual shares, or calculate shares from cumulative flows. These choices can produce different results.
One possible convention for a new replication is to use shares based on cumulative flows over the period:
wjk = ∑tukjt∑t ∑huhjt
(4) Illustrative fixed-weight convention; it is not attributed to the original script. It requires admissible nonnegative flows and a positive denominator.
When a correlation is undefined and its input has a positive weight, the series must be reviewed, or its exclusion and the renormalization of the remaining weights must be made explicit. Removing missing values without adjusting the denominator changes the indicator.
Second level: industry shares
S = ∑jqjSj
(5) qj ≥ 0 and ∑j qj = 1. The economic variable determining each industry’s share must be stated.
For example, qj could be defined as the industry’s share of cumulative gross output across all included industries. This choice must also be documented and distinguished from weighting by value added.
The equations above specify a family of indicators. Their exact application depends on the selected weights and data coverage. With normalized nonnegative weights, the sectoral and overall indicators necessarily lie within the interval [0, 1].
06 / Worked exampleInterpreting the weighting
Consider an industry with two input categories. The first has a correlation of 0.90 with output and accounts for 80% of its inputs; the second has a correlation of −0.20 and accounts for the remaining 20%.
SA = 0.80 × |0.90| + 0.20 × |−0.20| = 0.76
A hypothetical example explaining the operation; this is not a BEA estimate.
The simple mean of the two magnitudes would be 0.55. The weighted result is higher because the stronger association corresponds to the input with the larger share. Weighting expresses an economic choice; an increase in the indicator does not, by itself, improve the evidence.
If another industry scores 0.40 and the industry shares are 0.60 and 0.40, respectively, the overall indicator is:
S = 0.60 × 0.76 + 0.40 × 0.40 = 0.616
The result lies between the two industry indicators being aggregated.
07 / Published evidenceResults and verification note
The R outputs reproduced in the original publication show the following figures. They are transcribed to preserve documentary traceability; this edition neither recalculates the dataset nor certifies that the results have been reproduced.
Table 3. Figures reported in the 2021 screenshots
Stage
Reported value
Documentary interpretation
Mean of absolute correlations
0.6837338
Summary before economic weighting.
Mean of industry indicators
0.7351034
Output associated with the first level of weighting.
Correlation r must also be distinguished from the coefficient of determination R2. An average of absolute correlations cannot be presented as a proportion of explained variance. The familiar relationship R2 = r2 applies to simple linear regression with an intercept, not to this aggregation of multiple pairs.[4]
Finally, describing a correlation as “strong” requires a contextual criterion. If 0.70 is chosen as a descriptive reference, its distance from 0.6837338 is 0.0162662 indicator units. Proximity to that threshold neither replaces validation of the calculation nor establishes an economic conclusion.
08 / DiscussionInterpretation and scope
What this strategy can investigate
Once the data and calculations have been validated, the procedure allows comparisons of industry profiles of temporal association and an examination of how their synthesis changes when economic weights are introduced. Its usefulness also lies in making the passage from accounting tables to time series and indicators traceable.
Checks that would strengthen inference
Prices and trends. Examine how much of the association between monetary magnitudes reflects price changes or common trends. Depending on the question, compare levels, deflated series, growth rates, or justified time-series specifications.
Temporal dependence and stability. Examine autocorrelation, influential observations, and possible breaks. Statistical tests must respect the temporal structure of the data.
Aggregation decisions. Compare weights and coverage, retain sign information, and document the treatment of commodities associated with the industry’s own sector.
Structural content. Compare the indicator with measures based on flows and production requirements. Temporal comovement and the technical intensity of a linkage are distinct dimensions.
These checks are proposed extensions. They are not presented as tests already performed in the 2021 study.
Correlations between trending series can invite misleading interpretations; time-series techniques help distinguish these movements from more stable relationships.[4] Gross output also incorporates intermediate inputs within an accounting identity. This connection must form part of the economic interpretation of the result.
The connection to Marxist debate
Empirical research can contribute to debates on reproduction, competition, and the interconnectedness of branches of production. Connecting this indicator to the dynamics of the rate of profit requires justifying the step from observed association to the technical interdependence relevant to the model.
The United States provides a relevant setting for investigation. Its analysis alone neither establishes a universal regularity nor verifies every condition of a theoretical result on stability. Comparisons across periods, countries, and structural measures would allow the generality of the hypothesis to be assessed.
A study becomes stronger when its data, its operations, and the scope of its conclusions can be examined separately.
The contribution worth developing is a reproducible strategy for organizing production data and examining a hypothesis about economic interconnectedness. Reviewing the published calculation and conducting robustness checks are the next steps toward consolidating that contribution.
09 / MaterialsReplication and traceability
The materials archive linked at the end corresponds to the resource provided by the authors in the original post. A complete replication should retain both the downloaded files and the transformations produced by the code.
Record the source: download date, data vintage, tables, units, valuation, and industry and commodity codes.
Verify alignment: unique keys, annual coverage, classification changes, and correspondence between output and uses.
Audit the coefficients: variation in the series, number of observations, missing values, and the range of each correlation.
Audit the weights: temporal definition, positive denominators, nonnegative weights, and a sum of one at each level.
Publish the outputs: signed and absolute-value matrices, weights, sectoral results, and the overall aggregate, together with the versions of R and its packages.
Range checks are especially useful: an indicator of the form described must remain between zero and one. If an output violates that property, interpretation should pause while the operation generating it is located.
10 / SourcesReferences and further reading
Sources for this edition
[1] Kuroki, R. (1986). The equalization of the rate of profit reconsidered. In W. Semmler (Ed.), Competition, instability, and nonlinear cycles (pp. 35–50). Springer. Publisher’s record. Conference held in March 1985; publication year corrected according to the publisher.
[2] U.S. Bureau of Economic Analysis. (n.d.). Guide to the interactive industry input-output accounts tables. Read the guide.
[3] U.S. Bureau of Economic Analysis. (2006). Concepts and methods of the U.S. input-output accounts. Methodological manual.
[4] Hyndman, R. J., & Athanasopoulos, G. (2021). Forecasting: Principles and practice (3rd ed.). OTexts. Chapter 7: Time series regression models. Read the chapter.
[5] U.S. Bureau of Economic Analysis. (n.d.). Input-output. Access to tables and code concordances. Explore the data.
Debate bibliography and sources listed in the original publication
Retained as a bibliographic guide to the 2021 article; the works listed are not presented as an exhaustive review of the current state of research. Non-English publication titles are retained in their original language.
Cockshott, P., & Cottrell, A. (2005). Robust correlations between prices and labor values. Cambridge Journal of Economics, 309–316.
Cockshott, P., Cottrell, A., & Valle Baeza, A. (2014). The empirics of the labour theory of value: Reply to Nitzan and Bichler. Investigación Económica, 115–134.
Kliman, A. (2002). The law of value and laws of statistics: Sectoral values and prices in the US economy, 1977–97. Cambridge Journal of Economics, 299–311.
Kliman, A. (2005). Reply to Cockshott and Cottrell. Cambridge Journal of Economics, 317–323.
Kliman, A. (2014). What is spurious correlation? A reply to Díaz and Osuna. Journal of Post Keynesian Economics, 345–356.
Mindrila, D., & Balentyne, P. (n.d.). Scatterplots and correlation. University of West Georgia. Notes linked in the original.
Nabi, I. (2021). Sobre la metodología del U.S. Bureau of Economic Analysis para la redefinición y reasignación de productos en la matriz insumo-producto de Estados Unidos. Related post.
Sánchez, C., & Ferràndez, M. N. (2010). Valores, precios de producción y precios de mercado a partir de los datos de la economía española. Investigación Económica, 87–118.
Sánchez, C., & Montibeler, E. E. (2015). La teoría del valor trabajo y los precios en China. Economia e Sociedade, 329–354.
U.S. Bureau of Economic Analysis. (2021). The make of commodities by industries, after redefinitions; The use of commodities by industries, after redefinitions (producers’ prices). Tables used in the original study.
Zachariah, D. (2006). Labour value and equalisation of profit rates: A multi-country study. Indian Development Review, 4, 1–20.
Today's headlines reveal a global landscape shaped by technological advancement, political upheaval, and economic restructuring, with artificial intelligence emerging as a transformative force across sectors while political shifts and military actions reshape international relations and domestic policies.
· · ·
Economy & Politics
RT News: Netherlands plans to cut 25,000 government jobs by 2035
RT News · single source
The Netherlands announced plans to eliminate 25,000 government positions by 2035, aiming to save €3.5 billion annually through AI implementation and administrative reforms. The decision follows a 40% increase in civil service workforce since 2018, with police and security services exempt from cuts.
El Ojo Noticias: China demands international norms to prevent space militarization
El Ojo Noticias · single source
China presented a space governance document opposing the use of outer space to undermine other states' sovereignty, security, or development. The initiative calls for preventing armed conflicts in orbit and establishing new international legal rules after US Secretary of the Air Force acknowledged orbital weapons deployment.
“No debe permitirse que ningún Estado abuse de su legislación interna para levantar barreras o imponer sanciones unilaterales” (our translation)
Descifrando la Guerra: El Salvador's military operation escalates in Haiti after kidnapping
Descifrando la Guerra · single source
Four Salvadoran aviation technicians were kidnapped in Haiti after their armored vehicle was attacked by armed men, attributed to the Chen Mechan gang. President Bukele deployed 450 military personnel for a rescue operation, escalating tensions as gang leader 400 Mawozo publicly threatened to combat Salvadoran forces.
Negocios.com: Student-led movement ousts Vučić, reshaping European politics
Negocios.com · single source
A student-led political movement successfully ousted Serbian president Vučić, marking a significant shift in the country's political landscape and European relations. The movement's victory represents a generational change in Serbian politics.
Granma: Cuba reiterates rejection of coercive measures at Brics parliamentary forum
Granma · single source
Cuba reaffirmed its rejection of unilateral economic coercive measures during the first plenary session of the XII Brics Parliamentary Forum in New Delhi. These measures are incompatible with international law and the United Nations Charter.
RT en Español: Trump responds when asked if he wants to 'do something' about Brazil after Lula's victory
RT en Español · single source
Trump stated he doesn't govern Brazil but the US, saying he likes Lula and gets along well with him, but found the extension granted to be very strange.
“Well, I don't govern Brazil, I govern the US. I like Lula. I get along very well with him, but the extension that was granted was very strange.” (our translation)
Rollo Chino: China guides AI use toward sectors with fewer workers
Rollo Chino · single source
China's State Council has published guidelines to promote AI application and protect employees from unjustified dismissions. The document asks companies to evaluate AI's impact on the labor market and recommends prioritizing its use in sectors with staff shortages or worker health risks.
r/ClaudeCode: AI Successfully Deciphers 80% of Historical Ciphers in Six-Week Project
r/ClaudeCode · single source
A data scientist led a community using Claude Code to attempt 460+ historical ciphers from 1400-1900 Europe, achieving an 80% success rate. The AI demonstrated exceptional capabilities in archival research, cryptanalysis, and transcription of ancient manuscripts.
Bloomberg Technology: Broadcom Secures $63 Billion Financing for Anthropic's AI Chips
Bloomberg Technology · single source
Chipmaker Broadcom arranged a $63 billion financing deal with major banks to purchase chips for AI developer Anthropic PBC. The financing involves Bank of America, Blackstone, Citigroup, and Morgan Stanley.
Generación IA: Utah Approves AI-Generated Acne Prescriptions Without Physician Review
Generación IA · single source
Utah has authorized Nolla Health to evaluate acne cases and issue prescriptions through AI without requiring physician review for each treatment. The one-year pilot program will initially focus on topical treatments, gradually reducing medical oversight.
A Multidisciplinary Interpretation of Eigenspaces, Eigenvectors, and Eigenvalues
Structure, transformation, and knowledge: from linear algebra to data analysis and quantum mechanics.
JOSÉ MAURICIO GÓMEZ JULIÁN Originally published April 2, 2021 Revised and expanded edition · October 26, 2026
· · ·
I · THE PROBLEMWhat remains under a transformation?
A transformation can stretch, compress, reflect, or combine the coordinates of a vector. Among the many possible outcomes, one is particularly revealing: the transformed vector may be a scalar multiple of the original. In the real plane, this means that its image remains on the same line through the origin, although it may change in length, reverse its orientation, or become the zero vector.
A vector with this property is called an eigenvector, also known as a characteristic vector or proper vector. The scalar expressing the proportionality is its eigenvalue, also called a characteristic value or proper value. These terms refer to the same objects across different terminological traditions.
Av = λv, v ≠ 0The fundamental relationship in the eigenvalue problem.
The concept matters because a complex transformation can become more intelligible once its eigendirections are identified. That understanding, however, depends on the operator under consideration: a vector may be an eigenvector of one transformation without being an eigenvector of another. The property expresses a relationship between the two objects. [1]
II · THE FORMAL LANGUAGEEigenvectors, eigenvalues, and eigenspaces
Let V be a vector space over a field K, and let T: V → V be a linear operator. A scalar λ ∈ K is an eigenvalue of T if there is a nonzero vector v such that T(v) = λv. In finite dimensions, once a basis has been chosen, this operator can be represented by a square matrix A.
We should distinguish the vector space, the operator acting on it, and its matrix representation. A particular matrix is an element of the space of matrices of the corresponding size; it may also represent a linear map. Neither statement requires the dimension to be large or infinite.
For a given eigenvalue, the eigenspace contains all vectors satisfying the proportionality relation, including the zero vector:
Eλ = ker(A − λI)= {v ∈ Kn : Av = λv}I is the identity matrix; ker denotes the kernel.
Including zero makes this set a subspace. The zero vector itself is not an eigenvector. If v is an eigenvector, any multiple cv with c ≠ 0 is also an eigenvector for the same eigenvalue. When Eλ has dimension one, it is called an eigenline.
In finite dimensions, eigenvalues are found by solving det(A − λI) = 0. The choice of field matters: a 90° rotation in the plane has no real eigenvectors, although its matrix does have complex eigenvalues and eigenvectors. Moreover, the existence of eigenvalues does not guarantee a basis of eigenvectors; diagonalization requires additional conditions. [1][2]
III · AN ELEMENTARY CASETwo directions that reveal the structure
Consider a transformation of the plane represented by the following matrix:
A = 2112A(x, y) = (2x + y, x + 2y).
Applying it to v1 = (1, 1) gives Av1 = (3, 3) = 3v1. Applying it to v2 = (1, −1) gives Av2 = (1, −1) = v2. The eigenvalues are 3 and 1, respectively.
The eigenspaces are the lines y = x and y = −x. The transformation triples the vectors on the first and leaves those on the second unchanged. A general vector combines both contributions:
x = αv1 + βv2Ax = 3αv1 + βv2An eigenbasis separates two modes of action of the same operator.
01 / EIGENVECTOR
v₁Av₁0
02 / NON-EIGENVECTOR
wAw0
Figure 1. The worked example, with equal scales on both axes. Copper indicates the initial vector; brown, its image. The first case exhibits proportionality. In the second, w = (2, 0) and Aw = (4, 2).
This example clarifies what remains: for nonzero eigenvalues, the eigenline is preserved, though individual vectors on it need not remain unchanged. Only eigenvalue 1 leaves its eigenvectors fixed. The distinction between invariance of a subspace and a vector remaining unchanged will matter when interpreting the applications.
IV · DATA SCIENCEDimensionality, information, and noise
An observation described by p numerical variables can be represented as a vector in ℝp. This representation should be distinguished from the sample space of probability theory: the set of possible outcomes of an experiment does not necessarily have a vector-space structure.
Principal component analysis (PCA) constructs linear combinations of variables that concentrate the variation in the data. Observations are centered and, when their units and scales warrant it, standardized as well. Choosing between covariances and correlations changes the geometry of the analysis and may change its results. [3]
Let S be the covariance matrix. Since it is real, symmetric, and positive semidefinite, it admits an orthonormal basis of eigenvectors and nonnegative eigenvalues. For a unit eigendirection qi, the component is the projection of the centered observation onto that direction:
Sqi = λiqizi = qiT(x − μ)Eigenvalue λᵢ is the variance of component zᵢ, using the same covariance convention.
Reduction consists in retaining k < p components and representing the observations through those coordinates. The retained subspace is spanned by the selected directions; it may contain eigenvectors associated with different eigenvalues and therefore need not be a single eigenspace.
In the preceding example, if A were the covariance matrix, its eigenvalues 3 and 1 would indicate that the first direction accounts for 75% of the total variance. Its unit eigenvector would be (1, 1)/√2. Retaining only that component amounts to projecting onto the line y = x; the reconstructed observation loses its contribution along the perpendicular direction.
Nor does reduction require us to claim that parts of the real phenomenon are destroyed. Its representation changes, and certain differences become inaccessible through that representation. The scientific value of the operation depends on what is preserved, what is discarded, and the purpose for which the object is analyzed.
V · QUANTUM MECHANICSStates, observables, and measurement outcomes
In the usual formulation, the pure states of a quantum system are represented by vectors in a Hilbert space, subject to the corresponding physical equivalences. These spaces may be finite- or infinite-dimensional. An ideal spin-½ system, for example, can be described using a two-dimensional state space. High dimensionality alone does not define what is quantum.
Observables are represented by self-adjoint operators; in finite dimensions, by Hermitian matrices. In a problem with a discrete spectrum, an eigenvalue relation takes the form:
Ôui = aiuiÔ represents the observable; aᵢ is an eigenvalue; uᵢ is an eigenstate.
A general state may be a superposition of eigenstates of the chosen observable. In an orthonormal eigenbasis, the expansion coefficients determine the probabilities of the outcomes. For a nondegenerate eigenvalue, the probability is the squared modulus of its coefficient; in the presence of degeneracy, the contributions from the entire corresponding eigenspace are summed. [4]
The algebraic action of an observable should not be identified with the physical process of measuring it. In the model of an ideal projective measurement, the outcome selects an eigenspace, and the state is updated through the corresponding projection followed by normalization. The physical interpretation of that update is part of the measurement problem. The formalism alone does not decide among the different interpretations of the theory.
The wave function and the Schrödinger equation
The wave function is a representation of the state; the Schrödinger equation determines its evolution in time. In the position representation for a single particle, the normalized wave function provides a probability density through ρ(x, t) = |ψ(x, t)|2. The probability of finding the particle in a region is obtained by integrating that density over the region.
iℏ ∂ψ/∂t = ĤψTime evolution of the state.Ĥφ = EφThe stationary energy eigenvalue problem for a time-independent Hamiltonian.
An energy eigenstate evolves with a global phase factor e−iEt/ℏ. Under these conditions, its probability density remains constant, although its vector representation changes in phase. This stationarity does not imply immunity to every external perturbation: if the Hamiltonian changes, the state may cease to be an eigenstate. [5]
Continuous spectra require additional tools: not every possible value of an observable corresponds to a normalizable eigenvector within the Hilbert space. The elementary picture of a list of vectors and values should therefore be understood here as an introduction to the discrete case. [n. 1]
VI · THE COMPARISONOne formal structure, different meanings
The proportionality pattern reappears across several disciplines. Its specific meaning depends on what the operator represents, the units of the quantities involved, and the theory linking the model to the phenomenon.
What the eigenvalue expresses in each application
Context
Operator or matrix
Interpretation
Linear geometry
A transformation of the space
A proportionality factor along an eigendirection.
PCA
Covariances or correlations
The variance of the component defined by a unit eigenvector.
Quantum mechanics
A self-adjoint observable
A possible measurement outcome in the discrete case.
Linear dynamics
The matrix governing evolution
Growth, decay, or oscillation of eigenmodes.
In a continuous-time system dx/dt = Ax with a constant matrix, an eigenmode evolves through eλt; if all eigenvalues have strictly negative real parts, the origin is asymptotically stable. In a discrete-time system xt+1 = Axt, the corresponding criterion requires all eigenvalues to have modulus strictly less than one. Boundary cases require further examination of the operator’s structure. [6]
The sign of an eigenvalue therefore has no universal meaning. A negative eigenvalue may indicate a reversal of orientation in a real transformation or decay in a real continuous-time dynamical mode. The shared algebraic form allows us to compare the cases, but interpreting them requires preserving their differences.
VII · PHILOSOPHICAL INTERPRETATIONEssence as a question of relations
The philosophical interest of spectral analysis arises from its ability to make explicit relationships that an immediate description may leave concealed. Rather than considering each coordinate in isolation, it allows us to identify modes of organization within an operator. From a materialist and dialectical perspective, this possibility invites us to investigate how a structure manifests itself through its transformations.
In this essay, essence designates the constitutive relations through which the organization and behavior of a phenomenon can be understood. It does not presuppose an immobile substance behind its manifestations. Identifying it requires studying the genesis of the object, its conditions of existence, its internal and external relations, and the limits within which it retains a certain organization.
The persistence of a relation under a transformation can provide access to the structure of an object; its significance depends on what the operator transforms and how it represents the phenomenon.
The eigenvalue relation provides a precise example of preservation under transformation: acting on an eigenvector, the operator produces a result proportional to it. This structure admits a philosophical reading as a unity of persistence and modification. That reading, however, is an argued interpretation of the formalism; the mathematical definition does not by itself demonstrate an ontological thesis about reality as a whole.
The operator as a mediation of knowledge
For spectral analysis to contribute to our knowledge of a material phenomenon, the operator employed must be justified. In an empirical study, the selected variables, units, measurement design, and model assumptions matter. The robustness of the results across reasonable choices forms part of that justification.
Two situations should be distinguished here. A change of basis represents the same operator in another way and preserves its eigenvalues. By contrast, selecting different variables or changing their weighting in a statistical analysis may construct a different operator and alter its spectrum. Independence from coordinates does not amount to independence from modeling.
The algebraic property must also be distinguished from persistence over time. An eigendirection may correspond to a mode that grows rapidly, dies away, or remains constant. Being an eigenvector does not generally imply durability, stability, or resistance to perturbations.
The scope of a materialist reading
In PCA, concentrating variance may facilitate the description of a regularity, but it does not yet identify its causes. In quantum mechanics, an eigenvalue characterizes a possible outcome for a specified observable without thereby summarizing all the properties of the system. Explaining a phenomenon requires connecting spectral relationships with the theory and evidence of the relevant discipline.
The defensible thesis is therefore conditional: when an operator adequately represents relevant relations of an object, its spectral structure can contribute to our understanding of aspects of that object’s organization. The material relevance of those aspects must be established through investigation. This formulation preserves the ambition of the multidisciplinary approach while offering criteria for examining its results.
The movement of knowledge thus proceeds from observed manifestations toward the construction of explanatory relations, then returns to those manifestations to test them. Eigenvectors and eigenvalues participate in that mediation: they provide a formal structure whose scientific content is determined through its concrete application.
VIII · CONCLUSIONKnowing a structure through its transformation
An eigenvector is a nonzero vector whose image under an operator is proportional to it. The eigenvalue expresses that proportionality; the eigenspace contains the corresponding solutions, including zero. These relationships allow us to decompose and understand particular aspects of a transformation.
Their applications span geometry, statistics, physics, and the study of dynamical systems. In each field, the theory of the phenomenon gives the mathematical objects their specific meaning. Multidisciplinary comparison is productive when it makes explicit both the shared structure and the conditions of each application.
From the philosophical perspective developed here, spectral analysis is a tool for investigating constitutive relations, regularities, and modes of organization. The task is to justify the representation, delimit its inferences, and test what it reveals. Through this work, it can contribute to knowledge of essence understood as the material and relational organization of a phenomenon.
· · ·
CRITICAL APPARATUSNotes
In infinite dimensions, the spectral theory of self-adjoint operators encompasses discrete and continuous spectra, spectral measures, and domain questions. This discussion concentrates on the discrete case to develop the comparison without identifying the entire spectrum with eigenvalues associated with normalizable vectors. See reference [5], section 4. ↩
The philosophical section expresses the interpretation developed in this essay. The mathematical and physical sources support the definitions and applications discussed; the proposed philosophical thesis is not attributed to them.
SOURCES AND FURTHER READINGReferences
Margalit, D., and Rabinoff, J. Interactive Linear Algebra. Georgia Institute of Technology. Section 5.1, Eigenvalues and Eigenvectors. ↩
Strang, G. (2021). ZoomNotes for Linear Algebra. Wellesley–Cambridge Press; available through MIT OpenCourseWare, course 18.06SC. Course notes. ↩
Massachusetts Institute of Technology. (2025). Linear Differential Equations and Complex Exponentials. Course 6.3100, prelab 3. Natural modes and stability. ↩